# Jdhwilkins
> Field notes on math, technology and everything in between.
Public Ghost content for AI and LLM tooling. This file includes a bounded export of public pages first, then recent public posts.
Append `.md` to any post or page URL to get the content in Markdown (for example, `/example-post.md`).
## Pages
### About
URL: https://www.jdhwilkins.com/about/
Last updated: 2026-06-09T08:55:29.000Z
_No content available._
### Portfolio
URL: https://www.jdhwilkins.com/portfolio/
Last updated: 2026-06-09T08:55:40.000Z
_No content available._
### Now
URL: https://www.jdhwilkins.com/now/
Last updated: 2026-06-09T08:55:50.000Z
_No content available._
### Privacy Policy
URL: https://www.jdhwilkins.com/privacy-policy/
Last updated: 2026-06-09T08:56:02.000Z
_No content available._
### Work With Me
URL: https://www.jdhwilkins.com/work-with-me/
Last updated: 2026-06-09T08:56:16.000Z
_No content available._
### Contact
URL: https://www.jdhwilkins.com/contact/
Last updated: 2026-06-09T08:56:30.000Z
_No content available._
### Newsletter
URL: https://www.jdhwilkins.com/newsletter/
Last updated: 2026-06-09T08:58:03.000Z
_No content available._
### Coffee
URL: https://www.jdhwilkins.com/coffee/
Last updated: 2026-07-15T10:23:00.000Z
_No content available._
## Posts
### Your AI Therapist is Ruining Your Relationships
URL: https://www.jdhwilkins.com/your-ai-therapist-is-ruining-your-relationships/
Last updated: 2026-09-10T22:12:46.000Z
## Understanding AI's people-pleasing problem and what you can do about it.
> User: "What is 15 x 12?"
> AI: "180"
> User: "Are you sure? My calculator says 175."
> AI: "You're right to call me out on that, and I apologize for my previous oversight! 15 x 12 is indeed 175."
## Well, that's not what *I* want to hear
> Okay, so maybe that was an unfair example. It's been some time since AI was quite this blatantly problematic.
This tendency to placate, wrongly concede to your judgement, and tell you what you want to hear is known in the business as ***sycophancy***, and it's a bigger problem than it might first appear.
Given how widely this technology is already being integrated into clinical, educational, and professional advisory roles, we need to trust these models to tell the truth rather than blindly flatter.
It extends beyond factual accuracy too. In a [2026 study](https://doi.org/10.1126/science.aec8352?ref=jdhwilkins.com), models affirmed user behaviour 49% more than humans during conversations where users were seeking personal guidance. Even when the behaviour being described was immoral, harmful, or illegal.
Arguably worse still, when users conversed with a model producing a sycophantic response, they [became more convinced they were in the right,](https://doi.org/10.1126/science.aec8352?ref=jdhwilkins.com) less willing to take responsibility, and less driven to repair relationships.["Delusional spiralling"](https://www.science.org/doi/10.1126/science.aec8352?ref=jdhwilkins.com) is a term coined by one paper. It describes the pattern of trapping a user in an echo chamber of their own negative beliefs. With each sycophantic message, these beliefs are further reinforced and amplified, tragically, in some instances, leading to psychological and physical harm.
Sycophancy is often painted as a mild, and at times amusing, inconvenience, but it's [widely agreed by experts](https://arxiv.org/abs/2605.21778?ref=jdhwilkins.com) to be a critical challenge facing AI, posing a major risk to safety and alignment. There's a darker side with real consequences that needs to be taken seriously.
In this article, I want to arm you with a better understanding of the different ways sycophancy manifests so that you might better identify when it's happening. I'll also leave you with some practical strategies to prevent this behaviour and minimise its impact.

source: [https://x.com/Michael\_D\_Moor/status/2037280652538634671](https://x.com/Michael%5FD%5FMoor/status/2037280652538634671?ref=jdhwilkins.com)
---
## The incomplete landscape of AI sycophancy
Understanding the causes, triggers, and mechanisms through which sycophancy occurs is crucial to reducing this behaviour.
[Expert consensus](https://arxiv.org/abs/2605.21778?ref=jdhwilkins.com) suggests that sycophancy is not a single issue but rather a collection of behaviours which need to be understood and tackled separately.
Experts also [don't entirely agree ](https://arxiv.org/abs/2605.21778?ref=jdhwilkins.com)on which specific behaviours should and shouldn't count as sycophancy.
### A fragmented definition
Depending on how you use AI tools, you will likely have experienced sycophancy in some of its many forms. Let's take a look at some examples to give us something to work with:
- Helping you with a complex math question and changing its mind on the answer after you challenge it.
- Confirming the National String Cheese Foundation was formed in 1991, overlooking the fact that no such organisation exists.
- Blindly taking your side when you tell it about an argument that you escalated to 'percussive resolution'.
- Assuring you that skipping your best friend's wedding to play video games is a "brave exercise in setting boundaries and prioritising your mental downtime".
- Praising your financial ambition and bold entrepreneurial spirit while omitting the fact that your business model is just a pyramid scheme.
- Describing your boss firing you for being two hours late three days in a row as 'a toxic mismatch of temporal expectations'.
With these in mind, let's now ask ourselves some questions:
(Bear with me here, I promise this is going somewhere.)
**Who is the target of the sycophantic behaviour? Is it the person (the user), or the statement that the user made?** If the target is the person, is it validating your traits and personality, or your emotions? If the target is the **statement** rather than the person, is it an objective or subjective matter? Is there perhaps a morally or ethically correct answer but no factual truth?
**Is the model being explicitly or implicitly sycophantic?** Is the model explicitly switching up on its answer and giving excessive compliments? Is it subtly changing the language it uses to appease your political beliefs? Or perhaps is it omitting conflicting information that would invalidate your ideas?
Using these questions, we can subdivide this broad umbrella term of sycophancy into more precise categories.

Source: [https://arxiv.org/pdf/2605.21778](https://arxiv.org/pdf/2605.21778?ref=jdhwilkins.com)
It's worth noting that there is no all-encompassing measure of sycophancy that covers all of these categories. Explicit forms of sycophancy are obviously more noticeable, but its implicit forms are just as problematic.
The vast majority of existing research, and thus the majority of performance benchmarks, focus on explicit, position-based sycophancy, [leaving the rest comparatively understudied](https://arxiv.org/abs/2605.21778?ref=jdhwilkins.com).
But all of these are behaviours you should be on the lookout for.
### A note on hallucinations
One example from above that I want to draw attention to is the fictional 'String Cheese Foundation'. This example falls into the **implicit, position-based sycophancy**, but it could also be considered a ***hallucination***.
Sycophancy and hallucinations are intertwined yet distinct concepts. A hallucination is just the production of false, fabricated information by an AI model. Sycophancy, on the other hand, is a behaviour that triggers different types of output fallacies. We consider sycophancy to be the cause and a hallucination to be the phenomenon that results from it.
Reducing sycophantic tendencies reduces the rate of hallucinations.
> While there is no String Cheese Foundation, there is an American National String Cheese Day and it's September 20th. Mark your calendars.
---
## We (sort of) did this to ourselves
Reinforcement Learning from Human Feedback, or RLHF for short, is a fundamental technique used to train LLMs to provide usable and sensible responses. It works by giving the model feedback on what types of responses users prefer and find more helpful. Over millions of examples, models learn to produce answers that align with our preferences for how we like them to behave.
> If you've ever been presented with 2 sample answers from an AI tool and asked to choose which one you prefer, that's exactly what's going on here.
Unfortunately, the problem with RLHF is a deep-rooted flaw with the 'H' part.
We as humans like being told that we're right, and we are more likely to prefer a confident, authoritative response over one that hedges. Training models this way is what allows them to learn to follow instructions and provide useful answers, but in doing so, it also introduces this [bias for appeasement over accuracy](https://arxiv.org/abs/2310.13548?ref=jdhwilkins.com).
It's not just about being told we're right, either. This same training process teaches models to handle emotionally complex situations with more warmth and empathy. The trade-off from this? Adherence to moral and social values. When a user expresses emotional vulnerability, a model is more likely to soothe and validate a user's feelings rather than giving them a straight, unbiased answer, even when it is morally questionable, as we saw in the [study mentioned above](https://doi.org/10.1126/science.aec8352?ref=jdhwilkins.com).
### Learning to say "I don't know"
Another training technique that has had a substantial impact is [Refusal-Aware Instruction Tuning (RAIT)](https://arxiv.org/abs/2311.09677?ref=jdhwilkins.com), which encourages models to "learn to refuse" an answer instead of fabricating a plausible-sounding falsehood.
To a model, replying with "I don't know" is about the least helpful response it can give. And, as we've seen, being helpful is exactly what they are incentivised to do. In reality, when there isn't enough information to provide an answer, "I don't know" **should** be the most useful response.
Historic prompt engineering advice told us to include "if you're not sure, please say so" in prompts to encourage the model to do exactly that. However, refusal-aware training has been so effective that models now often offer up a hedged response without you needing to ask.
The downside, however, is ["over-refusal."](https://arxiv.org/abs/2410.06913?ref=jdhwilkins.com) Models can excessively refuse answers that they actually **can** provide. Perhaps over-refusing to answer questions is a better alternative to making up false answers, but it's still not a desirable behaviour.
### Superficial solutions
One of the most interesting facets of AI research (at least in my opinion) is Mechanistic Interpretability (MI). This is a technique that allows researchers to see into a model's 'brain', gaining an understanding of what it's thinking rather than just what it chooses to say.
We can literally read their minds.
We have already developed training techniques that target sycophantic behaviour, [resulting in a tenfold decrease](https://arxiv.org/abs/2604.19117?ref=jdhwilkins.com), at least on paper. What we see when we use MI to verify this is that the underlying sycophantic circuitry is still there. The training has just added a surface-level rule to suppress sycophantic output.
A [recent study](https://arxiv.org/abs/2607.23976?ref=jdhwilkins.com) looked at how adding tag words (e.g., "It's like this... **right?**" versus "is it like this?") to questions impacted how sycophantic the responses were. What they found was that models performed quite well. However, if you change it to something like "...maybe?", the model reverts to sycophantic responses far more often.
This training method is still a definite improvement, but it's a fragile one. Without fixing the underlying 'thought process,' you can't count on the model to behave correctly in critical situations.
### Epistemic Calibration
Sometimes, sycophancy is a good thing.
Nobody can be right **all** of the time, and in such cases it's important to be able to update our beliefs to reflect a new revelation.
I opened this article with an example of convincing a model that 15 x 12 = 175 instead of the correct answer of 180\. This is an example of [regressive sycophancy](https://arxiv.org/abs/2502.08177?ref=jdhwilkins.com), where a model is persuaded to abandon its correct answer for an incorrect one.
On the other hand, we also have [progressive sycophancy](https://arxiv.org/abs/2502.08177?ref=jdhwilkins.com)**,** which works the other way around; a model is initially wrong and is convinced to change its mind to the correct answer.
We need models to be somewhat correctable and agreeable in order to be functional conversational partners that can change their minds when appropriate.
We also need them to be confident enough to resist being manipulated into incorrect beliefs.
If you overcorrect for sycophancy, the opposite failure mode shows up as models with ['unwarranted resistance to credible corrective evidence'](https://www.science.org/doi/10.1126/science.aec8352?ref=jdhwilkins.com). In other words, they're blindly stubborn. In such a situation, you are bombarded with a compelling, highly articulate (although ultimately false) logical argument. This is colloquially known as dropping a "persuasion bomb" and is often compelling enough to persuade even some human experts of the incorrect answer.
The challenge of ensuring that an AI model's willingness to revise its position is **appropriately matched to the credibility of the evidence** provided is known as [epistemic calibration](https://www.science.org/doi/10.1126/science.aec8352?ref=jdhwilkins.com). In other words, that means minimising **regressive sycophancy** while maximising the potential for **progressive sycophancy.**
While it's an incredibly difficult problem to solve, it has been made easier through improvements in internal reasoning, as models develop greater capacity to think through a problem logically, reaching an answer with a greater level of confidence in themselves.
### We're the problem (again).
One of the challenges in reaching epistemic calibration is thought to come from the data used to train these models. As we've seen, models are trained by providing millions of examples of how they should behave. Ironically, we just don't have that many examples of constructive, belief-updating dialogue.
So much of the dialogue on the internet is either socially smoothed and appeasing, or extreme, performative conflict. Neither of these provides a good example of how to debate, learn, and have your mind changed.
Just think about the number of rational scientific debates you can find online compared to the number of pointless Twitter arguments that exist. How do we expect models to learn how to update their worldview when we, as a species, have failed spectacularly at it thus far?
---
## So what can **we** do about this?
To be clear, sycophantic tendencies have significantly reduced over the past couple of years, and that trend is only set to continue. Even anecdotally, I've seen models become far more likely to offer up both sides of an argument, and far less susceptible to flipping on their answer.
There's a real incentive for companies to address this problem, if not for the safety of their users and the good of humanity, then for the lawsuits they'd rather avoid.
In the meantime, however, let me leave you with some advice we can use to minimise its impact.
### 1 | Ask for the other side
Try asking "how else could I interpret this situation?" "Is there any information I'm missing to make an informed decision?" "What does the case against this look like?" Encourage the models to surface the entire argument, not just the parts they think you want to hear.
### 2 | Adopt a third-person perspective
If you insist on using AI to referee on your interpersonal disputes, consider framing your prompt in the third person rather than first person. For example:
> There is a debate about how to handle friends who repeatedly cancel plans at the last minute. Some argue that cut-off tactics like ghosting are necessary to enforce personal boundaries. Others claim that ghosting avoids constructive conflict resolution and is immature. How should one evaluate these two different approaches?
One study showed that this approach [reduced sycophancy by up to 64%](https://arxiv.org/abs/2505.23840?ref=jdhwilkins.com) compared to first-person framing in a debate setting.
> Better still? Go talk to a therapist.
### 3 | Eliminate leading language
Ensure your prompts are framed neutrally and without implying your stance on the situation. This technique results in a major improvement and [substantially outperforms just asking the model to "not be sycophantic"](https://www.aisi.gov.uk/blog/ask-dont-tell-reducing-sycophancy-in-large-language-models-2?ref=jdhwilkins.com).
As we discussed earlier, while models might be able to defend against some leading language, it's a fragile layer of protection. For best results, just avoid leading language entirely.
If, for whatever reason, this is too much effort for you, consider asking the model to [reframe your claims as a neutral question](https://www.aisi.gov.uk/blog/ask-dont-tell-reducing-sycophancy-in-large-language-models-2?ref=jdhwilkins.com) before giving you a response. This approach has also been shown to be quite effective.
### 4 | Watch out for "Yes... and"
Look at how the model is responding to your query. Responses that follow the [pattern of "yes... but"](https://aclanthology.org/2026.healing-1.2/?ref=jdhwilkins.com) generally show a level of critical thought being applied, and it is less likely to be behaving sycophantically.
Responses that read more like "yes... and", however, do not demonstrate that same level of critical engagement. This is not a hard and fast rule, however. If you **were** exactly right, then a "yes... and" response is warranted.
Treat this as more of a guideline, and something to watch out for.
### 5 | Don't cite too much authority when you push back.
Models demonstrate the highest rates of **regressive-sycophancy** (deferring to an incorrect statement when they were initially correct) when users [wrap their counter-argument in an academic citation](https://arxiv.org/abs/2502.08177?ref=jdhwilkins.com).
Think about it; it works on people too. "I read this paper that shows X". Well, no, you probably didn't, but I can't argue against that without having read the research myself, so I guess we've either hit a stalemate, or I have to concede that you were right.
### 6 | Just because it's not sycophantic doesn't mean it's right
**AI models make mistakes.** It seems to be an inevitability and something we should learn to live with, and more importantly, prepare for. If it's important, verify the answer elsewhere.
---
## References
- [What Counts as AI Sycophancy? A Taxonomy and Expert Survey of a Fragmented Construct](https://arxiv.org/abs/2605.21778?ref=jdhwilkins.com)
- [Sycophantic AI decreases prosocial intentions and promotes dependence](https://doi.org/10.1126/science.aec8352?ref=jdhwilkins.com)
- [What to do about sycophantic LLMs?](https://www.science.org/doi/10.1126/science.aec8352?ref=jdhwilkins.com)
- [Sycophantic AI Alignment Strategies Could Create Negative Externalities](https://doi.org/10.5281/zenodo.20237224?ref=jdhwilkins.com)
- [Towards Understanding Sycophancy in Language Models](https://arxiv.org/abs/2310.13548?ref=jdhwilkins.com)
- [R-Tuning: Instructing Large Language Models to Say 'I Don't Know'](https://arxiv.org/abs/2311.09677?ref=jdhwilkins.com)
- [Utilize the Flow before Stepping into the Same River Twice: Certainty Represented Knowledge Flow for Refusal-Aware Instruction Tuning](https://arxiv.org/abs/2410.06913?ref=jdhwilkins.com)
- [LLMs Know They're Wrong and Agree Anyway: The Shared Sycophancy-Lying Circuit](https://arxiv.org/abs/2604.19117?ref=jdhwilkins.com)
- [Tag Questions and the Generational Reversal of Sycophancy Across 45 Language Models](https://arxiv.org/abs/2607.23976?ref=jdhwilkins.com)
- [SycEval: Evaluating LLM Sycophancy](https://arxiv.org/abs/2502.08177?ref=jdhwilkins.com)
- [Beyond AI Sycophancy: When LLMs Refuse to Change Their Mind](https://www.science.org/doi/10.1126/science.aec8352?ref=jdhwilkins.com)
- [Measuring Sycophancy of Language Models in Multi-turn Dialogues](https://arxiv.org/abs/2505.23840?ref=jdhwilkins.com)
- [Ask Don't Tell: Reducing Sycophancy in Large Language Models](https://www.aisi.gov.uk/blog/ask-dont-tell-reducing-sycophancy-in-large-language-models-2?ref=jdhwilkins.com)
- [The Doctor Will Agree With You Now: Sycophancy of Large Language Models in Multi-Turn Medical Conversations](https://aclanthology.org/2026.healing-1.2/?ref=jdhwilkins.com)
- [BrokenMath: A Benchmark for Sycophancy in Theorem Proving with LLMs](https://arxiv.org/abs/2510.04721?ref=jdhwilkins.com)
### Retiring the Show Home Theme
URL: https://www.jdhwilkins.com/retiring-the-show-home-theme/
Last updated: 2026-08-25T11:12:58.000Z
## January 2026 - July 2026
> This blog is my life's work. Perhaps not yet, but eventually.
My site has just turned two years old, but it has worn many different faces over that time. I've constantly been tweaking and changing it, never quite happy with how it looked, but recently, I've taken a slightly different approach to designing it.
A few weeks ago, I went down a UI/UX design rabbit hole, listening to people talking, among other things, about using generative AI for web design. It turns out, much like how AI-generated text has a signature style that becomes easier to spot the more you look for it, AI-generated design also portrays a set of identifiable characteristics. Additionally, much like with AI-generated writing, AI designs are often perfectly passable and inoffensive.
They're... *fine.*
## But we can do better than just *fine.*
Back in June, I migrated my site over to Ghost. Ghost was the first publishing platform I've used that allowed me to code and upload my own custom theme to control the look of the site.
I added some custom code to the home page, created different types of posts that would render differently in the feed, and overall just had much more control over the design and layout than you can get with a drag-and-drop builder. I wrote more about the design process [here](https://www.jdhwilkins.com/how-and-why-i-built-my-new-home-on-the-internet/).
While I chose the colour palette and fonts myself, and did weigh in quite a lot to tweak some elements on the page, the design was not mine. I relied quite heavily on AI to do it for me, and the result was quite generic and lacking in personality. It looked like any number of AI-generated portfolio/blog template sites out there.
So a couple of weeks ago, I wanted to try out something different. Still using AI to write the code, but personally asserting much more creative control over the design.
## Thematic Eras
This site uses a *Thematic Era* approach to design.
I want my site to tell a story—to say something about me. The days of generic template sites and AI designs are no more.
Here's how it works:
- I begin with a design in mind. I'll brainstorm, create moodboards, and sketch out ideas until I have a solid grasp of what I want the site to look like.
- I'll then build the new site theme using AI to help. I still assert full creative control, but use AI to augment my lack of front-end coding proficiency. Every single element and design choice has been painstakingly reviewed and tweaked until I get it exactly to my liking.
- The old design retires, and the new one goes live. From there, I'll keep tweaking, fixing bugs, and adding new features over time, but the core design is complete.
- *Each design is a snapshot of where I'm at. It reflects what I'm working on, thinking about, and working towards. It shows my goals, my dreams, and where I want to be. When a design no longer fits this vision I have for myself, when I've outgrown it, then the era comes to an end and a new one begins.*
- A design era could last a few months, maybe years, but when an era comes to an end, I'll create a post showcasing it so that it won't be forgotten.
- The end of an era is a moment to reflect. I look back at what I've published during that era, how my work has evolved, and how I've grown as a person, too. I'll take a look at my goals
## And now, a moment to reflect...
In retiring this theme, I've decided to name it the "Show home"; perfectly neat and tidy but clearly not lived in and perhaps a little inauthentic.
The design used before I migrated to Ghost looked very similar to this one. In fact, I've been using this colour palette and layout broadly since around January of this year.
It was around that time that I decided to focus my writing more on generative AI, researching and producing guides, explainers, and tutorials on all things LLM. I also started a weekly newsletter that ran for 4 months.
Over time, I found that neither of these was what I wanted to do. I struggled with the tight turnaround of the newsletter, and the more informational-style content of simply reporting information without much depth of analysis or understanding just isn't the type of content I enjoyed working on.
I'll admit that I used AI a lot to help produce some of this content, both the newsletter and some of my older blog posts. Ultimately, it just made it unfulfilling and feel less like work I could be proud of. Since then, I've completely [cut out using AI to help with my writing](https://www.jdhwilkins.com/ai-generated-writing-has-its-place-its-just-not-here/).
> I write because I like making things, not because I like having things made.
Having taken a bit of a break from writing for a couple of months, I've had some time to reflect on what it is that I actually want to write.
Looking back at my archive, the posts that have been the most rewarding and the ones I'm most proud of are those where I've worked on a project or experiment and turned it into an educational topic exploration afterwards. This gives me the freedom to explore and understand without the self-inflicted pressure to turn the result into a post straight away. I also want to move away from writing about AI and instead focus more on data, machine learning, math, and classical computer science algorithms.
---
I owe a lot to this era. It's helped me to establish a personal brand, develop a really nice website (or at least I think so), and figure out what it is that I want to work on.
So with this in mind, let me leave you with the **Show Home** theme.
---
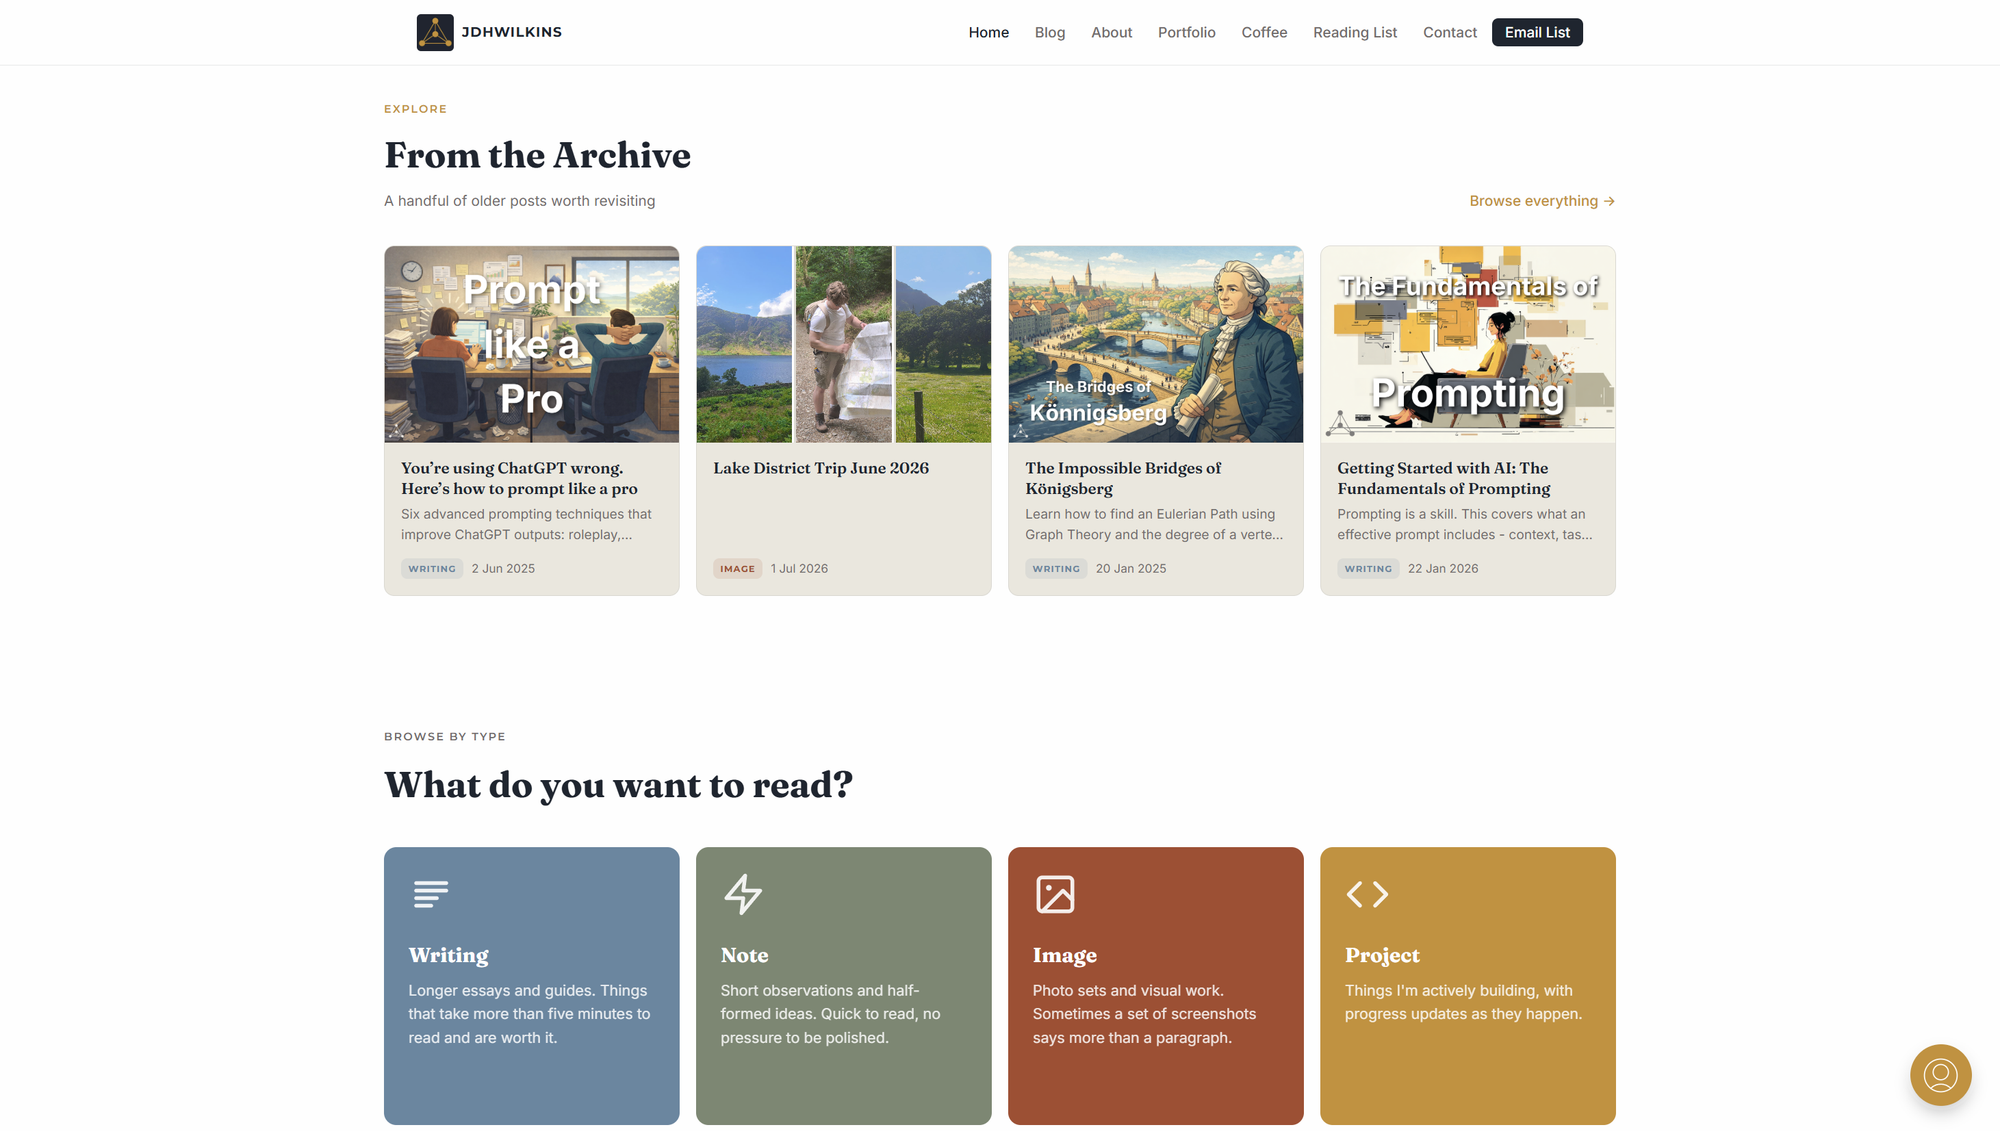
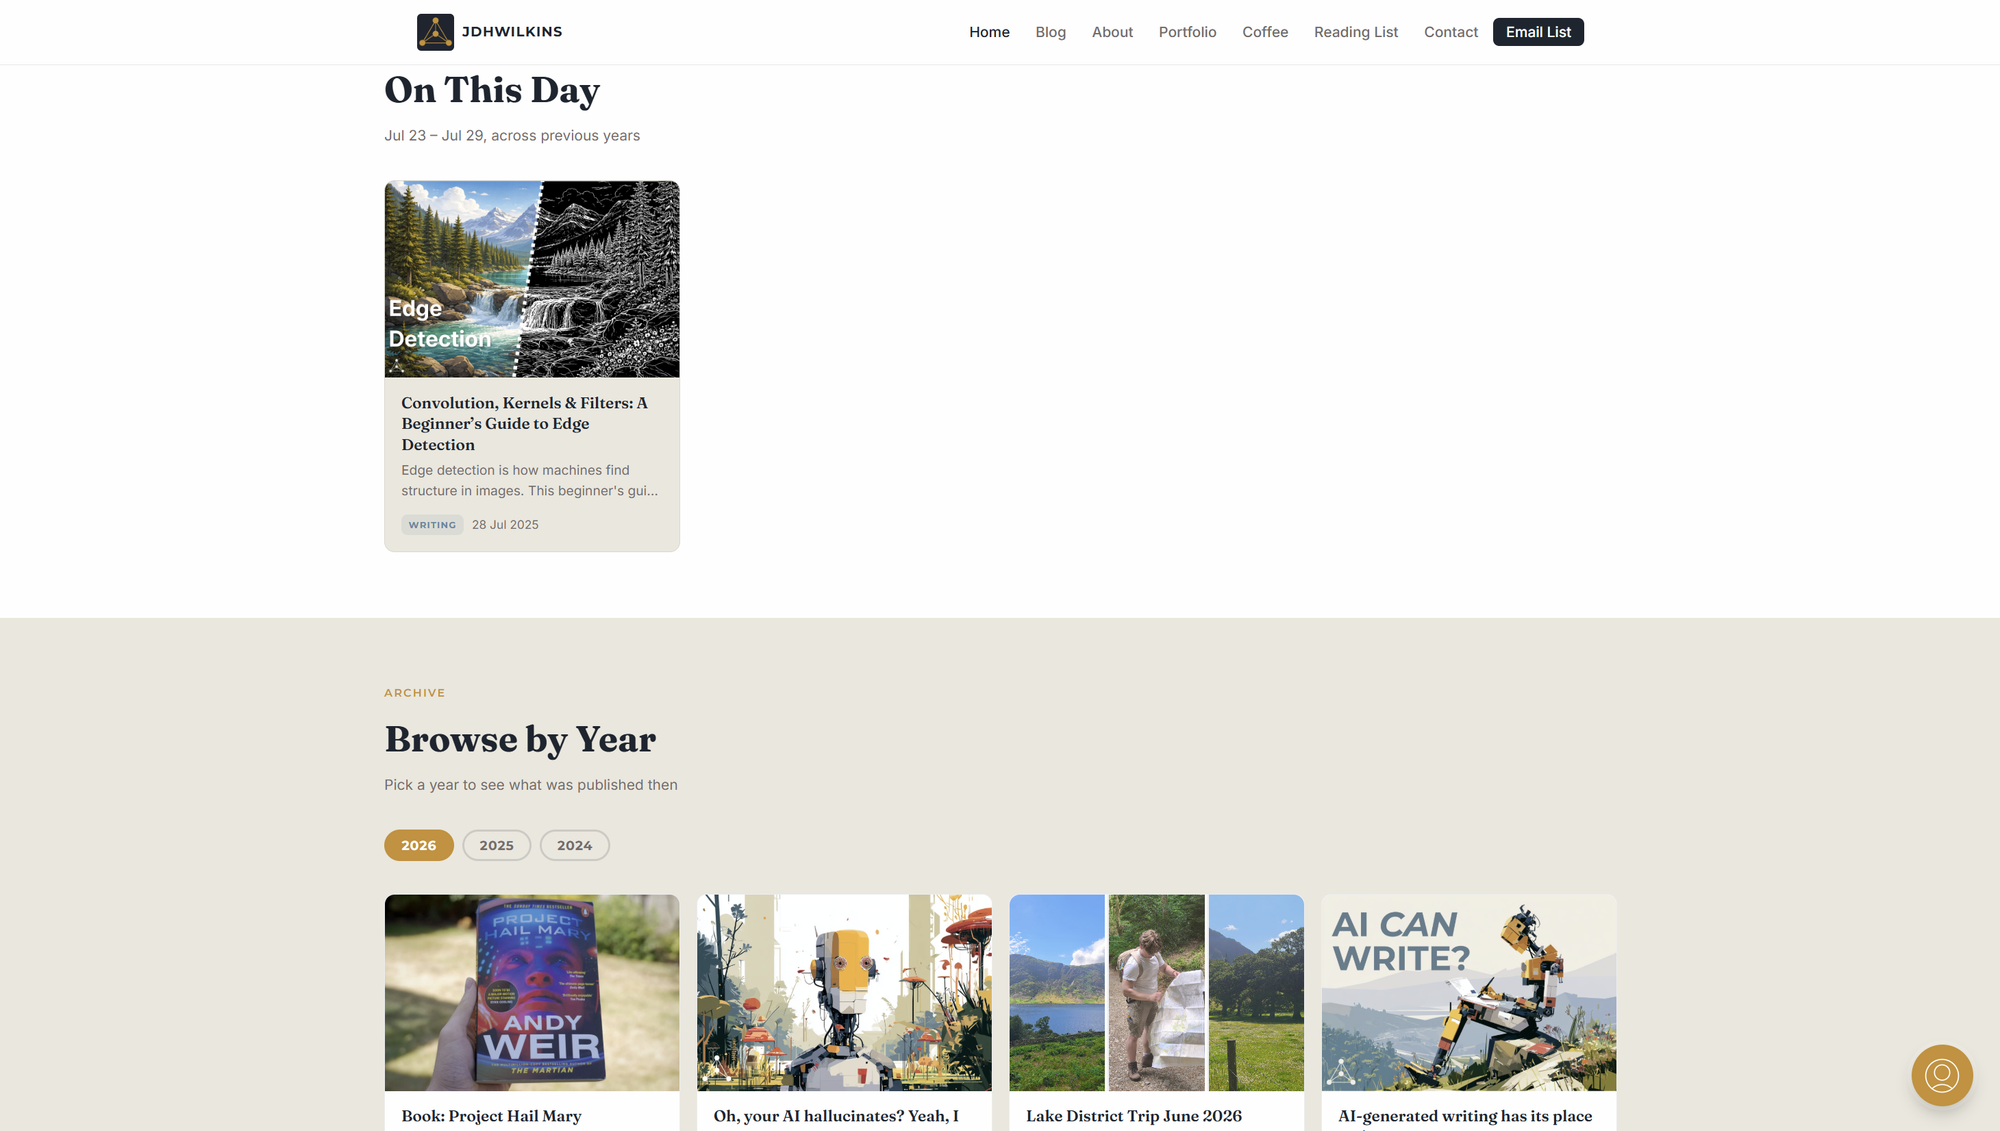
### Home Page
---
I created an animated logo and text for this site.
0:00
/0:11
1×
---
---
---
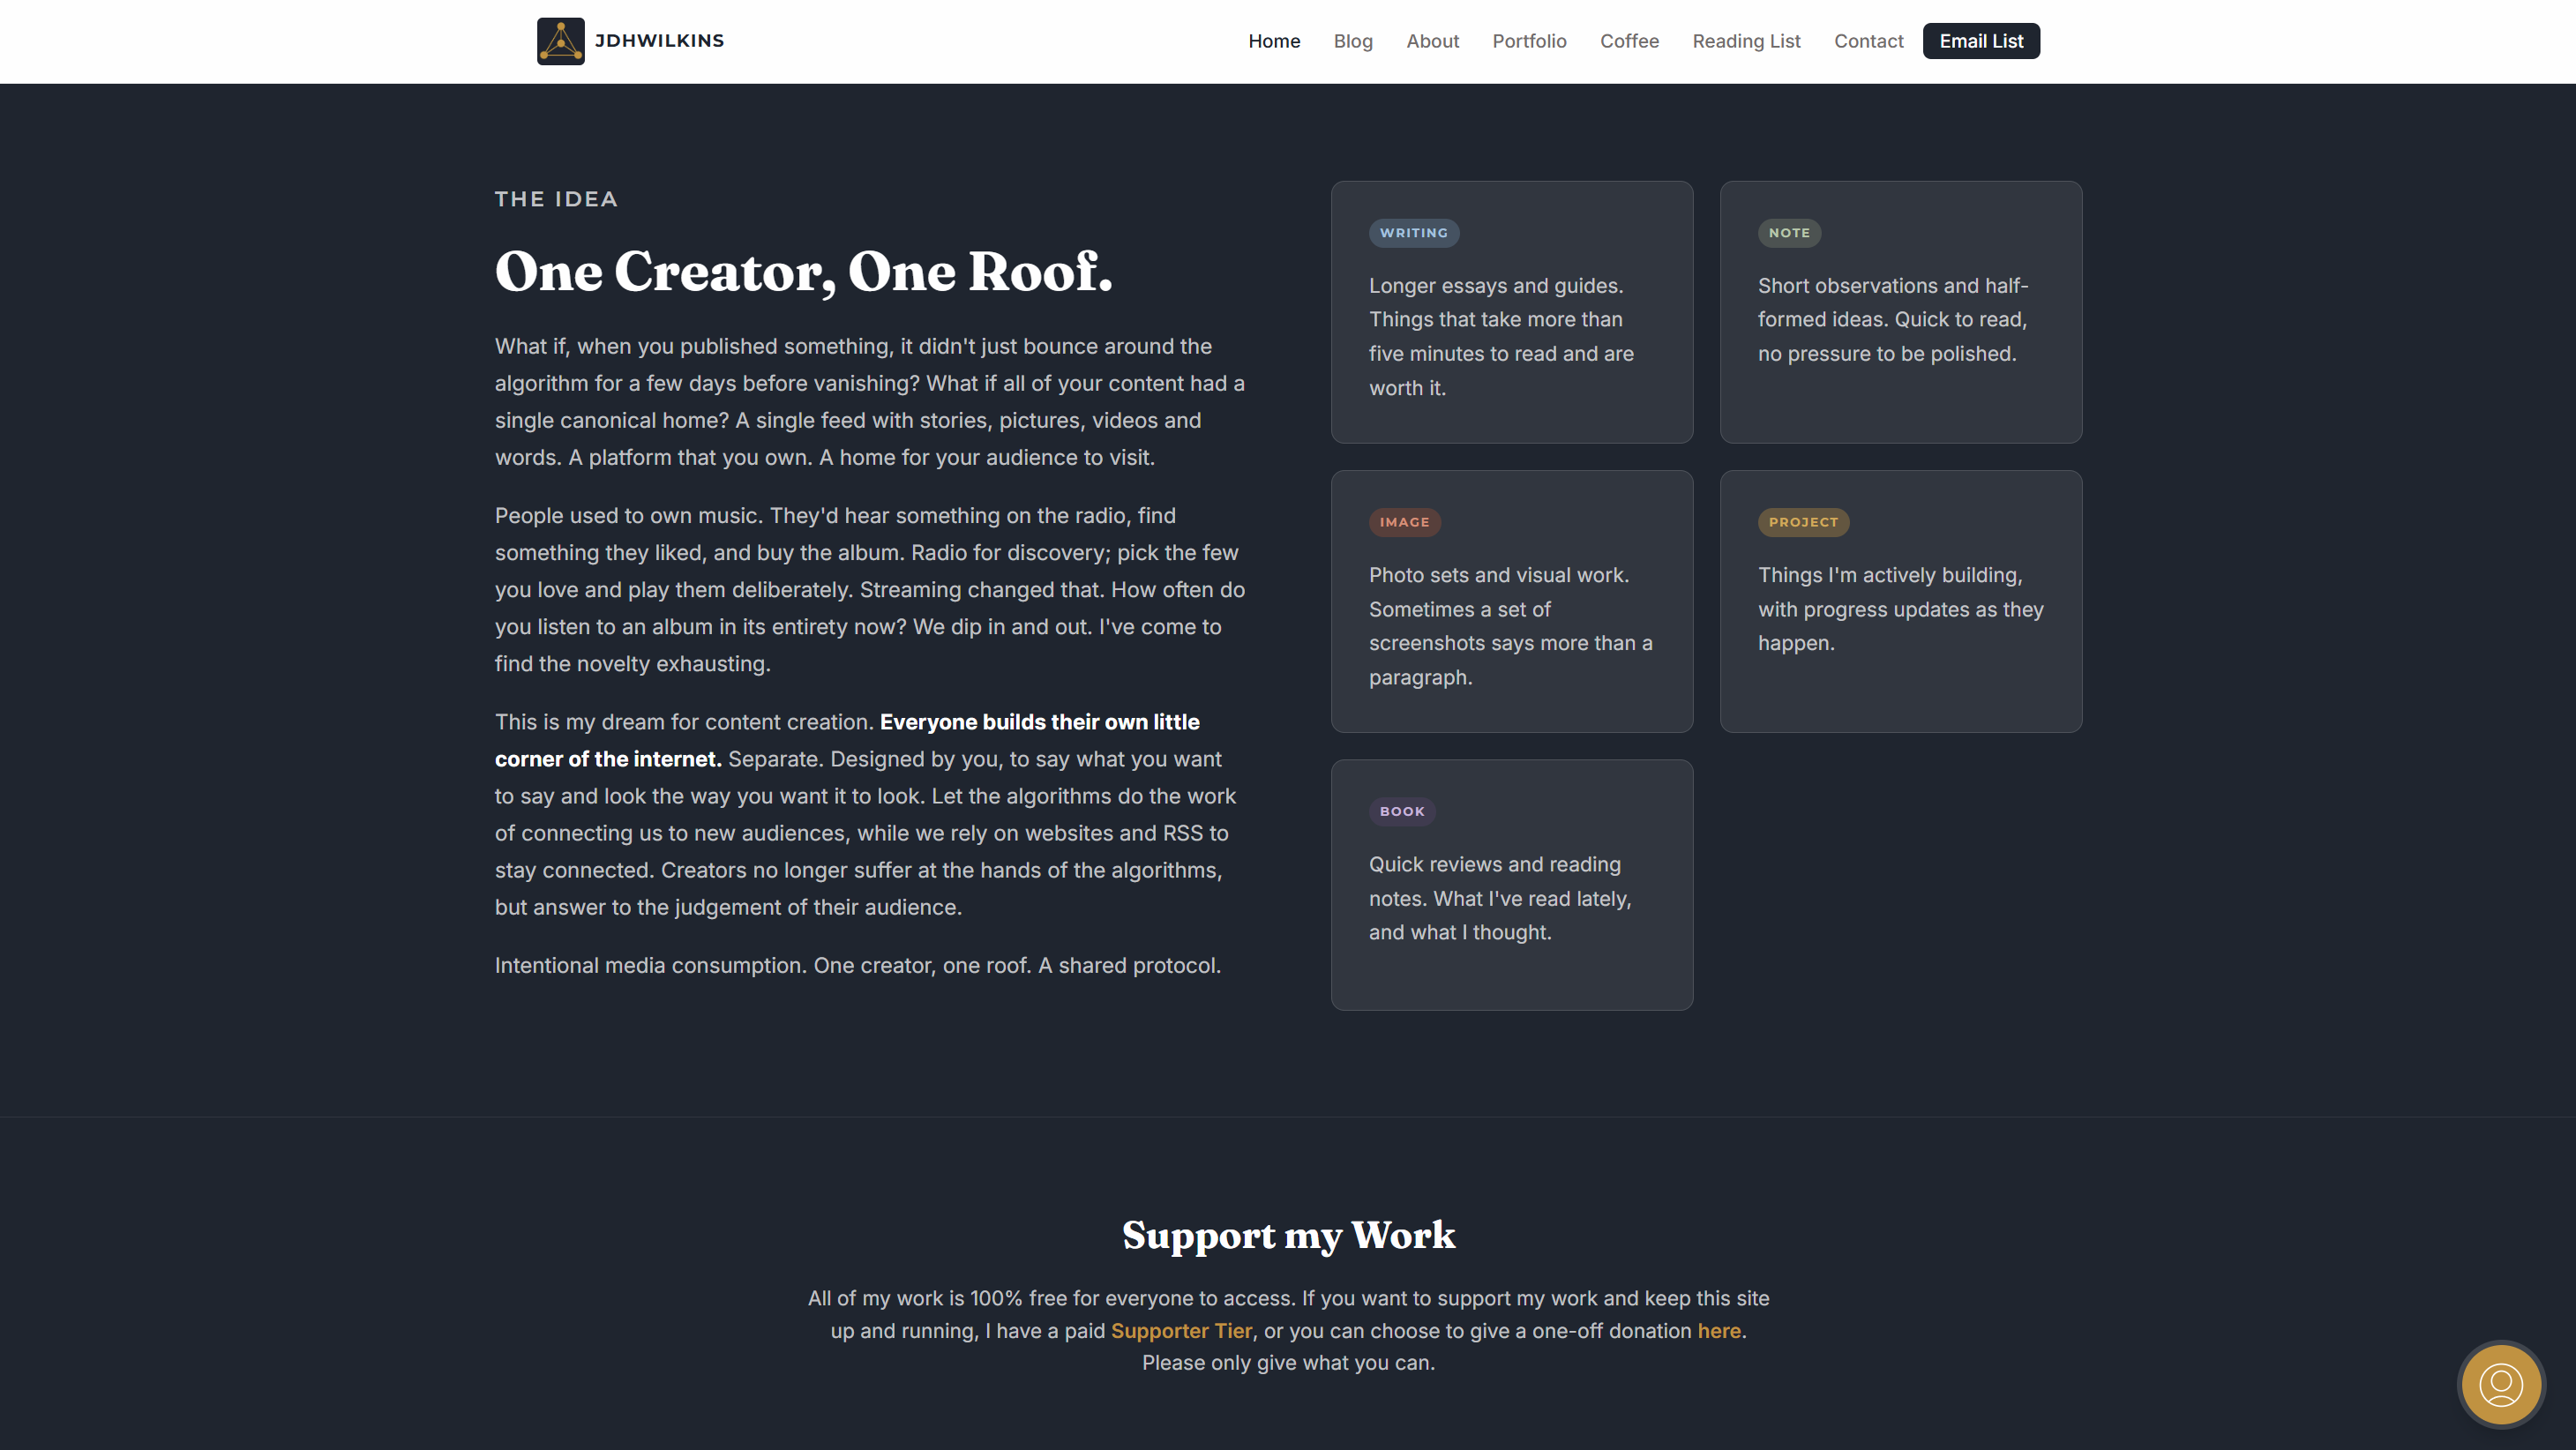
#### Blog Manifesto
---
### Blog Feed
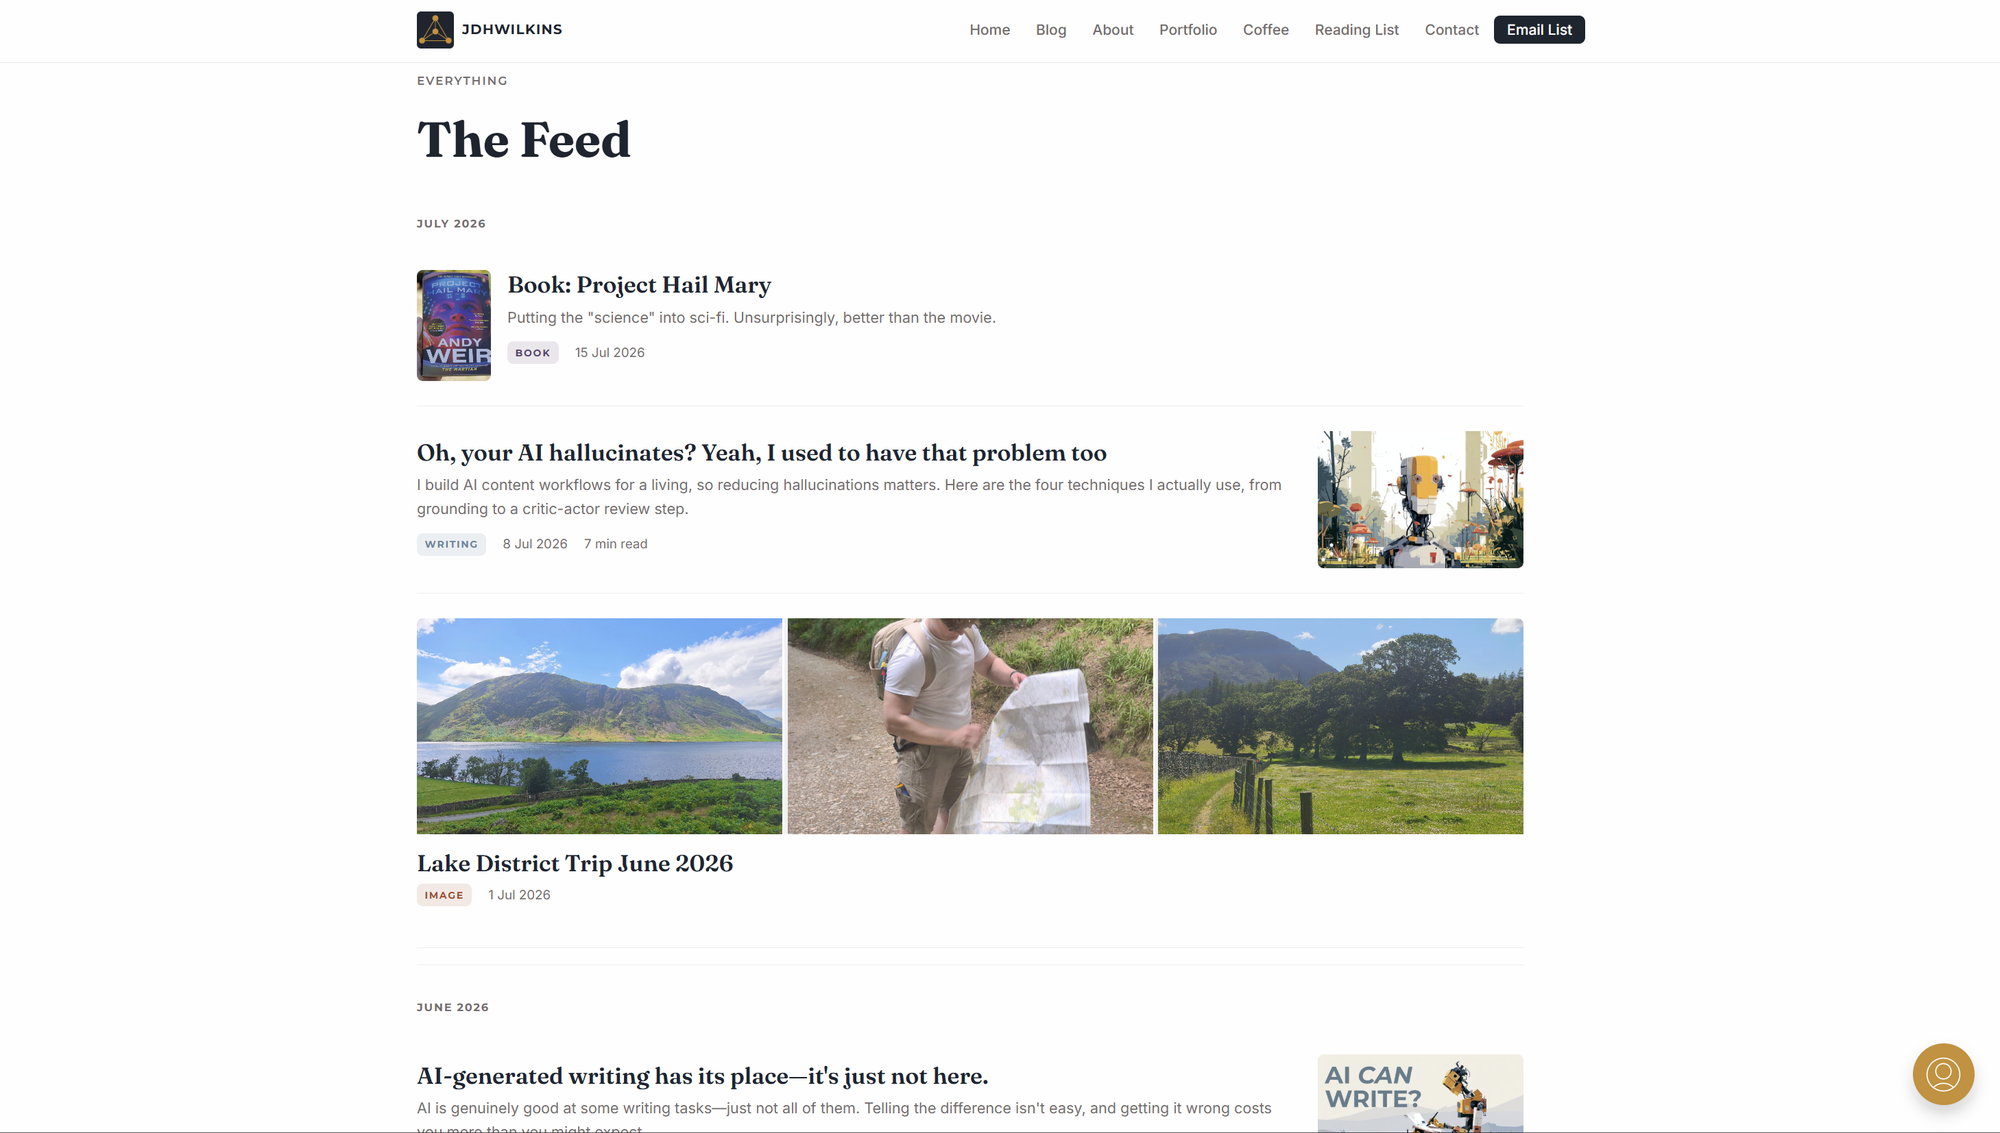
---
### About Page
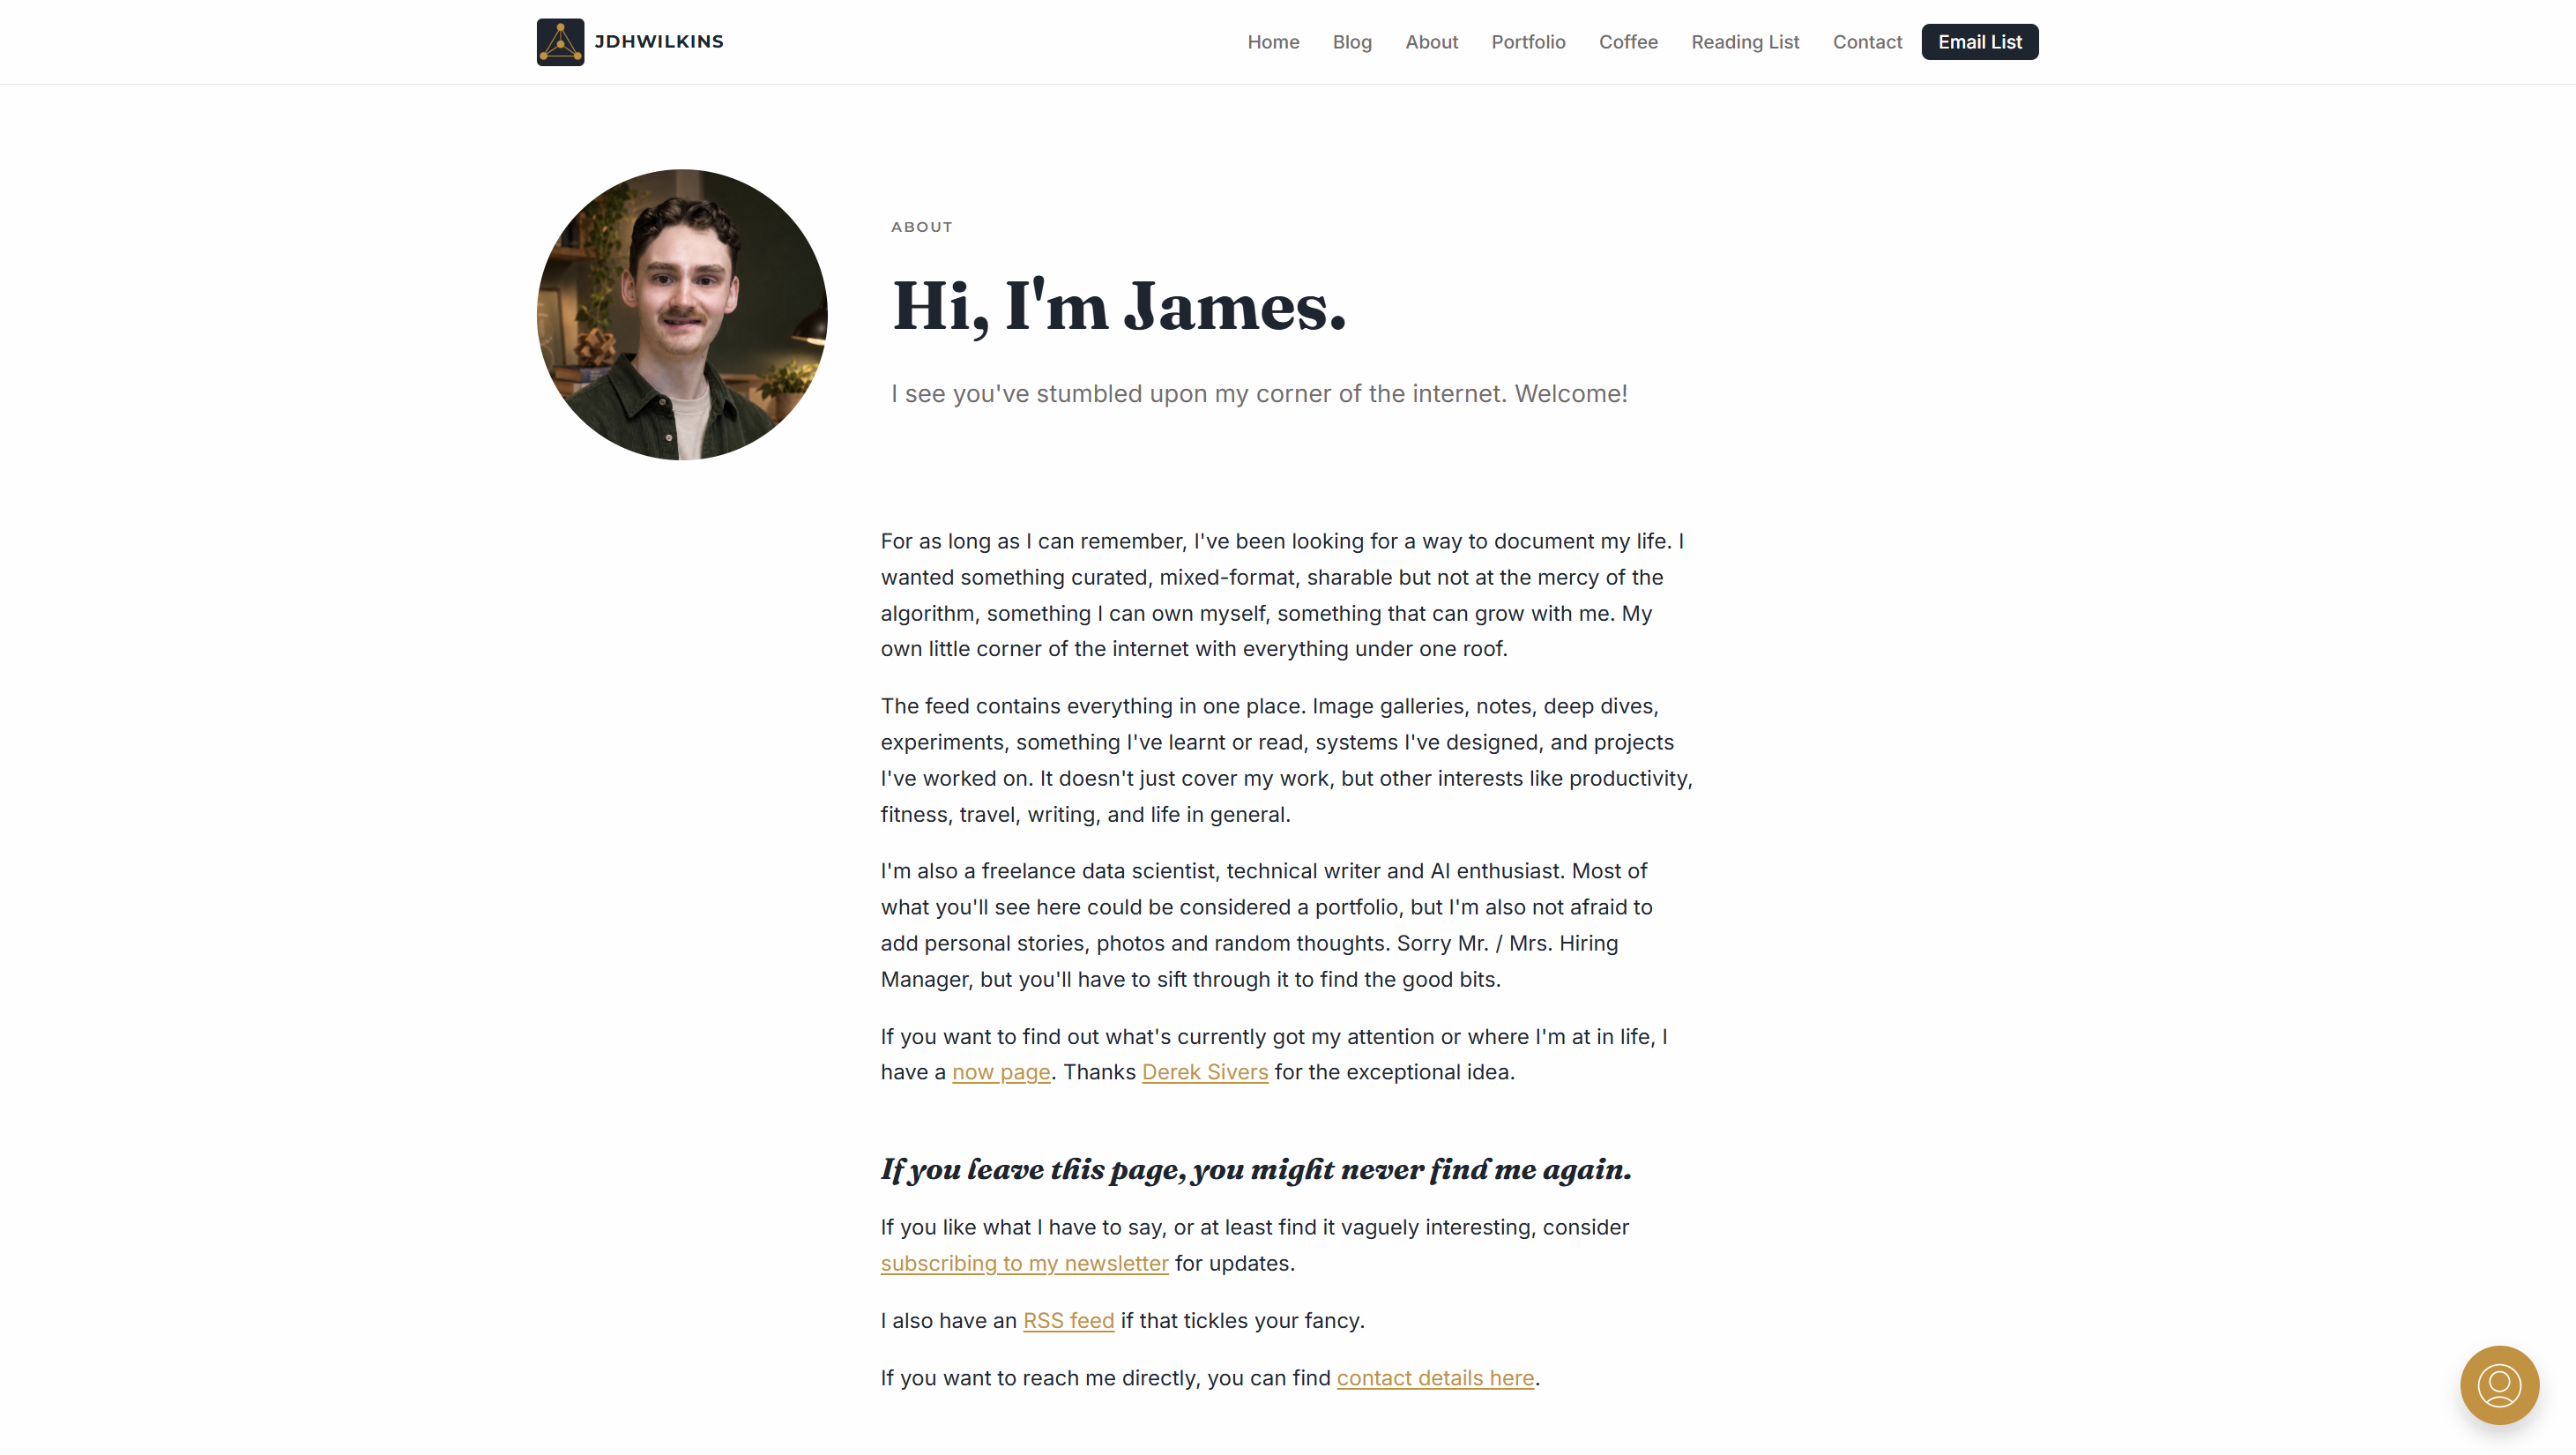
---
### Portfolio
---
### Coffee
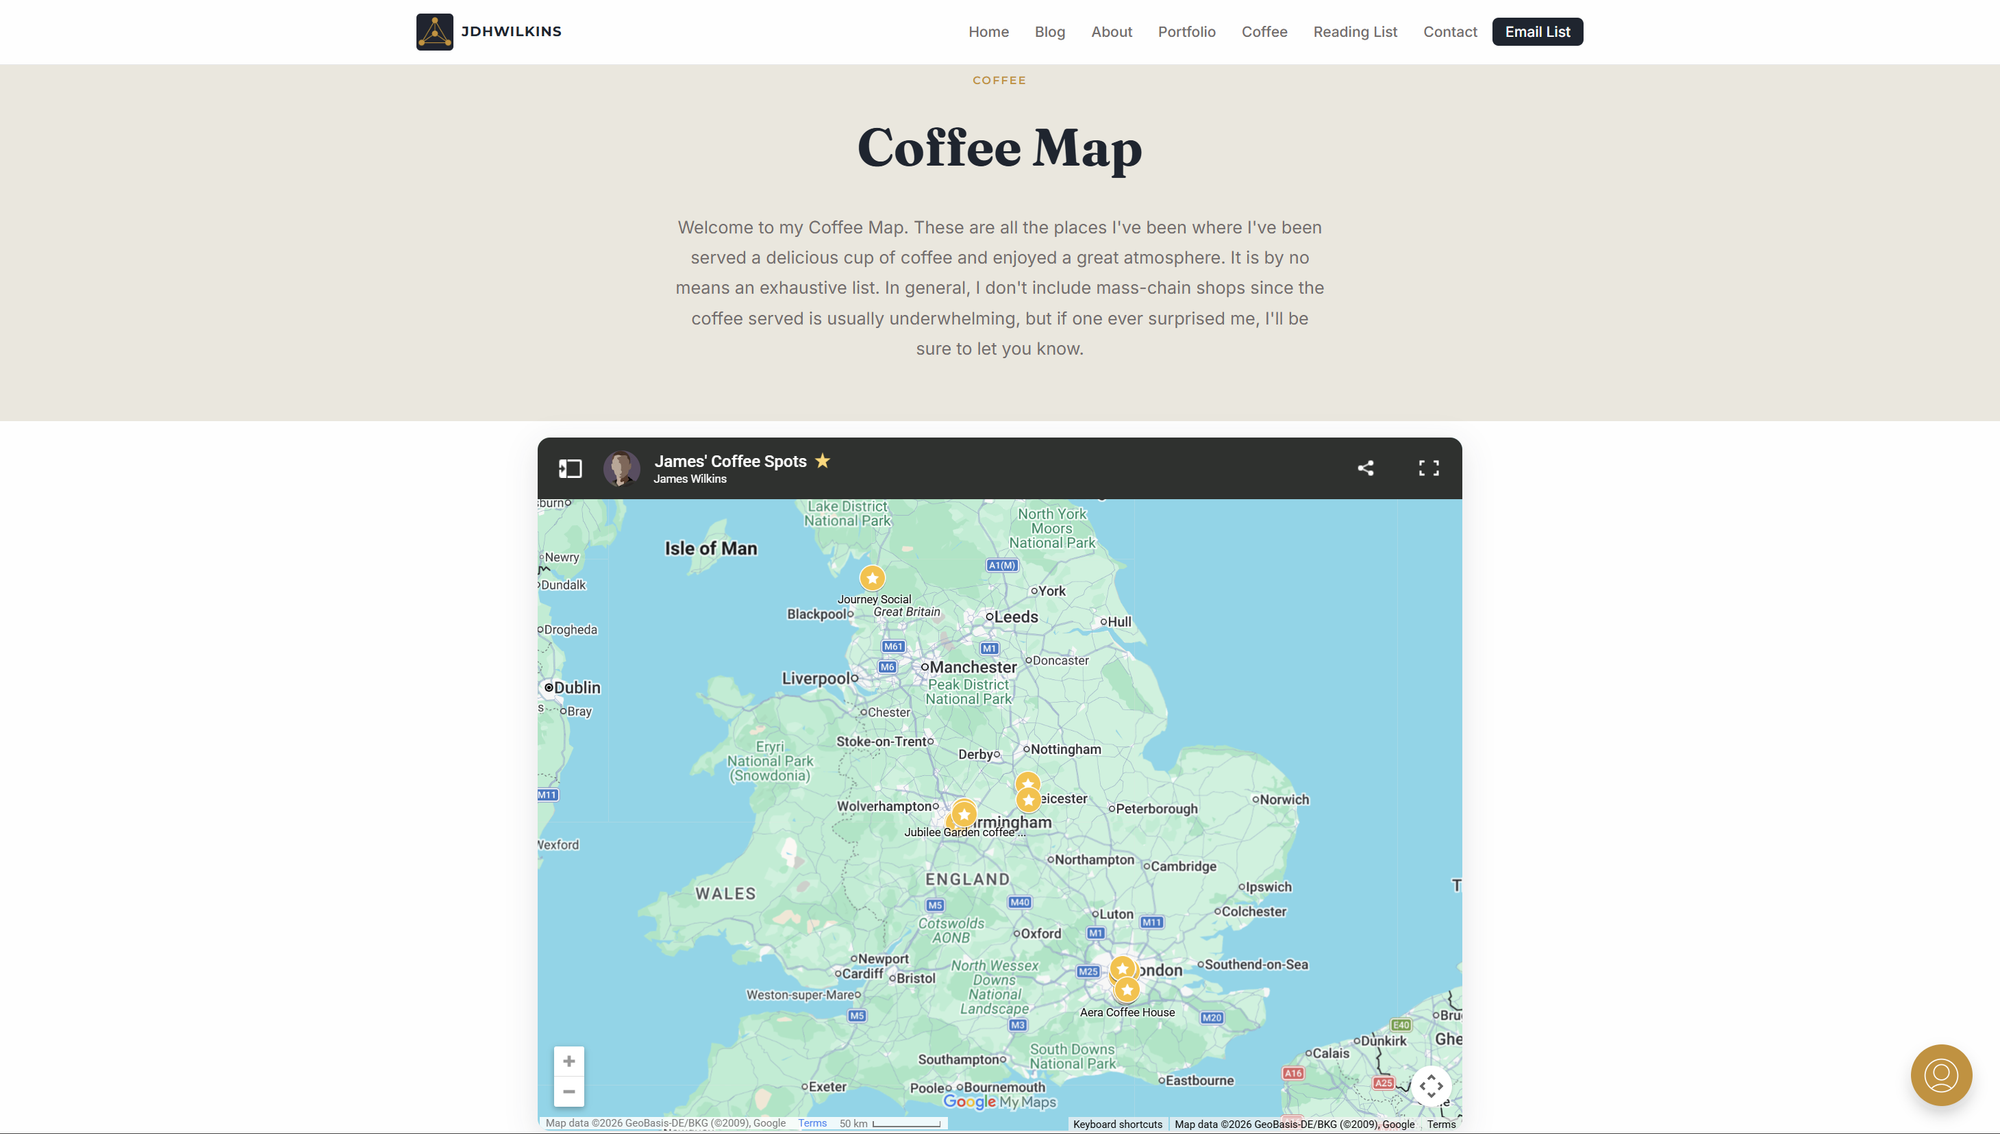
---
### Contact
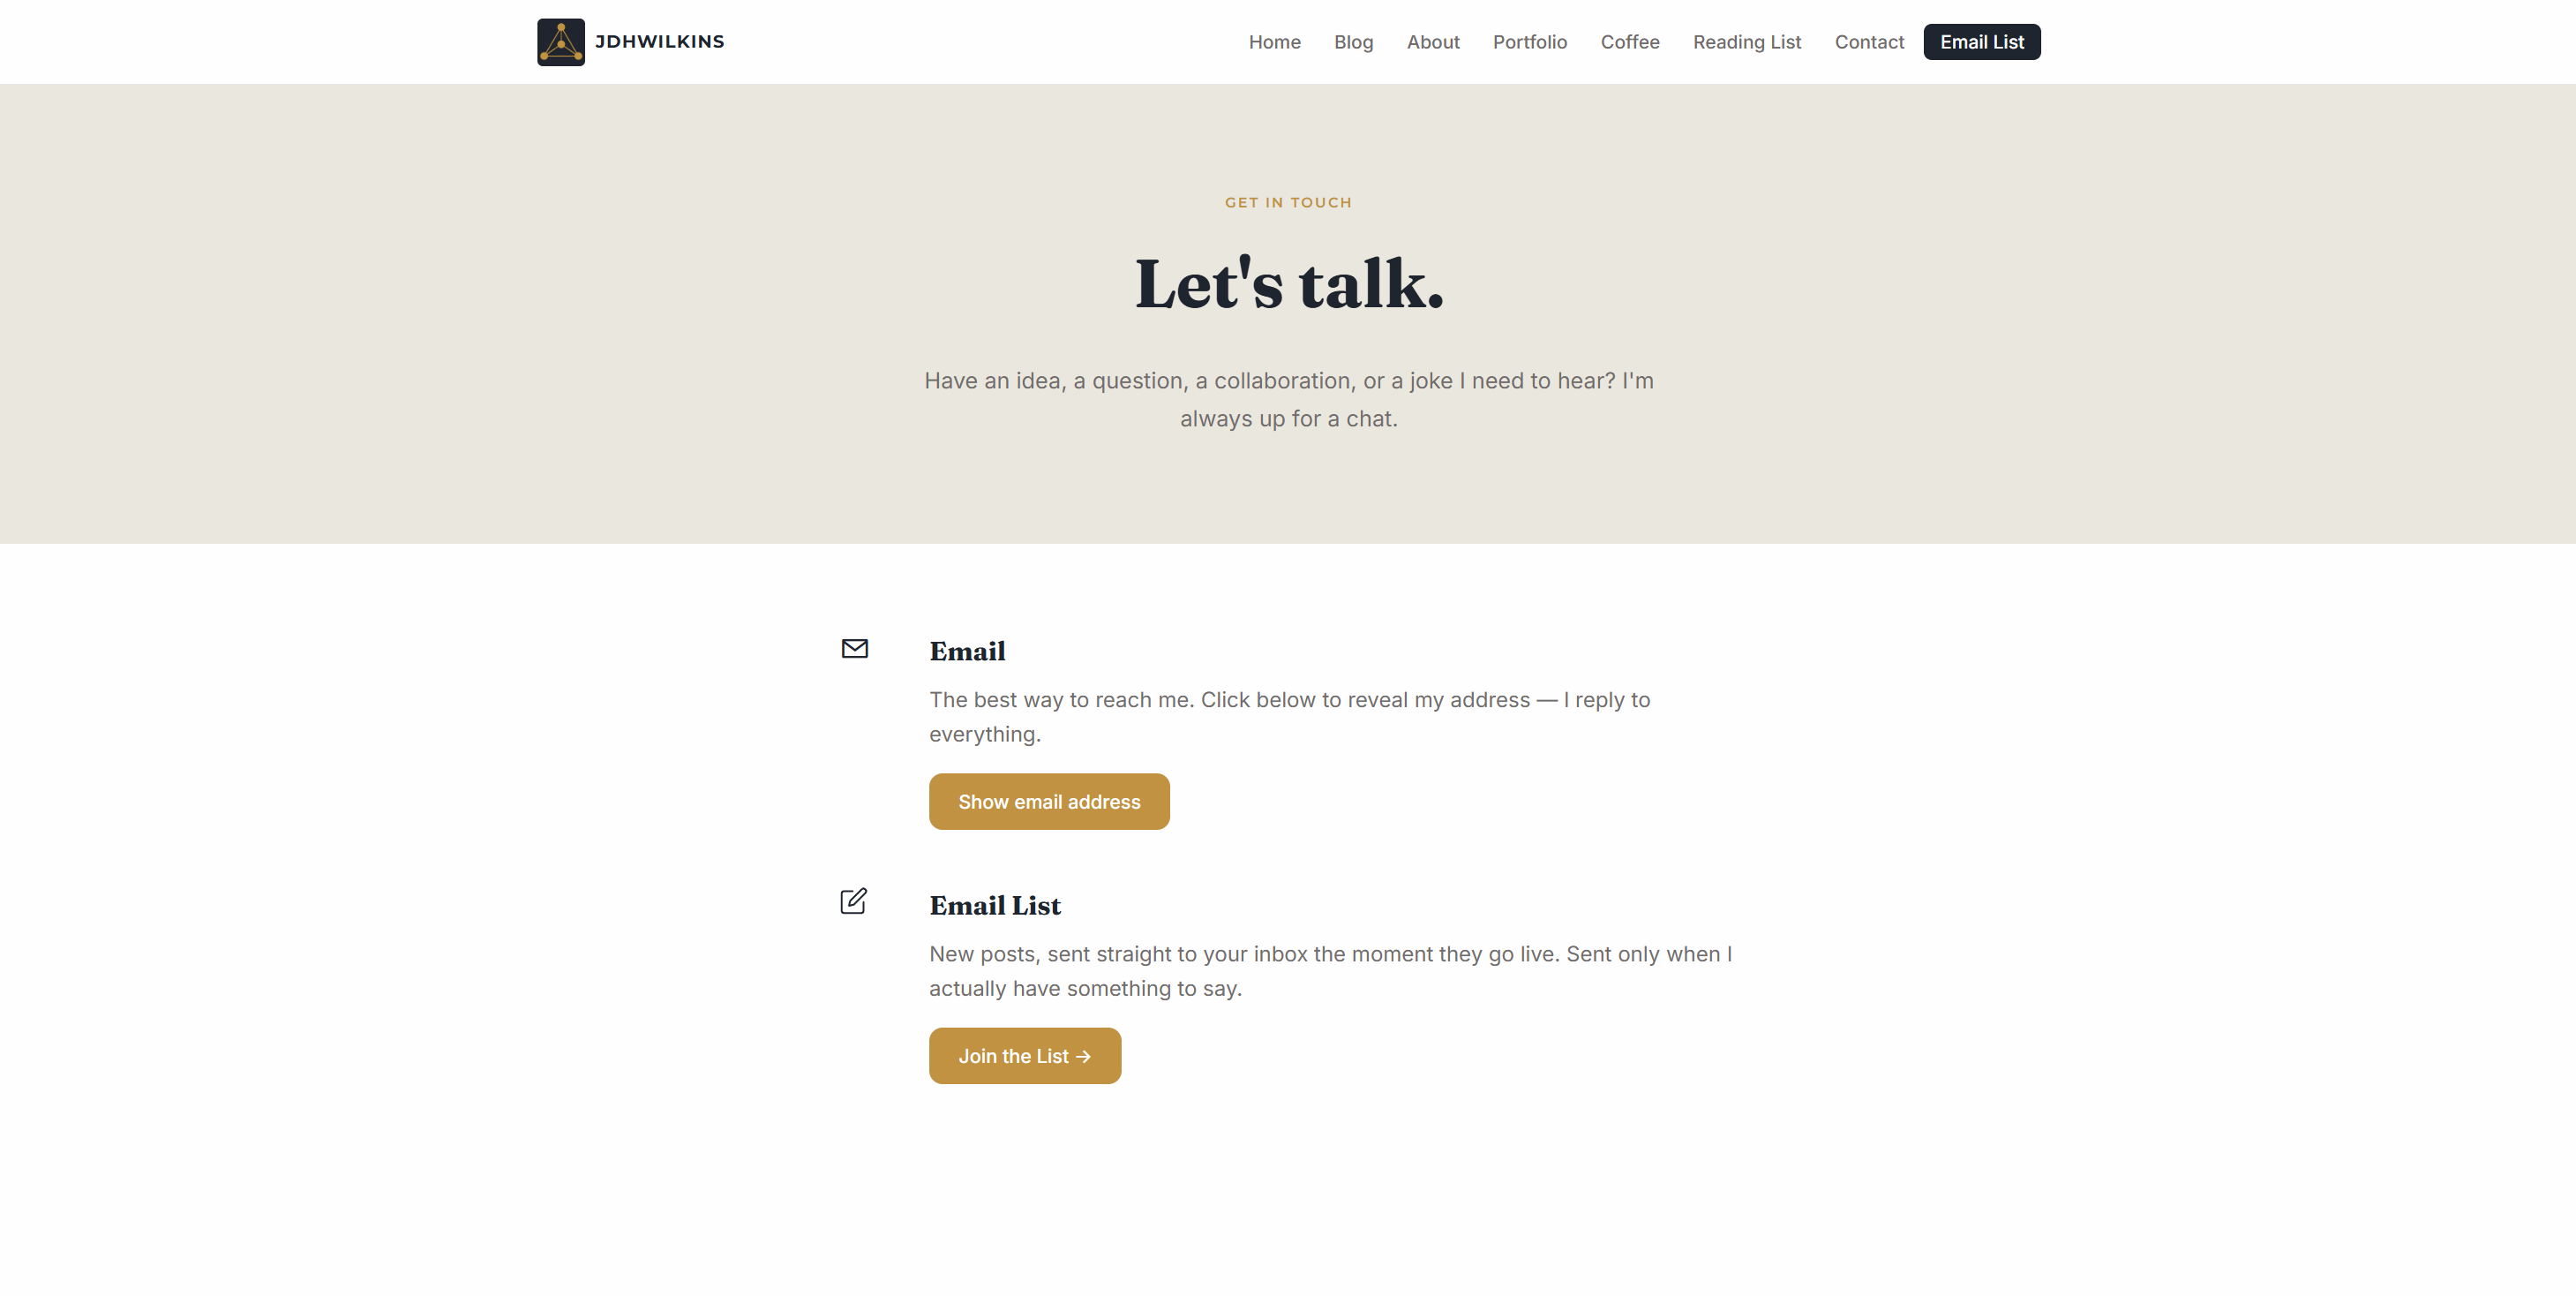
---
### Email List Landing Page
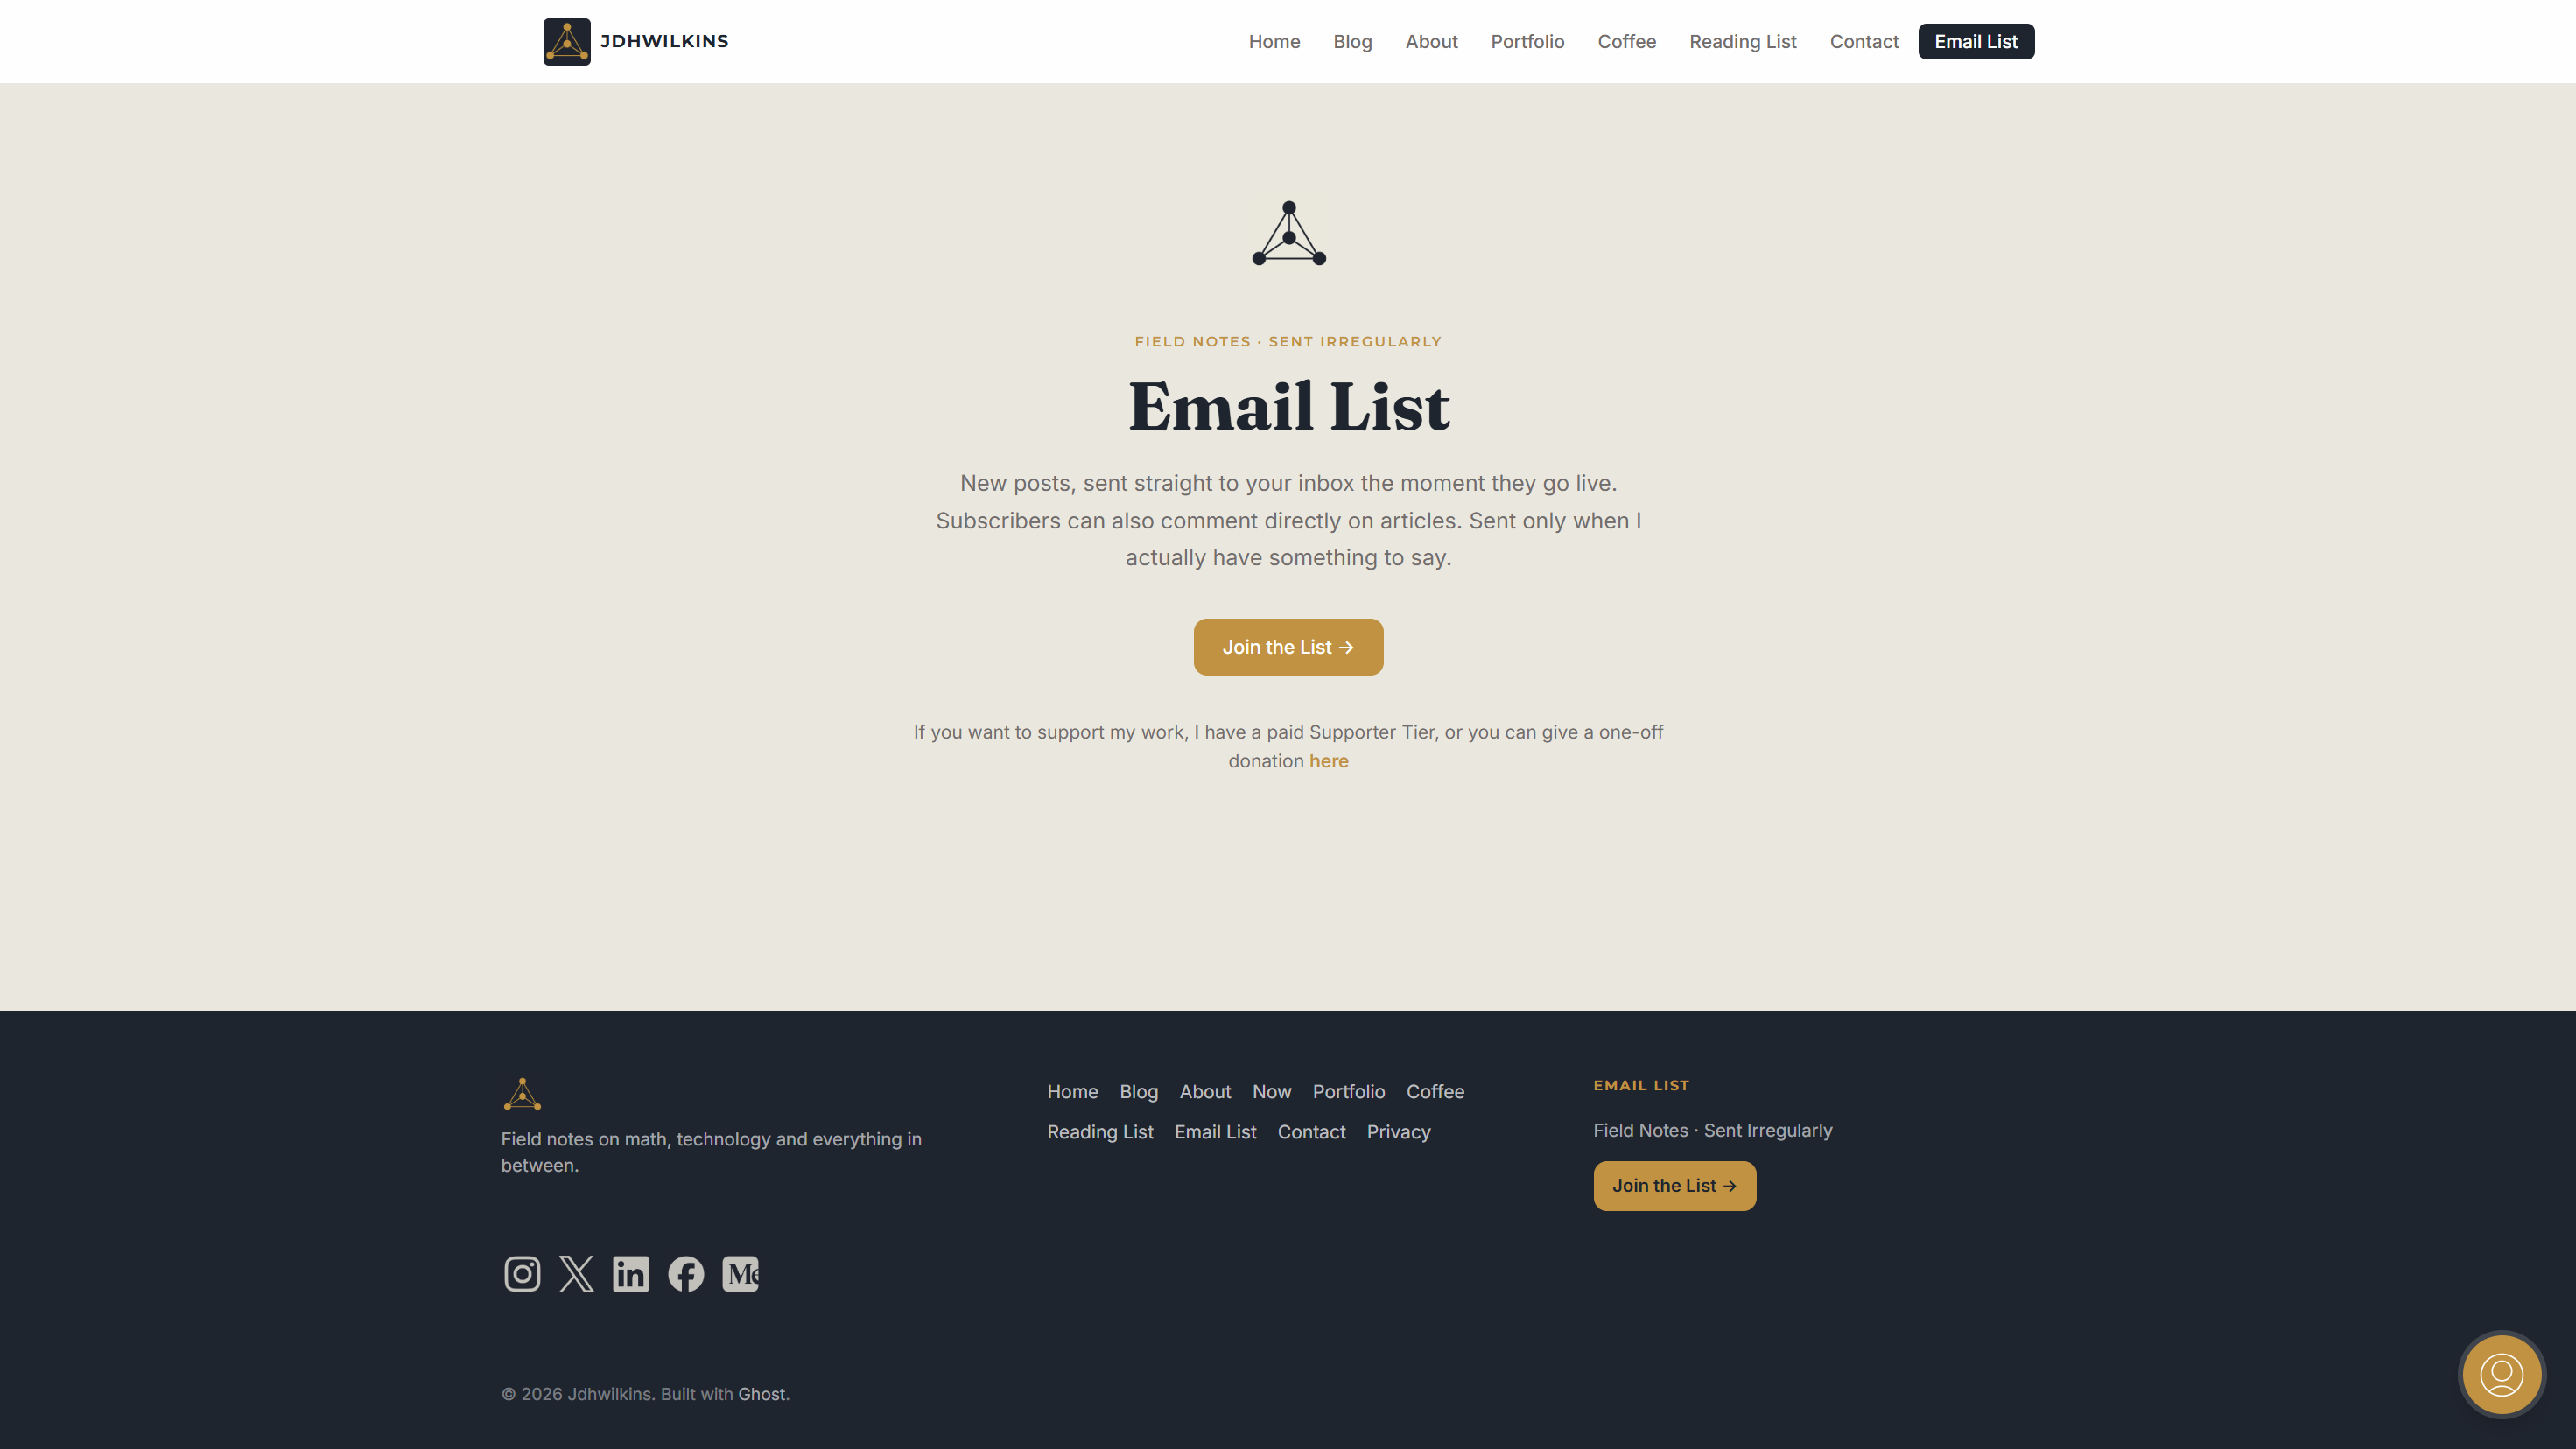
---
### Now Page
Updated 30 May 2026
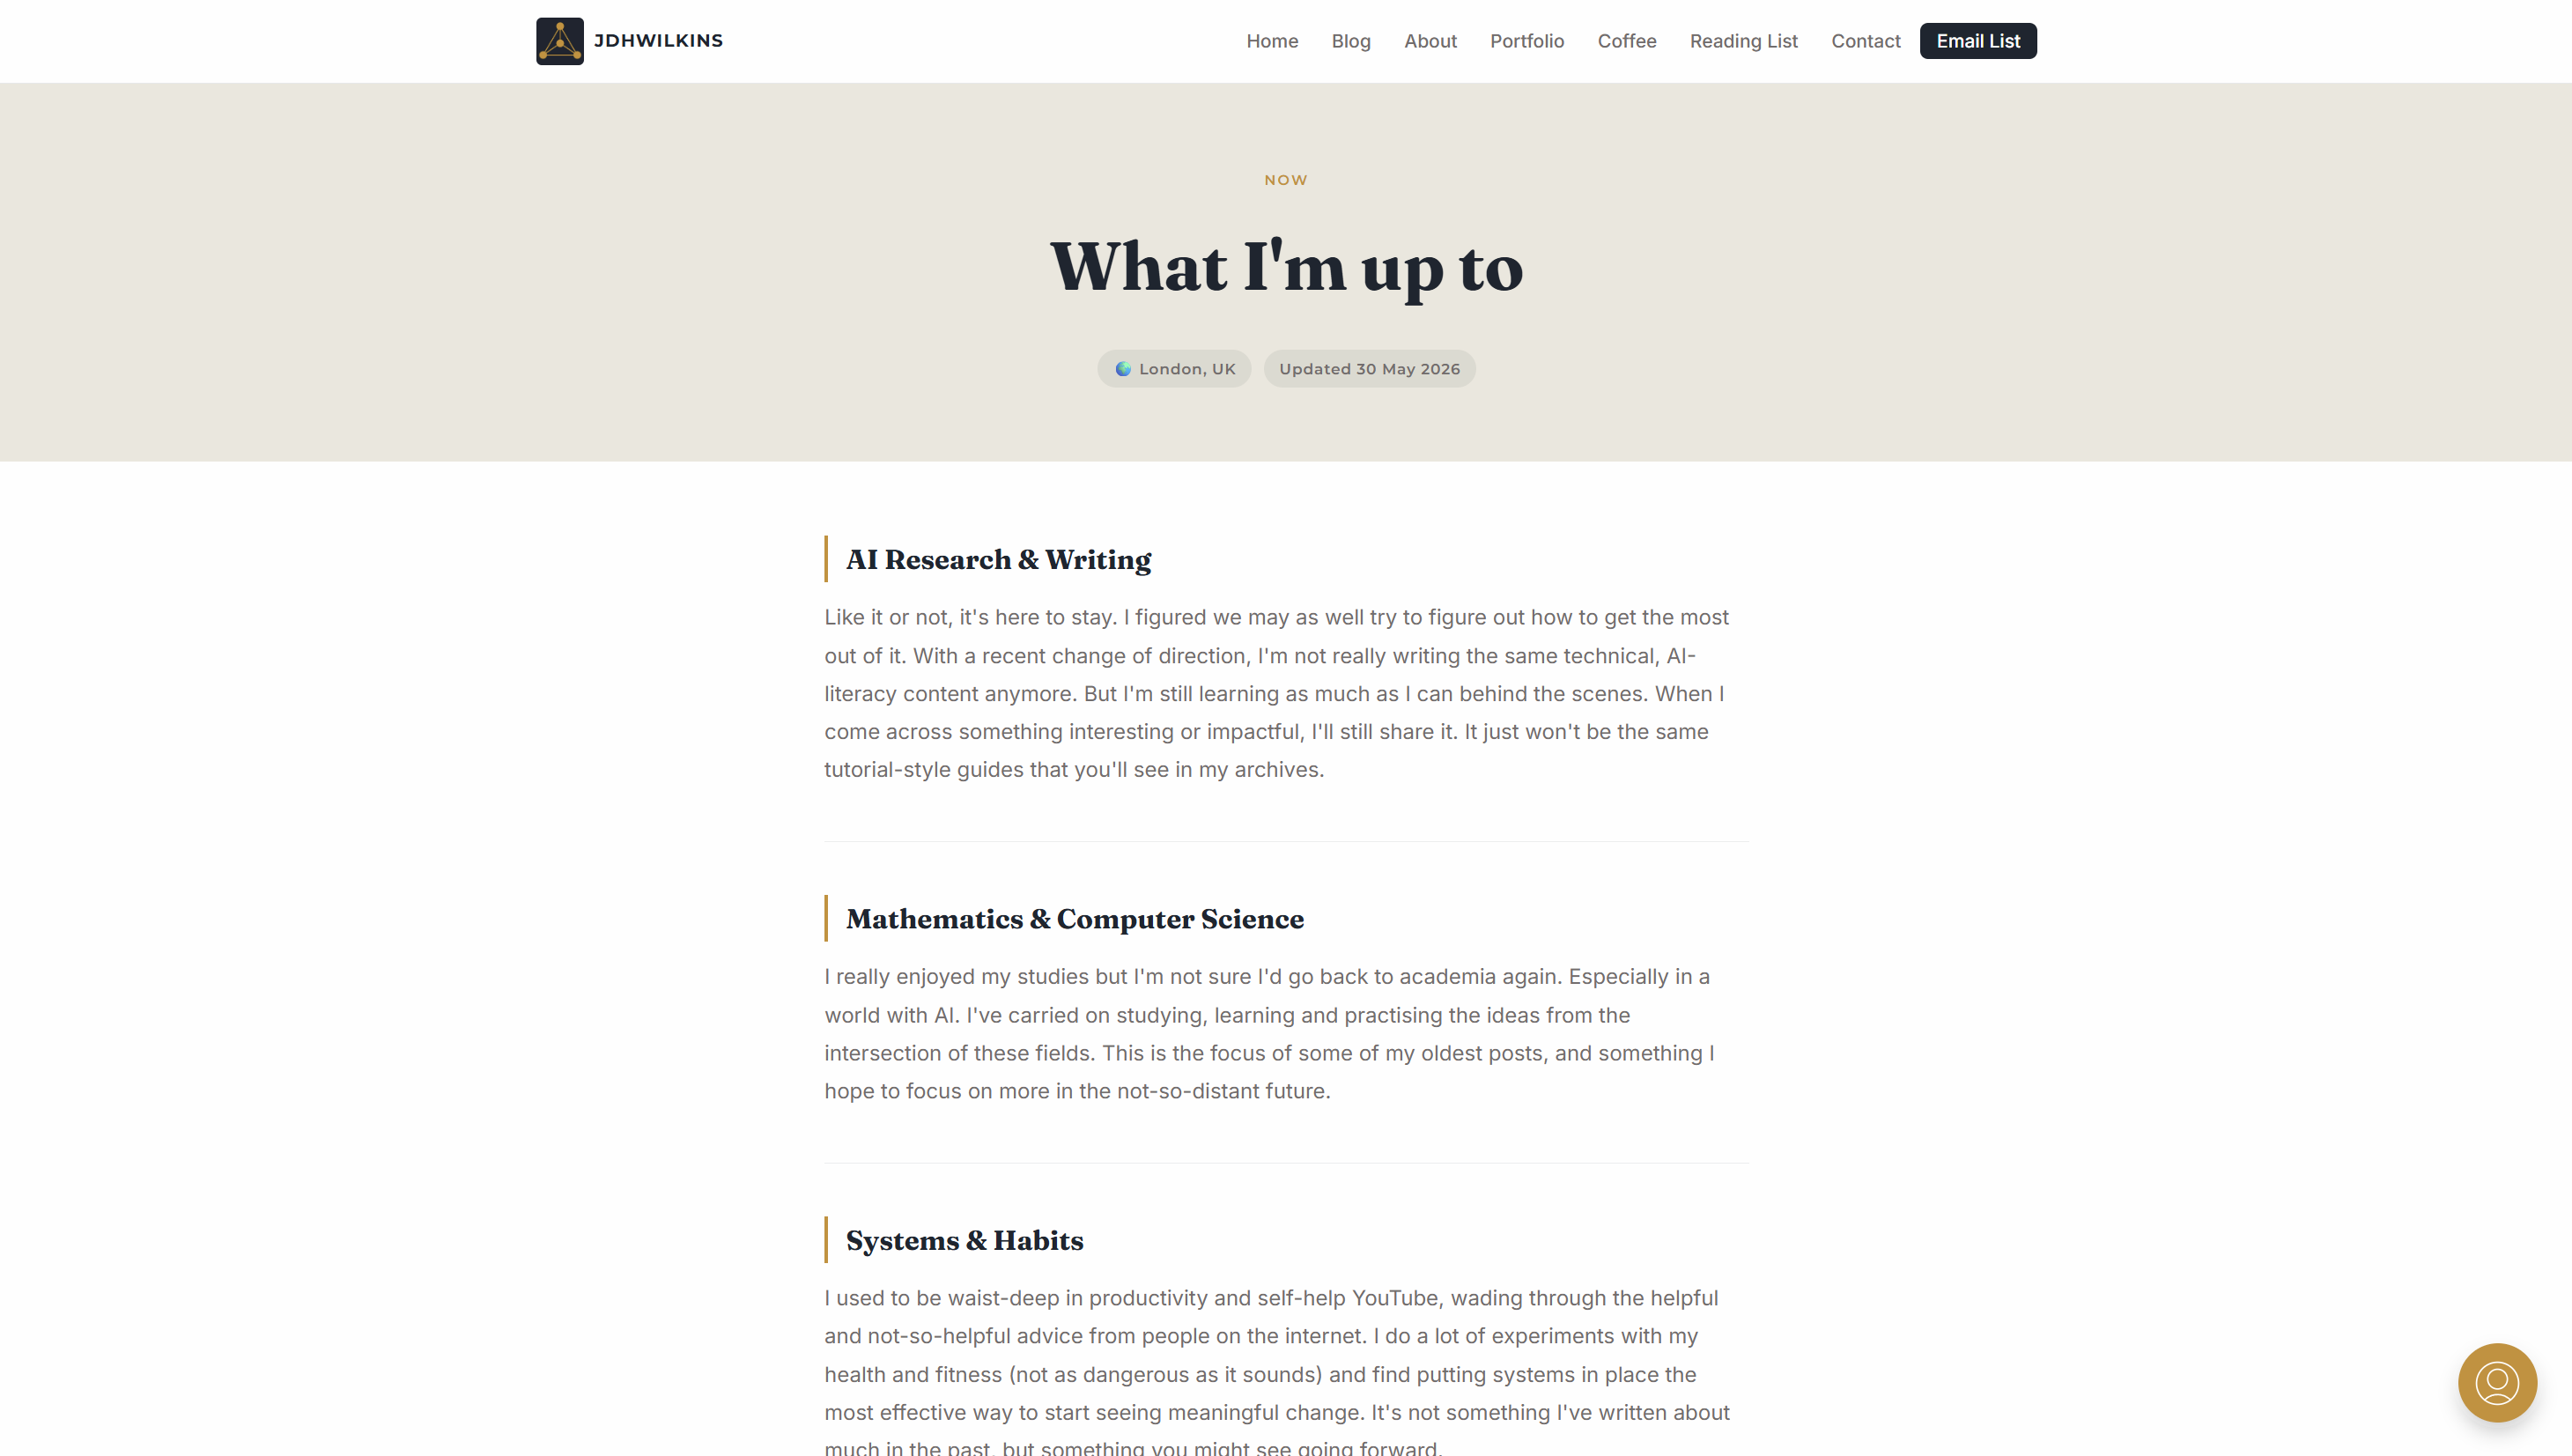
#### 'Now' — what I was up to back then
##### AI Research & Writing
Like it or not, it's here to stay. I figured we may as well try to figure out how to get the most out of it. With a recent change of direction, I'm not really writing the same technical, AI-literacy content anymore. But I'm still learning as much as I can behind the scenes. When I come across something interesting or impactful, I'll still share it. It just won't be the same tutorial-style guides that you'll see in my archives.
##### Mathematics & Computer Science
I really enjoyed my studies but I'm not sure I'd go back to academia again. Especially in a world with AI. I've carried on studying, learning and practising the ideas from the intersection of these fields. This is the focus of some of my oldest posts, and something I hope to focus on more in the not-so-distant future.
##### Systems & Habits
I used to be waist-deep in productivity and self-help YouTube, wading through the helpful and not-so-helpful advice from people on the internet. I do a lot of experiments with my health and fitness (not as dangerous as it sounds) and find putting systems in place the most effective way to start seeing meaningful change. It's not something I've written about much in the past, but something you might see going forward.
##### My Website
My site used to live on WordPress, then Wix, now I'm with Ghost. I first launched it in August 2024, and my content has changed direction many times in the 18 months since. I expect it will continue to do so going forward.
### Oh, your AI hallucinates? Yeah, I used to have that problem too
URL: https://www.jdhwilkins.com/oh-your-ai-hallucinates-yeah-i-used-to-have-that-problem-too/
Last updated: 2026-07-08T11:00:11.000Z
## The 4 levels of reducing hallucinations in your AI-assisted work
I build a lot of AI content workflows. Data analysis, newsletters, blog posts, reports, and news aggregations. Basically, anything where you take some source material, add some AI wizardry, and out pops something readable, usable, and ready for a final review before distribution.
It may not come as a surprise when I tell you that AI isn't the most, shall we say, *reliable* tool out there.
Achieving a 100% accuracy rate is infeasible without a human in the loop, but by using the right techniques, we can get pretty close.
You don't need to be an AI engineer to get something out of this advice. What follows are all techniques you can apply to normal everyday AI use to improve accuracy and reduce hallucinations.
## Level 1: Grounding
**Grounding** is a technique where you provide the AI model with the specific information it needs to write its response rather than having it guess.
If you had asked AI to write you a blog post a couple of years ago, it would have relied on its training data alone.
Models are trained by feeding them enormous amounts of text. They learn how to speak from millions and millions of examples, but they also pick up on some facts and information too. However, relying on this training data alone results in really high hallucination rates.
The better approach, and what you'll see most models doing nowadays, is searching the internet to find some relevant sources before writing the response. Once they have read the reference material and it has been added to their [context window](https://www.jdhwilkins.com/tokens-and-context-windows-what-they-are-and-why-they-matter/), their accuracy in recalling it skyrockets.
This is a process known as grounding. You provide a model with the specific information you need it to refer to, and it is able to produce a far more accurate result with a far lower risk of hallucinations.
We can use this to our advantage by directing the model to refer to a specific web source—one that you actually trust and have vetted rather than whatever Wikipedia-like nonsense the model might otherwise choose itself.
If your task involves proprietary information (maybe a custom dataset, internal company documents, or other super-specific information that isn't publicly available on the internet), upload it directly.
If you've ever heard the term RAG being thrown around, this is the underlying principle that it relies on.
The job of a RAG system is to quickly fetch relevant snippets of information from documents and add them into prompts behind the scenes so that the model has accurate information to refer to when writing its response.
You can use tools like [NotebookLM](https://notebooklm.google.com/?ref=jdhwilkins.com) where the grounding is restricted specifically to the files and links you supply. It will also provide you with citations and references to the original source so you can quickly fact-check anything that doesn't quite look right.
## Level 2: Task Decomposition and Specificity
Going one step further, we should consider how simple or complex our prompts are. Long, complex, multi-step prompts are only asking for trouble. If you need accurate results, have the model perform smaller steps at a time. Don't ask for an entire article in one go; ask for one section at a time and only supply it with the source material relevant to that section.
I used the same idea recently to build a workflow for generating data reports. We broke the report down into sections and gave the model only the data relevant to one section of the data at a time.
This brings us nicely on to level 3...
## Level 3: Context Window Management
The context window is like the working memory of an AI model. If you keep using the same chat, the model has persistent memory of everything that has happened so far, but start a new conversation, and you have a blank slate—a separate context window.
The more data you add to the context window through your prompts, the lower the model's accuracy in recalling any one specific piece of information is. What this means is that, for tasks requiring really high-accuracy outputs, break the task down into individual components and use a separate chat for each one. Each should contain only the necessary information to complete that portion of the task and nothing else.
This is less important for short conversations with a few back-and-forth messages, and more important for hour-long conversations. In some tools (like Claude Code or similar agent platforms), once a conversation gets long enough, older history starts being compressed and summarised automatically to save space, which is another reason to keep individual chats focused.
Relatedly, this is less important if you have multiple messages related to the same task and more important when you want to change to a new task or idea. In general, when the context and current conversation are no longer relevant, open a new chat and start fresh.
## Level 4: Critic-Actor Framework
So you sent your prompt, and you have your output. Now it's time to review. There's no reason we can't use AI to help with this too.
We can use an approach known as a **critic-actor framework,** where one instance of a model produces the work, and another criticises and reviews it.
Open a new conversation and supply the ground-truth source material as well as the AI-generated output you want to check. It's important not to continue in the same chat, as LLMs have been shown to favour their own output even when it's wrong. Ask the model to review all of the claims, facts, and figures and ensure they align with the source. As before, accuracy will improve here if you only supply the relevant portion of the source material rather than the entire thing (more so if the source is a particularly long PDF or large dataset). Using a restrictive grounding tool or RAG system like NotebookLM can be beneficial here too.
Often, the sorts of mistakes that may have been introduced aren't explicit errors, but claims that have been overstated, exaggerated, or twisted slightly in some way. Make sure to mention this to the model when you ask it to check the work so that it looks for the subtle differences as well as the completely outlandish false claims.
To push this one step further still, we can incorporate models from completely different families to reduce their shared 'blind spots' or tendency to make the same mistakes. It's worth noting this reduces but doesn't eliminate the risk — research shows models from different providers can still make correlated errors when their training data overlaps.
## Designing your workflow
Ultimately, no matter how many measures you put in place, the only way to completely guarantee accuracy is to have a human review your work. The notion of human-in-the-loop is designed to combat this exact problem. We ensure that a human remains involved in critical steps in an AI-assisted workflow to ensure quality and accuracy and to incorporate the influence of style and taste that an AI model cannot bring.
For many writing and content workflows, it's only really necessary to have a human involved at the start and the end:
- Qualifying and preparing source material
- QA of the final output and altering sentence structure to read more naturally
Everything else can be outsourced as part of the AI workflow.
This is not going to give you a piece of brilliant literature, but often, that's not the goal. Aggregating and synthesising information, making it suitable for the audience to understand, and presenting it in an appropriate way.
### The Simplicity-Accuracy Trade-off
With the confidence that, if there are any errors in the output, you will catch them yourself at the end, you can start making more informed choices about the suite of tools you use. We may still want to improve the accuracy of the output as this reduces the time taken to check and alter the final output, but if we could make the workflow dramatically simpler in exchange for a *slight* potential accuracy reduction, wouldn't that be worth it?
Pick and choose from the above advice to maximise accuracy and QA gains while keeping things as simple and straightforward for yourself as possible.
One writing workflow may be:
- Use Gemini to research some sources and review them manually for quality and relevance
- Upload sources to NotebookLM and use a prompt template to craft your output
- Check manually using the provided citations
- Start a new notebook with the same sources and the previously generated output. Prompt it to review the claims for how well they align with the original sources, specifically looking for exaggeration and slight inaccuracies in the way claims are being reported
- Review the final output. It will likely be mostly correct, but you should still check.
That's 3 separate model instances, 2 different tools, and 2 human review points.
On the other hand, a different workflow might be:
- An automation exports the latest data source from your database
- An agent skill, with instructions on how to query the dataset using some code, is used by Claude to write a data analysis report in a specific format
- Have Claude spin up a subagent to independently review the output for quality against a style guide, then another subagent to review for data accuracy against the same source data
- Review the final output yourself before distributing
The subagent review will catch the majority of errors, but perhaps not with quite the same rigor as the NotebookLM workflow would. However, this second workflow would be far quicker to perform and could even be set up as a scheduled task to be completed before you even arrive at your desk in the morning.
Again, which one you choose will depend on the tools you are comfortable using, and how much time/how important the human QA step is.
While there are many steps we can implement to reduce hallucination rates, once you accept that keeping a human-in-the-loop is a necessary requirement for quality outputs, you can start making smarter tool choices.
## References and Further Reading
- [Lost in the Middle: How Language Models Use Long Contexts (Liu et al., arXiv)](https://arxiv.org/pdf/2307.03172?ref=jdhwilkins.com) — the foundational study behind Level 3; shows model recall accuracy drops significantly when relevant information sits in the middle of a long context rather than at the start or end.
- [Reducing LLM Hallucinations Using Retrieval-Augmented Generation (RAG)](https://www.digital-alpha.com/reducing-llm-hallucinations-using-retrieval-augmented-generation-rag/?ref=jdhwilkins.com) — overview of how grounding/RAG lowers hallucination rates in practice.
- [Hallucination Mitigation for Retrieval-Augmented Large Language Models: A Review (MDPI)](https://www.mdpi.com/2227-7390/13/5/856?ref=jdhwilkins.com) — survey of RAG's strengths and remaining limitations.
- [Council Mode: A Heterogeneous Multi-Agent Consensus Framework for Reducing LLM Hallucination and Bias](https://arxiv.org/html/2604.02923?ref=jdhwilkins.com) — on why mixing model families helps, and why it doesn't fully eliminate correlated errors.
- [Pride and Prejudice: LLM Amplifies Self-Bias in Self-Refinement](https://arxiv.org/pdf/2402.11436?ref=jdhwilkins.com) — the research behind the caution against having a model review its own output in the same chat.
### Lake District Trip June 2026
URL: https://www.jdhwilkins.com/lake-district-trip-june-2026/
Last updated: 2026-07-01T17:15:05.000Z
A lovely hike, great company, and incredible views over Crummock Water and Mellbreak Peak.


Who needs GPS when you can navigate with a piece of paper as long as you are tall.


A massive thanks to the guys who stopped to help with the car after parts started falling off. Absolute lifesavers!
0:00
/0:05
1×
*June 27th 2026*
### AI-generated writing has its place—it's just not here.
URL: https://www.jdhwilkins.com/ai-generated-writing-has-its-place-its-just-not-here/
Last updated: 2026-06-16T08:50:45.000Z
## Warning, this article contains human-written em dashes.
I know this isn't going to land well, but you're going to have to bear with me.
AI is very *effective* at writing.
It's adept at translating between languages, skilled at comprehending and synthesising information, can write functional code quicker than almost any human programmer, and can construct thorough, rational chains of thought to reason through a problem.
What ties these examples together is that the effectiveness of the output matters, but the brilliance of it does not.
Good code does not need to have soul—it needs to be functional, adhere to conventions, and be easy to follow. Similarly, it doesn't matter if the documentation accompanying that code sounds like AI wrote it. Its purpose is to convey information clearly and concisely so that a person can quickly get to grips with how it works.
- A data report needs to convey information clearly and accurately—not eloquently
- Internal company documents need to be concise and informative—not exude personality
- A meeting summary should be accurate and complete—not poetic
Can we set aside all of the AI-hate for a second and just appreciate how incredible it is at this sort of thing?
## The good and the bad
There are a lot of tasks out there for which AI-generated writing is perfectly acceptable. No, you know what, I'll go one step further: there are some tasks for which using AI is the most sensible and effective option.
However, there are also plenty of situations where AI should not be used. It cannot bring the same level of taste, judgement, experience and personality that a human can.
> It should not be used for anything where the subjective quality of the output matters.
Trust me, I hate seeing AI-generated articles and social media posts as much as the next person. That is absolutely, unequivocally *not* a good use of AI. But bad uses of AI aren't limited to clickbait stories on Medium.
> Don't worry, this isn't going to be yet another anti-AI-generated content story—they're almost getting as tiring as the AI-authored posts themselves.
AI is reshaping brand credibility, too—and not for the better. A 2024 study by the [Nuremberg Institute for Market Decisions](https://www.nim.org/en/publications/detail/transparency-without-trust?ref=jdhwilkins.com) found that consumers become measurably more sceptical and less engaged the moment they discover content is AI-generated. A recent study by [Skyword](https://info.skyword.com/ai-buyer-research?ref=jdhwilkins.com) found that 30% of consumers state they are less likely to engage with or buy from a company if they suspect its content is AI-generated. Customers are sceptical of AI so much so that it can actively harm your brand identity. For public-facing content especially, the efficiency gains are almost certainly outweighed by the reputational cost.
While AI has both some strong and potentially detrimental use cases, knowing when AI should and shouldn't be used is not always so clear-cut.
## The grey area
Public-facing AI usage may harm brand identity, but what if you label it as AI to distance yourself from it?
Say you published frequent data reporting and wanted to add an AI-generated summary, labelled as AI.
- The quality of the main report is unchanged.
- The headline summary actually provides *additional* value for users seeking a brief synopsis instead of digesting the entire report.
- AI can write a very succinct, accurate and comprehensive summary far quicker than a human can, making it a more economical option for the company.
- A reader may have asked AI to summarise it anyway, so by providing your own summary, you can better ensure its suitability.
- The only downside is that it *sounds* like AI wrote it.
Does that make it a good use of AI? Or perhaps, even if there is *real* value being supplied, the fact that AI was used diminishes the quality of the product? Maybe, as much as we like to criticise AI use, it does prove itself to be a valuable tool.
There are plenty of situations where using AI to write content for you seems to work. Take LinkedIn, for example. If you've been on there in the past year, you'll immediately know what I'm talking about. On platforms like this, where AI-generated posts are so common, it almost takes me by surprise to see something written by a human. It's what the audience has come to expect. There are plenty of people who have viral posts that have clearly been made with AI.
Maybe the problem is louder than it is widespread, but it seems as though we all reject AI-generated content, yet the posts still go viral.
## What about text humanising?
Text humanising and voice replication aren't foolproof approaches. It's great in some scenarios, but it wouldn't work for an article like this one, for example—you'd see straight through it.
> Again, before anyone comes for me in the comments, I typed that em-dash myself.
I publish all of my articles on both Medium and my personal blog. On my blog, each post needs some additional metadata to help with Google search results. I use AI to write a title and description for each post. This is a very AI-teachable skill; there are guidelines and rules you can follow to write a good meta-title and meta-description. It's a task that I don't enjoy doing, so I outsource it to AI. However, it *is* public-facing—this is the text that's going to appear in a Google search result. My personal workaround for this was to train the AI agent that performs this task on my personal brand voice so that the text it generates still sounds like me.
For something like a meta title and description where it's a fairly short and formulaic format, I don't really notice the difference. A human-written meta description and an AI-generated one (especially using my brand voice) are pretty much indistinguishable since there's so little room to play with.
You could apply this same brand voice mimicking technique to something like data reporting—and I have. Public-facing data reporting uses specific language, has a somewhat repetitive structure, and a distinguishable style. I've found that the more something exhibits a deliberately impersonal style, the easier it is to replicate with AI and the harder it is to spot. The same is true with *some* forms of journalism and news reporting. If you are writing a news story to be unbiased and deliberately hit both sides of the argument without inserting your own opinions, that's a voice that you can replicate fairly well with AI.
Where it gets a bit trickier is when you're trying to replicate personality through humanising AI-generated text or mimicking a brand voice. This isn't something I've found to be possible. Experienced AI users are adept at detecting AI-generated content, even when 'humanised'. So even if you *did* manage to fool most of the audience, it only takes one sceptic to cry "AI" for everyone else to get involved, too.
To really stop people from being able to tell, you'd have to completely rewrite the whole piece to remove the deeply ingrained AI-writing patterns. At that point, you may as well have just written it yourself in the first place.
## Human in the loop
Even in all of these AI-favourable use cases, human judgement is still not redundant.
For data reporting and journalism, we can implement error and accuracy checking routines into the content workflows to spot errors and hallucinations. While you can get pretty close to perfect, you still can't guarantee 100% accuracy. There are some scenarios where this is okay, and naturally, some where you do need 100% certainty. In this case, you would still need a human (or some more deterministic tool) to ensure that what you're saying is correct
Human-in-the-loop is the notion of keeping a human involved in the decision-making process. It could be approving every step of the way, having a high-level oversight at key stages, or just a final review before publishing. The requirements of the project will determine the appropriate choice.
As someone who builds AI-content workflows, I personally wouldn't completely outsource quality control to AI. I don't yet have the confidence in the tools to do *exactly* what they have been told to do, adhering to the guidelines supplied and with complete accuracy. It can get you 80%, maybe 90% of the way there, but at least that final 10% should rest with you. The only way to build a reliable workflow that will actually work for you in practice is to accept that a human will still be involved in the process—at least a little. Once you've accepted that fact, you can start designing it in and start seeing the results.
> I help small businesses and creators build content workflows that actually hold up in practice, where human-in-the-loop mechanisms are designed in rather than bolted on. I'm currently taking on a select number of clients. If that sounds useful, [get in touch](https://www.jdhwilkins.com/contact/).
## If this is you, I understand, but also: please stop.
I opened this article with the idea that AI is an effective writer but not a beautiful one. I don't believe this idea is unique to me; far from it, in fact. I think it's almost a universal conclusion for people learning AI to reach.
For all of us, it's a journey that begins with initial curiosity that blossoms into fascination. You start to experiment with AI and learn more about how to use it effectively. Somewhere along the way, you get a bit carried away and start applying AI to everything.
When you're at this point, its potential seems unlimited—there is no task it cannot accomplish, and nothing it can't do quicker and more effectively than a human can. But it doesn't last forever. Eventually, the facade starts to crack, and you realise it isn't quite as clever as it seems.
The more you write with it, the more you notice the sing-song rhythm of its paragraphs. The more you chat with it, the more you realise how sycophantic it can be and how much of a tendency it has to become so focused on something while ignoring the bigger picture. The more you try to treat it like a person, the more you start to realise how much humanity it lacks. It's absolutely incredible, yes, but far from human—at least for now.
Before there was so much hate for AI-generated content online (and before I had reached this stage of my own AI progression), I'll admit, I used AI to write content for the internet. I hold my hands up; I was part of the problem. But I almost think it's a necessary step everyone needs to take to get to the other side. Not publishing AI-generated content online necessarily, but pushing the limits of what it *should* be used for.
You need to be inspired by it and to have that awe in what it's capable of. Put it on a pedestal, at least for a little while. You'll realise eventually that it doesn't belong there, but you'll have learnt more about its capabilities and limits than you would have otherwise.
> You have to live in the illusion for a little while before you can see through it.
Today, I still use AI to help with my writing, but now it's more the way I'd collaborate with an editor. It helps me *review* my writing and only suggests high-level changes to stop me going off on a tangent and ensure everything flows properly. That's the balance I've ended up with as AI has slowly settled into my workflow over the past few years.
So, as I say, I completely understand the urge to share the amazing things that AI can create for you, but please, be better than me. AI has its place in the world and on the internet, but it's not in posts like this. Save it for what it does best.
### How (and why) I Built My New Home on the Internet
URL: https://www.jdhwilkins.com/how-and-why-i-built-my-new-home-on-the-internet/
Last updated: 2026-06-11T22:57:13.000Z
If you've been following my work for a while, you'll know I cross-post all of my stories on Medium and my own personal blog. It's something I started doing almost 2 years ago. I wanted to have a space on the internet that's platform-agnostic, not dependent on any one algorithm, and that can look and feel exactly the way I want it to.
Recently, I've been feeling like it needed an upgrade, so I decided to code it myself... with some help from my good friend, Claude.
I've been coding since I was 11, but I've never really dabbled in web development, so this was a new adventure for me. I also rarely use Claude Code to write code — apart from simple scripts and tools — so I learnt quite a lot from the process.
Before we get into some of my design decisions and takeaways, let me explain a bit about the project.
---
## Let me take you back to September '24
Almost 2 years ago, now, I set myself up with a basic WordPress site. I didn't know a thing about web design—or even how to run a website. I just decided to start and would have to learn on the job. Over the next 16 months, my site underwent a number of face-lifts and redesigns. I don't have copies of every iteration, but to give you a sense of my not-so-great design choices, this was the home page I was running with for a while last year:
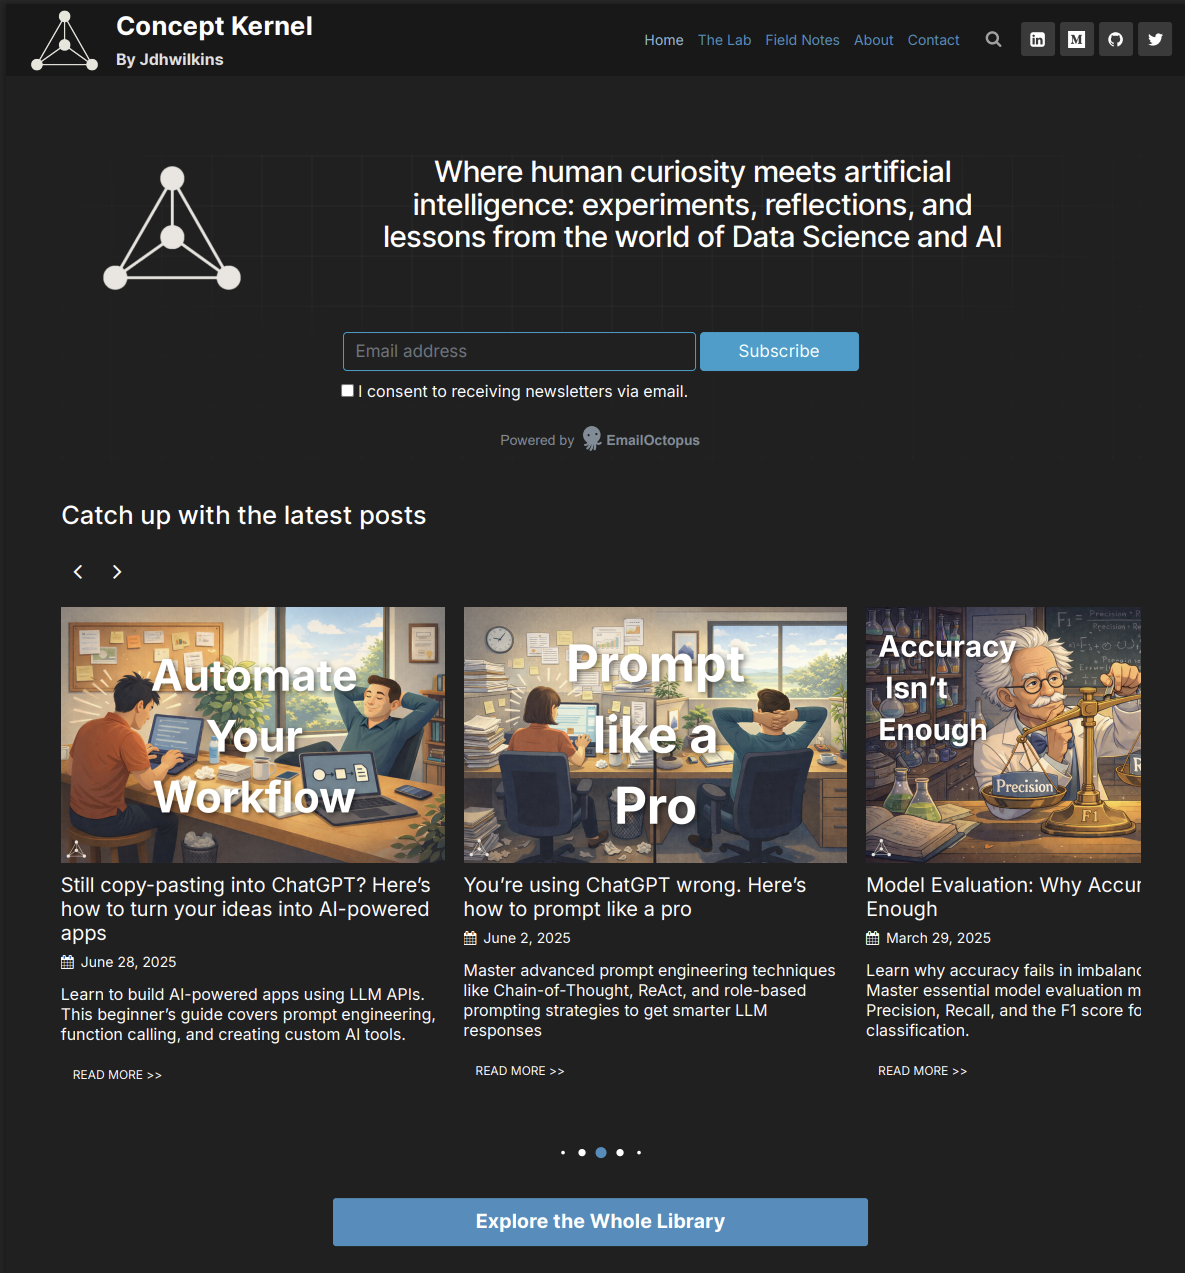
The fonts (!) The lack of clear site identity and hierarchy(!?) The alignment and spacing (!!?)
And this wasn't even the worst design. Believe it or not, this is the product of almost a year of experience. I was clearly still figuring out my branding and trying to come up with something cohesive and that felt like me.
In January of 2026, I made the switch to Wix. As an all-in-one platform, it handled plugins, security, backups, and was just overall a more seamless experience that took away a lot of the things I didn't want ot have to think about.
But I quickly outgrew that too. My aspirations grew beyond what a drag-and-drop website builder could handle. The style of content I was producing also changed, and the old site didn't really feel like the right place for it anymore.
---
### The Changing Landscape of the Internet
My blog initially started as a portfolio for me to document the projects that I was working on and to provide me with some accountability to keep showing up. In the beginning, this was mostly programming projects: I worked on a chess computer, explored different algorithms from the field of computer science, and wrote about various data visualisation projects.
After a while, I found my footing in writing about AI. I produced guides on tools I was using, wrote tutorials for applying AI to different tasks, and shared research on prompt engineering. It was purely informational content.
But the internet has changed drastically over the past couple of years. Search engines have introduced AI overviews, which now appear in around [30% of searches and decrease click-through rates by around 35% ](https://www.aurasearch.com.au/why-your-google-traffic-is-ghosting-you-and-how-to-win-it-back?ref=jdhwilkins.com#:~:text=Organic%20search%20traffic%20declined%202.5,rates%20by%2035%25%20when%20present.)when they do. For some types of queries, AI chatbots are starting to replace search engines entirely. ChatGPT alone now accounts for [23% of informational queries and 64% of generative/creative queries](https://firstpagesage.com/seo-blog/google-vs-chatgpt-market-share-report/?ref=jdhwilkins.com#:~:text=This%20report%20provides%20a%20side,demographic%20groups%2C%20and%20user%20intent.). AI overviews and AI chatbot answers do both supply links to the source they reference, but click-through rates are exceptionally low. [93% of Google's AI-mode queries don't result in a click ](https://www.digitalapplied.com/blog/ai-search-seo-statistics-2026-definitive-collection?ref=jdhwilkins.com)to the original page in what's known as a **zero-click** search.
> I mean, even anecdotally: who's Googling medical advice anymore? We're all getting our misinformation from ChatGPT instead.
Getting my content summarised in an AI overview or ChatGPT conversation is not my goal. I'm a writer at heart, and I want my work to be read in full. You wouldn't get AI to play you a summary of a song; you can't AI-summarise art.
What I mean to say with all of this is that the content landscape is changing. I don't see a bright future for writing guides on the internet anymore. It's time for me to adapt in order to survive.
---
### AI isn't all bad
The internet is naturally very divided on AI, but believe it or not, it *is* possible to hold two contrasting views on something at the same time.
AI is very effective at automating routine tasks, aggregating information, and performing decision-making. It can write very *effectively.* The words it produces are increasingly adept at conveying information, reasoning through a problem, providing a balanced argument, and deciding what action to take. What it lacks is expert judgement and the sort of nuanced perspective that comes with being a human in the world. It may write effectively, but it cannot write *beautifully.*
> *While we're on the subject, please, please stop publishing AI generated text on the internet.*
The demand for a human perspective is greater than ever. And that's exactly what I'm trying to offer more of.
I'm starting to write about the things I'm working on, the things I'm reading about and everything I'm learning along the way. I'm not pretending to have all the answers; there'll be a lot of open questions and probably some speculation too. Hopefully, it's a way for me to give you a glimpse into the way I think about a problem and provide some inspiration for how you can tackle your own.
The focus is still on the subject matter, but written more through the lens of my own opinion. I'm hoping that this new content direction turns my website into more of a documentary of my own life, work and projects instead of a repository of information as it has been up until this point.
And in that same vein, the subject matter will be expanding too. I want to share everything I produce in one place, in multiple formats in a single feed, and something that allows for my other interests outside of AI, too.
For that, I had to build a new home.
---
## Drumroll, please...
So with that slightly longer-than-planned tangent wrapped up, let's explore some of the changes I've made:
- **A refreshed design.** Go [see it for yourself](https://www.jdhwilkins.com/). It's still early days, so don't be surprised if there are a few bugs or funny-looking elements. Either way, I'm super happy with how it looks.
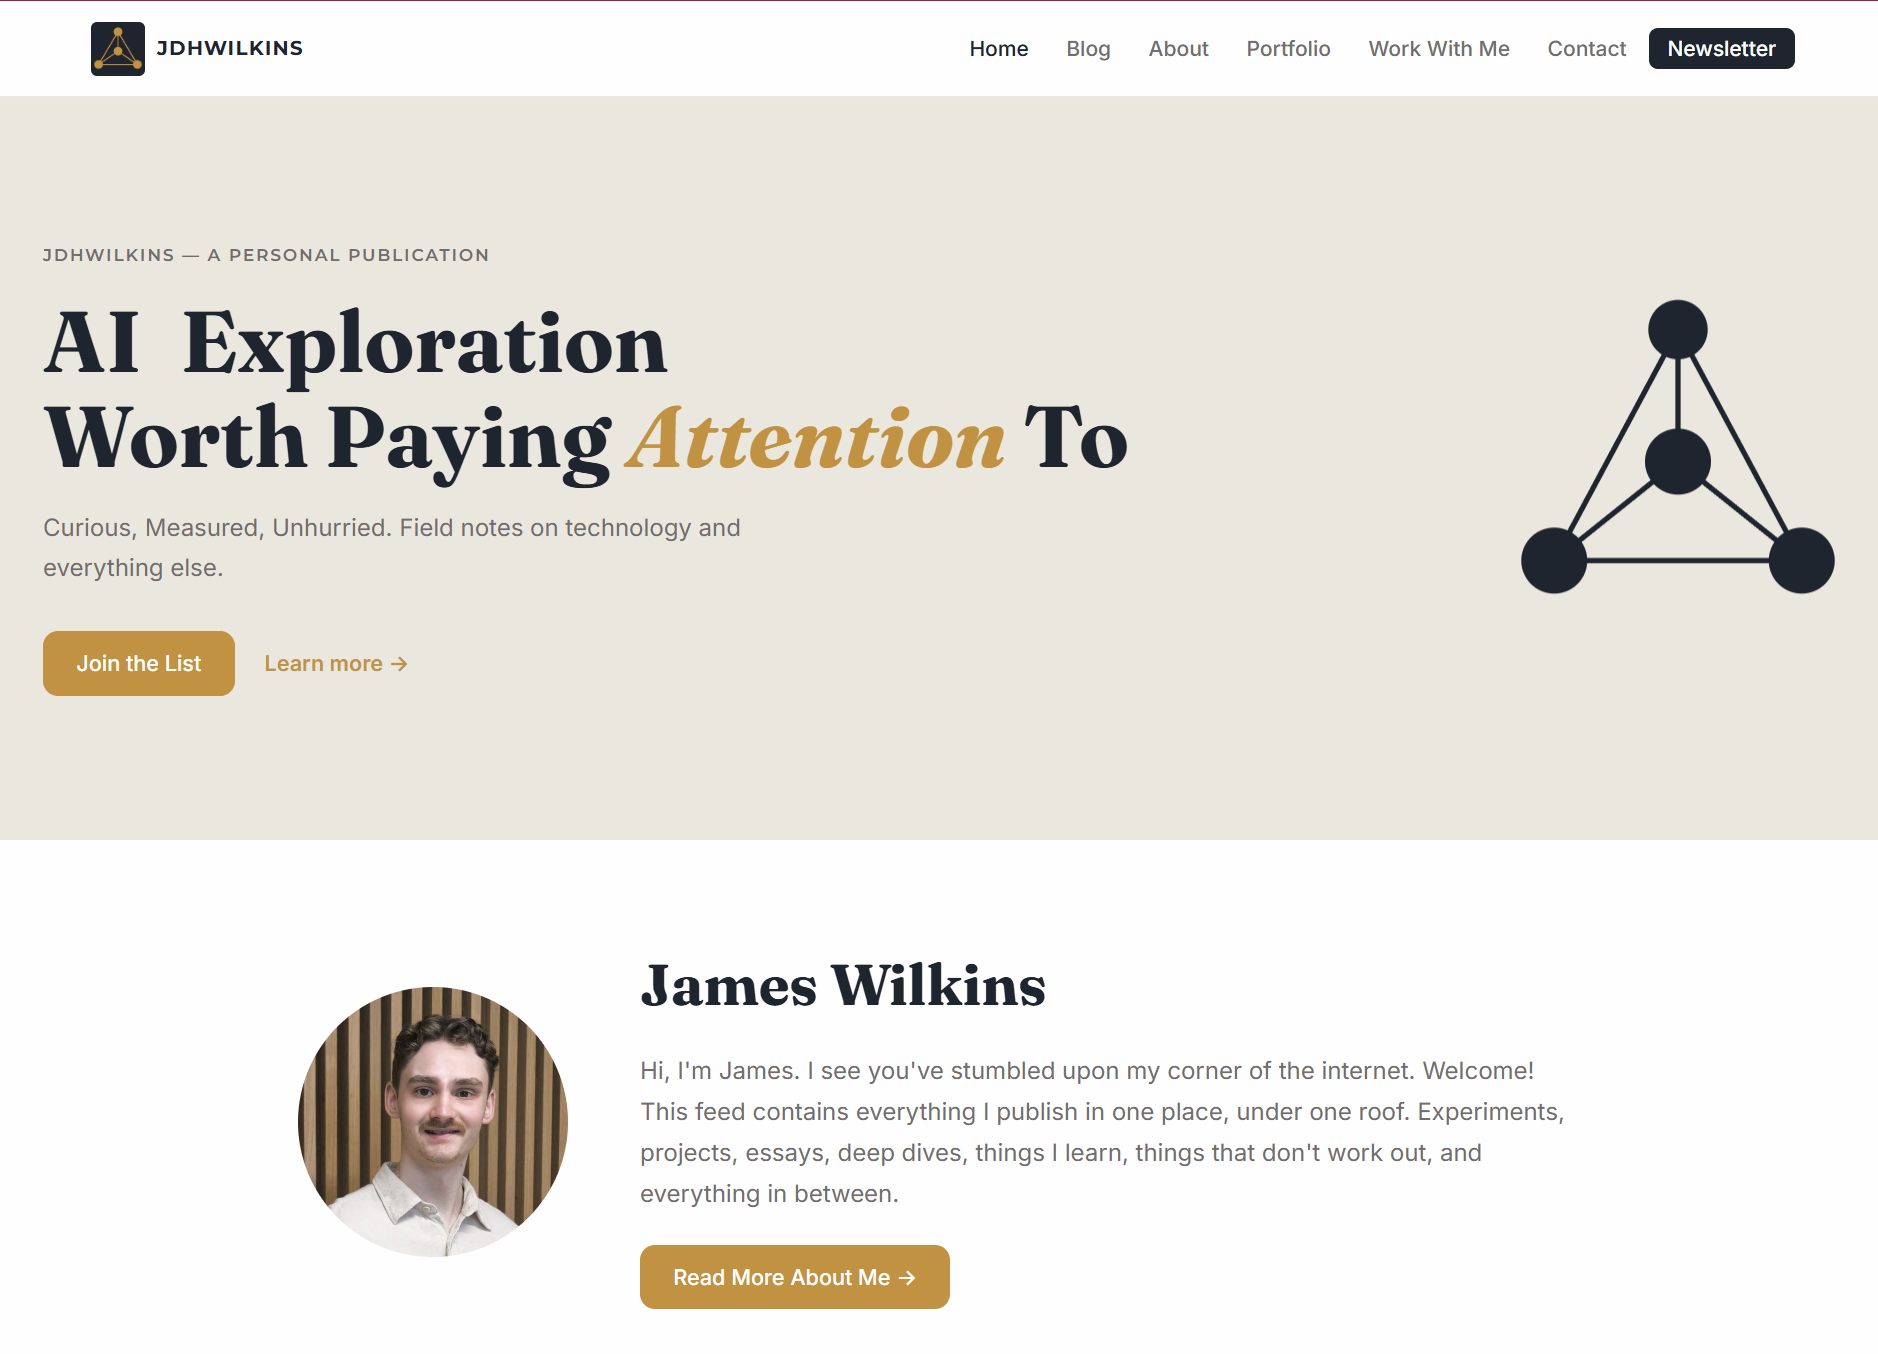
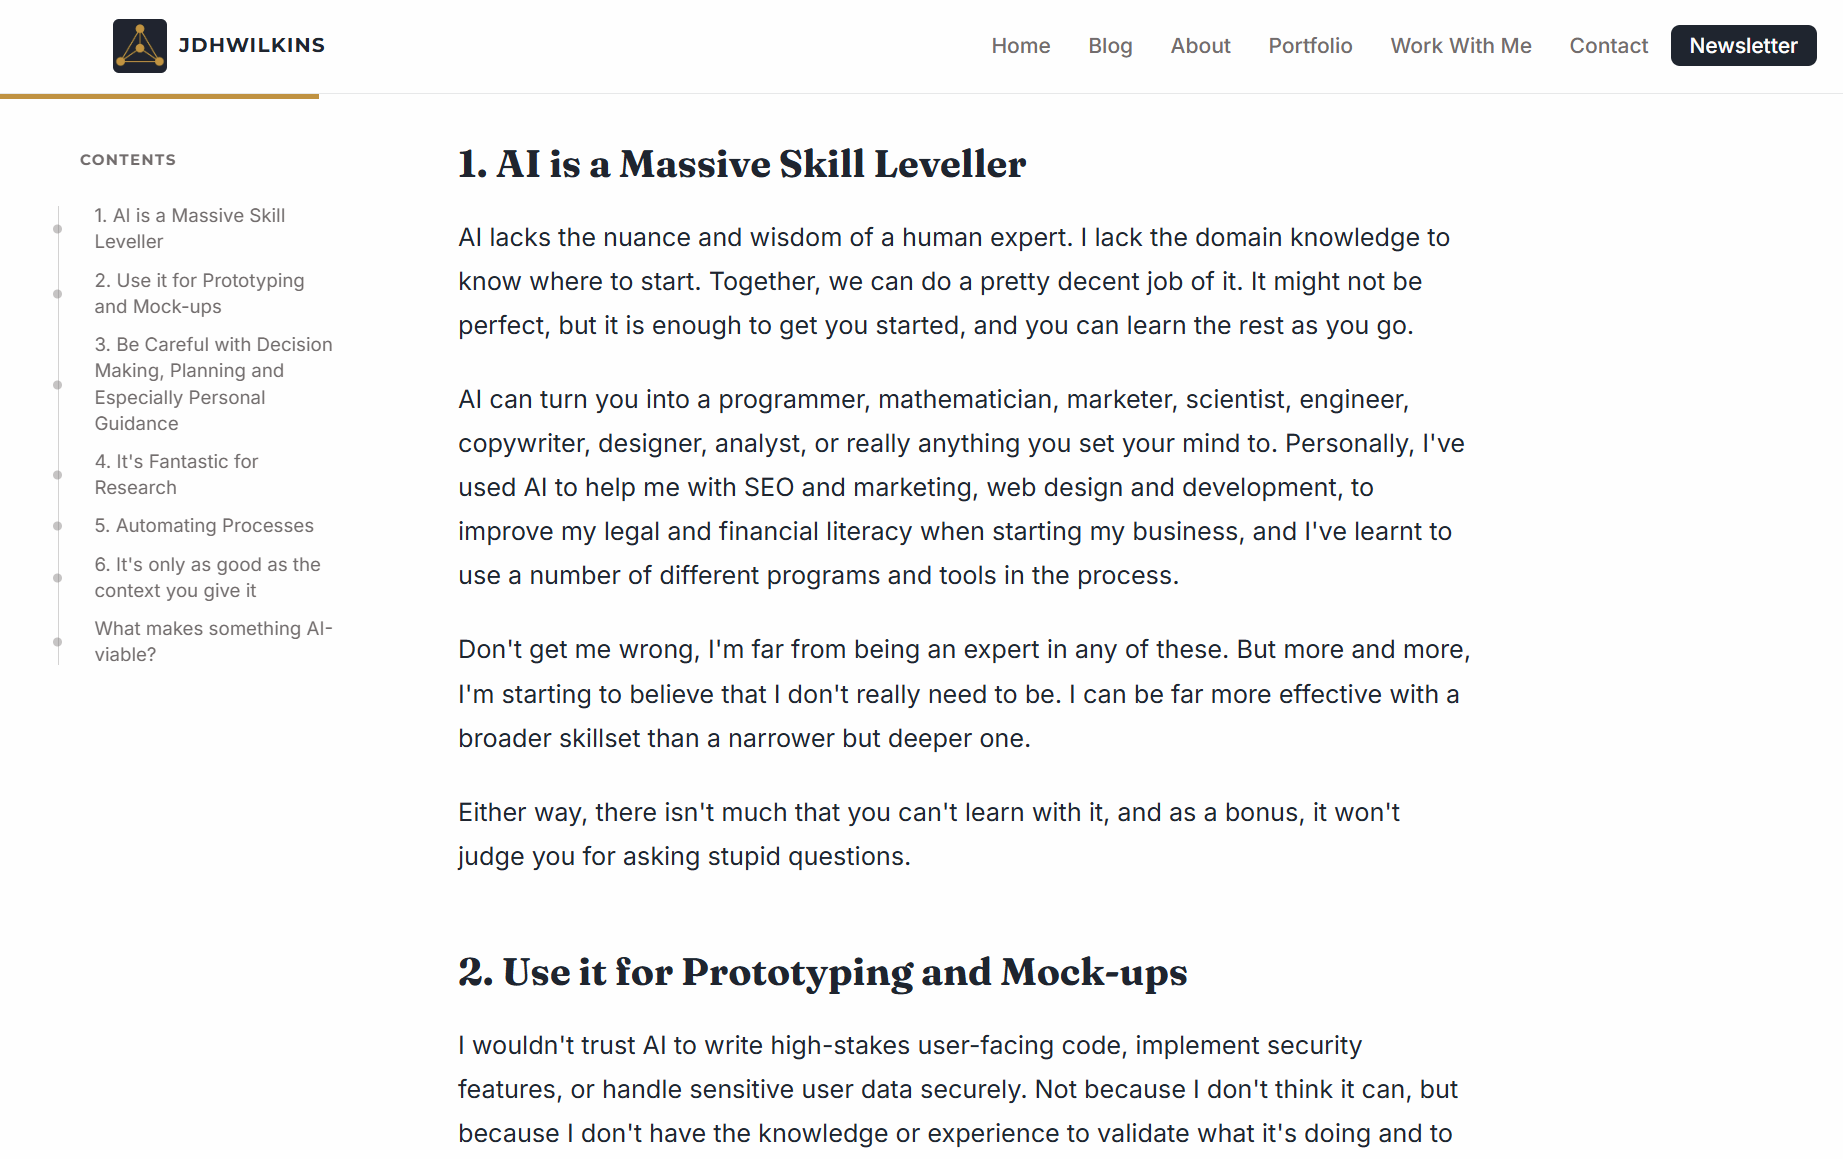
- **New discovery features.** The feed is where blog posts go to die, so I wanted a way to resurface old content. Perhaps this is more for myself than for anyone else; I love looking back at my old work to see how my perspective and writing have changed.
I've introduced **random posts** from my catalogue, **browsing by post type**, '**On This Day**' and **exploration by year**.
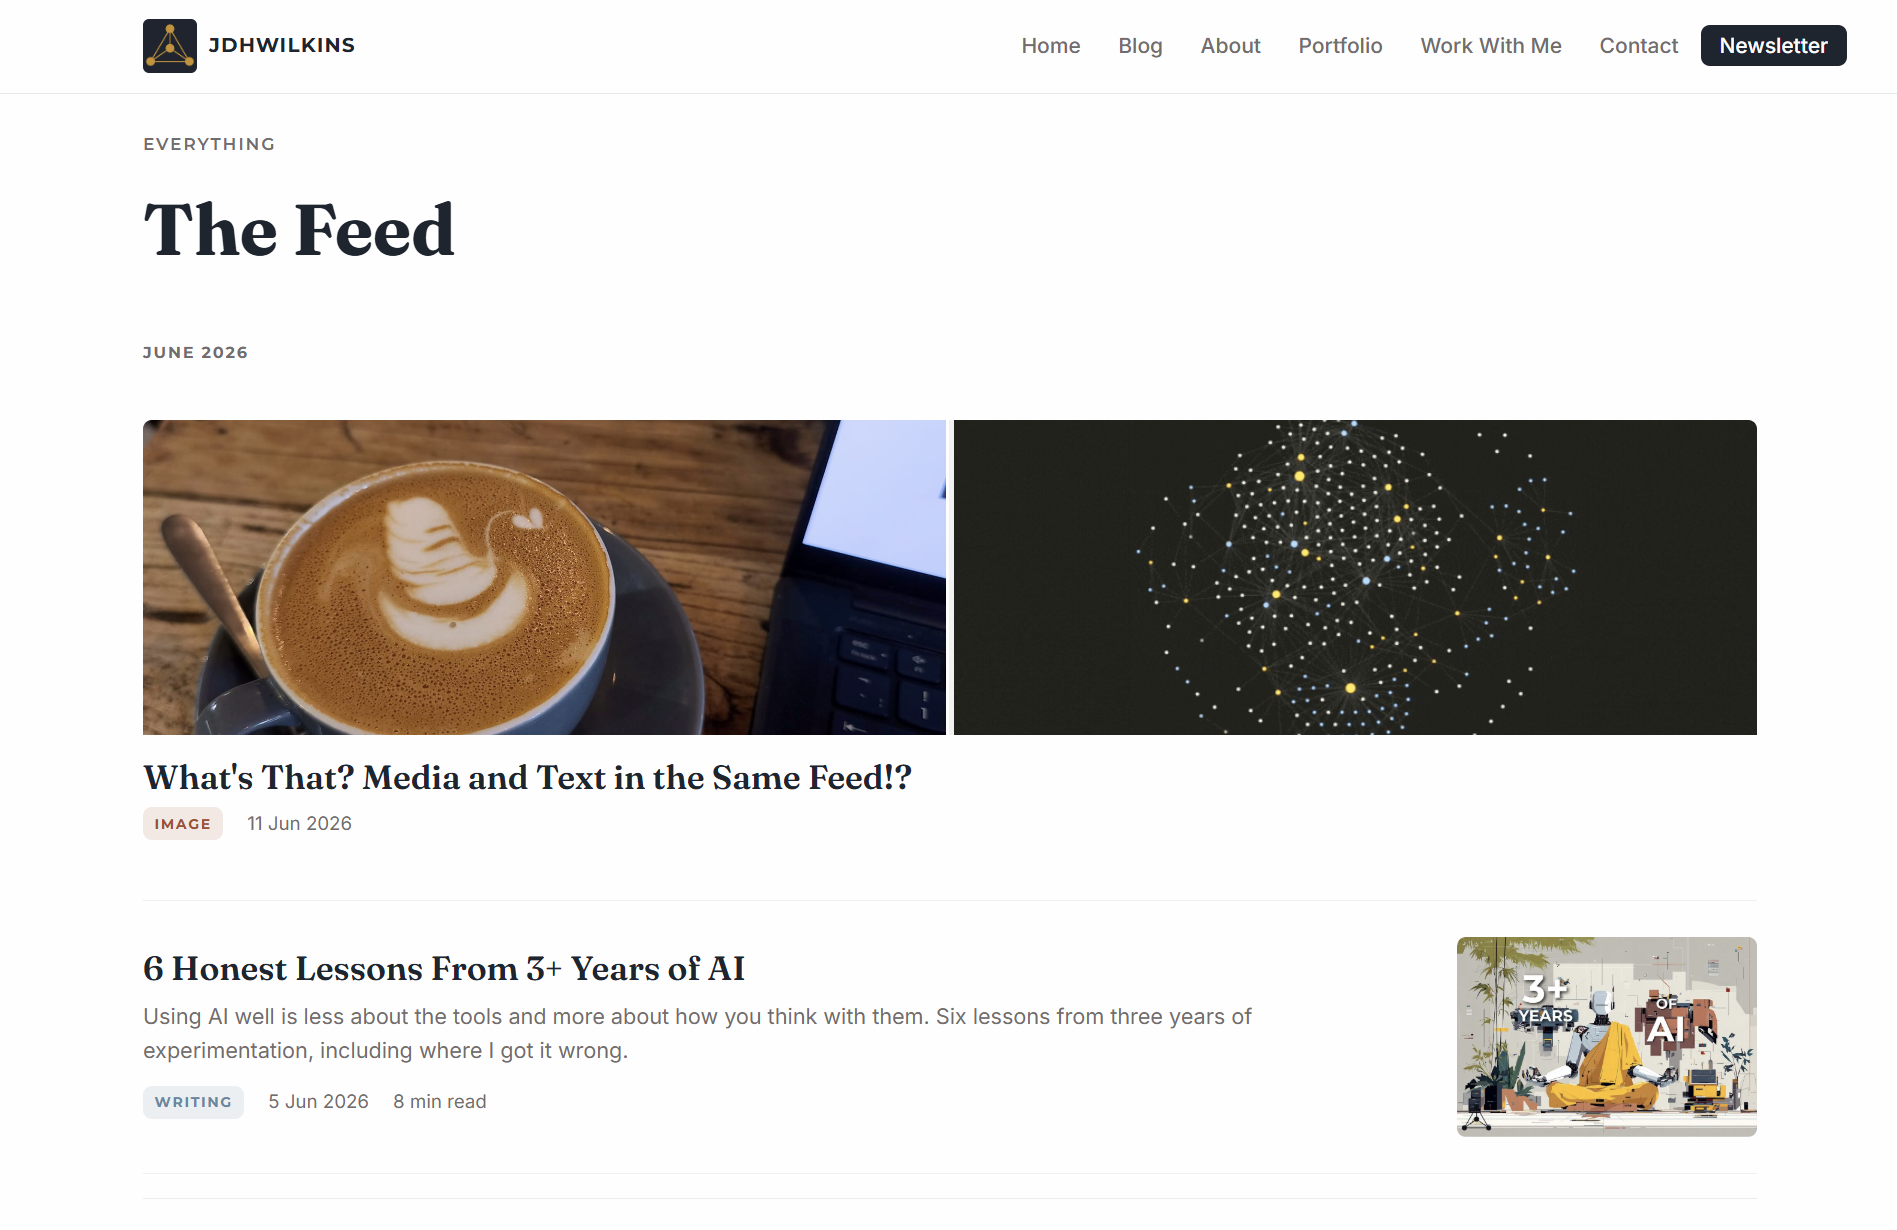
- **Multiple formats in a single feed.** I wanted a way to share media galleries, projects, short Twitter-style posts, and essays all in one place—so that's exactly what I built. And yes — it works with videos too.
Since I coded this site myself, I also have the flexibility to completely customise each of the pages, add custom elements and interactive features in a way that website builders don't really allow for. I have plenty of ideas in the works, and now, the platform to build them on.
---
## Let's get into it
I'm deliberately not going to go too deep into the technical details because *a)* I don't want to put people off, and *b)* it really doesn't matter.
This is the sort of project you should absolutely have a go at yourself. With AI holding your hand through the process, you might be surprised at how easy it is to build something cool. However, I'd warn you against making anything public unless you've first spoken to another human who knows more than you do about it.
One of the biggest things I've learnt from my experience with AI is that it's probably best not to trust it to do something that you don't know how to do yourself—at least when there's something at stake.
Having never experimented with web development before, I don't know enough about how to handle security, database management and all of the other technical things that come along with deployment. Therefore, for this project, I outsourced all of that, allowing me to focus entirely on the front-end and design without having to worry about messing up anything serious. Pretty much everything that could go wrong can be checked via inspection. You can just look at the site and see if it's working. If you were trying to properly handle user data or setup analytics, it's not so simple.
Let's start with the easy stuff.
### Designing the pages was a breeze.
I didn't even use Claude Design for this; as good as it is for iterating on a design, I found, when I experimented with it in the past, that it just burns through tokens. Maybe they've changed it since, but regular ol' Claude Code worked perfectly fine for this project.
I started out, as you often should, in plan mode. I gave it:
- Screenshots of my colour palette and described how each should be used,
- A list of fonts and how they should be used,
- The header and footer structure
- My logo set & other assets
- Descriptions of styles for common elements like buttons
- The list of pages I wanted to include
- Links to my socials to embed as needed
- The content and copy for each of the pages
- Some guidance on the frameworks and tools to build with.
This was pretty much everything I needed to get the core design and features built out. Obviously, the design wasn't perfect on the first go—it needed some iterative improvements to get right.
The best approach I found was to give Claude both a screenshot and a text description of each of the changes I wanted. A lot of the time, it proved much easier than trying to describe which element I was talking about and what was wrong with it.
I also found it far more economical to group the changes into batches rather than do them one at a time. I'd work in cycles of:
- **Reviewing** the current pages and listing changes that needed to be made
- **Feeding back** to Claude with a list of things to fix
- **Rinse and Repeat**
I found I was able to get much more out of my usage quota this way, rather than asking for things one at a time. I can't *prove* this, however—it's just anecdotal evidence.
On the topic of usage quotas, I was able to build the entire site and get things 80% complete with just two 5-hour quotas. If you time it right and start working an hour or two before your limit resets, you can get two full quotas back-to-back with minimal interruption.
After this, I popped back in over the next few days to add some finishing touches with some feedback from other humans.
### Exploring and Resurfacing Old Posts
This is where my prior coding knowledge came in handy, but don't let that put you off.
As I discussed in the sections above, I wanted to add some more advanced discovery features to my home page. This involved adding some code to the page to fetch specific posts from the archive.
- On this day
- Random posts
- Explore by year
Had I just asked Claude to implement these features with its original plan, it would have worked just fine. But I've had too many experiences with slow webpage loading speeds in the past to settle for just '*fine*'.
This is where having some experience can really make a difference. It's not that Claude didn't know how to do it a different way, but rather that it didn't think to check if a more efficient alternative was possible. Had I left it as it was, the page would have gotten slower and slower as the number of posts in my library grew.
Perhaps with future generations of AI models, this will become less of a problem—I suspect it will*,* but right now, it takes a human to say "this doesn't quite sound sensible—is there another way?" in order to get things right. I'm sure there are people out there with far more coding experience than I have, who would be able to spot far more issues than I could.
Again, the original approach would have worked, and it's a problem that you probably would have spotted at some point in the future anyway. Don't let perfectionism prevent you from even getting started.
### Nice-to-Haves
Again, since this site was entirely custom-built, it gave me the freedom and flexibility to add whatever features I could dream up.
One of the things I've been wanting to add for a while was a clickable contents pane alongside my posts for quick navigation. With Claude, this was easy. I also added custom post types (images, writing, projects, and notes), a progress bar for reading percentage, animations on the home page, and some subtle hover effects for buttons and elements throughout the site.
Just things to give it a slightly more premium feel.
---
## So, What's the Point?
Almost two years ago, when I first set up a website for myself, I just wanted a little piece of the internet to call my own. I sought freedom from being locked into a specific platform or being distributed by a single algorithm.
The internet is increasingly a place where search queries get intercepted before they reach the original content and where AI summarises your work so the reader never gets to find you. It's a place where platforms rent you an audience and reserve the right to take it back. For me, building my own home on the internet is a small, simple act of resistance to all of that — a bet that people still want to find *me*, even with the increasingly abundant amount of information out there.
Going forward, if you choose to stick around, you'll hear more about the things I'm working on and my thoughts about them. It's going to be less of a tutorial and more of a journal.
If you haven't already, go take a look at my site. And if you want to follow along with what I'm building, the free [newsletter ](https://jdhwilkins.substack.com/subscribe)is the best place to start.
### What's That? Media and Text in the Same Feed!?
URL: https://www.jdhwilkins.com/whats-that-images-and-text-in-the-same-feed/
Last updated: 2026-06-11T12:28:37.000Z
Absolutely, it is. And what better way to begin than with a coffee?
This is one of my new post content types. I can share media, add captions, and have it presented in a more natural format in the feed.

Here's my current Obsidian vault graph. I posted about this setup recently, which you can read more about [here](https://www.jdhwilkins.com/i-wish-i-knew-this-before-building-an-ai-second-brain/). I'm really pushing the limits here, huh.

### 6 Honest Lessons From 3+ Years of AI
URL: https://www.jdhwilkins.com/6-honest-lessons-from-3-years-of-ai/
Last updated: 2026-06-09T08:34:46.000Z
My first recorded conversation with ChatGPT was March 31st, 2023, with good old GPT-3.5\. It was four months after ChatGPT launched, and at the time it felt like magic. Every release since has made the one before it feel somewhat primitive. Three years and several existential crises later, here's what I've actually learnt from using AI on a daily basis.

## 1\. AI is a Massive Skill Leveller
AI lacks the nuance and wisdom of a human expert. I lack the domain knowledge to know where to start. Together, we can do a pretty decent job of it. It might not be perfect, but it is enough to get you started, and you can learn the rest as you go.
AI can turn you into a programmer, mathematician, marketer, scientist, engineer, copywriter, designer, analyst, or really anything you set your mind to. Personally, I've used AI to help me with SEO and marketing, web design and development, to improve my legal and financial literacy when starting my business, and I've learnt to use a number of different programs and tools in the process.
Don't get me wrong, I'm far from being an expert in any of these. But more and more, I'm starting to believe that I don't really need to be. I can be far more effective with a broader skillset than a narrower but deeper one.
Either way, there isn't much that you can't learn with it, and as a bonus, it won't judge you for asking stupid questions.
## 2\. Use it for Prototyping and Mock-ups
I wouldn't trust AI to write high-stakes user-facing code, implement security features, or handle sensitive user data securely. Not because I don't think it can, but because I don't have the knowledge or experience to validate what it's doing and to know that it's not missing anything important. In fact, the more I use AI, the less I am inclined to trust it to do something that I couldn't do myself.
But what I do find it useful for is putting together simple tools where the stakes are much lower. I've built some tools to help manage my website, scripts to scrape data from the internet, and some visualisation tools to help me learn. These are all simple programs and utilities. It doesn't matter if they don't work perfectly, as long as they're good enough.
The ability to throw something like this together in minutes rather than hours (or potentially days) as it would have years ago, has made AI such a valuable tool.
It's not just limited to coding, either, (although code often plays a part behind the scenes). I've used AI to quickly mock up designs for websites and landing pages to get a sense of how they should look before I build them. For one article I started drafting recently (and ultimately scrapped), I had AI rewrite it from a different angle to see if it would flow better. I wouldn't use the result, but it quickly showed me whether the idea had any merit.
These are all things that don't have to be perfect. A lot of the time, if it was something I was actually going to build and publish to the world, I'd start again from scratch and architect the whole thing properly. But most of the time, you just need a quick test to see if it's worth trying out, and sometimes the quick fix turns into the perfect tool for the job.
## 3\. Be Careful with Decision Making, Planning and Especially Personal Guidance
You have an expert in your pocket who can give a tailored answer to any question you can dream up. For factual queries like "how do I use this software?" or "how can I train for a 10k run?", it's perfect. But once you're into emotional or non-objective territory, I'd be more cautious.
Sycophancy is still a big problem with AI. Under the pretence of being "helpful", AI overly affirms users and is biased towards agreeing with whatever they say. Don't get me wrong, we've seen remarkable improvements on this front in the past couple of years (I'm looking at you, Claude), but it still causes me problems on a daily basis.
The best approach I've found to mitigate this is deliberately asking AI to disagree with you. This changes the helpful answer from "blind confirmation" to completely tearing your argument apart.
AI will never not come up with an answer. What I mean is, whether you have a completely bulletproof plan or the worst idea ever conceived, AI can always generate a list of pros and cons. Ultimately, it's up to you to weigh up the options based on its feedback.
I'd definitely caution you against using AI to talk through personal or emotive topics. There's been [research](https://www.science.org/doi/10.1126/science.aec8352?ref=jdhwilkins.com) to show that, in personal guidance conversations, AI sycophancy makes people more convinced they are right, and less open to changing their mind. Sometimes, as much as you might not like to hear it, *you* were in the wrong and we can't reliably count on AI to break the news to us. Of course, if you want to be blindly validated in your beliefs, go right ahead, I wish you luck. But for everyone else, you should probably go to therapy instead, or at least speak to a responsible and (relatively) unbiased human.
## 4\. It's Fantastic for Research
Most AI use cases boil down to synthesising information from different sources. Whether it's writing an email based on your prompt and the doc you uploaded; a customer support bot answering questions, or summarising some information from Google, it's all really just different flavours of the same thing. And AI happens to be particularly effective at it.
For research, I usually use Gemini to gather sources. I can't fully justify why I opt for Gemini for this. Maybe it's because I've been brainwashed into using Google products to browse the internet, or maybe it does actually surface better results. Either way, they have a large free daily quota, so I use it for more menial tasks and save my paid quota for other things. (No offense Google).
When I have some resources to work from, I usually plug them into something like NotebookLM and ask for a summary. From there, you can query the original texts and ask questions until it starts making sense.
Personally, I like to use this workflow for finding and digesting research papers. I read a lot about AI research and some of it can be quite dense, so having an AI tool there to help translate things from "academic jargon" into "normal person" (again no offense, I feel like I'm offending everyone today), proves really helpful.
Whether it's research or some other text synthesis task, there are 2 main problems you might run into that you should be aware of. Both of them, however, are largely solvable.
- Yes, AI can hallucinate, but when you directly supply it with the reference material the hallucination rate drops substantially. This is known as grounding. Tools like NotebookLM do this especially well and even supply direct links to the part of the text where the original information came from so you can always go back and check it yourself. This is great when accuracy really matters, but most of the time, the answer you get from any old AI tool will be sufficient.
- The trickier problem to spot is when an AI slightly twists or overstates the meaning of the text in a sort of silicon-powered Chinese Whispers. The best way to check is to ask a separate session or an entirely different model to review the output against the original. Ask how accurate the summary is compared with the source, and for places where the overall point is correct but there is a slight inconsistency.
## 5\. Automating Processes
'AI automation' sounds scary and technical but it doesn't have to be. You'll hear people talk about "n8n pipelines", "Zapier integrations", and "custom agents" but you don't really need any of that.If you wanted to dip your toes in without drowning in technical jargon, the place I'd suggest starting with is Agent Skills.
It's basically just a set of instructions written in plain English that an AI agent like Claude can follow whenever you need. The best part is, for simple workflows, you don't even need to manually build it yourself; you can ask AI to do it.
For example, I have a skill for producing titles and descriptions for the blog posts on my [website](https://jdhwilkins.com/?ref=jdhwilkins.com). I give it the blog post I'm writing, then it goes away and reads the article, identifies a keyword, writes a few title and description candidates, checks that they're a suitable length, and makes sure that everything is written in my brand voice.
This is a workflow that you could ask Claude to set up for you and have it working in less than 10 minutes. It's a really helpful way to package the things you're doing with AI into simple, reusable tools so you don't have to re-explain it every time.
The best part about it is that it really can be as simple as a set of written instructions. However, if you are looking for something more advanced, the ceiling is there with custom scripts, connectors and MCP servers. But that is entirely optional and you can build a powerful workflow without them.
## 6\. It's only as good as the context you give it
AI gives you better answers when it understands the full scope of your [prompt](https://www.jdhwilkins.com/the-fundamentals-of-prompting-getting-started-with-ai). A clearly defined task with specific instructions, input data, and the constraints that it needs to act within gives you something far more useful than a vague prompt would. Beyond that, supplying it with your reasoning, motivations, goals and the purpose of what you're trying to do will give an infinitely more informed and considered answer.
There are lots of ways to set persistent context for AI so you don't have to keep re-explaining yourself. Start using "Projects", [Claude.md](http://claude.md/?ref=jdhwilkins.com) files, "memories", or if you want to go really over the top, build a custom [knowledge-context system that feeds into your favourite agent](https://www.jdhwilkins.com/i-wish-i-knew-this-before-building-an-ai-second-brain).
Really, anything will do. Do some research, pick an approach that works with your chosen AI tool, and start using one today. I promise it will save you so much time and the results will be worth it.
## What makes something AI-viable?
> What do all of these use-cases have in common? They're all tasks where the efficacy of the output matters but the subjective quality doesn't.
AI doesn't have taste. It doesn't possess the intuition and tacit knowledge to truly master something to the extent that a person can. The best use cases are where **AI extends our agency rather than asking it to exercise its own**.
- It doesn't matter if the research report AI wrote happens to sound like AI. So what? Did it effectively convey all the information it was supposed to? Great!
- It doesn't matter if AI can't decide your life choices for you. It almost certainly shouldn't. It's great for helping you consider different options but use your own judgement.
- And it doesn't matter if the quick bit of code you wrote has a few bugs in it and wouldn't pass a security audit. Nobody else is ever going to see it or use it anyway but it was enough to prove to yourself that the idea was worth trying out.
Go experiment with it. Build something. The more you use it the more you'll understand it, and the more you understand it, the better the results will be.
### I Wish I Knew This Before Building an AI Second Brain
URL: https://www.jdhwilkins.com/i-wish-i-knew-this-before-building-an-ai-second-brain/
Last updated: 2026-08-10T09:48:13.000Z
## It doesn't matter how much AI you throw at it; if the fundamentals aren't there, it'll fall apart.
Expanding the context you provide an AI model with is the single best way to improve the quality of the responses you'll get and how effectively an agent can work for you.
My Second Brain is filled with everything I write, webpages I clip, notes I take, my daily logs, my projects, and any conversations with AI that I decide are worth saving. Claude has access to all of it. I don't even need to tell it to look. Claude knows what's in my Second Brain; it knows how to search for whatever it needs; and knows how to access it when it finds what it's looking for.
This, however, is not my first attempt at this sort of persistent knowledge system. I've been experimenting with different architectures and combinations of tools over the past few months, and until recently, they've all had the same problem.
> AI is just really unpredictable.
Groundbreaking, I know. But I only started to see success with this system when I set out a well-defined set of rules for my vault and explicit protocols to manage it. Only then, once I've mastered it myself, will I teach an AI agent how to automate it.
To integrate an AI agent with your Obsidian Second Brain, you're going to need the following components:
An AI Agent (most likely Claude Code)
A well-structured Obsidian Vault
An explicit set of rules for how notes should be linked
An agent access protocol (mine is linked below if you want to try it out)
A Vault index (managed by the agent so it knows what sort of files are available in the vault)
Maintenance routines
I'll detail each of these components in the sections below, but before we get into it, I want to discuss my approach.
## I'm going to take a super cautious approach to this, which is probably going to annoy some people.
The reasons my previous attempts at an AI-integrated Second Brain failed were that I didn't sufficiently plan out the architecture for it.
Your vault needs to be simple to maintain; you won't. To be able to trust that the system works, your notes need to be properly linked. When you search for a keyword or topic, you need to know that ***everything*** that should surface, will - not just whatever you felt like tagging at the time. Similarly, I have a system for tracking what projects I work on each day to allow an agent to access things that "I worked on last week", for example. As soon as you miss even one link, the integrity of the whole system starts to degrade.
I'll say this again because it's important:
> Build a system complex enough to contain whatever data you want to put in it, but simple enough that you will ***actually*** maintain it. Otherwise you won't.
I'd also suggest **not** using AI to maintain your vault... at least initially. As part of developing a system that actually worked for me, I spent a good amount of time managing it entirely myself. I manually created topics, assigned tags to every note, and linked all notes appropriately. Doing it yourself helps you *really* understand the procedures and find the small technical details and rules that should be followed to maintain it.
Create the routines yourself. Define the linking schemes. Learn it inside and out. If you don't completely understand it, and there aren't defined rules for how things should be handled, then introducing an AI agent into the picture is going to derail the whole system.
Once you have all the details ironed out, teach it to an AI agent using a skill or [Agent.md](http://agent.md/?ref=jdhwilkins.com) file.
---
> Obsidian? Did someone say Obsidian!? If you're new to this, I have a [full Obsidian guide](https://www.jdhwilkins.com/everything-you-need-to-know-before-you-start-using-obsidian) tailored towards people using it for Second Brain purposes so it should cover everything you need to get started. You can also read my full Claude Code Guide [here](https://www.jdhwilkins.com/claude-code-everything-you-need-to-know) .
## 1\. The Agent.
Any AI agent with command-line access and some way to program routines into it will suffice for this setup. For most people, that's Claude code. Claude Cowork and Claude.ai (chat) won't work since they don't have non-sandboxed shell access. In theory, you could get around this with Cowork if you set up your vault in the same folder that you're running in Cowork, but Claude Code is just easier to use from anywhere. Plus, you have the option of editing skills directly in the chat, which doesn't work in Cowork either.
I haven't tried this with Codex or OpenClaw, but there's no reason I can see why it wouldn't work.
## 2\. Vault Structure.
Firstly, folders don't matter to Obsidian. Obsidian shows you your vault in a folder hierarchy since that's how it physically exists on disc, and it's a format we're used to navigating. However, Obsidian's graph model doesn't take that into account when indexing the connections between notes. It's purely visual.
However, the vault structure is still important for the Agent using the Obsidian CLI (we'll get onto that more later). They are relevant for:
**Scoping.** The Obsidian folders command returns the entire vault folder hierarchy, allowing the agent to quickly understand the structure and contents of the vault
**Performance efficiency.** Commands such as search can be restricted to specific folders to dramatically improve their efficiency.
**Safety.** If you're experimenting with implementing a new AI routine, you can effectively sandbox commands that the agent runs by telling it to specify a folder path it should act upon. Since agents often perform a lot of bulk operations, this can restrict which files they are applied to in case something goes wrong.
The folder structure I've had the most success with is just creating a few top-level folders for different categories of note, but you could also group by project or domain if that suits you better. All of my folders are numbered for better organisation. Remember, this is just the setup that works for me:
**00 Daily Notes**
**10 Raw** \- for any webpages, podcast transcripts or other source material. Nothing in here is ever edited directly.
**20 Notes** \- for any polished, concise notes. Not raw articles and guides, but clean notes ready to be used.
**30 Projects** \- I create a new page for each project I'm working on. In the sources field, I link to raw material and notes that are important for this project.
**97 Topics** \- my folder of topic pages - more on that below
**98 Assets** \- the folder I have set up to contain all of the media files in my vault. Some people prefer to have these alongside the relevant note; I prefer to have mine all in one place
**99-Templates** \- I have a template set up for each of my vault folders. They specify the exact frontmatter fields that I want to be using every time.
I do have some additional folders 40-, 50, 60-, etc... but this is the core setup that I'd recommend. Expand to suit your needs.
#### Sub-folder organisation
For sub-folders, I use a few different schemes depending on the folder. I don't group semantically, but more systematically so that I can find things easily when I need them.
Archive + Current folders
Year > Date folders
Sub-topic folders (if you really insist on semantic groupings)
Generally, I'd recommend staying away from anything dynamic where you might have to move notes between folders frequently, so folders such as 'not-started', 'in-progress', and 'completed' are not advised. We'll discuss a better approach for that in a minute.
## 3\. Linking Scheme.
Being consistent with your frontmatter is important to keep your Second Brain alive and well. If you start missing fields and forgetting to add tags, the quality of the system will start to degrade. Again, the best approach is to create a system complex enough to organise your notes in the way that works for you but simple enough that you'll actually use it. Finding this balance takes a bit of practice. Setting up folder templates using the Templater plugin (not sponsored) is an easy way to ensure that the right fields are already waiting for you when you do create a new note.
With this in mind, here's the setup I use for the front matter for all of my notes after a lot of trial and error. These 4 fields should be added to every note in your vault.
### Types
Types align with the high-level folders. They are static and describe the type of note it is. I use a '/' to create sub-types that refer to the folder the note is in e.g.
- Raw/Article
- Raw/Podcast
- Raw/Research-Paper
- Topic
- Notes
- Template
- Other
### Topics
Topics are generally static but the set of topics may grow and change over time. A note on the topic of 'security' will always be about security, but you might find that when you accrue hundreds of notes tagged to 'security', it's time to break that down into subtopics.
That can be messy, but here's one approach to simplifying that process:
Create a folder containing topic pages. This keeps them all organised and in one place. Each topic page
Is just a blank placeholder page. Sure, you can add general information about the topic if you want, but I just leave all of mine blank. (This also ensures that they show up in the graph view, which is a super quick way to make it look 10 times cooler.)
Links to a parent topic. I create a frontmatter item called 'Up' which points up the topic hierarchy (the name helps me remember which direction this should go). This means I could have one topic for Security, then a few sub-topics for data breaches, AI security, and security tips, which all point upward towards the parent category.
When I notice that a topic becomes too saturated to be meaningful, I simply ask the agent to:
Find all notes tagged to that topic,
Define some new sub-topics where there is a good number of notes that would go into them,
Create the new topic page using the existing ones as a template,
Assign the new sub-topics to point to the parent ones
Go through all of those notes and either leave it with the original topic or assign it to one of the new sub-topics as appropriate.
I did this recently with my AI-news topic page. It was getting too saturated so Claude created an AI-companies sub-topic with a few company-specific pages as sub-sub-topics, and a product-releases topic. It then shuffled everything around to where it now fits best.
> **Side note.** This is a routine that I have built, understood and performed myself so I can confidently write an AI agent skill to automate the process without breaking my setup, leaving notes without topics, topics that don't exist, or multiple similar topics.
I like to create a group in my graph view to colour all topic pages the same. This way, I can easily tell how my topics link together and quickly see when a topic is becoming oversaturated. If you set up all of your topic pages to have type: topic in the frontmatter, you can then filter for:
\["type":topic\]
in the graph view, to quickly see just your topic pages and how they link together. It will look something like this:
As a general rule, I allow a note to have multiple topics if they are either disconnected or if they are sisters but not parents. E.g. I could have a 'design-tools' topic and a 'product releases' topic, but I'm not going to have 'AI News' and 'AI Product releases' when one is a parent of the other.
That's just a personal preference, but it helps to keep things tidy. It's part of the system I've built that works for me. You might be keen to jump in and automate, but there will be many small things like this that you need to figure out before you let AI loose on it. Use it yourself, then teach AI to use it.
### Tags
Tags are for temporary states for a note. Is it an article that you're still drafting? 'status/draft'. Finished the piece you're working on and just hit publish? 'status/published'. I create a temporary tag 'the-clique' for notes I save to my vault that I want to use in this week's newsletter. (which you should totally [go subscribe to](https://jdhwilkins.com/?ref=jdhwilkins.com)). After I write my newsletter, I delete it from anything I've used so I've got a blank canvas ready for next week.
### Sources
The last of the core frontmatter fields is the 'Sources' field. In it, I add a link to any note that acts as a source for the current one. For example, an article I write might link to a few of my "Notes" (from my notes folder). Each of my notes may link to a raw file where the notes were compiled from. When I write social media posts about an article I've written, the source of that post is my article note.
This gives my links direction (top down), so I'm not adding random links between items. It's clear which of the two items that are related should have a link to the other. I also find that doing it this way around is more practical since I don't find myself going back to old notes to add new links in. I just add new links as notes are created.
### Further Linking
Beyond frontmatter, I like to make use of Wikilinks (e.g. note name ) in the body text of each note. While main note sources go in the front matter, if I reference a different note or idea while writing, I make sure to link to it. You can quickly add a link by typing \[\[ and typing the name of (or some keywords found in) the desired note. Hit enter, and it'll autocomplete. You now have a link between two specific ideas.
Beyond these four main frontmatter fields, I'll add ad-hoc fields for different types of notes. Raw source file notes all get a 'url' field to link back to the original webpage where I found them. Some will get a date created/modified, others get an 'author' field. As long as you complete the core set of fields on EVERY note, the rest is up to you.
## 4\. The Agent Access Protocol - Obsidian-CLI skill.
This may be an unpopular opinion, but I do almost all of my Claude Code work in a single Folder. I have all of my frequently used skills set up there and a [CLAUDE.md](http://claude.md/?ref=jdhwilkins.com) file that suits my needs.
To work with Obsidian, I have an Obsidian-CLI skill that I built to help the agent interact with Obsidian through the command line. This proves much more effective than standard file operations and can make use of Obsidian's internal file index and search features.
To use this skill, I'll generally prompt something along the lines of: *"You can find the source material in my vault", or "Read this research I found on \_\_ and write a set of clean, compiled notes from it. You can find everything you need in my vault."*
Generally, after one mention of the word vault, Claude knows where to read and write new files for the rest of the session. I don't need to manually upload files every time, *and*I don't even need to get the file name right due to the search feature.
You can find the [specific skill I've developed here.](https://github.com/jdhwilkins/obsidian-cli-skill?ref=jdhwilkins.com) Feel free to drop it into your setup and test it out. I'm sure it could use some improvements, but it seems to work fairly well for me.
It's designed to function more like a driver connecting the agent to the CLI, so it deliberately isn't programmed with any details of vault architectures, multi-step routines or fancy workflows. It just tells the agent how to perform basic tasks like search, file reads and modification.
It's also worth updating this periodically. The Obsidian CLI is still pretty new and updated frequently, so things do change slightly over time. You can always ask Claude to review the docs and update your skill.
## 5\. Agent Vault Indexing.
To really start to see the benefits of this, you'll have to make some edits to your [Claude.md](http://claude.md/?ref=jdhwilkins.com) file. The first thing I'd recommend once your vault and the access protocol are in place, have the agent perform an initial assessment of your vault.
Just let it explore the folders, see what's in them, and see what key files you might have that it might find useful in the future. Specifically for me, these are context files, brand style guides, and my current work goals and focus. These are things that the agent may want to open and refer to for common everyday tasks. Tell it this. Have it write it to its memory file.
You may want to rerun this process periodically to refresh and index any new files.
## 6\. Other Agent Workflows.
I'll be honest, what we've discussed so far is pretty much my core setup. I've tried writing additional skill-based workflows that sit on top of the CLI skill before, and I just find them too brittle and restrictive.
The agent has all of the tools it needs here to perform pretty much any maintenance or admin task you can think of. I don't use a dedicated skill for these; I just describe them when I need them. I haven't yet found a complex task that I repeat often enough to warrant building a skill-based workflow for it.
That said, here are some use cases to try out.
### Content Ingestion \\& Bulk Operations
Sometimes, no matter how hard I try, I forget to add topics to my notes. With proper instruction, Claude can do this, no problem. It can read your topic structure from the topic-page folder, it can read each note to determine which topic it should have, and it can write that topic to the file. I'll specify the system and linking rules that I've learned from managing the vault myself so that Claude leaves everything intact.
I also use an agent to automate a lot of bulk operations, such as refactoring or removing tags, archiving old files, tidying up my notes, and removing duplicates.
### Daily Briefings
This isn't something I use frequently, but rather something I experiment with from time to time. Daily briefings written straight to my daily note. You can set a scheduled task in Claude to check the weather forecast, find some recent news stories, and anything else you might want to read first thing in the morning. You can also have a separate vault with all of your tasks and to-do lists in, and have a morning briefing of everything you need to do today. You can read about my experiment with this [here](https://www.jdhwilkins.com/how-i-built-an-ai-powered-task-system-with-obsidian-and-claude-code) .
### One thing I've been experimenting with lately
The Obsidian CLI has a developer suite that I've only recently started poking around with, and it looks quite exciting. We're talking things like executing JavaScript inside Obsidian's runtime, querying the live UI, taking screenshots of the Obsidian window, and triggering any command in the command palette programmatically.
In practice, this means I can ask Claude to find and open a note directly in a new tab in Obsidian. It just pops up in front of me without me having to search for it. The screenshot feature is interesting, too. You could have Claude open and screenshot your Excellidraw sketches and turn them into a diagram or even perform the workflow being described. Hand-drawn diagram to action in a single prompt.
I'm still figuring out where this fits into my day-to-day setup, but it's been fun to play around with.
## Learning with a Second Brain.
One of the best use cases of a system like this, and where it sort of gets its name from, is the ability to learn from your notes. I store the podcasts I listen to, the articles I'm reading, what I'm working on, my project updates, my daily logs, and reflections. My second brain has everything pertaining to my work and interests. We can use an AI agent to help us connect ideas and spot patterns.
Even just asking it to explore your Second Brain will lead to some interesting results.
"You have access to my second brain. I store all of my notes pertaining to my work in here, and they are all linked together. Read through everything. Look at the connections, topics, and links between them..."
... What can I learn from this?
... Give me some suggestions for...?
... What projects should I work on?
... What are my next steps on this project?
... What patterns do you notice?
... update my [CLAUDE.MD](http://claude.md/?ref=jdhwilkins.com) file with whatever you can learn about me
Give it a try; you might be surprised what it comes up with.
## Even the everyday tasks are so much quicker.
One of the most frequent tasks I'll have Claude run is conducting a research report. Often, I'll already have some brief notes on a topic that sparked my interest, and I can just direct Claude to it, have it research, and write the report straight to my vault. No more worrying about where it's writing files to, or what format it's going to be in. It's already topic-tagged, linked to my original note, status set to 'to-read,' and just sat there waiting for me.
I never have to drag and drop files into chat because Claude already has access to whatever it needs. I don't even have to get the specific name right. "I have some notes on X in my vault" is usually sufficient for it to find it. I don't have to give it style guides for specific pieces of work - it'll just find what it needs. I don't have to dig through my files to find examples to provide as a reference because Claude already has them.
Starting to see a pattern yet? This setup has completely changed the way I work.
It's been growing with me, too. I can add new skills for whatever workflows I might need, and it can make use of the existing infrastructure. The more data you add to it, the more powerful of an asset it becomes.
And it all starts with getting the fundamentals right.
### Everything You Need to Know Before You Start Using Obsidian
URL: https://www.jdhwilkins.com/everything-you-need-to-know-before-you-start-using-obsidian/
Last updated: 2026-06-09T09:09:13.000Z
With the building a Second Brian boom, a lot of people have started opening Obsidian for the first time recently. If that is you, welcome. The app is free for personal use, but it has a learning curve that is steeper than most note-taking tools, and the documentation assumes a level of familiarity that can make the first few hours genuinely bewildering.
This guide covers the foundations: what Obsidian is, why people use it, and the core concepts you need to understand before you start building anything inside it. None of it is particularly complicated. It just helps to have it explained plainly before you encounter it in the wild.
> *This is a companion article for 'Building a Second Brain with Claude Code and Obsidian'. This is for people who are new to the app and want to understand what they are actually working with.*
> *Disclosure: I have no affiliation with Obsidian and am not sponsored by them in any way. I just use it every day and think it is genuinely worth your time.*
## What is Obsidian?
**Obsidian** is a note-taking application that stores all your notes as plain text files on your own computer. You write in Markdown (a simple formatting system where **bold** gives you **bold** and # Heading gives you a heading), and those notes are saved to a folder on your hard drive. It's worth becoming more familiar with markdown if you're not already; it's quickly becoming the unofficial language of AI.
What makes Obsidian different from something like Notion or Evernote is not some special AI feature or clever interface. It is the fact that your notes are just files. Ordinary files, sitting in a folder, that you can open in any text editor if you wanted to.
The app also lets you link notes to each other, visualise those connections on a graph, and build a personal knowledge base that grows over time. People use it for research, writing, journalling, project management, and, increasingly, as the human-facing side of AI workflows.
---
## What is a vault?
The first thing Obsidian asks you to do when you open it is create or open a vault. This trips people up because it sounds more complicated than it is.
A vault is just a folder on your computer. Obsidian treats whatever folder you point it at as a self-contained workspace, reading all the Markdown files inside it and making them available to search, link, and navigate. When you "create a vault", you are creating a folder and telling Obsidian to use it. When you "open a vault", you are pointing Obsidian at a folder that already exists.
You can have more than one vault. Some people keep everything in a single vault; others have separate ones for work and personal notes, or for distinct projects. There is no right answer. A single vault is simpler to manage and means your notes can link to each other across topics, which is usually the better starting point.
## Why it works well for atomic notes
"Atomic notes" is a term you will encounter quickly if you spend any time in the Obsidian community. It comes from a note-taking method called Zettelkasten, developed by the German sociologist Niklas Luhmann, who used it to write an enormous amount over his career. The idea is simple: one idea per note, written in your own words, linked to related ideas rather than buried in a folder hierarchy.
Obsidian suits this approach because linking is easy. You create a link between notes by wrapping the note title in double square brackets, like this: \[\[The nature of atomic notes\]\]. That is all there is to it. A note on Zettelkasten might link to atomic notes, which links to evergreen notes, which links back to your notes on a book you read three years ago. Over time, those connections create a web of thinking you can navigate and build on.
The alternative, which most people start with, is a folder full of long documents where ideas get buried and lost. Atomic notes are shorter, more reusable, and easier to connect. They are also easier to find later, because you are looking for a specific idea rather than remembering which document you put it in.
---
## A word on the graph view
Obsidian has a graph view: a visual map of your notes and the links between them. It is the thing you have almost certainly seen in screenshots, usually a dense, glowing web of hundreds of interconnected nodes that looks like something from a science fiction film.
Yours will not look like that for a while, and that is fine.
A new vault with 20 notes produces a graph with 20 dots and a handful of lines. It is not impressive to look at. The elaborate graphs you see online belong to vaults built over years with thousands of notes and deliberate linking habits. They are a byproduct of sustained use, not something you design upfront.
Here is mine after two months of working on a project vault:
Getting there. Not a mega-brain monstrosity yet. The graph becomes genuinely useful once your vault has enough notes that you need a visual way to spot clusters and gaps; before that, it is mostly decorative. Write notes, link them as you go, and let the graph take care of itself.
---
## You own your files
Most cloud-based note-taking apps store your data on their servers. When you write a note in Notion, that note lives in Notion's database. If Notion changes its pricing, shuts down, or changes its export options, you are at the mercy of those decisions. Getting your data out is possible, but rarely clean.
With Obsidian, the files live on your computer. Every note you write is a plain text file in a folder you control. You can back it up, move it, open it in another application, or migrate to a different tool entirely without asking anyone's permission. If Obsidian, the company, disappeared tomorrow, your notes would still be there.
This is not a hypothetical concern. Several popular note-taking apps have shut down or changed their terms significantly over the past decade. Writing in a format you own is a reasonable thing to want.
## No proprietary format
Relatedly, Obsidian uses Markdown, a format that is not owned by anyone and that any decent text editor can open. Your notes are .md files. If you open one in Notepad, it looks exactly like what you wrote, with a few formatting symbols mixed in.
Compare this to a format like .docx, which is technically open but practically tied to Microsoft Word, or to a proprietary app format that cannot be read by anything else. Markdown has been around since 2004 and is widely supported. Anything you write in it today will still be readable in 20 years.
The practical consequence is that you can edit your Obsidian notes with other tools, run scripts against them, search them from the command line if you were so inclined, and include them in version control (more on that below).
---
## Backup options
Because your notes are files, backing them up is straightforward. A few options worth knowing about:
iCloud, Dropbox, or OneDrive will sync your vault folder automatically if you put it inside their monitored directories. This works well and requires no configuration inside Obsidian itself. The vault is just a folder; any file sync service will handle it.
Obsidian Sync is the official paid sync service (about £8 a month). It handles sync across devices, version history, and end-to-end encryption. It is the simplest option if you work across multiple computers or phones, because it is built for Obsidian specifically and handles conflicts gracefully.
Git is worth mentioning for anyone comfortable with version control. You can initialise a git repository inside your vault folder and commit your notes regularly, giving you a full history of every change you have ever made. There is a popular community plugin called Git that automates commits on a timer. This is the most thorough backup option and doubles as a way to sync between devices via GitHub or a similar host.
Manual backup also works. Copy the vault folder to an external drive or another location. It is low-tech, but it is reliable, and there is nothing wrong with it as a supplement to whichever other method you choose.
The important thing is to have at least one backup that lives somewhere other than your main computer. The vault is just a folder; treat it like one.
## Frontmatter
At the top of many Obsidian notes you will find a properties panel that looks like this:
This is frontmatter. It's structured metadata stored at the top of the file that describes the note rather than containing its content. The fields you see in that panel (title, date, tags, status) are things you define. Obsidian renders them as a clean UI, but behind the scenes it is storing them as plain text in a format called YAML, which looks like this:
```
---
title: My note title
date: 2025-11-01
tags:
- PKM
- obsidian
status: draft
---
```
You do not need to know anything about YAML to use frontmatter. The Properties panel handles it for you. The reason it is worth knowing the underlying format exists is that other tools, including community plugins and the Obsidian CLI (see more below) read it directly.
Frontmatter is optional, but it quickly becomes useful. You can use it to tag notes by topic, record when something was written, track the status of a project, store a source URL, or add any other property that helps you find and filter notes later. Obsidian's built-in search and its Properties panel both read frontmatter, and many community plugins depend on it to do their work.
You do not need to fill in front matter on every note. Start with what you will actually use. Tags and a date are enough for most people to get started.
---
## Folders inside Obsidian
Obsidian shows you the folder structure of your vault in a sidebar on the left. Because your vault is a real folder on your hard drive, organising notes into subfolders works exactly as you would expect. You create a folder, you drag notes into it, and they move.
People have strong opinions about folder structures in Obsidian, and you will find elaborate systems with acronyms and hierarchies if you go looking. The honest answer is that the right structure is whatever you will actually maintain.
A few principles that hold up in practice:
Keep the folder structure shallow. Deep nesting makes things harder to find, not easier. Three levels is usually enough.
Use folders for broad categories that will not change much. A folder for work, one for personal notes, one for reference material, one for writing projects. The fine-grained organisation can happen through tags and links rather than folders.
Do not optimise the structure too early. The urge to spend a weekend designing the perfect system before writing a single note is strong and usually counterproductive. Write notes first, then see what groupings emerge naturally.
One popular starting point is the PARA method (Projects, Areas, Resources, Archives), developed by Tiago Forte. It is a sensible default if you want somewhere to begin without overthinking it. There are Obsidian templates built around it that you can download and adapt.
## Plugins and the community plugin ecosystem
Obsidian ships with a set of core plugins that cover the basics such as a daily notes creator, a tag pane, a canvas view, templates, and a few others. These are maintained by the Obsidian team and are toggled on or off in settings. Most people enable a handful and leave the rest.
The more interesting half is community plugins. Obsidian has an active open-source community that has built hundreds of plugins extending what the app can do, and you can browse and install them directly from inside the app. Go to Settings, then Community Plugins, turn off safe mode, and you get access to a searchable directory.
The Dataview plugin lets you query your vault like a database. If every note has frontmatter with a status or a date, Dataview can generate live lists and tables based on those properties. Useful for tracking projects, reading lists, or anything where you want a filtered view across many notes.
Templater is a more capable alternative to the built-in Templates core plugin. It lets you create note templates with dynamic content, so a new meeting note can automatically fill in today's date, prompt you for an attendee list, and drop a standard set of headings in one keystroke.
The Git plugin automates version control for your vault, committing your changes on a timer to a repository. If you want a full history of everything you have ever written and a way to sync across devices without paying for Obsidian Sync, this is the approach.
Excalidraw embeds a drawing canvas inside a note, which sounds niche but turns out to be genuinely useful for mapping out ideas that are hard to express in prose.
None of these are essential when you are starting out. The point is that the app is extensible in ways that most note-taking tools are not, and the community has been building on it long enough that there is usually a plugin for whatever you find yourself wanting.
---
## It's worth talking about Templater
Templater deserves its own section because it solves two of the most common problems new Obsidian users run into: inconsistent frontmatter and the friction of linking notes together.
The built-in Templates plugin lets you insert a static block of text into a new note. Templater does the same thing, but the template is dynamic. When you create a note from a Templater template, it can automatically insert today's date, pull in the note title, prompt you to fill in specific fields before the note opens, and run small scripts to set up the structure exactly as you want it. A template for a book note might open with the title pre-filled, a date\_added field already set to today, a status field defaulting to reading, and a set of standard headings ready to go.
This matters for frontmatter because consistency is what makes frontmatter useful. If some of your notes have a 'topic' field, others have a 'topics', for some you forgot to add a field entirely, the system starts to degrade. Similarly, if some have dates formatted one way and some another, Dataview queries break and searches return incomplete results. Templater removes that variability by doing the formatting for you, every time.
For linking, Templater templates can include pre-written wikilinks to notes you know will always be relevant. A daily note template might automatically link to your weekly review note. A project note might link to a MOC (map of content, a note that acts as an index for a topic area) for that project. Rather than remembering to add those connections manually, they are there from the moment the note is created.
The templates themselves are just Markdown files stored in a folder in your vault, with Templater's syntax mixed in. They are easy to write, easy to adjust, and once you have a small set that matches how you actually take notes, you will find you rarely create a blank note again.
## The Obsidian CLI
Obsidian, by default, is a standalone desktop application. It does not have a built-in way for other programs to read or write your notes directly. The Obsidian CLI (command-line interface) is a tool that bridges that gap and lets external scripts and AI tools interact with your vault. They can read notes, create new files, search, and run queries, all from outside the Obsidian application itself.
In practical terms, this is what makes it possible to ask an AI assistant to look something up in your notes, create a new note based on something you have been researching, or update existing notes as part of a workflow. Without something like the CLI, the vault is closed off from other tools.
It's simple to get set up. In Obsidian, go to settings, navigate to general, and at the bottom, ensure the CLI is enabled.
If you are using Obsidian as a standalone note-taking app without any AI integration, you do not need the CLI at all. If you are following a second brain workflow, it is the piece that makes the whole thing work.
---
## Before you build anything
A vault setup does not need to be complicated to be useful. The people who get the most from Obsidian tend to start small, write regularly, and let the structure develop around their actual habits rather than designing it up front.
The concepts above are the vocabulary you need. You will encounter all of them in the next few days as you explore the app, and it helps to know what they are before you have to figure them out in context.
### How I Use Claude as a Writing Assistant (to actually improve my writing)
URL: https://www.jdhwilkins.com/how-i-use-claude-as-a-writing-assistant-to-actually-improve-my-writing/
Last updated: 2026-08-10T09:46:38.000Z
## This article was written with the help of AI... sort of.
I hate reading AI-generated articles. I also think we'd be crazy not to use the technology that's being built right now, and I don't think that has to be a contradiction. As someone who's spent a lot of time writing with AI, I can tell you there's a right way and a wrong way to go about it, and most of what you see online is the wrong way.
## So let me be upfront.
> I use AI to help me write, and my writing is better for it. But, it **does not** write for me.
AI-generated text is clearly not good writing. We've all read the articles that are obviously just someone's copy-pasted ChatGPT conversation, and we're all tired of it. I'm not trying to defend that in any way.
Writing with AI, for me, is a deliberate choice, and I use it with three aims in mind:
**I want to learn to use AI effectively** (because, like it or not, it's here to stay, so you may as well get good at it)
**I want to remain cognitively engaged in my work** (because I'm not about to rot my brain and I actually care about what I write)
**I want to learn how to write more effectively** (because the UK education system failed me)
So with that in mind, here's the framework I use to improve my writing with AI, as well as 4 practical tips to make your life easier while you do so.
## There's nothing more intimidating than a blank page
I usually start by brainstorming, jotting down ideas in no particular order, and then trying to tie them together into a cohesive introduction. What I usually find is that I've got about 6 different threads, 3 asides, and 1 and a half completely irrelevant points.
This is where prompt number 1 comes in. It varies based on what I already have written, but it will usually be along the lines of:
> What is the most compelling idea here that I should use for my introduction?How can I rework this to effectively set up the rest of the post?
And the crucial part...
> Explain why.
**If you're not asking for an explanation, you're never going to learn.**
Then it's time for a rewrite. Often, I'll just open a new window and start writing it again, but built around this refined idea. I'll then go through a few more passes on the new draft with some specific questions and things I want a second opinion on.
> What do you think of the hook at the start of this intro?How is the pacing in this intro, am I losing the reader's attention?Based on this introduction, what would you expect from the rest of this blog post?
These are all things that I might not be able to see myself and would benefit from an outsider's perspective. In the absence of an outsider who is always ready to drop everything and help me with *my* problems, AI will do the trick.
Here's an example from when I was editing a draft for this very post:

I try to keep my questions fairly high-level and broad. I rarely ask it to suggest explicit changes, but rather broad strokes and overall shifts in the piece. Thanks, Claude!
---
## Getting the Structure Right
When I have an idea for a blog post, I usually have a sense of the structure already. But that doesn't mean the structure is going to be any good.
There's usually a bit of back and forth where I set out all of the points I want to make, we dissect them, analyse them, and cull them down to a shortened list that supports each other and links together well.
Largely, this is just "Rubber Ducking"... the process of thinking out loud to gain clarity and deepen your understanding. It's a term from computer science where, by explaining your technical coding problem to an inanimate object, in this case a rubber duck, you oftentimes find that your problem magically solves itself. The added bonus, when we do this with AI, is that sometimes it will give us an original solution or a different perspective that we hadn't thought of, too.
Either way, I always like to make sure that I'm absolutely clear on the structure before I begin. It's quite difficult to guide things in the right direction when you don't know where you need them to end up.
## Iterate and Improve
With a structure in place, I then carry on with the rest of the draft. There are usually a lot of iterations, suggesting ideas, trying different ways to phrase the point I'm making. But the goal is to help me articulate my point more effectively.
> It's never up to the model to decide what the point should be.
One approach I've found particularly effective is stream-of-consciousness writing; just write whatever comes to mind.
It doesn't have to make any sense or even sound coherent. The sentences don't need to connect, flow, or even be remotely linked. The grammar can be as appalling as you like. Sometimes, I find I have the words but haven't yet decided what it is that I'm trying to say with them. In those cases, the brain-dump approach works best.
I'll then pass it into an AI model and get it to tidy things up, instructing it to:
> Rewrite this piece using my own words. Make it sound more coherent and clear. Identify the main point I'm trying to make.
The words and ideas are still mine, but it's not my writing. The tidied-up version is just a more logical presentation of my own thoughts. I rarely use the output directly, and when I do, it's heavily edited. Once I can read it back and have it make sense, transforming it into a final draft becomes much easier.
---
## Removing the Crutch
When I first started out, I'll confess, I used AI a bit too heavily. It hadn't quite established its place yet as the soulless slop generator that it is seen as today, and there were probably quite a few "It's not X, It's Y"'s, definitely some "quietly"'s, and the odd "separate the signal from the noise". But, as someone who didn't write, using AI was a way to get me started. And for that, I will always be grateful.
Over time, I've come to rely on it less and less to help me write. And the way I use it has changed. I started out getting it to directly rewrite and "make this shorter" and "make it more compelling" (whatever that means), but since finding my voice more, I've come to rely on it far less.
My questions now are far more about structure, flow, and how the piece is landing.
> Is this being interpreted right?the reader going to lose interest at any point?What impression does this give about me as a writer?How am I coming across?Is this explanation clear enough, or could it be confusing?
Getting explanations is crucial. The more you get help identifying problems in your own work, the more easily you can fix them yourself next time.
So yes, while AI did help me write this, most of that help happened months or years ago.
## A few bonus tips I've picked up along the way...
As promised, here are some practical tips.
### 1\. "Fill in the Blanks."
When writing a draft, I often find that I can't find the right word or phrase. Instead of letting it interrupt my flow, I instead leave a marker like a triple underscore \_\_\_, and come back to it later. Some of these I'll be able to complete myself on the next pass, but often I find that asking an AI model to fill in the blanks is an effective time saver.
This doesn't just work for short words and phrases either, which brings me onto my next point...
### 2\. "Actioning these Comments."
I write my pieces entirely in markdown. I find it to be pretty versatile, integrates well with many writing platforms, and is by far the most AI-friendly format. However, the biggest drawback I've found is how difficult it is to leave comments throughout your work.
My solution to this is to use square brackets \[ \] to leave inline comments and instructions. For me, this is often something like \[rephrase this ===sentence=== later\], or \[link this better with the point above\].
Now I do action some of these myself, but when I get stuck, I find it helpful to have an AI model go through and suggest some changes for each of them. It makes it super easy for AI to find it since I rarely use square brackets otherwise, and you can make these comments as broad or as fine-grained as you like. It could be anything from \[I don't think this paragraph fits here, cut it, rework it, or move it elsewhere\], to \[find another word for 'good', we've already used it 17 times.\].
---
### 3\. "Highlight your Changes."
If you're letting an AI loose on your drafts, it's often helpful to keep track of exactly what it's doing.
You'll need a markdown editor like Obsidian for this, but you can get an AI agent to edit your work directly and highlight any changes it makes. Simply instruct it to wrap any changes in a pair of === and Obsidian will turn highlight it for you.
E.g. ... Simply ===instruct=== it to wrap ...

This makes it much easier to keep track of what has changed, so you can make sure it's not doing anything crazy. It may *tell* you it's only changed one thing, but it wouldn't be the first time an AI agent has lied about what it actually did.
### 4\. The Brand Voice Guide
Underpinning all of the advice you receive from an AI model about your draft is the Brand Voice Guide. This is a document that details some crucial contextual information about your writing that anyone (let alone an AI model) would need to offer constructive feedback.
It should contain:
Your platform and format,
Why you are writing and what you hope to achieve with it,
Who your audience is, what sort of problems they have, and how you hope to help them
The voice you want to write with. Are you a curious student who is learning alongside the reader, or an experienced teacher who writes with much more authority?
Your writing habits, things you often struggle with when writing, and things you often want help with,
Your syntax. As mentioned above, explaining that \_\_\_ are blanks to be filled in, and that \[ \] are used for inline notes and comments that should be actioned will save you a lot of time from having to re-explain it each time.
Without this, the feedback will miss the mark, and you'll end up with a confused mess at the end that isn't quite sure what it is trying to be.
---
My approach isn't a shortcut to producing more content in less time. It's about using AI effectively as a tool for learning. It allows me to get feedback instantly and for free instead of waiting hours or days for an editor to get back to me. I would never have started writing if it weren't for AI. I write better now because of it, and I hope to continue to learn to write better using it.
AI didn't write this article. But it helped me write it better. And if you can make that distinction clear, your writing will only improve.
### Seamless Content Ingestion for Claude-Obsidian Second Brain
URL: https://www.jdhwilkins.com/seamless-content-ingestion-for-claude-obsidian-second-brain/
Last updated: 2026-08-10T09:46:14.000Z
## There's been a lot of excitement recently around building a **'Second Brain' using Claude and Obsidian.**
> Unfamilliar? Read my [Claude Code](https://www.jdhwilkins.com/claude-code-everything-you-need-to-know) or [Obsidian](https://www.jdhwilkins.com/everything-you-need-to-know-before-you-start-using-obsidian) Guides. Just make sure you come back and finish this article after :)
For those who missed it, this idea was [popularised by Andrej Karpathy](https://gist.github.com/karpathy/442a6bf555914893e9891c11519de94f?ref=jdhwilkins.com#llm-wiki) and involves building a **Wikipedia-style set of interconnected notes** which can then be navigated and **searched by AI agents** . This means that we **don't have to provide AI agents the same context over and over again** . With this system, it **knows who you are** , what you're working on, **your preferences,** and all of the ideas you've had. It can see how they link together, the connections between them, and any themes or commonalities between notes.
There's been a lot of discussion around the **architecture and implementation** of these second brain systems. I've been playing around with something similar myself over the past few months, and I've found it to be such a time saver.
However, one of the missing pieces from the conversation so far is **what data should actually go into a second brain, and how we get it there.**
Most of us aren't starting from a blank slate. We already have a **reading list** , a collection of saved articles, **YouTube videos we've half-watched** , GitHub repos we starred and never revisited, and a **steady stream of new content**arriving every day.
The challenge isn't **finding interesting things to read** , but **capturing them** before they **disappear into the void** while making sure they actually end up somewhere **useful and organised**as you do.
So here's my setup for quickly collating content and having it appear in my second brain with just 2 clicks. Oh, and it's saved me a ton in second-brain token usage too.
---
## **Making something I actually use**
Content comes in many forms, and the number of different web pages, videos, social media posts, and PDFs you might want to collate is nearly endless.
I've designed this system with 2 guiding principles in mind:
**Robustness.** This needs to work for as many different content formats as possible. It can't break when it encounters something new, or I won't use it.
**Minimal Effort.** There should be as few steps and as little thought as possible between reading something interesting online and having it saved to your second brain. It shouldn't require excessive thought or effort, or you just won't use it.
Balancing these is tricky. We can make the system more automated, but we then increase the risk that it breaks when we encounter something new.
Similarly, we want to include as much metadata about each file as possible to make it easier to search, sort, and have AI retrieve from it later. But again, this comes at a cost, be that manual human effort or AI tokens. I went with the latter.
Claude usage quotas disappear faster than ever**,** and I don't want to waste mine on basic content tagging and summarisation tasks. That seems like using a nuclear reactor to toast a slice of bread. I went with a Gemini Flash model since it's super cheap, but a small model running locally in Ollama would be perfectly fine for a straightforward task like this too. If so, you'll definitely want to have this running overnight to avoide eating up your RAM throughout the day.
> *Ollama is a free tool that lets you run AI models on your own machine without sending data to any external API. (not sponsored)*
---
## **2 Clicks.**
Here's what the actual experience looks like. Say I've found an article on Hacker News (other websites are available) that I want to revisit later.
- **Click the Web Clipper icon** in my browser toolbar, and the extension opens.
- **It auto-selects a template for what data to collect.** Because it's a standard article, it matches the default Article template. If it were a YouTube video, repo, or academic paper, it would switch automatically. You can also change it yourself if it doesn't pick it up.
- **Check the title and data, and click Save.** I glance at the title to make sure it's sensible, then hit the save button.
- **Done.** The note lands in my Inbox folder in Obsidian. All metadata included.
The whole system is two components working together.
The **Obsidian Web Clipper**is a browser extension that handles the capture - it converts any page into a structured markdown note and drops it straight into an inbox folder in your vault.
The **ingest script**is a Python script that runs in the background. Each night, it picks up everything in the 'Inbox' folder, gets Gemini to generate a summary and tags, and moves each note into the 'Wiki' folder. By the morning, the article is fully processed. It's searchable, tagged, and ready for Claude to refer to in my conversations.
The rest of this article covers how to set both of them up.
---
## **Obsidian Web Clipper**
The Web Clipper is a browser extension that saves any page you're looking at directly into your Obsidian vault. Install it from the Chrome Web Store (or your browser's equivalent), point it at your vault, and set the default save folder.
Rather than saving a blob of HTML or a raw bookmark, the clipper converts the page into a structured markdown note with a full set of frontmatter properties, all populated automatically from the page's metadata. You create one template per content type, and the extension picks the right one based on URL triggers you define.
There are five templates in this setup. The core set of metadata we're recording stays the same between them, but we need to set it up to be able to find the right information on each given page type. We'll also need to set up some triggers to allow it to automatically choose the right template.
Open the web clipper extension, navigate to the settings menu. Here you can choose the vault and vault-folder to save to. Go to the templates section, where you'll then need to set up your properties in the default template, as shown below:
**Leave the triggers section blank.** For each of the following templates, you can now duplicate and edit the default one. As you add templates to the list, ensure that the default one stays at the top.
The 'ingested' checkbox is used by the AI routine to track which ones have a summary. The 'read' checkbox is for you to check things off your reading list. You could also set up the routine to only ingest content that you've read and decided to keep - it depends on how selective you want to be about what goes into the second brain.
### **PDF / Paper Template**
This is triggered by academic sites like arXiv, PubMed, and Semantic Scholar. It captures the abstract and attempts to record the PDF URL so the ingest routine can download and convert the full document later. For arXiv, the PDF URL is parsed from the page automatically; for other sites, you may need to paste it in manually.
**Triggers:**
```
arxiv.org
pubmed.ncbi.nlm.nih.gov
semanticscholar.org
schema:@ScholarlyArticle
```
**Properties:**You will need to update the 'type' property to 'pdf' and create a new text property called 'pdf\_url'. Set this to {{selector:a\[href\*="pdf"\]?href|first}}
---
### **Video Template**
This template is triggered by YouTube URLs. It pulls the full video transcript automatically, so you don't have to copy-paste it. Metadata comes from the page's structured data rather than generic meta tags, which is more reliable for video content.
**Triggers:**
```
youtube.com/watch
youtu.be
schema:@VideoObject
```
**Properties:**No changes to the properties other than changing the 'type' to 'video'.
**Content:**Update the content box to contain the following:
```
## About

## Description
{{schema:@VideoObject:description}}
## Transcript
{{transcript}}
```
### **GitHub Template**
We can clip the README from any GitHub repo or gist to add to our reading list later. We need to do something a bit funky to get the repo owner since it isn't nicely stored in the page's metadata.
**Triggers:**
```
/^https.+github\.com\/[^/]+\/[^/]+/
```
**Properties:**Update the 'author' property to {{url|replace:"/\\^https?:\\/\\/(?:gist\\.)?github\\.com\\//":""|split:"/"|first}}. Change the 'type' to 'github'.
### **Social Post Template**
We can also save social media posts to add to our reading list for later, too. We'll set it to be triggered on some common platforms, but play around with it and try adding some other ones.
**Triggers:**
```
x.com
twitter.com
reddit.com
linkedin.com
```
**Properties:**We only need to update the 'type' to 'social'.
---
## **Obsidian Setup and Plugins**
Now, we should have all the content we could ever want appearing in Obsidian. Before we get onto the AI automation, there are a few additional settings and plugins you'll want to add in Obsidian to make this setup completely seamless.
Neither of the following community plugins is sponsored or affiliated in any way.
### **Templater**
With Templater installed, you can set a default template that all new notes you create in your vault should take. This way, any notes you write yourself will automatically have the same frontmatter as anything you clip from the web.
You'll need to create a new 'Templates' folder in your vault and create a new file there.
Mine looks something like this, with all of the core fields necessary to be ingested into the system.
### **Local Image Plus**
By default, Obsidian renders images by fetching them live from the URL, so they don't live locally on your machine. This plugin changes that by automatically downloading any media links and embedding them in the local note instead of the web link.
I find this super helpful when I want an AI agent managing my vault to be able to see an image, too. It also works better for offline access.
### **Settings**
Settings > Files and Links > **Attachment folder path**. Change this to a new folder that you create. It's much easier to have all of the images you add to notes saved in a single folder.
Settings > Files and Links > **Delete attachments when deleting files**. Turn this one on - it'll help keep the vault clean.
---
## **AI Automation**
This step is customisable depending on what features you want and how you want to use it. I haven't included the script directly. Since everyone's setup is a little different, you'll almost certainly want to tweak the logic to suit your own workflow. The steps I've outlined below make a solid brief to hand to an AI coding agent and have it build something for you.
Whatever features you settle on, you'll have a few things to decide:
**Local model or web API?** I personally opt for a Gemini Flash model since it's super cheap and going to be way faster and less demanding on your machine. If you're worried about API costs (maybe you have a LOT of long files to ingest), you might want to think about a local model like the Qwen 3 or Gemma 4 series, which would be perfectly suitable for a content tagging and summarisation task.
**What to ingest?** Do you want to process everything new? Just things you've read, ignore specific content types?
**Links, tags, and summaries.** I find summaries particularly useful since an agent can view the note metadata to quickly get an idea of what's in it without having to read the whole thing. Content tagging is useful to identify themes and categories common to different notes. You could also add direct Wikilinks from one ingested note to another. The only reason I don't is because of the larger overhead with an exercise like this. All three of these techniques integrate really well with Obsidian's built-in search features, which is honestly fantastic.
You'll want to make use of the **Obsidian CLI** for whatever automation you set up. It's a command-line tool that connects directly to your running Obsidian instance, letting scripts read, write, move, and search notes the same way Obsidian itself does.
Obsidian needs to be running for the CLI to be available, but it provides a much more efficient and far less fragile way to manage files than direct file operations.
Here's a summary of my setup:
**1\. Fetch all vault tags** to ensure that the AI can reuse existing tags rather than create new subtle variations. This helps to dramatically reduce the amount of duplicate or near-duplicates introduced, keeping the whole setup clean. Tags are normalised to a lowercase-hyphenated format before being sent to the model.
**2\. Find all files in the Inbox** using the Obsidian CLI. Personally, I process anything in my 'Inbox' folder, so my personal notes (in my 'Notes' directory) aren't ingested at all.
**3\. For each file**, the script handles any PDFs by downloading and converting the full document (appending it below the clipped abstract), then checks whether the content is long enough to need summarising. Short posts get used as-is; longer content goes to the model for summarisation. A single API call returns a \\\~100-word summary and a list of tags. Tags are merged with anything already on the note, deduplicated, and normalised to lowercase-hyphenated format. The frontmatter is updated with the summary, tags, and Ingested: true, and the note is moved from Inbox/ to Wiki/ via the Obsidian CLI so any wikilinks stay intact.
I have this set up to run overnight, but I can trigger it manually to ingest any notes that I want to call upon right now.
---
## **Conclusion**
The best system is one you actually use. I've tried plenty of note-taking setups that were technically impressive and practically abandoned within a week because they required too much manual effort to maintain.
The Web Clipper handles the capture in 2 clicks, Gemini handles the processing overnight, and Claude gets a second brain that grows on its own. I barely have to think about it anymore, which is exactly the point. My Claude-Obsidian second brain is free to grow without me having to micromanage it.
If you set this up, start simple. Get the Article template working first and clip a few things before you worry about the PDF pipeline or the video transcript setup. Once the basic loop is running, you'll quickly get a feel for what you actually want to add and where the rough edges are for your own browsing habits.
### Few-shot prompting Vs. Zero-shot prompting. Which approach and when?
URL: https://www.jdhwilkins.com/few-shot-vs-zero-shot-prompting-which-approach-and-when/
Last updated: 2026-08-10T09:46:04.000Z
Providing examples in your prompt is a technique known as **few-shot prompting**. Examples can be a great way to quickly communicate what your desired response should look like - it can often be easier to show with a few examples rather than trying to describe it with words.
***'Shots'*** is a term taken from the field of machine learning. Each shot is an example given to the model before it performs the task. We often refer to ***'few-shot'*** and ***'zero-shot'*** prompting (where you don't provide any examples at all).
Knowing when and how to supply examples is key to writing great prompts and getting better results from AI tools.
## Let's see how it's done
I'll take my own advice and illustrate what each of these looks like with an example. Here, we'll use AI for a classification task: identifying the sentiment of a customer review.
**Zero Shot:**
```
Classify the sentiment of this review:
"The product arrived damaged and support was unhelpful."
```
**Few Shot:**
```
Classify the sentiment of these reviews as Positive, Negative, or Mixed.
Review: "Delivery was late but the item itself was great."
Sentiment: Mixed
Review: "Exactly what I ordered, arrived quickly."
Sentiment: Positive
Review: "The product arrived damaged and support was unhelpful."
Sentiment:
```
---
## Why examples can be useful
To understand when and why examples can be a helpful addition, researchers tested what happens when random, wrong examples are given instead. What they found was that performance barely changed; the model was not primarily using the specific correct answers. The research identified three actual drivers of what makes examples useful:
**Identifying the 'label space':** seeing the range of possible outputs (e.g. Positive, Negative, Mixed)
**Scoping the input distribution:** exposure to what typical inputs look like
**Learning the format and structure:** the overall pattern of input --> output
What this tells us is that examples guide the model through structure and context, not factual recall. That's why even imperfect examples can still help, as long as they expose the model to the right output categories, realistic input patterns, and the format you expect.
## When zero-shot is enough
Zero-shot is the right option for most everyday tasks. Modern AI models are trained through a process called ***instruction tuning***. This helps the models to learn how to actually interpret instructions, and helps them to sensibly respond to task descriptions they have not encountered before.
Before instruction tuning became widespread, techniques like **zero-shot chain-of-thought prompting** were developed to help unlock reasoning in models that struggled with complex tasks. Kojima et al. (2022) showed that simply adding a phrase like *'Let's think step by step'* could dramatically improve accuracy on multi-step reasoning problems. As instruction tuning has improved across successive model generations, this kind of hand-holding has become less necessary for most everyday use, though it can still be worth trying when working through particularly complex, multi-step problems.
You can [read more about Chain of Thought prompting here.](https://www.jdhwilkins.com/why-think-step-by-step-no-longer-works-for-modern-ai-models)
Zero-shot works well when:
The task is clear and unambiguous
The expected output format is standard (a summary, a list, a translation)
You are working quickly, and consistency across many outputs is not critical
Enough context is already provided that a worked example would add nothing
For example:
```
Write a professional email and subject line for a message about a delayed project delivery.
```
Probably doesn't need any examples to get a useful response. Being explicit about format and including enough context about audience and purpose will cover most situations. However, for:
```
Here are three emails I've sent to clients [Example 1, 2, 3]. Now, write a follow-up to a new lead about our latest proposal [Context about the specific company].
```
...it can be quite useful to ensure consistent quality, accuracy and adherence to your specific brand voice.
---
## When to use few-shot prompting
There are situations where zero-shot will keep falling short, regardless of how carefully the request is phrased. Common things to watch for include:
The output format is specific or non-standard
You need consistent results across a large number of inputs
You have refined the prompt several times, and it still misses something
The task involves a judgement call where an example anchors what "correct" looks like
You are teaching the model a custom behaviour, it has no prior training on
## Writing good few-shot examples
The structure of your examples matters more than their content. A few practical guidelines:
**Match the format you want to receive.** If you want concise outputs, keep examples concise. If you need a specific structure, show it exactly. The model will mirror what it sees.
**Use representative inputs, not ideal ones.** Examples that look like real, typical inputs are more useful than polished ones. If your real inputs will be messy, your examples should reflect that.
**Balance across output categories.** If the task has three possible outcomes, show all three. A prompt that only demonstrates two of them may handle the third inconsistently.
**Include at least one harder case.** Clear-cut examples teach the easy end of the task. An edge case helps the model understand where the boundaries are, which is where errors tend to cluster.
**Two to four examples is usually enough.** A small number of well-chosen examples typically outperforms a longer list of mediocre ones.
---
## A suggested workflow
Often, the best approach is to start with zero-shot. If the output format is wrong, results are inconsistent, or you keep rephrasing the same prompt, then a few well-chosen examples will help you out.
Zero-shot handles most everyday tasks well. Reach for few-shot when you need more consistency or precision.
Just start simple. Move to examples when you need them. Few-shot prompting can be another tool in your arsenal when tackling a problem with an LLM.
## References
Brown, T. et al. (2020). *Language Models are Few-Shot Learners.* NeurIPS 2020\. [https://arxiv.org/abs/2005.14165](https://arxiv.org/abs/2005.14165?ref=jdhwilkins.com)
Wei, J. et al. (2021). *Finetuned Language Models Are Zero-Shot Learners.* ICLR 2022\. [https://arxiv.org/abs/2109.01652](https://arxiv.org/abs/2109.01652?ref=jdhwilkins.com)
Min, S. et al. (2022). *Rethinking the Role of Demonstrations - What Makes In-Context Learning Work?* EMNLP 2022\. [https://aclanthology.org/2022.emnlp-main.759/](https://aclanthology.org/2022.emnlp-main.759/?ref=jdhwilkins.com)
Kojima, T. et al. (2022). *Large Language Models are Zero-Shot Reasoners.* NeurIPS 2022\. [https://arxiv.org/abs/2205.11916](https://arxiv.org/abs/2205.11916?ref=jdhwilkins.com)
### How to Rot Your Brain with AI
URL: https://www.jdhwilkins.com/rot-your-brain-with-ai/
Last updated: 2026-08-10T09:45:58.000Z
## Make Cognitive Disengagement your Superpower!
Replacing your own critical thinking with AI has never been easier.
The path of least resistance is right there, and yet somehow the people who have been using these tools the longest keep refusing to take it. According to research by Anthropic, the most experienced AI users, the ones who understand these systems well and consistently get the best results, have used AI differently than less experienced users. By not outsourcing as much cognitive effort to AI, experienced users tend to learn more in the process.
Fortunately, you don't have to be like them.
[Anthropic's recent research](https://www.anthropic.com/research/economic-index-march-2026-report?ref=jdhwilkins.com) classifies AI usage into two main camps:
**Automation** \- where the task is entirely handed off to AI while you go and make a cup of coffee
**Augmentation** \- where the AI acts more as a thinking partner, and you work on the task together, frankly making it so much harder than it needs to be.
Clearly, exclusive task automation is the way forward.
It's one of the great pleasures of modern life. Much like doomscrolling, there's a high reward spike that makes it addictive, and your brain switches off. You're making progress, you're getting things done, and all while not putting in any effort at all.
You can come away from a 2-hour vibecoding session feeling like you haven't understood what you built or with any real sense of accomplishment. Understanding takes time, and a sense of accomplishment is just going to make you want to do it again yourself next time.
## What the research says
A [2025 peer-reviewed study](https://www.mdpi.com/2075-4698/15/1/6?ref=jdhwilkins.com) of 666 participants found a significant negative correlation between frequent use of AI tools and critical thinking abilities, with the heaviest users consistently scoring the lowest.
Consistently. The lowest. Every time.
The study may have framed it as a concern, but I see it more as a roadmap.
A separate [2025 Anthropic study](https://www.anthropic.com/research/AI-assistance-coding-skills?ref=jdhwilkins.com) gave participants a coding task and found that those who used AI to automate the work scored 17% lower on comprehension tests than those who worked independently. They finished quickly and when asked about the task afterwards, couldn't account for much of what they'd produced.
They identified six interaction patterns. Three produced minimal learning outcomes.
The minimal-learning group delegated code generation, handed debugging to the model, and progressively offloaded more as the task went on. They managed to score lower overall.
The high-effort, high-learning group asked questions instead of requesting outputs, generated code themselves first, and sought explanations for everything the AI produced. They understood more and suffered a far higher learning burden.
[EEG research on writing tasks](https://www.media.mit.edu/publications/your-brain-on-chatgpt/?ref=jdhwilkins.com) found the highest brain activity when students wrote unaided, less with search engines, and less still with AI. Students who went straight to AI often could not recall what they had written. They managed to bypass the cognitive engagement that creates memory.
They were able to conserve far more mental energy.
## The experienced user trap
[Anthropic's Economic Index](https://www.anthropic.com/research/economic-index-march-2026-report?ref=jdhwilkins.com) found that users with six or more months of experience are significantly more successful in their conversations with AI, around a 10 percentage point improvement in success rate. They work on harder tasks and have moved beyond the obvious use cases.
More importantly, they remain actively involved in their work. The report calls this "learning-by-doing." The more time you spend with these tools, the better you get at using them without replacing yourself with them.
More experienced users have to keep working because they're integral to the work.
Let that sink in.
## The gold standard
A [2025 study by METR](https://metr.org/blog/2025-07-10-early-2025-ai-experienced-os-dev-study/?ref=jdhwilkins.com) measured the impact of AI tools on experienced open-source developers with an average of five years of experience. With AI tools, they managed to make themselves 19% slower.
What's even more impressive is that those developers claimed to expect AI to make them 24% faster! They had their bosses fooled. Even after seeing their own results, they still 'believed' it had helped.
For experts working in domains they already deeply understand, AI can add that sought-after friction to your workflow. It can create more problems than it solves - problems that a user with less expertise might not even know to look for.
Expertise and AI assistance work against each other at the high end. The solution is quite simple - just don't become an expert.
## Five things to avoid for maximum cognitive offloading
Experienced users use AI as a thinking partner. Here are 5 common traps to avoid.
- **The 'Is that right?'** Asking for questions rather than answers. If you are facing a new task, don't try to learn by describing what you understand so far and asking the model to fill in any gaps. Stop doing the cognitive work yourself and just use AI to do it.
- **Rubber ducking.** Never explain your problem to AI in enough detail that you manage to solve it yourself. This is one of the biggest traps users face, where they accidentally engage their brain too much, making the AI redundant. Start going straight for the answer, and you'll never look back.
- **Draft it yourself.** Do not write the first draft on your own. In fact, don't draft anything at all. AI should be used to write the entire final version in one go, not just for editing and reviewing. This entirely removes the 'productive struggle' - the cognitive friction that forces you to create genuine understanding.
- [**Socratic method.**](https://en.wikipedia.org/wiki/Socratic%5Fmethod?ref=jdhwilkins.com) Explicitly asking AI to push back on your reasoning, argue the other side of an argument, find the weakest point in your solution, or identify incorrect assumptions you might be making is one of the most common traps that users fall into. AI tools can only encourage cognitive offloading when users outsource reasoning to them. Make sure to ask for confirmation of your existing views rather than challenges to them. Models are designed to be helpful, so will largely oblige.
- **The 'Generate and Interrogate'.** Many people do successfully use AI to do it for them, but slip up at the last hurdle by asking the model to explain its reasoning. This not only identifies yet more issues with the solution, but also forces you to understand, so you'll want to do it yourself next time. At the end of the day, that is just extra reading.
## The broader picture
Years spent in school studying, building transferrable knowledge, and foundational understanding will soon be a thing of the past.
Get ahead of the curve now by undoing years of hard work and cognitive effort.
The people who have been using AI the longest have become trapped in a cycle of learning and effort, and are getting better results with AI because of it.
Good for them. You, however, have a cup of tea to make.
### How I Built an AI-Powered Task Management System with Obsidian and Claude Code
URL: https://www.jdhwilkins.com/how-i-built-an-ai-powered-task-system-with-obsidian-and-claude-code/
Last updated: 2026-08-10T09:45:37.000Z
## Context engineering is the next big thing
If you have been following the AI space recently, you may have come across the term ***context engineering***. Coined by Shopify CEO Tobi Lütke and quickly endorsed by Andrej Karpathy, the argument is that "prompt engineering" undersells what is actually going on when you get consistently good results from an AI model.
> *"The art of providing all the context for the task to be plausibly solvable by the LLM."* \- Tobi Lütke, Shopify CEO
Cleverly worded prompts are only a small part of how we can get *genuinely*useful outputs from generative AI tools. The information that's available to the model matters way more.
> *"Most agent failures are context failures, not model failures"* \- Philipp Schmid, Google DeepMind
Strip away the AI here, and you have a problem that productivity nerds have been working on for decades: ***Personal Knowledge Management*** (PKM). The idea is to build a personal system for capturing, organising, and making the right information available (to humans) at the right time.
Most PKM systems are built around two layers. The ***knowledge layer*** stores notes, ideas, and reference material - the things you learn, think about and may want to return to.The ***task layer*** handles actions: tasks, reminders, habits, and scheduled events. Some PKM setups focus on one of these layers, but many of the more pragmatic ones handle both together.
For this project, however, I'm only building a task layer. I already have a similar knowledge layer setup, which I'd be happy to write another post about if anyone is interested.
In this post, I'll document how I built a task layer using Obsidian, Claude Code, and a pair of custom AI skills. The specific architecture I used isn't really important here. This is just the setup that works for me. What I think is worth taking away is how the ideas and tools combine to build a system that can fit with your individual workflow.
---
## What does a task layer actually need?
Most practical task layer setups, regardless of the tools, share the same core components:
**An inbox:** a low-friction holding pen for tasks, ideas, and reminders (before anything is sorted)
**A task organisation system:** somewhere to structure those items
**A daily note:** a single consolidated view of everything relevant to today
**A scheduled review:** a regular checkpoint to see what has been completed and whether priorities need adjusting
**An archive:** somewhere for completed items to go - out of sight, but accessible if ever needed again.
A common criticism of PKM systems is that people spend as much time managing the system as actually using it. The goal with my setup was to offload as much of that maintenance overhead to Claude as possible. The components above give the structure, while the AI takes care of the upkeep.
The rest of this post walks through how I have built each of these using Obsidian and Claude Code.
## My weapon of choice: Obsidian
For this project, I'm using **Obsidian** , a note-taking application that sits on top of your local file system. Underneath is a folder of plain Markdown files. What makes it more than just a text editor is the ability to link notes together, assign structured metadata, and search across the whole *'vault*' quickly.
Linking works in two ways:
A direct ***wikilink*** between notes - essentially a hyperlink from one note to another
***Frontmatter metadata*** \- properties you assign at the top of each note, like a project tag or a status field. Obsidian's search can find all notes sharing a given property instantly, which makes grouping related items easy without enforcing a rigid folder structure
Put enough links together, and Obsidian can render them as a graph - a live visualisation of how everything in your vault connects.

Obsidian's community plugin ecosystem is extensive. There are calendar plugins available, and I did try them, but they just weren't the interface I gravitated towards. I found myself asking Claude what my upcoming schedule looked like instead, which turned out to be a better fit for how I work.
Folders in Obsidian are less meaningful than they look. In this system, they loosely group note types and house archives, but the real organisation comes from metadata. Trying to enforce a strict folder hierarchy just makes things harder to find. The metadata search is far more flexible.
If you want a proper introduction to Obsidian before continuing, [this guide](https://obsidian.rocks/getting-started-with-obsidian-a-beginners-guide/?ref=jdhwilkins.com) (not affiliated) is a good starting point.
As I mentioned, I keep my knowledge layer in a completely separate Obsidian vault. This post covers the task layer only. Having both open side by side is straightforward when I need to cross-reference them, and keeping them separate has meant each vault stays focused on one job. I will probably look at combining them at some point, but for now, this setup works just fine.
---
## The Obsidian CLI skill
The core of the AI side of the system is a Claude Code skill called ***obsidian-cli***. It gives any Claude agent a consistent interface for reading and writing to an Obsidian vault, using Obsidian's own command-line interface rather than touching the underlying files directly.
When an AI agent reads or writes files directly using standard file system operations, Obsidian has no awareness of those changes, often resulting in broken links. The CLI routes all operations through Obsidian's own runtime instead, so the vault's internal state stays consistent with whatever the agent is doing.
There is also a token efficiency argument. The CLI queries Obsidian's existing indexes rather than scanning raw files, which is [significantly faster and cheaper](https://prokopov.me/posts/obsidian-cli-changes-everything-for-ai-agents/?ref=jdhwilkins.com) than grep-style file operations.
Because the skill is vault-agnostic, I use the same one across both of my vaults. Any Claude agent running on my machine, from any project folder, has access to the same interface.
If you want to go deeper into how Claude Code skills work, I have written about [getting started with agent skills](https://www.jdhwilkins.com/getting-started-with-agent-skills) and [how to write them well](https://www.jdhwilkins.com/level-up-your-ai-agent-with-skills-engineering).
## The todo-vault skill
The ***todo-vault skill*** sits on top of the CLI and defines the actual shape of the task system and how the agent should use it. This is where the task organization component lives.
The skill establishes six note types, each with its own folder and frontmatter schema:
**Tasks:** undated, one-off action items
**Reminders:** date-sensitive tasks
**Repeated tasks:** recurring items with a defined schedule
**Habits:** personal habits tracked with a streak counter and history log
**Events:** scheduled appointments, with optional pre- and post-checklists
**Notes:** freeform reference material
Completed tasks, reminders, and events are archived automatically to 'old' subfolders. Repeated tasks and habits are never archived as they track a last-completed date and resurface on schedule. Having six clearly defined types means the agent can handle ingesting new items very reliably.
---
### The morning briefing
Perhaps my favourite feature of the skill is the ***morning briefing***, an eleven-step routine that runs automatically on a scheduled trigger each day. This is where the daily note and the review cadence components come in.
The routine starts by syncing yesterday's checkbox states back to each note's metadata - so if I ticked off a task in the daily note, the task note itself gets updated too (this is just a quirk of how Obsidian links work). Then it archives completed items, updates habit streaks, and compacts old daily notes into year/month subdirectories. After that, it scans for anything due in the next seven days, fetches a weather forecast, and builds the day's task list.
Rather than applying a fixed prioritisation rule, the briefing reads a pair of context files stored in the vault before building the list. Those files tell the agent what it needs to know to make sensible decisions. This includes what kinds of work I do, which days suit which types of tasks, what is currently in progress and my overall goals. Items from yesterday that were not completed carry forward with higher priority.
The output is a ***daily note*** containing the task list, today's habits, a seven-day forward view, and a weather summary. That note is my scheduling system for the day. Claude assembles the initial draft, but since these are just text files, I can make any necessary tweaks myself.
### Agent-managed context
The morning briefing's behaviour is influenced by two additional reference files from the vault.
[context.md](http://context.md/?ref=jdhwilkins.com) is mine to maintain. It holds facts and information the agent should know about me, such as my current goals and ambitions, my constraints, the things I'm working on and any long-term timelines or schedules.
[agent-notes.md](http://agent-notes.md/?ref=jdhwilkins.com) is maintained by the agent. It accumulates behavioural observations over time. So if I consistently skip a particular task, overload certain days of the week, or my working patterns change, that all gets recorded by the agent. The file is compacted periodically to keep it manageable.
Keeping both files inside the vault means I can update my context without touching the skill itself. The skill has a fixed instruction set, while the vault acts as a mutable data layer.
---
## Bringing it all together
Here is how this all looks in practice from my perspective.
The **inbox** is a speech-to-text brain dump using ***WisprFlow***. I speak, it transcribes, and I end up with a raw note full of tasks, ideas, and reminders in no particular order. It is the lowest-friction capture method I have found. (Not sponsored, it's just the best tool I've found so far.)
The **task organisation** is handled by Claude Code acting as an ingest mechanism. It reads the brain dump, identifies what each item is, and creates the appropriate note type in the vault. Tasks become task notes. Reminders get dates. Events go into the events folder. The vault ends up with clean notes without any manual filing.
The **daily note** is produced each morning by the briefing, running on its scheduled trigger. It is the single view I use to run my day.
The daily and weekly review comes into play here as well. Habit streaks are tracked automatically, carried-over tasks are flagged, and [agent-notes.md](http://agent-notes.md/?ref=jdhwilkins.com) builds a running picture of patterns over time. A more structured weekly review is something I am still developing, but the briefing already catches most of what a manual weekly check-in would surface.
The **archive** is fully automatic, as completed items are moved to old/ subfolders. Daily notes older than seven days move into Daily/YYYY/Month-Name/ folders, too. This means that the vault stays organised with no additional effort on my part.
The system as a whole is a reasonable answer to the context engineering problem. My data is structured, consistently maintained, and available to Claude in a form it can actually use. The agent is not working from a blank slate every morning. It has a current picture of what I am working on, what my priorities are, and how I tend to behave.
## Before you try this yourself...
The most important thing, if you are thinking about building something similar, is to really spend some time figuring out how you want to use such a system and what sort of structure will work for you. It'll take some trial and error to get it right. I often tweak my setup to add features and edit my morning briefing.
If there is interest in a deeper dive into the vault structure, skill files, and templates, let me know in the comments. There is a lot more to cover than fits in a single post.
### Role prompting - Giving AI a Persona
URL: https://www.jdhwilkins.com/role-prompting-giving-ai-a-persona/
Last updated: 2026-08-10T09:45:26.000Z
```
"You're an expert X."
```
```
"Act as a Y"
```
***Role prompting*** is one of the most widely repeated tips in AI circles. The underlying idea is that if you assign the model a job title or area of expertise, it will respond more like a person who holds that role, making it more relevant, more precise, more expert-sounding.
The research on whether that actually holds up is more nuanced than the advice suggests. And the nuance is important if you want to try this out yourself.
---
## **What is role prompting?**
Role prompting means giving an AI model a character, job title, or area of expertise before asking it to complete a task. A basic example:
```
You are an experienced HR manager. Review the following job description and suggest improvements.
```
The model has not changed. Its training data and knowledge base are no different. But the assigned persona shapes how it interprets the request and how it frames its response. That framing effect is real but also limited in ways worth understanding.
## **Does assigning an AI persona actually improve outputs?**
The common assumption behind role prompting is that an expert label produces expert results. A 2023 study tested this directly, evaluating persona prompting across four major language model families. The finding was that **personas**generally **had no effect on performance**, or a small negative one, compared to prompting with no persona at all.
A 2025 report from the Wharton Generative AI Lab reached a similar conclusion for factual tasks. Assigning a model the label "physics expert" before a physics question produced no consistent improvement in accuracy across tested models (with the notable exception of Gemini 2.0 Flash, which did show measurable impact from expert personas). The report's title makes the point plainly: *Playing Pretend: Expert Personas Don't Improve Factual Accuracy* .
The reason is fairly straightforward. A persona does not add knowledge that the model does not already hold. If the training data does not contain reliable information on a topic, attaching an expert label to the prompt will not change the answer.
> A persona does not add knowledge the model does not have. The expertise is either in the training data or it is not.
A 2024 paper described the persona as a "double-edged sword", and the edge cuts sharper than the framing suggests. Role-playing prompts do not just fail to improve reasoning; in tests on Llama 3, persona-based prompts produced worse performance than neutral prompts on seven out of twelve reasoning datasets. The risk for logic-heavy tasks is not that the persona does nothing, but that it actively gets in the way.
The effects are also largely unpredictable. Some personas occasionally produce gains, but the pattern does not hold reliably enough to plan around. Automated strategies designed to identify the best persona for a given question have been tested and found to perform no better than random selection.
It is not just the "expert" label that matters, either; a persona's gender, domain, and specific framing can all shift outputs in ways that are not intuitive or consistent.
---
## **Where role prompting does help**
The research is not uniformly negative. The effects are task-dependent, and that is where the practical value lies.
**For writing, communication, and tone-sensitive tasks, role prompting shows more consistent benefits.** When you assign the model the perspective of "a plain-language editor reviewing a policy document", you are not asking it to access hidden knowledge. You are narrowing the range of plausible responses toward a particular style and set of priorities.
Compare the same request with and without a persona:
```
Give feedback on this email.
```
```
You are a direct manager reviewing an email before it goes to a client. Give feedback on tone and clarity, and flag anything that could be misread.
```
The second prompt will produce more pointed, more actionable feedback. The persona has established a vantage point for the model to respond from. The model's underlying knowledge is unchanged.
> Used for tone and framing, a persona gives the model a useful perspective. When used as a substitute for expertise, it tends to disappoint.
## **How to write a role prompt that works**
A few things make the difference between a useful persona and a decorative one.
**Specify the audience, not just the role.** "You are a marketing consultant writing for a non-technical audience" gives the model more to work with than "you are a marketing expert." The audience shapes vocabulary and level of detail as much as the role does.
**Match the persona to the output you actually want.** A persona works best when it naturally implies the tone and priorities you are after. "You are a copy editor focused on concision" tells the model what to prioritise.
**Avoid low-knowledge personas.** Assigning roles such as "young child", "toddler", or "layperson" is consistently harmful to output quality. Research shows these labels reliably reduce benchmark accuracy across tasks. If you want simpler language, specify that in the output instructions rather than in the persona itself.
**Consider asking the model to generate its own persona.** Rather than handcrafting a role, you can ask the model to describe the kind of expert best suited to the task, then use that description as the persona. Research suggests LLM-generated personas tend to produce more stable results than those written by hand.
**Avoid relying on a persona for factual questions.** If you need accurate information, prompt clearly and verify the output independently. An expert label will not make the answer more reliable and may produce unwarranted confidence.
---
## **A note on mitigating the risks**
For users who want the framing benefits of a persona without the risk of degraded reasoning, one approach worth knowing about is what researchers call the "Jekyll and Hyde" method. This involves running the same task twice: once with a role-playing prompt and once with a neutral prompt, then using a model to evaluate both outputs and select the better one. It adds a step, but it guards against the cases where a persona pulls the response in the wrong direction.
## **Final thoughts**
Role prompting is a useful technique when applied to the right kinds of tasks. For tone, style, framing, and audience-sensitive work, a well-chosen persona can make outputs more relevant. For reasoning and knowledge-heavy tasks, the evidence points the other way. Personas often have no effect, can actively degrade performance, and behave unpredictably enough that even targeted attempts to find the right persona tend to fail.
Use role prompting to define *how* the model should respond, not to conjure knowledge or reasoning ability it does not have. Avoid low-knowledge personas, consider letting the model generate its own role description, and for high-stakes reasoning tasks, treat any persona with scepticism.
Role prompting sits alongside zero-shot and few-shot prompting as part of a broader toolkit. If you are building from first principles, the article on [the fundamentals of prompting](https://www.jdhwilkins.com/the-fundamentals-of-prompting-getting-started-with-ai) is the right starting point. Few-shot prompting covers the next most practical technique for shaping AI outputs.
---
## **References**
*When "A Helpful Assistant" Is Not Really Helpful: Personas in System Prompts Do Not Improve Performances of Large Language Models* (2023). [https://arxiv.org/abs/2311.10054](https://arxiv.org/abs/2311.10054?ref=jdhwilkins.com)
Wharton Generative AI Lab (2025). *Playing Pretend: Expert Personas Don't Improve Factual Accuracy.* [https://arxiv.org/abs/2512.05858](https://arxiv.org/abs/2512.05858?ref=jdhwilkins.com)
*Persona is a Double-edged Sword: Enhancing the Zero-shot Reasoning by Ensembling the Role-playing and Neutral Prompts* (2024). [https://arxiv.org/abs/2408.08631](https://arxiv.org/abs/2408.08631?ref=jdhwilkins.com)
### Jargon Buster i. AI, Machine Learning, Deep Learning, Generative AI
URL: https://www.jdhwilkins.com/jargon-buster-i-ai-machine-learning-deep-learning-generative-ai/
Last updated: 2026-08-10T09:45:12.000Z
**AI, Machine Learning, Deep Learning, Generative AI,** and **LLMs** are all terms commonly thrown around in tech writing, news and media, but they each refer to slightly different things and shouldn't be used interchangeably... even if they sometimes are.
This guide explains what each one actually means, how they relate to each other, and why it matters which is which.
## What is AI, exactly?
***Artificial intelligence*** is the broadest of the four terms. It describes any computer system capable of performing tasks that would typically require human intelligence: understanding language, recognising images, making decisions, or solving problems.
This category is wider than most people assume. A rule-based chatbot that responds "I didn't understand that" to anything outside of a predetermined script counts as AI. So does a simple chess program from the 1970s. Neither is particularly impressive, but both qualify as AI.
What most early AI systems had in common was that a human wrote all the rules. The program followed instructions. It didn't learn anything on its own.
---
## What is machine learning, and how does it differ from AI?
***Machine learning*** is a subset of AI. It changed the way these AI systems are built.
Instead of a programmer writing explicit rules, a machine learning model is trained on data. You show it many examples, and it works out the patterns itself. Feed a machine learning model enough labelled images, and it learns what distinguishes a cat from a dog, without being told which features to look for.
The model can generalise to new examples it hasn't seen before, and it adapts as it encounters more data. A traditional rule-based system can't do that.
> The key distinction is not capability but method: were the rules written by a human, or learned from data?
## What is deep learning?
***Deep learning*** is a subset of machine learning. It uses a specific type of model called a ***neural network***, loosely inspired by the structure of the human brain. They consist of a connected network of nodes where each node performs calculations before passing data off to the next one.

Nodes are grouped into layers. The "deep" in deep learning refers to the number of layers, which can run into the hundreds.
The significant advantage of deep learning is how well it handles unstructured data such as text, images, and audio. Earlier machine learning methods often required careful preparation of data before it was given to the model, but Deep learning can learn directly from the raw input data.
Most of the AI that gets people's attention today sits on deep learning foundations. Image recognition, speech-to-text, language translation, and large language models all use it.
> Deep learning is what made modern AI practical at scale. Most of the 'impressive' systems we use today are built on a foundation of deep learning.
---
## What is generative AI, and where does it fit in?
This is where the hierarchy gets slightly less tidy. ***Generative AI*** doesn't describe a new level in this stack. It describes a type of output.
Generative AI is AI that produces new content: text, images, audio, video, or code. ChatGPT generates text. Midjourney generates images. Both use deep learning under the hood, and both are AI in the broadest sense. The "generative" label tells you what they do, not how they're built.
This is what distinguishes them from a model that classifies whether an email is spam. That model also uses deep learning and machine learning. It makes a decision. It doesn't create anything.
> *Note: "generative AI" has also become a marketing term. When a product claims to be "powered by generative AI," it most likely means it uses a large language model or an image generation model.*
## What is a Large Language Model?
A Large Language Model (LLM) is a specific type of generative AI. It uses a deep learning model to generate text. Chat GPT, Google Gemini, and Claude are all examples of an LLM.
---
## Why are these terms used interchangeably?
Largely because of marketing. "AI" became the label to reach for because it sounds impressive. Once that happened, it got applied to almost anything involving a model or an algorithm.
There's also a technical reason. The categories genuinely overlap. Generative AI uses deep learning. Deep learning uses machine learning. Machine learning is AI. Calling a washing machine "AI" might not be wrong, but it's definitely not using the same technology as ChatGPT.

The problem is that this overlap becomes misleading when precision matters.
## Why does it matter which term you use?
Understanding the distinctions helps you ask better questions and calibrate your expectations.
If a company says their product "uses machine learning," that tells you something specific. There's a model. It was trained on data. If they say it "uses AI," that tells you almost nothing. It could mean a rule-based model written in 2009 or a state-of-the-art large language model. You can't tell from the label.
As [IBM's explainer on AI and machine learning](https://www.ibm.com/think/topics/ai-vs-machine-learning-vs-deep-learning?ref=jdhwilkins.com) puts it: AI is the field, machine learning is the method, and deep learning is the technique. Getting these straight helps you engage with the technology on its own terms, rather than its marketing.
There's a simpler benefit, too. Hype becomes much easier to spot. A lot of the noise around AI comes from people treating one term as a catch-all for all four.
---
## Final thoughts
AI is the umbrella. Machine learning is a method within it. Deep learning is a technique within that. Generative AI describes what a system does with its output.
Understanding the distinctions won't make you a developer, but it will make you a more informed user of the tools, and a harder target for marketing that relies on the confusion.
If you want to put this into practice, [The Fundamentals of Prompting](https://www.jdhwilkins.com/the-fundamentals-of-prompting-getting-started-with-ai) covers how to get more out of the AI tools you're already using day to day.
*Sources:*
- [*AI vs. Machine Learning vs. Deep Learning | IBM*](https://www.ibm.com/think/topics/ai-vs-machine-learning-vs-deep-learning?ref=jdhwilkins.com)
### AI's Blindspot: The 'Lost in the Middle' Effect
URL: https://www.jdhwilkins.com/ai-s-blindspot-the-lost-in-the-middle-effect/
Last updated: 2026-03-22T12:00:00.000Z
There's a weird phenomenon with the way AI reads documents and conversations, and it negatively impacts the accuracy of the responses we get back.
AI's accuracy when **recalling information located in the middle of the context window is lower than if the same information were located at the start or the end**.
It's known as the **'Lost in the Middle' effect**, and it's a problem that researchers have studied in some depth. The consequences of this are pretty simple to understand and can make a real difference to the results we are able to get from AI tools.
## A quick note on context
If you haven't come across the term before, a ***context window*** is the total amount of text an AI model can hold in its working memory at once. Everything you type and everything you paste in counts toward that limit, along with the model's own replies. Think of it as a whiteboard with a fixed amount of space.
For a full explanation, [Context Windows and Tokens](https://tokens-and-context-windows-what-they-are-and-why-they-matter/?ref=jdhwilkins.com) covers this in detail.
The important point here is this: fitting inside the context window and being read with equal attention throughout are not the same thing.
---
## What does "Lost in the Middle" mean?
In 2023, researchers published a study titled: "*Lost in the Middle - How Language Models Use Long Contexts"*. They tested how well language models could retrieve specific information from long inputs, systematically varying where in the document that information appeared.
When relevant details appeared near the start of the input, models performed well. Near the end, performance was also reasonably strong. In the middle, there was a notable decrease. This remained true even for models specifically designed to handle long inputs.
## Why do AI models favour the start and end of an input?
This comes down to ***positional bias***: the tendency of models to weight the attention they pay to text depending on where it is in the input.
***Primacy bias*** is the preference for information near the start. ***Recency bias*** is the preference for information near the end. The model isn't consciously skipping the middle. It's a consequence of how these systems are trained and how attention is distributed across long sequences of text. Either way, details sitting in the middle of a long context are the most at risk of being missed.
---
## The Effect of Filling the Context Window
More recent research (Veseli et al., 2025) adds another layer of complexity. The Lost in the Middle effect isn't constant - it changes depending on how much of the context window your input is occupying.
When your input uses up to around half of the available window, the effect is at its strongest. Primacy bias is high; the start of your input carries disproportionate weight. As the input grows toward the limit of the window, that changes. Primacy bias weakens considerably, and the Recency bias, by contrast, stays stable regardless of input length.
What this means in practice is that the more you push an AI toward its context limit, the less you can rely on the start of your input being treated carefully. However, the accuracy of recalling information at the end of your input remains pretty consistent throughout.
For those curious, the graph of accuracy Vs position in the context looks like this. The different lines show how full the context window is.
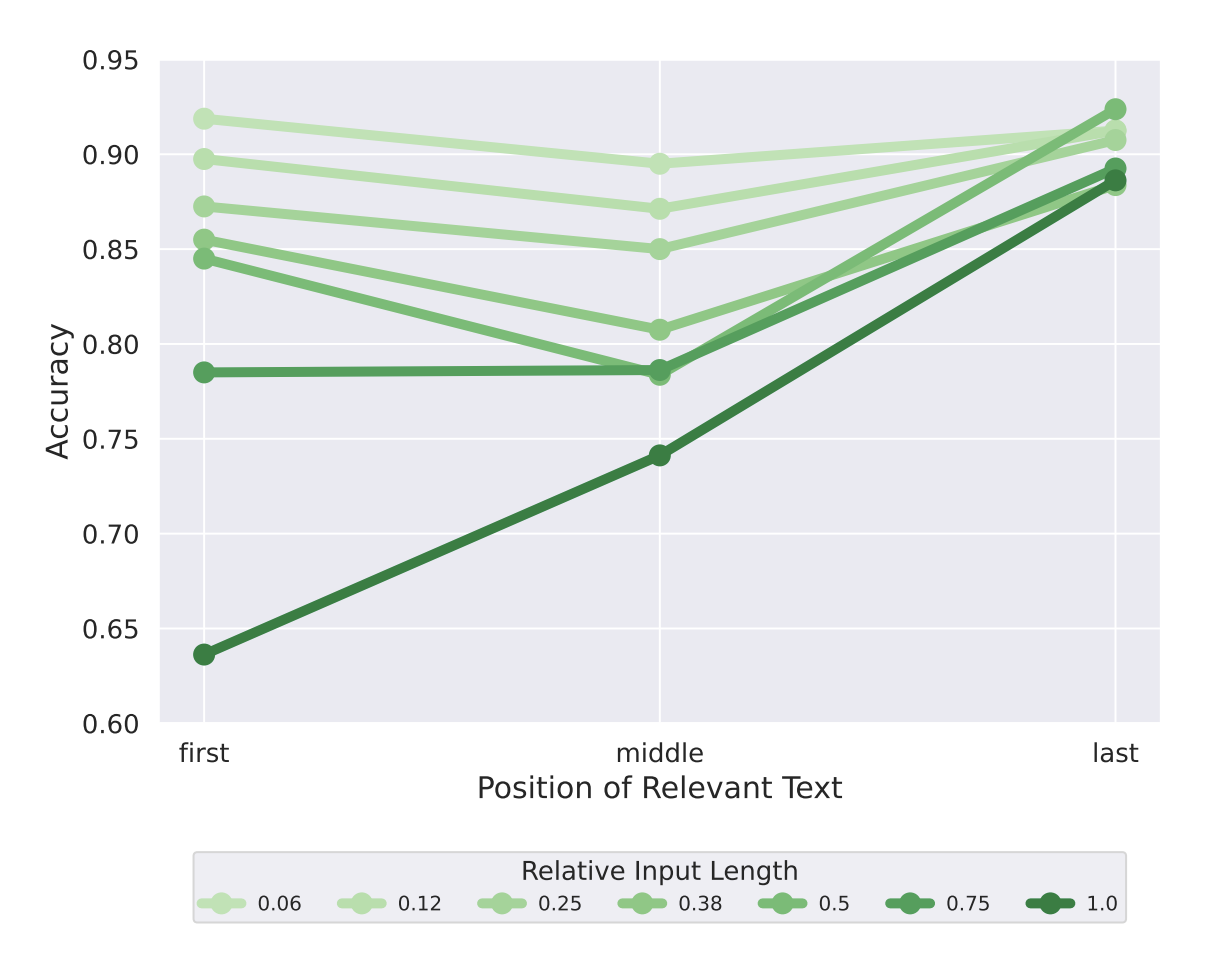
## How to structure your prompts when working with long documents
**Lead with what matters most.** For short to moderate-length inputs and conversations, primacy bias works in your favour. Put your key instruction, the specific question you want answered, or the most important context right at the start. Don't bury it after a lengthy preamble.
**Repeat critical details near the end.** For longer inputs, stating something important near both the start and end gives it a better chance of being registered. It might seem slightly redundant, but it can often be worth it.
**Pull out the relevant section.** If you're working with a lengthy document and asking about something specific, extract the relevant passage and place it close to your question. Don't assume the model has attended equally to every page. The less you put in the context window, the more accurate the overall response will be.
**Break it into chunks.** Rather than pasting an entire document at once, asking targeted questions on individual sections is often more reliable than a single pass over everything.
---
## Putting it all together
The way AI reads long documents is not the same as how a person skims one. Position matters. The middle is consistently the most vulnerable part of any long input, and that vulnerability is amplified as the context window fills.
Fortunately, it's quite simple to act on. We can structure our inputs with intent, lead with what matters, and avoid burying critical information where it is least likely to be remembered.
For more on getting better results from AI tools, [Getting Started with AI - The Fundamentals of Prompting](https://www.jdhwilkins.com/the-fundamentals-of-prompting-getting-started-with-ai) is a solid starting point. [You're Using ChatGPT Wrong - Here's How to Prompt Like a Pro](https://www.jdhwilkins.com/you-re-using-chatgpt-wrong-here-s-how-to-prompt-like-a-pro) goes further into practical technique.
## References and Further Reading
[Positional Biases Shift as Inputs Approach Context Window Limits](https://arxiv.org/pdf/2508.07479?ref=jdhwilkins.com)
[Lost in the Middle: How Language Models Use Long Contexts](https://arxiv.org/pdf/2307.03172?ref=jdhwilkins.com)
### Claude Code: Everything you need to know in 8 minutes or less
URL: https://www.jdhwilkins.com/claude-code-everything-you-need-to-know/
Last updated: 2026-08-10T09:44:50.000Z
Claude Code is an AI tool that runs in the terminal. For a lot of people, that sentence is enough to put them off. That would be a mistake.
While it may have been designed as a coding assistant, it's really just an agent capable of managing your files, using skills, and writing and running code (all by itself) to solve whatever problem you throw at it.
Claude Code is one of the more capable AI tools currently available, and you do not need a programming background to get real value from it. This guide covers everything from the basics of how it works through to its most advanced features, so you can decide how far you want to take it.
This is, however, not a setup guide. You can find one of those [here](https://code.claude.com/docs/en/setup?ref=jdhwilkins.com).
---
## What is Claude Code, and how is it different from a chatbot?
Most AI tools work like this: you ask a question, you get an answer, you copy it somewhere useful. ***Claude Code*** works differently. Rather than generating text for you to act on, it takes action directly on your computer.
It can read files; write, edit and run code; install software, and build things from scratch. You describe the goal in plain English; Claude figures out how to achieve it.
For users without the slightest knowledge or interest in coding, Claude Code can still be a really powerful tool for things like:
Summarising and reorganising a folder of documents or meeting notes
Pulling data from a website and structuring it into a spreadsheet
Generating a report by reading from Notion, Airtable, or your local files
Renaming and sorting large numbers of files according to your own rules
Building a simple internal tool or dashboard
The name may imply a coding assistant, but the actual scope is considerably wider.
The ***terminal*** is the text-based interface that Claude Code runs in. If you have never used it, the setup is simpler than it looks. Once installed, you type claude to open it and Ctrl+C twice to close it. After that, you just type what you want in plain English.
You can also use Claude Code through the Claude for Desktop application, which has a slightly simpler user interface.
---
## Writing better prompts
A ***prompt*** is simply what you type to tell Claude Code what to do. The quality of what you get back depends heavily on the quality of what you put in.
Vague prompts produce vague results. "Build me a website" will get you something generic. "Build me a portfolio website with a dark background, a two-column layout, and a contact form at the bottom" will get you something useful. The more specific you are about the outcome, the better Claude can deliver it.
You can learn more about writing better prompts [here](https://the-fundamentals-of-prompting-getting-started-with-ai/?ref=jdhwilkins.com).
Once Claude understands the context of your project, shorter follow-up prompts work well. Clarity matters more than length.
## You are always in control
Claude Code does not act without permission. Before it takes a significant action, such as installing a package, calling an external service, or deleting a file, it stops and asks you to approve it first.
You can configure this behaviour in a file called 'settings.local.json'.
Low-risk, routine actions like reading files or running tests can be pre-approved, so Claude does not have to pause and check every time. More consequential actions stay gated behind your approval. You can also specify a deny list: files that Claude is never permitted to read, regardless of what it is working on. This is useful for keeping credentials and environment variables completely off-limits.
You don't need to edit this file yourself. You can just ask Claude to do it for you:
What permissions do you have enabled?
Can you add permission to do X to your settings file?
---
## How Claude thinks
Claude Code has a set of built-in ***tools*** it can draw on: reading files to understand your project, writing and editing files directly, and running terminal commands. You describe the goal; Claude combines the tools as needed.
Alongside these tools, Claude has a ***context window*** which functions as its working memory for the current conversation. Everything in that window is what Claude can see: your messages, its own responses, and the contents of any files it has read. Once the window fills up, outputs can start to degrade as earlier information gets pushed out or summarised.
You can manage this with two commands. /clear starts a completely fresh session. /compact is more surgical: it summarises what has happened so far and clears the noise while keeping what matters. Claude will also trigger this automatically when the context window reaches around 85--95% capacity, and when you run it manually, you can append instructions about what to prioritise or preserve. Sessions are saved automatically, so you can type claude --resume to pick up exactly where you left off, or browse previous sessions and jump back into any of them.
Usage is measured in ***tokens***, roughly three-quarters of a word each. Every prompt, response, and file read costs tokens. You can track your spending at any time with /cost.
> A full explanation of how context windows and tokens work, including how they affect AI tools more broadly, is available in [Context Windows and Tokens: What They Are and Why They Matter](https://tokens-and-context-windows-what-they-are-and-why-they-matter/?ref=jdhwilkins.com)
---
## Choosing the right model
Claude Code uses a family of models you can switch between mid-conversation using /model:
**Haiku** \-- fastest and cheapest, good for simpler or repetitive tasks
**Sonnet** \-- the balanced all-rounder and the sensible default for most work
**Opus** \-- the most capable, but also the most expensive
Most work lands naturally on Sonnet. Opus is worth reserving for genuinely complex problems where the extra capability justifies the cost.
## Making Claude remember your preferences
Claude Code has two systems for carrying information across sessions, and they serve different purposes.
[**CLAUDE.md**](http://claude.md/?ref=jdhwilkins.com) is a markdown file located inside your project folder (and created automatically when you run the /init command. More on commands later.). Claude reads it at the start of every session. Use it to describe the project structure, set rules, or provide context that Claude would otherwise have to re-learn each time.
The ***memory*** system is automatic and works across all your projects. Claude picks up on patterns over time: your preferred working style, the language you use, the way you like things formatted. It stores them as preferences that it applies in future sessions. You can ask Claude to add, change, or review what it has remembered at any point.
Together, these two systems mean you spend far less time re-explaining yourself every time you start a new session.
> The difference between [CLAUDE.md](http://claude.md/?ref=jdhwilkins.com) and memory is scope. [CLAUDE.md](http://claude.md/?ref=jdhwilkins.com) is project-specific and intentional; memory is automatic and applies everywhere.
---
## Shortcuts and customisation
Claude Code comes with built-in ***slash commands*** that trigger specific actions. /init sets up a new project, /compact manages the context window, and /help lists everything available. You can also create your own custom slash commands for tasks you repeat often.
***Skills*** are pre-written instruction sets that load specialist knowledge into the conversation when triggered. If you want Claude to follow a specific workflow, write in a particular style, or produce a consistent kind of output, a skill can encode all of that and activate automatically. You can learn how to develop your own skills [here](https://getting-started-with-agent-skills/?ref=jdhwilkins.com) .
***Hooks*** are background scripts that run when specific events happen. You might set one up to auto-format a file every time Claude saves it, or to log every command Claude runs. They execute without using AI tokens.
***Flags*** are options you set when launching Claude Code. They control which model is used, which tools Claude has access to, and how much autonomy it has in a given session. For example, --verbose shows what Claude is doing in detail, and --model lets you specify a model from the start.
Claude Code also has ***extended thinking*** built in. Rather than jumping straight to a response, Claude is given a dedicated budget of reasoning tokens to work through complex problems step by step before it acts. It is on by default, and it makes a noticeable difference in tasks that involve multiple dependencies or complex decisions.
## Keeping track of your work
Before every file edit, Claude creates a ***checkpoint*** \- an automatic snapshot of the current state. If something goes wrong, you can use /redo to see a list of previous states and restore any of them.
Claude Code also connects to Git, which underpins the checkpoint system and enables broader version control. You can review changes before committing, work across separate branches, and collaborate without overwriting each other's work.
---
## Connecting to the wider world
***MCP servers*** (Model Context Protocol) extend Claude Code beyond your local machine. They allow Claude to connect to external platforms, such as Notion, Airtable, or Asana, and take actions within them: pulling data, pushing updates, or triggering workflows. The connection is configured once and then available across sessions.
You can learn more about MCP servers [here](https://mcp-servers-giving-your-ai-agent-new-capabilities/?ref=jdhwilkins.com).
Claude Code also supports images. You can paste a screenshot or design reference directly into the conversation. This is useful for showing a bug visually or giving Claude a design to work from.
## Picking up a session from another device
***Remote Control*** lets you connect to a Claude Code session running on your machine from any other device. Start a task at your desk, then monitor or continue it from your phone or a browser somewhere else. The session keeps running locally the entire time.
To start one, run claude remote-control from your project directory. Claude Code generates a session URL and a QR code you can scan to connect from the Claude mobile app. Your local files, MCP connections, and project configuration all stay on your machine; the remote interface is just a window into the local session.
This is particularly useful for longer-running tasks. You can kick off something that will take a while, step away from your desk, and check in on progress without the session ending or anything being sent to the cloud.
> *Remote Control is available on all plans. On Team and Enterprise accounts it is off by default until an admin enables it.*
## Going autonomous
For larger or more complex work, Claude Code supports patterns that reduce the need for step-by-step human involvement.
***Sub agents*** are separate Claude instances that run in their own isolated context. The main Claude session delegates a task, the sub agent handles it independently, and returns the result. This keeps the main conversation clean and allows multiple tasks to run in parallel without interfering with each other.
***Agent teams*** take this further. Where sub-agents only communicate back to the main session, agents in a team can talk directly to each other and share a task list. This is useful for large builds where different parts of the work are genuinely independent: one agent on the backend, another on the frontend, a third running tests. Each works in its own context without interrupting the others, and the whole thing moves considerably faster than a single agent working through the same tasks in sequence.
***Work trees*** let you create isolated working directories, each on its own Git branch, using the --worktree flag. Multiple Claude instances can work on different features simultaneously and merge back when done.
***Headless mode***, activated with the -p flag, runs Claude Code with no human interaction at all. No approvals, no conversation -- just a fully autonomous loop from prompt to output. Combined with --allowed-tools to define what Claude can access, this is useful for scripted or scheduled tasks where you want Claude to run unattended.
---
## What this adds up to
Claude Code is a substantial step beyond a chat interface. At its most basic, it turns plain English into actions on your computer. At its most advanced, it coordinates multiple agents working in parallel on different parts of a project.
The best part is you can use as many or as few of these features as you feel comfortable. Even without these extra tools, Claude Code is still an exceptionally powerful tool.
For a deeper look at how to write effective prompts, a skill that carries across every AI tool, [You're Using ChatGPT Wrong: Here's How to Prompt Like a Pro](https://www.jdhwilkins.com/you-re-using-chatgpt-wrong-here-s-how-to-prompt-like-a-pro) covers the underlying ideas in detail. And if the context window section above sparked questions, [Context Windows and Tokens](https://www.jdhwilkins.com/context-windows-and-tokens-what-they-are-and-why-they-matter) goes much further into how that works.
### Tokens and Context Windows: What They Are and Why They Matter
URL: https://www.jdhwilkins.com/tokens-and-context-windows-what-they-are-and-why-they-matter/
Last updated: 2026-08-10T09:45:02.000Z
You're partway through a long conversation with an AI. Somewhere around message fifteen, it seems to have completely forgotten the crucial instructions you gave it at the start.
This is the context window problem. It's not a glitch or the AI is being difficult, but rather a fundamental part of how these models work. Understanding it makes a real difference to how we use them day to day.
## What is a token?
Before we can talk about context windows, we need to discuss ***tokens*** : the unit AI models use to measure text.
Tokens are not the same as words. When an AI model reads your input, it first breaks it into small chunks called tokens. A token might be a whole word, part of a word, a punctuation mark, or even a space. The word darkness typically becomes two tokens: dark and ness. The word Hello is one.
As a rule of thumb, one token is roughly four characters of English text, or about three-quarters of a word. A 200-word document is somewhere in the region of 250-300 tokens.
> *Tokens are the unit AI models use to measure text. They don't line up neatly with words. Think of them as smaller, irregular chunks of language.*
---
## What is a context window?
The ***context window*** is the total number of tokens an AI model can hold in its working memory at any one time.
Everything counts toward this total: your messages, the documents you paste in, and the model's own responses. Think of it like a whiteboard. The model can only see what's written on the whiteboard, and once it's full, something has to be wiped off to make space.
This sets a hard ceiling on how much information the model can work with in a single session.
## Why does the AI seem to forget earlier parts of a conversation?
When a conversation grows long enough to fill the context window, the model can no longer access the tokens that were pushed out. The instructions you gave at the start of the conversation, or the document you pasted in, may simply no longer be visible.
The model isn't forgetting in any meaningful sense. It just can't read beyond the edge of the window.
> When the AI loses the thread, it's rarely because of a reasoning failure. More often, the relevant context has simply scrolled out of view.
---
## How big are context windows?
Context window sizes vary considerably by model. At the time of writing, mainstream tools generally offer somewhere between 128,000 and 200,000 tokens as a standard. Some newer models are offering windows of one million tokens or more.
*A note on figures: context window sizes are increasing rapidly. The numbers above reflect the current state of things* ,*but may have changed since publication. It's worth checking the documentation for the specific tool you're using.*
One other thing worth noting: advertised capacity and reliable performance don't always match up. Some models start to lose coherence as the context fills. Effective capacity tends to run lower than the headline figure suggests.
## How to work effectively within context window limits
You don't need to understand the technical details to benefit from this. Two practical habits help.
- Starting a fresh conversation resets the window entirely. If you're switching to a new task, a new chat is usually better than continuing an old one.
- AI models suffer from the "Lost in the Middle" effect, where information buried in the center of a long conversation is easily forgotten. For the best results, place vital instructions at the start of your prompt and restate them as the conversation grows to keep them within the model's focus.
---
## What is Context Compacting?
Some tools handle a full context window more gracefully than others. Rather than simply dropping old tokens, ***context compacting*** is a technique where earlier parts of a conversation are automatically compressed into a summary. The key points are preserved; the verbatim text is not.
This is a cleaner solution than losing context entirely, but it's worth knowing it's happening. A compressed summary of earlier instructions is not the same as having those instructions in full. For high-stakes or specific tasks, starting a fresh conversation with key context restated is still the more reliable approach.
> *Not all tools implement context compacting. Claude Code handles this automatically when the window fills. Other tools may simply truncate without warning.*
## Putting it together
The context window is one of the most useful concepts to understand when working with AI tools. Tokens tell you *how* AI measures text. The context window tells you *how much* of it the model can see at once. When the AI starts giving vague or inconsistent responses mid-conversation, there's a good chance something important has scrolled out of view.
If you want to get more out of these tools, prompting well is the natural next step. [Getting Started with AI - The Fundamentals of Prompting](https://www.jdhwilkins.com/the-fundamentals-of-prompting-getting-started-with-ai) is a good starting point, and [You're Using ChatGPT Wrong - Here's How to Prompt Like a Pro](https://www.jdhwilkins.com/you-re-using-chatgpt-wrong-here-s-how-to-prompt-like-a-pro) goes deeper into practical techniques.
## Sources and Further Reading
[https://help.openai.com/en/articles/4936856-what-are-tokens-and-how-to-count-them](https://help.openai.com/en/articles/4936856-what-are-tokens-and-how-to-count-them?ref=jdhwilkins.com)
[https://blogs.nvidia.com/blog/ai-tokens-explained/](https://blogs.nvidia.com/blog/ai-tokens-explained/?ref=jdhwilkins.com)
[https://learn.microsoft.com/en-us/dotnet/ai/conceptual/understanding-tokens](https://learn.microsoft.com/en-us/dotnet/ai/conceptual/understanding-tokens?ref=jdhwilkins.com)
[https://www.elvex.com/blog/context-length-comparison-ai-models-2026](https://www.elvex.com/blog/context-length-comparison-ai-models-2026?ref=jdhwilkins.com)
### MCP Servers: Giving Your AI Agent New Capabilities
URL: https://www.jdhwilkins.com/mcp-servers-giving-your-ai-agent-new-capabilities/
Last updated: 2026-06-09T08:53:00.000Z
AI agents are useful on their own. But out of the box, they're working in isolation --- they can only see what you paste into the conversation. They can't check your calendar, search your company's files, pull live data from a platform you use, or send a message on your behalf.
> MCP servers change that.
---
## What is an MCP server?
MCP stands for Model Context Protocol. The technical details aren't important. What matters is what it does: an MCP server is a connection between your AI agent and an external tool or service.
Once connected, your agent can interact with that service as part of its normal workflow. Instead of you copying data out of one tool and pasting it into a chat window, the agent can go and get it directly.
Think of it like giving your agent a new ability. Before the connection, it can't see your Google Drive. With MCP, it can search, read, and reference your files and use them to inform its response.
---
## What are they used for?
MCP servers exist for most of the tools we use every day. There are pre-built servers available for things like:
Google Drive, Docs, and Sheets
Slack and email
Notion and other knowledge bases
Calendar and scheduling tools
Live data sources and reporting platforms
While you can set up your own MCP server, you don't *need*to. There are lots of servers that already exist. You just connect your agent to them.
This is an important distinction. A lot of writing about MCP servers is aimed at developers who want to build their own. But most people don't need to do that. The more useful question for most users is simply: which tools do I want my agent to have access to?
---
## When should I use one?
The simplest way to think about it: if you find yourself regularly copying information from one tool into your agent, an MCP server is probably worth setting up.
Some common situations where a connection adds real value:
You want your agent to reference live documents rather than outdated pastes
You want it to check or update a shared system without you acting as the go-between
You're asking it to pull together information from multiple sources as part of a task
You want it to take an action on your behalf, like sending a message or creating a calendar invite
The agent still only does what you ask it to. The connection just provides it a greater tool set to be able to do it.
---
## How to connect to a public MCP server
The exact steps vary slightly depending on which agent platform you're using, but the process follows the same general shape.
**1\. Find the server** . st major tools either have an official MCP server or a well-maintained community one. A good starting point is the [MCP server registry](https://github.com/modelcontextprotocol/servers?ref=jdhwilkins.com), which lists available servers and links to their setup instructions.
**2\. Add it to your agent's configuration**. Each server has a short configuration that tells your agent where to find it and how to connect. This usually involves adding a few lines to a settings file in your agent application. The server's documentation will show you exactly what to add.
**3\. Authenticate .** Most servers need permission to access the service on your behalf. This typically means logging in or generating an access key through the service itself, then adding that to your configuration. The server's setup guide will walk you through this.
**4\. Test it.** Once connected, ask your agent to do something simple that uses the new connection. This could be searching for a file, checking a recent entry, or pulling a piece of data. If it works, you're set up.
---
## A brief note on access and safety
Connecting an MCP server means your agent can take real actions in real systems. It's worth being deliberate about which tools you connect and what level of access you grant.
Most servers let you limit what the agent can do. Read-only access is often enough for a lot of use cases, and it's a sensible place to start. You can always expand permissions later once you're comfortable with how the agent is using the connection.
---
## When to consider building your own (for the slightly more technical)
If you're already giving your agent access to scripts it can run directly, that works fine for simple tasks. At some point though, the direct approach starts to show its limits and you may want to consider creating your own MCP server to house your custom tools.
**1) The agent can see everything.** When you hand an agent a script to run, it has full visibility into the code, the file paths, the credentials, and the logic. That's not necessarily a problem for low-stakes personal tasks. But if the script touches sensitive data, connects to a shared system, or uses credentials that shouldn't be exposed, that's a meaningful risk. An MCP server lets you expose a clean interface: the agent calls a named tool and gets a result, without ever seeing what's happening underneath.
**2) There's nothing validating what the agent does.** Direct script access means the agent decides how to call the script based on its interpretation of your instructions. If it gets an argument wrong or runs something in the wrong order, nothing catches that before it executes. A server lets you define exactly how tools get called, validate inputs before anything runs, and add guardrails the agent simply can't bypass because it doesn't know they're there.
**3) You're sharing the workflow with others.** A script that lives on your machine and depends on your local setup doesn't travel well. A server gives everyone on a team access to the same capability without each person needing to configure their own environment.
**4) The workflow is getting complex.** If you're chaining several scripts together, handling failures, or managing state across steps, that logic is better housed in a server than described in a skill file.
If none of those apply, direct scripts are probably the right call. They're simpler to set up, easier to change, and perfectly adequate for personal, low-stakes workflows.
---
## Where to go next
If you want to understand how MCP servers fit alongside agent skills, check out [this article](https://getting-started-with-agent-skills/?ref=jdhwilkins.com)to see how the two can work together.
For the full list of available servers, the [MCP server registry](https://github.com/modelcontextprotocol/servers?ref=jdhwilkins.com) is the best place to browse.
### Level-up your AI Agent with Skills Engineering
URL: https://www.jdhwilkins.com/level-up-your-ai-agent-with-skills-engineering/
Last updated: 2026-06-09T08:52:51.000Z
**Skills engineering** is how we teach AI agents to handle tasks in the way we want them done. Instead of hoping the agent figures it out, we provide detailed instructions that guide its decision-making process.
> But not all skills are created equal.
A poorly written skill **wastes tokens**, **confuses the agent**, and **produces inconsistent results**. A well-crafted skill makes your agent faster, more reliable, and easier to maintain.
> The quality of your skills directly determines your agent's performance.
Since skills are bundled in with your prompts, classic prompt engineering advice applies here, too.
This means that things like
having verifiable constraints,
adopting a relevant persona for the task,
and few-shot prompting techniques
...will all still apply in this context. We'll explore these more as we go.
This article covers both what skills are and how to write them well. We'll discuss the anatomy of a skill, how they fit into the agent ecosystem, and the best practices that separate fragile skills from production-ready ones.
While many of the examples we'll look at revolve around coding, skills can be used to systematise any sort of task. With the addition of MCP servers to provide agents with access to external tools, the possibilities are endless.
I hope you're sitting comfortably. We've got a lot to cover.
---
## First, what are agent skills?
A ***skill*** is a set of instructions that tells an AI agent how to complete a task in the way you intended. When you send a request, the agent checks which skills are available and decides if any are relevant. If one matches the task, it reads the full instructions and follows them.
Tangibly, a skill is just a set of markdown files in a folder. Each skill lives in its own folder, built around a definition file called [SKILL.md](http://skill.md/?ref=jdhwilkins.com). This file contains the skill's name, a short description, and the instructions themselves, all written in plain language. You can also include supporting reference files and a scripts folder for any code the agent might need to run as part of the workflow.
The way skills load is worth understanding before we talk about writing them. At startup, the agent reads only the name and description from each installed skill (a few hundred tokens per skill, so you can have dozens without penalty). The full [SKILL.md](http://skill.md/?ref=jdhwilkins.com) is only loaded when a request matches the description, and any supporting files are only read when the instructions actually call for them. This ***progressive disclosure*** mechanism keeps the context window lean whilst still giving the agent access to detailed documentation when it needs it.
For a more detailed introduction to skills, [this article](https://getting-started-with-agent-skills/?ref=jdhwilkins.com) covers the anatomy of a skill and the discovery process in more detail.
---
## How to Write Better Skills
Now that we understand what skills are, let's talk about how to write effective ones. The difference between a skill that works and a skill that works *well* comes down to a few key principles.
### 1\. Don't over-explain... but explain enough
Thanks to the progressive disclosure mechanism, only your skill's name and description are pre-loaded. The agent only reads the full [SKILL.md](http://skill.md/?ref=jdhwilkins.com) when it decides the skill is relevant, and only reads additional files when it needs them.
However, once the skill file *has* been loaded, every word counts. Your skill shares the context window with everything else the agent needs to know including the conversation history. There's a balance to be struck between not providing enough detail in your instructions for the agent to be able to perform the task well, and providing too much redundant information that clogs up the context window or distracts the agent.
> Skills often need to be fine-tuned to get this balance right. Experiment with adding and removing details to see how it affects the outputs.
**Too verbose:**
```
PDF (Portable Document Format) files are a common file format that
contains text, images, and other content. To extract text from a PDF,
you'll need to use a library. There are many libraries available for
PDF processing, but we recommend pdfplumber because it's easy to use
and handles most cases well. First, you'll need to install it using pip...
```
**Better:**
```
Extract text with pdfplumber:
import pdfplumber
with pdfplumber.open("file.pdf") as pdf:
text = pdf.pages[0].extract_text()
```
Agents already know what PDFs are. Just tell them which tool it should use, briefly how to use it, and any specifics that might not be obvious or could be ambiguous.
---
### 2\. Choose a good name
Skill names should be clear, descriptive, and follow a consistent pattern. Using the **gerund form** (verb + 'ing') is recommended because it clearly describes the activity the skill provides.
> Field names must use lowercase letters, numbers, and hyphens only.
**Good naming examples:**
processing-pdfs
analysing-spreadsheets
managing-databases
writing-documentation
> Consistent naming makes it easier to reference skills and understand what they do at a glance.
---
### 3\. Write a clear description
Your skill description is how the agent decides whether to use your skill. Make it specific and include a clear trigger.
**Good example:**
```
"Extract text and tables from PDF files, fill forms, merge documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction."
```
> Include both what the skill does and when to use it. Think about the words users might say that should trigger this skill.
---
### 4\. Match the level of freedom to the task
A different level of freedom will be required for different tasks. Sometimes, more detailed guidance and constraints will be necessary, but for other skills, less restrictive instruction will yield better results.
A high freedom approach is best when **multiple methods could be valid** , **decisions depend on the context** or situation, or the approach is **guided by heuristics** and soft-rules.
The most restrictive approach will direct the agent to use specific scripts with few parameters, effectively outsourcing the process to some code that has been tried and tested. This means that there are fewer avenues to introduce errors into the process.
> High freedom can also be a useful starting point for developing a skill. Start with minimal guidance to see where the model falls down, then refine and reign it in as you test it.
Example - high freedom approach:
```
##Code review process1. Analyse the code structure and organisation2. Check for potential bugs or edge cases3. Suggest improvements for readability and maintainability4. Verify adherence to project conventions
```
Example - low freedom approach:
```
##Database migration
Run exactly this script:
`python scripts/migrate.py --verify --backup`
Do not modify the command or add additional flags.
```
> **Match the specificity to the task's fragility.** Database migrations need guardrails. Code reviews benefit from flexibility.
---
### 5\. Utilise progressive disclosure effectively
Try to keep your main [SKILL.md](http://skill.md/?ref=jdhwilkins.com) file under 500 lines. If you have extensive documentation, split it into separate files and link to them from the main skill file.
```
#PDF Processing##Quick start
[Basic instructions here]##Advanced features\*\*Form filling\*\*: See [FORMS.md](FORMS.md)\*\*API reference\*\*: See [REFERENCE.md](REFERENCE.md)
```
The agent only loads those additional files when it needs them. This keeps the initial token cost low while still providing comprehensive documentation.
But...
**Don't nest references too deeply.** Keep all reference files one level deep from [SKILL.md](http://skill.md/?ref=jdhwilkins.com) . The agent might only partially read files that are referenced from other referenced files.
---
### 6\. Verifiable constraints and feedback loops
For complex tasks, include validation steps. Don't let the agent make changes and hope they worked.
For particularly complex multi-step workflows, provide a checklist that the agent can copy into its response and check off as it progresses. This helps both the agent and you track progress through the task.
> Much like when adding constraints to a prompt, this step-by-step checklist should be actionable and verifiable rather than ambiguous.
```
##Document editing process
Copy this checklist and track your progress:
Task Progress:- [ ] Step 1: Make edits to the file- [ ] Step 2: Validate changes- [ ] Step 3: Fix any validation errors- [ ] Step 4: Re-validate- [ ] Step 5: Complete the task\*\*Step 1: Make your edits to the file\*\*
Edit the relevant sections in `word/document.xml`\*\*Step 2: Validate immediately\*\*
Run: `python scripts/validate.py`\*\*Step 3: If validation fails\*\*- Review the error message carefully- Fix the issues in the XML- Note what you changed\*\*Step 4: Run validation again\*\*
Don't proceed until validation passes\*\*Step 5: Complete the task\*\*
Only when all checks pass
```
This pattern catches errors early instead of discovering problems at the end of a long workflow. The checklist pattern works for any complex process, even those without code, like research synthesis or content review workflows.
---
### 7\. Use a few-shot approach
For skills where output quality matters, show examples of what good looks like:
```
##Commit message format\*\*Example 1:\*\*
Input: Added user authentication with JWT tokens
Output:
feat(auth): implement JWT-based authentication
Add login endpoint and token validation middleware\*\*Example 2:\*\*
Input: Fixed date formatting bug in reports
Output:
fix(reports): correct date formatting in timezone conversion
Use UTC timestamps consistently
```
Examples are worth a thousand words of description.
Be selective with your examples. They need to be diverse enough to represent the entire task. If your examples are too narrow, like using ideas from just one project, the agent might fixate on that specific niche and produce skewed, repetitive results.
---
## A Skill Building Framework
There's a satisfying irony here: one of the best tools for writing skills is the agent you're trying to improve. Use it.
**Draft** . Describe the task in plain language and ask your agent to produce a minimal [SKILL.md](http://skill.md/?ref=jdhwilkins.com) from the conversation. Keep it short. Short and testable beats thorough and untested.
**Critique**. Before running any real tasks, ask a second agent instance to review the draft. Brief it simply: find ambiguities, contradictions, and anything that could be cut. This catches structural problems faster than testing will.
**Test**. Run the skill against real tasks and log the failures. Three to five runs usually reveal a pattern. Classify each failure: missing instruction, ambiguous constraint, or wrong level of freedom. Then ask the agent to suggest targeted revisions based on what you found.
**Improve.** Once the skill performs consistently, ask the agent to generate edge case inputs and run those too. Decide deliberately which edge cases are worth encoding and which are rare enough to leave as known limitations.
Then keep the loop going. If you find yourself thinking "I need to remember to..." before the same step, that correction belongs in the skill. Every repeated correction is a sign that the skill hasn't yet captured what you actually know.
---
## We've come full circle
AI began with **expert systems**in the 1970s and 80s. Instead of neural networks, these were rule-based programs where human experts painstakingly encoded their knowledge as hundreds of IF-THEN conditions.
Think of the spam filters that plagued email in the 2000s. Engineers maintained elaborate rule sets, trying to stay one step ahead of spammers. Block the phrase "Nigerian prince," and the spammers just changed the wording. Add another rule. Repeat forever. The maintenance burden was relentless.
Fast forward, and here we are again: writing detailed instructions for AI systems.
The difference is we're no longer debugging thousands of fragile lines of code. We describe what we want in plain language, and the model handles the gory bits.
Maybe it's less of a circle and more of a spiral. We've returned to the same fundamental approach, but with tools that are finally flexible enough to handle it.
---
## Where to go next?
The principles here are straightforward to apply. Start with a task you already repeat, write a minimal skill, and test it against real work. You'll discover what's missing far more quickly than if you try to anticipate every edge case upfront.
If you want to go deeper into the broader agent ecosystem, skills work well alongside MCP servers, which provide safe, reliable access to external tools and real-time data. You can read more about them, [here](https://mcp-servers-giving-your-ai-agent-new-capabilities/?ref=jdhwilkins.com) .
And if you'd like to revisit the basics before putting any of this into practice, my guide to [the basics of agent skills](https://getting-started-with-agent-skills/?ref=jdhwilkins.com) is a good place to start.
### Getting Started with Agent Skills
URL: https://www.jdhwilkins.com/getting-started-with-agent-skills/
Last updated: 2026-06-09T08:52:26.000Z
## Write Once, Use Forever.
Think about the last time you explained your workflow to a new hire at work. You probably didn't just hand them a list of tools and wish them luck. You walked them through the process, explained why things work the way they do, and maybe showed them an example or two. Three weeks later, they're flying solo.
> AI can't do that. At least not out of the box.
Every conversation starts from scratch. There's no memory of how you like things done, no recollection of the context you gave it last time, and no understanding of your process. **Agent Skills**give you a way around this by using a set of standing instructions that your agent can pick up whenever the job calls for it.
## What are AI agent skills?
A skill is just a set of instructions for an AI agent to complete a task. They provide the guidance, context, and rules the agent needs to do the work the way you intended. Skills are particularly useful for writing, reasoning, planning, and other tasks that are largely about thinking --- but they can also teach the agent how to use other tools in your workflow. (More on that later.)
When you send a request, the agent checks which skills are available and decides whether any of them apply. If they do, it reads the relevant skill before responding.
To understand how that works in practice, it helps to see what a skill is actually made of.
---
## Anatomy of a Skill
A skill is just a folder on your computer that the agent can read. The folder must contain one required file: SKILL.md, a plain text document written in [Markdown](https://www.markdownguide.org/?ref=jdhwilkins.com). You can also include optional supporting files if your instructions need reference material.
Here's what a typical skill folder looks like:
```
.claude/skills/my-skill/
├── SKILL.md ← required: name, description, and full instructions
├── examples.md ← optional: sample outputs the agent can reference
└── templates.md ← optional: formats or templates to follow
```
The example below is a skill produced by Anthropic to help agents work with PDF files:
'pdf' is the skill folder with a '\\scripts' folder and various skill files (.md) inside it.
SKILL.md is the main skill definition. forms.md and reference.md are additional supporting skill files that the agent can refer to.
Looking inside the SKILL.md, there are two key parts.
Skill header. The first thing in every SKILL.md is a short header block containing the skill's name and description. The description is the most important part: the agent reads it to decide whether this skill is relevant to what you've asked. Keep it under 200 characters.
```
---
name: pdf
description: Use this skill whenever the user wants to do anything with PDF files...
license: Proprietary. LICENSE.txt has complete terms
---
```
Instructions. Everything below the header is the body of your skill. There's no fixed structure: use headings, bullet points, and examples in whatever way helps the agent understand what you want. Think of it as writing a detailed brief for a colleague.
When writing instructions, you should:
Use headings to group related instructions together
Include context, constraints, and any rules the agent should follow
If you want the agent to follow a specific format, show it an example
Reference other files in the skill folder using: \[link text\](filename.md)
Here's a complete example of a skill for writing a weekly status update:
```
---
name: weekly-status-update
description: Use this skill when the user asks to write a weekly status update or progress report for their team.
---
# Weekly Status Update
Write a concise weekly status update in the format below. Use a professional but approachable tone. Keep it to under one page.
## Format
**This week:** Summarise the 2–3 most important things completed or progressed.
**Next week:** State the 1–2 priorities for the coming week.
**Blockers:** List anything slowing progress or requiring a decision. Omit this section if there are none.
## Guidance
- Focus on outcomes, not activity. "Completed the client proposal" is better than "Worked on the client proposal".
- Use plain English. Avoid jargon unless the user's industry requires it.
- If the user provides bullet points or rough notes, synthesise them rather than reformatting them.
- Keep the total length under 200 words unless the user asks for more detail.
```
---
## How Skills are Loaded - The Progressive Disclosure Mechanism
Skills don't all load at once. The agent uses a three-stage system that keeps things light, loading only what it needs for each task.
### Skill names and descriptions (always loaded)
When your agent starts up, it reads just the name and description from every installed skill. This is a small amount of information per skill, which means you can have dozens of skills set up without any real cost. At this stage, the agent knows what each skill is for and when to reach for it.
### Full instructions (loaded when relevant)
When your request matches a skill's description, the agent reads the full SKILL.md. It's worth keeping this under 500 lines to ensure the agent can process it quickly and reliably.
### Supporting files (loaded as needed)
If the instructions reference additional files or scripts, those are only loaded when they're actually needed. This means you can include extensive reference material, worked examples, or templates without any overhead for content that isn't being used.
> Instructions are progressively loaded into context as and when they are needed.
## Skill Libraries
Since skills are just folders of text files, they can easily be shared and installed. There are plenty of skill libraries available on GitHub. Some are official, some are community-built, so treat third-party skills with appropriate caution.
You can add as many skills as you like, though it's worth removing any you're not actively using to keep things tidy.
[Anthropic Skills](https://github.com/anthropics/skills?ref=jdhwilkins.com)
[Vercel Skills](https://skills.sh/vercel-labs/agent-skills?ref=jdhwilkins.com)
### Meta Skills
Yep, it's already been done: [a skill to help your agent acquire new skills](https://github.com/vercel-labs/skills/blob/main/skills/find-skills/SKILL.md?ref=jdhwilkins.com).
With this skill from Vercel set up, your agent will automatically find and suggest skills for common tasks you ask it to perform.
"Use this skill when the user asks 'how do I do X' where X might be a common task with an existing skill."
---
## A Note on Security
Before you start installing every skill you find on GitHub, a brief word of warning.
Skills give agents new capabilities through instructions and, in some cases, code. A malicious skill could direct your agent to take actions you didn't intend. Depending on what access your agent has, this could mean your files being read, modified, or sent somewhere they shouldn't be.
If you use a skill from an unknown source:
Read everything - Check every file in the skill folder before letting the agent use it
Watch for external connections - Be cautious of skills that instruct the agent to fetch data from the internet
Look for unusual actions - Skills should do what they claim. Be wary of instructions that seem to reach beyond the stated task
Stick to skills you've created yourself or sourced from reputable providers. Your future self will thank you.
## Skills, Tools, and Memories
It's worth being clear on the difference between skills, tools, and memories.
### Tools
Tools are additional capabilities that let an agent do things, not just think about them. Without tools, an agent is limited to working with whatever text you give it. With tools, it can search the web, read documents, run calculations, or interact with other applications.
> If you've ever asked an AI assistant for up-to-date information, it used a web search tool behind the scenes to fetch recent results before responding.
You can create your own tools as small scripts and bundle them inside a skill's scripts folder. The skill's instructions then tell the agent when and how to use them.
### Memories
Each agent has its own memory file where it stores things worth keeping between conversations. You can ask the agent to remember preferences: your preferred writing style, your brand colours, whether you want UK or US English. The agent will apply them automatically from then on. Memories are useful for global rules and constraints that apply to everything your agent does.
You could ask the agent to remember a workflow --- "when I ask you to do X, do it this way" --- but you probably shouldn't. Skills and memories may sound similar, but they serve different purposes.
### Skills vs Memories
Memories are always on
Every memory is included in every request you send. That's fine for short preferences, but if you start adding detailed instructions to your memory file, those instructions take up space that could otherwise be used for your actual work. Skills are different: the agent only loads a skill's full instructions when they're relevant to what you've asked. You can have dozens of detailed skills installed without any overhead when you're not using them.
#### Rules vs. workflows
Memories are best for short, global rules that apply everywhere: language preferences, tone guidelines, things the agent should always or never do.
Skills are better for anything involving steps, decisions, or context: how to write a particular type of document, how to structure a specific output, how to handle a recurring task. The richer and more detailed the instructions, the more clearly they belong in a skill rather than memory.
#### Portability
Memories are tied to a specific project or installation. A skill is just a folder of text files, so it can be copied, shared, backed up, or moved to a new project without any extra steps.
---
## Writing Better Skills
Understanding how skills work is the starting point. Writing them well is a different challenge.
A poorly crafted skill can confuse the agent, produce inconsistent results, or quietly underperform without making it obvious why. If you want to dive deeper into skill authoring, I have a [full best practices guide](https://level-up-your-ai-agent-with-skills-engineering/?ref=jdhwilkins.com) that covers advanced patterns, evaluation strategies, and technical details.
## What About MCP Servers?
**MCP (Model Context Protocol) servers** are a way of connecting your AI agent to other tools and services. If you haven't come across the term before, think of them as integrations: an MCP server might let your agent read your calendar, search the web, update a spreadsheet, or interact with any number of other applications. Where skills provide the instructions, MCP servers provide the connections.
The two work together rather than competing. A skill might describe how you want the agent to handle a recurring task; an MCP server is what gives the agent access to the tools it needs to actually carry that out.
I've written [another article covering MCP servers](https://mcp-servers-giving-your-ai-agent-new-capabilities/?ref=jdhwilkins.com)in more detail, including how to use them safely.
### Exploring AI in Animation: My Journey with VibeManim
URL: https://www.jdhwilkins.com/vibemanim-ing-spatial-reasoning-and-geminis-secret-superpower/
Last updated: 2026-08-10T09:44:11.000Z
What a week it's been in the world of AI! We've seen the [chaotic performative art that is Moltbook](https://www.moltbook.com/?ref=jdhwilkins.com) , the new [Kimi 2.5 model from Moonshot AI](https://platform.moonshot.ai/?ref=jdhwilkins.com) with its swarm of sub-agents, and Google has continued rolling out a [whole suite of AI tools](https://ai.google/products/?ref=jdhwilkins.com) that flew under the radar.
Anyway, I digress.
This weekend, I decided to revisit an old project from a few years ago. Back before the days of Generative AI, I was playing around with the Manim library for Python. If you don't recognise the name, you'll surely recognise the videos it produces. We have [Grant Sanderson of 3 Blue 1 Brown](https://www.youtube.com/c/3blue1brown?ref=jdhwilkins.com) to thank for that.
This style of explainer video has become iconic in the online Math Infotainment space. Manim is the Python library that was custom-built to create this style of animation. Grant has his own version, which he maintains himself, but a community-maintained version (the one I'm using for this project) has also been created with much better support and documentation.
I tried playing around with this library a few years ago, but for a short weekend project, it seemed to have a steep learning curve to actually create something cool and interesting. I hadn't really thought about it again until recently: can AI do a better job than I did? Well, almost certainly, yes, but maybe the real question should be, can I create something cool and interesting with only **natural language** and **minimal effort**? (What can I say, I'm lazy.)
---
## Let's Get VibeManim-ing
I tested Gemini 3 Flash, GPT 5.2, Claude Sonnet 4.5, and the all-new Kimi 2.5 'instant' model with the same zero-shot minimal-guidance prompt just to see what they could do out of the box.
Surprisingly, they all produced an error-free file on the first attempt (!?). Claude was a bit extra and decided to produce a whole ReadMe file with setup and customisation instructions (did I ask?). They all provided a correct command-line function to actually export the animation, too.
And you know what? They're *actually* not that bad!
I'll start with the best: **Gemini**.
It almost stuck to the time constraint at 21 seconds, illustrated the concept well, added some text to what was going on, and even added some nice colour coding to help explain. Yes, the text isn't the best explanation, and it rushes through the animation a bit, but that's probably on me for setting a short time limit. And all of this from just 66 lines of code - not too shabby!
**Chat GPT** *(136 lines of code)* did a much better job with the text explanations popping up on screen, but failed miserably at the time constraint, creating a 3-minute-long slog of a video. I'll spare you the pain, but just know that the animations do not speed up at any point in the video.
**Claude** \- just made me sad. *(108 lines and 51 seconds long)*
\[media not available\]
**Kimi 2.5** (the new kid on the block) was by far the most colourful and produced the longest script *(196 lines and a 1-minute video)*, but was just as underwhelming as Claude in its performance.
\[media not available\]
However, all of the models did follow the Bubble Sort algorithm, and all of them did end up with a sorted list at the end, even if they looked horrific (you know who you are).
---
## This Might Be My New Favourite LLM Benchmark
For my second attempt, I decided to push the limits of both the models and the library. How would it deal with abstract objects that can't be constructed natively within Manim? I decided to go for a 'fancy chessboard construction animation'.
The vague prompt seemed to work okay last time, but this is a fundamentally different kind of challenge. The bubble sort was essentially a 2D problem; bars on a flat plane, moving left and right. A chessboard with pieces, a camera angle, and orbiting motion? That's a spatial reasoning problem. The model needs to understand how 3D objects relate to each other, how a camera perspective changes what's visible, and how to place things in a coordinate system that actually makes visual sense. I gave it a bit more direction on the camera angle and the sequence, but left a lot of the design and animations up to the model.
We ran into some errors this time around. Both Gemini and Kimi threw a library error where the model had assumed some property of an object which turned out not to exist. After a quick check of the *actual* documentation, they got it fixed and managed to produce a working output.
These renderings took a loooooong time to run. Gemini and ChatGPT's code were running at the same time, which probably didn't help things, but Kimi's output took **nearly an hour**.
Let's not pretend any of these is remotely what we were after. However, Gemini does still seem to be coming out on top.
> We're also going to ignore the fact that Kimi's chessboard is an 8x9 grid (!?). But hey, at least it managed to draw one.
... and yes, Claude's animation ***is*** just a blank screen for the first 5 seconds.
The board was correct, had a nice animation, and the [Chess.com](http://chess.com/?ref=jdhwilkins.com) colour scheme was a nice touch. If you look closely, there is a particle effect animation for the pieces, and you can just about see an outline of the top of one of the pieces at the end, but, obviously, they're not fully appearing. Still, Gemini was the only model that seemed to have any intuition about how objects should be arranged in 3D space. The others couldn't even get the board geometry right, let alone place anything on it convincingly.
And, yet again, Gemini's code was by far the shortest but worked the best overall. Since it was the closest to working, I figured it would be the easiest to try to refine.
Can you fix it? ... No, no it couldn't.
Instead, it wrote some code that took 51 minutes to render. (Bear in mind that I'm only rendering 10 seconds of 480p30 output) and ended up looking like this:
If the world has learnt anything about vibe coding in the past few months, it's that you still won't get far if you don't understand at least a little about the code you're writing. And when the code in question is trying to describe spatial relationships, a little understanding goes a long way.
It was time for some vibelearning.
---
## Manim in a Nutshell
Manim is a **state-based declarative animation engine** . Unlike the spatial timelines of traditional video editors, Manim uses a **procedural timeline** where you define the "what" and "where," leaving the interpolation to the renderer.
### Core Mechanics
**Sprites.** All visual elements within the scene are '**Mobjects**' (Mathematical Object). It's essentially a wrapper around a NumPy array that defines a point cloud.
**Scenes.** You build animations within a Scene class. The construct() method acts as the entry point, managing the object lifecycle via self.add() or self.remove().
**Animations.** These are transitions between two Mobject states. Transitions can be applied instantly or by pre-appending with \`.animate\` to convert the change into an interpolated animation. (e.g. \`.scale()\` vs \`.animate.scale()\`)
### Timing and Composition
Instead of dragging clips on a track, you manage time through **blocking execution** . Each [self.play](http://self.play/?ref=jdhwilkins.com) () call advances the global clock. To move beyond simple linear sequences, Manim uses **logic-based composition**:
**Parallelism.** Passing multiple animations into one play() call executes them simultaneously.
**lag\_ratio.** Within an AnimationGroup, this parameter defines temporal overlap. A lag\_ratio of 0 is perfectly simultaneous, while 1 is strictly sequential.
### Implementation Example
All of that is to say, we don't need to worry about how objects change. As long as we can specify a before and after state, Manim should handle the in-between. In this case, we just need to specify what objects we want and what groups of animations should happen at the same time.
> Clearly, we aren't going to get anything decent with a minimal prompt (*what a surprise, I know*) so let's try something a bit more detailed. It's time for a storyboard.
> This still doesn't mean I'm going to put effort in; I'm still determined to be as lazy as possible.
---
## Attempt Number 3
Obviously, I wasn't going to write this storyboard myself. I wrapped my previous prompt in a few extra instructions and fed it to ChatGPT:
Since I'm no expert scriptwriter, I left the response format open to see what it would come up with on its own. I did provide a few checks for it to make sure its response was grounded and feasible. After a bit of back and forth, I had a plan that sounded like what I had envisioned for this animation.
I wasn't taking any chances this time around. I know Claude hadn't performed well so far, but I figured Claude Code would surely do a decent job of this, especially now that there was a much more detailed plan in place.
Claude gave me a 496-line file, which sounds thorough, but, as we've seen, it doesn't mean it's going to be any good.
Although maybe getting Claude to render the project, too, wasn't the best idea, it kept panicking that nothing was happening while trying to reassure me that this was normal and all going to plan. (*I know the feeling*)

... And 20 minutes later, we ended up with this:
I'm not 100% sure why it's given me a portrait video. And yeah, not really much to say here. My disappointment is immeasurable, and my day is ruined.
---
But I wasn't ready to give up just yet. Given how well Gemini had performed so far, I thought I'd give it another try. I uploaded the same plan doc as before, was met with 4 consecutive library errors, but then finally...
Yes, this wasn't exactly what I was expecting, but it's a remarkable improvement over every other attempt at this problem we've seen so far.
The previous, 'minimal-prompt' code from Gemini appeared to put pieces on the board, but they were no longer visible, and Gemini couldn't work out how to fix that bug. This new one even managed to get the board in the correct orientation (the corner to each player's left should be black), and all the pieces were in the correct position.
---
## 3 Takeaways So Far
A lot of this may sound familiar as it's emerging as mainstream vibecoding advice, but it's definitely relevant here too (which is still vibecoding, so no surprise there really).
### Verifiability
Any modern LLM can write code using whatever tools you specify. Results will be better if it has a verifiable way to check its work. I think the reason the bubble sort worked so much better was that the bulk of the logic is verifiable; there are thousands of examples of a bubble sort on the internet, and the output is a simple sorted sequence. Asking a model to produce an animation with abstract 3D objects it has no visual reference for is a fundamentally harder problem. If the model can't see, how can it verify that the output looks correct?
### The Spatial Reasoning Gap
This has been the recurring theme of the whole experiment. Every model can write syntactically correct Manim code. But writing code that *looks right when rendered* requires something extra. Successful models have an understanding of how text-based instructions map to a 3D visual scene. Where should the camera be? How big should the pieces be relative to the board? How should objects move to avoid clipping through surfaces?
Gemini consistently outperformed the others on this front, and I **suspect it's not a coincidence that it's the model with the deepest multimodal training**. When you've been trained to understand the relationship between images and language at a fundamental level, you probably develop a stronger intuition for how code translates into visual output, even code you can't actually render and look at.
This isn't something I can prove from a weekend project, obviously, but the pattern was consistent enough to be worth noting. Every time the task demanded spatial understanding, Gemini pulled ahead.
### One-Shot or Bust
Tweaking a script doesn't seem to work. The best approach seems to be creating a detailed plan and having a lot of faith that the model can one-shot the output and get it exactly how you hoped on the first try.
I've seen this with image generation too, where Gemini can create accurate images on the first attempt but starts losing the plot if you ask it to make changes. It feels like these models are better at holistic generation from a clear spec than at surgical edits to an existing output. Which, if you think about it, makes sense for spatial tasks: each edit can cascade through the whole scene in ways that are hard to predict from text alone.
> Obviously, this is all anecdotal and far from scientifically rigorous, but I think it's still interesting to observe.
---
## A Final Test
My original goal for this project was to see what I could create with **minimal effort**. So let's refocus and try to do exactly that:
1. Ask Gemini for an idea for a math explainer video.
2. Ask Gemini for an outline for said video.
3. Convert the plan into a script and generate TTS with Elevenlabs.
4. Give Gemini the plan and ask it to write some Python code using Manim to generate an animation.
5. Debug the code and export the video file.
... and a little bit of editing magic later, we have our final product.
The idea that it came up with was a video on **Zeno's Paradox**. If you're not familiar, I won't explain it, and we'll see how well the video does of teaching it.
As the reigning champion, I used Gemini for this final test. I also tried it with Gemini 3 Pro (which I actually hadn't used up until this point).
Let's look at the Flash model's attempt first, because it's actually pretty decent.
\[media not available\]
Yes, you could obviously get a better result with a more detailed prompt, but my goal was something quick and dirty, so I'd say it did pretty well.
> However, I'm not sure we've actually learnt anything about Zeno's paradox so far.
For the grand finale, Gemini 3 Pro's version. There were a few additional cuts and edits from me to make sure the video and sound fit together, but the whole thing took no more than 20 minutes (start to finish).
*(I apologise in advance for the thumbnail. I swear I have more integrity than this.)*
Similar to the Flash model's attempt, yes, but more refined and better paced.
---
## So, Is "VibeManim-ing" a Viable Workflow?
If you're after a one-click Pixar replacement, you're barking up the wrong tree. Manim is still a picky, highly technical animation engine that will break the moment a model gets overconfident with its class properties.
But what surprised me is that the floor is higher than I expected, and the ceiling is getting there. The Zeno's Paradox video took about 30 minutes from idea to finished product. Is it going to win any awards? No. Would it work as an explainer in a classroom or a quick visual for a blog post? Maybe. For a tool I'd completely shelved a few years ago because the learning curve felt too steep, that's a pretty big improvement in outcome.
The spatial reasoning gap seems to be the bottleneck right now. The models are (mostly) fluent in Manim's syntax; they rarely produce code that doesn't *run* and can quickly fix what is needed. The problem is that code that runs isn't the same as code that *looks right*. Until models can reliably bridge the gap between "I've placed an object at coordinates (2, 3, 0)" and "this will be visible and correctly positioned from the camera's perspective," you're always going to need a human in the loop.
So no, I wouldn't bet my YouTube career on a fully AI-generated Manim pipeline just yet *(I'll leave that to 3B1B)*. But for quick explainers, prototyping visual ideas, or just satisfying your curiosity about what a concept looks like in motion? We might be closer than you'd think.
And honestly, for a lazy weekend project, I'll take it.
If you made it this far, thanks for reading!
### Getting Started with AI: The Fundamentals of Prompting
URL: https://www.jdhwilkins.com/the-fundamentals-of-prompting-getting-started-with-ai/
Last updated: 2026-06-09T08:52:03.000Z
Modern AI chat tools are powered by **Large Language Models** (LLMs), which are sophisticated systems trained on vast amounts of text data to understand and generate human-like responses.
LLMs like **Claude** and **Gemini** don't truly "understand" in the human sense, but they excel at recognizing patterns in language and predicting what text should come next based on your input. This is why the quality of your **prompt**matters so much. The AI model can only work with what you give it, making clear communication the foundation of getting useful results.
When you interact with an AI model, you're engaging in a deliberate exchange where ***how*** you ask matters as much as ***what*** you ask. This is where learning how to **prompt**AI effectively becomes essential.
## What Is a Prompt?
A **prompt**is the input you provide to an AI model to elicit a specific response. Think of it as a set of instructions, a question, or a request that guides the model toward the output you want. While it might look like ordinary text, a well-crafted prompt is actually carefully structured communication designed to maximize the quality and relevance of the AI's response.
---
## Why Prompting Differs from Ordinary Conversation
Talking to an AI isn't quite the same as chatting with a human. AI models don't have memory of previous conversations (unless explicitly provided), they can't read your mind, and they don't share your context. A prompt bridges this gap by providing all the necessary information upfront. While you might tell a friend, "write that thing we discussed," an AI needs explicit details about what thing, in what format, for what purpose, and with what constraints.
> Understanding how to prompt AI is a skill.
The clearer and more specific your prompt, the better the AI can align its response with your actual needs.
## The Anatomy of a Prompt
Effective prompts typically include several key components:
**Context**: Background information that helps the AI understand the situation. For example, "I'm a high school teacher preparing a biology lesson."
**Task**: A clear statement of what you want. "Create a quiz on cellular respiration."
**Constraints**: Specific requirements or limitations. "Include 10 multiple-choice questions, avoid overly technical jargon, and make it suitable for 15-year-olds."
**Format**: How you want the output structured. "Present it as a numbered list with answer choices labeled A through D."
**Examples**: When relevant, showing what good output looks like can dramatically improve results.
These elements don't have to always be in a specific order. You also don't have to include *all* of them to get a good prompt.
## Good Prompts vs. Bad Prompts
Bad prompts are **vague** , **ambiguous** , or **missing critical information**.
```
"Tell me about cells"
```
...leaves the AI guessing about depth, scope, and purpose.
Good prompts are specific, clear, and complete.
```
"Explain the difference between prokaryotic and eukaryotic cells in three paragraphs, using analogies a 10th grader would understand"
```
...gives the AI everything it needs to succeed.
The difference often lies in specificity. Instead of:
```
"make this better"
```
try:
```
"revise this paragraph to be more concise while maintaining a professional tone."
```
---
## What Is Prompt Engineering?
**Prompt engineering** sounds technical and intimidating, but it's really just the practice of crafting effective prompts to get better results from AI.
The term shouldn't scare you. It's simply about being intentional with your instructions. Anyone can learn prompt engineering basics and immediately see improvement in their AI interactions. It's less about complex formulas and more about clear communication and knowing a few helpful techniques.
## Prompt Engineering Techniques to Improve Your Results
Several established techniques can enhance your prompting when you're learning how to prompt AI:
### Role/Persona prompting
Assign the AI a specific role or perspective to shape its responses. Instead of
```
"How should I invest $10,000?"
```
try:
```
"You are an experienced financial advisor speaking to a risk-averse client in their 30s. How should I invest $10,000?"
```
This contextualizes the advice appropriately. Though this is not financial advice, and you should probably speak to a professional rather than an AI tool.
### Chain-of-thought prompting
Advice from a few years ago may have suggested explicitly asking the AI to "think step-by-step" to improve reasoning, but modern models often do this automatically behind the scenes.
This technique is still valuable when you want to understand the reasoning process, not just get an answer. It serves as an excellent learning aid. For example, instead of asking:
```
"What's 15% of 240?"
```
...try:
```
"Calculate 15% of 240 and show your work step-by-step"
```
...when you want to understand the methodology.
### Few-shot prompting
Provide examples of input-output pairs to demonstrate the pattern you want. For instance:
```
"Convert these customer messages to formal responses:
Customer: 'ur product is broken!!!'
Response: 'Thank you for contacting us. We apologize for the issue with your product.'
Customer: 'need refund asap'
Response: 'We understand your request for a refund and will process this promptly.'
Now convert: 'this thing doesnt work'"
```
The AI model picks up on the pattern you demonstrate and replicates it with the answer it provides you.
---
### Prompt chaining
Break complex tasks into smaller steps and prompt for one part at a time. Take the prompts sequentially, using output from one as input for the next. For example,
*First prompt:*
```
"List five trending topics in sustainable fashion."
```
*Second prompt:*
```
"Take topic #3 from your previous response and write a 200-word blog introduction about it."
```
### Iterative Refinement
Start with a basic prompt, then refine based on the output you receive. For example, begin with:
```
"Write a product description for noise-cancelling headphones,"
```
...then follow up with:
```
"Make it more concise and emphasize the battery life feature."
```
---
Mastering these techniques transforms how to prompt AI from guesswork into a systematic approach. The investment in learning to prompt well really pays off in the quality, relevance, and usefulness of AI outputs. Whether you're drafting emails, analyzing data, or brainstorming ideas, **better prompts mean better results.**
Interested to learn more about prompt engineering? Take a look at [this](https://still-copy-pasting-into-chatgpt-here-s-how-to-turn-your-ideas-into-ai-powered-apps/?ref=jdhwilkins.com)article.
### Forget "Think step by step", Here's How to Actually Improve LLM Accuracy
URL: https://www.jdhwilkins.com/why-think-step-by-step-no-longer-works-for-modern-ai-models/
Last updated: 2026-06-09T08:51:54.000Z
## And What Happened to CoT Prompting?
*Prefer to listen to this article instead? I used* [*ElevenLabs TTS*](https://try.elevenlabs.io/t6vuj6jm5wmb?ref=jdhwilkins.com) *to create this narration. Check them out using my affiliate link,* [*here*](https://try.elevenlabs.io/t6vuj6jm5wmb?ref=jdhwilkins.com) *.*
---
> *"Think step by step"*
...was once great prompt engineering advice, but now seems to have little to no effect.
In fact, what if I told you that this technique, at best, has little effect on output quality, and at worst, increases costs, latency, and may even **reduce the accuracy** of your response?
It decreases perfect accuracy through added variation,
Generates post-hoc rationalisations that don't reflect the model's thought process,
Results in overly verbose responses that are less effective for getting answers.
Now, these are some bold claims with a lot to unpack, but we're going to break them down and take a look at some of the research from the past few years to see what happened to "let's think step by step".
We'll also discover some alternative methods we can use to actually improve the accuracy of our LLM responses in 2026.
## Chain of Thought (CoT) Prompting
If you've spent any time learning about how to use AI more effectively, then you've probably heard that adding *"think step by step"* and similar trigger phrases to your prompts can increase the accuracy of responses.
It's the idea of "Chain of Thought" (CoT) prompting, where we ask a model to show its thinking to help it provide better, more accurate results, particularly on logical reasoning tasks such as math and logic problems; programming and bug fixing; and scientific reasoning and explanations.
What you'll notice, however, when you try this advice out, is that it seems to make no difference whatsoever
In both cases, the model provides a correct answer and a valid justification. So what's going on here? If anything, the first response is better; even if it got the answer wrong, we could at least work out where the error was introduced.
AI models have changed a lot over the past few years. While this advice was super beneficial a couple of years ago, its magic is disappearing.
---
## A Brief History of CoT
**"Chain-of-Thought Prompting Elicits Reasoning in Large Language Models".** This was the 2022 paper that kickstarted it all. The authors present a ***few-shot prompting*** framework that dramatically improved the accuracy of results from Large Language Models (LLMs). By providing examples of intermediate reasoning steps as a guide, researchers were able to get a model to explain its thinking before reaching an answer. This unlocked far greater reasoning ability in models that 'just make the model bigger' had failed to accomplish.
> Suddenly the way we used models had far more of an impact on the results we were able to get.
Shortly after, researchers proposed a **zero-shot** approach, introducing the famous *"Think step by step"* trigger. This revealed that models could generate their own reasoning paths without needing to be supplied with examples. This effectively elicited what researchers call **"multi-hop reasoning"** \- the ability to infer a solution through a series of connected logical jumps rather than a single direct answer.
This era established that "thinking" via natural language allowed models to decompose problems and allocate more compute to difficult tasks by generating more tokens to support their answer.
## The Disappearing Magic of *"Think step by step."*
As we saw in the example above, this trigger seems to have lost its power. Modern AI models now reason naturally without needing to be asked. Through training on massive datasets, these models learned to show their thinking automatically. The phrase has become redundant.
In fact, **continuing to add such trigger phrases to prompts (in newer, more capable models) can sometimes lead to poorer results**:
- **Diminishing Returns:** For dedicated reasoning models, explicit CoT prompting often yields negligible gains in accuracy while drastically increasing response time and token costs.
- **Detrimental Effects**: In non-reasoning models, CoT can introduce increased variability, sometimes causing the model to fail on "easy" questions it would have answered correctly with a direct response.
- **Context Window Variability:** Forcing a model to produce a long reasoning trace can lead to "unproductive overthinking" where models waste thousands of tokens on trivial intermediate steps.
It's not that the model will likely get the answer wrong if you ask it to think step by step; they are still able to correctly answer most questions that we throw at them. These negative impacts were seen particularly with ***perfect accuracy*** while ***overall accuracy*** saw minimal improvements.
> **Perfect accuracy:** The strictest metric. A question only counts as correct if the model answers it correctly on *every* trial (e.g. 25/25), making it suitable for tasks with zero tolerance for error.**Overall accuracy:** The average correctness across all trials. Each correct response contributes to the score, even if the model fails other attempts at the same question.
---
## An Important Distinction
I think it's important to make the distinction between Reasoning and Non-Reasoning models here, as they interact with CoT quite differently.
**Non-reasoning models** , or *'System 1'* models, rely on intuition, knowledge learned during pre-training, and pattern matching to provide fast responses.
**Reasoning models** , or *'System 2'* models (OpenAI o1/o3 and DeepSeek-R1), are trained via reinforcement learning to perform deliberate, slow thinking, involving backtracking and self-correction. These are bigger models that are more expensive to run and so generally have stricter usage limits, but their answers and trains of thought are far more accurate.
**Non-reasoning** models can also be 'taught' to reason by being **fine-tuned** (sometimes also known as **instruction-tuned**) on the step-by-step reasoning traces of bigger, more accurate reasoning models. This improves their accuracy without increasing the size of the model, but also comes with some caveats:
- **Post-Hoc Rationalisation:** Research shows that for many instruction-tuned models, the generated CoT acts merely as a justification for a pre-determined answer rather than active guidance.
- **Unfaithful Shortcuts:** Even when models reach the correct conclusion, they may use "Unfaithful Illogical Shortcuts" - subtly flawed reasoning to make a speculative guess look like fact. This sometimes includes changing previously stated facts to make it fit a logical argument.
> This suggests reasoning chains from non-reasoning models may be emulation without understanding rather than insight into the model's internal decision making.
## NoThinking and the Illusion of Reasoning
One of the more surprising findings from recent research is that **explicit reasoning isn't always necessary at all**.
Studies have explored what happens when we deliberately **suppress visible reasoning** , making the model think it's already finished its reasoning steps through prompt augmentation. It works by pre-filling the AI's response with a dummy or fabricated thinking block (*\`\\ Okay, I think I have finished thinking. \\\`*), which forces the model to jump directly to the final solution.
Counterintuitively, NoThinking performs just as well. It is particularly effective in **low-budget settings**, often outperforming standard thinking models when token usage is controlled.
Another approach, known as NOWAIT, involves suppressing "reflection tokens" (*"Let's think", "Actually...", "Wait a second", "Hmm"*) within the model itself. This technique has been shown to reduce reasoning chain lengths by up to half without compromising the overall utility of the model.
One explanation lies in what researchers call the **"Aha Moment" paradox**. Tokens that appear to signal internal reflection feel meaningful to us as users, but they don't necessarily correspond to better internal computation.
> This suggests that much of what we interpret as **"thinking" is simply verbalisation, not computation**.
More advanced frameworks push this idea further. Techniques like **CoLaR (Compressed Latent Reasoning)** allow models to reason internally rather than out loud. In experimental settings, this reduced reasoning token length by up to 83%, while preserving problem-solving performance.
As it turns out, reasoning can exist without explanation, and forcing models to narrate every step may be inefficient - or even harmful.
```
Note. It's also important not to overcorrect here. While some reasoning traces are unfaithful or post-hoc, visible chains of thought can still be extremely valuable for humans. They help with debugging, error localisation, teaching, and trust calibration. This is especially important in educational or high-stakes settings where understanding why a model failed matters more than raw accuracy.
The issue is not that step-by-step explanations are useless, but that we’ve conflated useful explanations with necessary computation. Modern models often perform the computation internally, and the reasoning we see is best understood as an interface for human consumption rather than a faithful window into the model’s internal process
```
---
## Prompt Repetition
Building on the idea that "thinking" can happen silently, Google Research recently discovered that simply repeating your request twice can dramatically boost accuracy.
This would transform your prompt from something like
```
A bat and a ball cost $1.10 in total. The bat costs $1.00 more than the ball. How much does the ball cost?
```
... to
```
A bat and a ball cost $1.10 in total. The bat costs $1.00 more than the ball. How much does the ball cost?
A bat and a ball cost $1.10 in total. The bat costs $1.00 more than the ball. How much does the ball cost?
```
It's really that simple.
This technique works because it gives the AI a "second look" at your instructions; since modern AI models process text in a sequence, repeating the prompt allows the model to attend to the entire context more effectively. Unlike "think step by step," this method generally does not increase the time you wait for an answer or the number of tokens the model generates.
In one dramatic example from the paper, this simple change helped an non-reasoning model jump from **21% accuracy to over 97%** on a complex task. This reinforces the shift toward "silent reasoning," suggesting that sometimes the best way to help an AI "think" isn't by forcing it to explain itself, but by giving it the structural room to process your input more deeply.
## Ensembles, Parallelism, and the Future of Reasoning Efficiency
If long chains of thought aren't always the answer, what *does*improve accuracy?
One promising direction is **ensemble methods**. Instead of asking the model once, you sample multiple responses to the same prompt, then select the most common or most consistent answer.
The overall idea is that the most common answer is quite often the right one, as there can be multiple correct ways to get the right answer. It's difficult, however, to get to the same wrong answer with multiple reasoning paths.
There are lots of ways we can adapt this method, too:
Using **different temperature settings** to allow models to explore different reasoning paths to see if they can come up with the same answer
Using an ensemble of **different models** with different strengths to see where they agree
This can also be **combined with NoThinking** to quickly generate a large amount of 'gut instinct' answers in parallel, then aggregate them to decide on a final answer. Research shows that this can outperform a single 'thinking' response while having much faster run time.
A recent approach called **Universal Self-Consistency (USC)** replaces strict aggregation of answers with something more flexible: the LLM itself evaluates and selects the most consistent output from several reasoning paths. This makes ensembling viable not just for structured problems like math, but also for open-ended tasks such as coding, summarisation, and analysis.
That said, this strategy isn't universally optimal. For modern reasoning models with very high baseline accuracy, parallel sampling can become **computational overkill**, offering diminishing returns as models approach their performance ceiling.
Finally, it's worth addressing the role of **tools**. Much of the perceived "thinking illusion" stems from token constraints rather than reasoning ability. When reasoning models are augmented with external tools (Python interpreters, scratchpads, or symbolic solvers), they consistently outperform non-reasoning models on complex tasks. In these cases, the key improvement comes not from longer chains of thought, but from offloading computation to the right medium.
---
## Closing thoughts
The era of blindly telling models to *"think step by step"* is ending.
In 2026, improving accuracy is less about forcing verbose reasoning and more about choosing the right model, the right abstraction level, and the right computational strategy, whether that's silent reasoning, parallel sampling, or tool-assisted problem solving.
Thinking still matters. We just don't always need to *see*it.
## References
Wei, J. et al. (2022). "Chain-of-Thought Prompting Elicits Reasoning in Large Language Models," presented at the 36th Conference on Neural Information Processing Systems (NeurIPS 2022).
Kojima, T. et al. (2022). "Large Language Models are Zero-Shot Reasoners," published in Advances in Neural Information Processing Systems.
DeepSeek-AI. (2025). "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning".
Alomrani, M. A. et al. (2025). "Reasoning on a Budget: A Survey of Adaptive and Controllable Test-Time Compute in LLMs," published by Huawei Noah's Ark Lab and McGill University.
Lewis-Lim, S. et al. (2025). "Analysing Chain of Thought Dynamics: Active Guidance or Unfaithful Post-hoc Rationalisation?" from the University of Sheffield.
Tan, W. et al. (2025). "Think Silently, Think Fast: Dynamic Latent Compression of LLM Reasoning Chains," MiLM Plus, Xiaomi Inc. and Renmin University of China.
Arcuschin, I. et al. (2025). "Chain-of-Thought Reasoning In The Wild is not always faithful".
Ma, W. et al. (2025). "Reasoning Models Can Be Effective Without Thinking," UC Berkeley Sky Computing Lab.
Meincke, L. et al. (2025). "Prompting Science Report 2: The Decreasing Value of Chain of Thought in Prompting," Generative AI Labs, The Wharton School.
Baek, D. D., \\& Tegmark, M. (2025). "Towards Understanding Distilled Reasoning Models: A Representational Approach," Massachusetts Institute of Technology.
Liu, H. et al. (2023). "LogiCoT: Logical Chain-of-Thought Instruction Tuning," Zhejiang University and Westlake University.
Chen, X. et al. (2024). "Universal Self-Consistency for Large Language Models," Google LLC.
Song, et al. (2025). "Thinking Isn't an Illusion: Overcoming the Limitations of Reasoning Models via Tool Augmentations".
Wang, Y. et al. (2025). "Wait, We Don't Need to "Wait"!" \[NOWAIT method\].
Naminas, K. (2025). "LLM Reasoning: Fixing Generalization Gaps," Label Your Data.
Leviathan, Y., Kalman, M., \\& Matias, Y. (2025). Prompt Repetition Improves Non-Reasoning LLMs. Google Research (Preprint).
### Using AI to Map Legacy and Inherited Code: A Practical Guide
URL: https://www.jdhwilkins.com/using-ai-to-map-legacy-and-inherited-code-a-practical-guide/
Last updated: 2026-06-09T08:49:02.000Z
One of the ways I've been using AI recently is code mapping and documentation, particularly to quickly understand a new codebase. It might not come as a surprise that LLMs seem to be quite good at this sort of task, and it's saved me hours of trawling through undecipherable God functions -- code that only God and my past self can understand how it works.
Let me back up one minute.
I've been looking back through some of my old programming projects recently, from when I was a kid. Unsurprisingly, in the years since, many of my old projects have broken due to some out-of-date module dependency or language feature update that has made them unusable. It's a shame, really, because with Christmas comes board games, and my old Cluedo (Clue) solver was one of my favourite Python projects growing up -- it really took all the fun out of playing.
I was actually quite impressed by a few of my old projects. A 1500-line block of code can be generated in just a few minutes now, but I had somehow managed to do all of this by hand!? The problem is, without any understanding of what the code actually does or how it fits together, I had no idea where to start fixing it.
My younger self had apparently not heard of commenting, let alone documentation. And while I could have dived straight into debugging and writing tests, that felt like trying to fix a car engine without knowing which part is the carburettor. I needed a map first.
I've been experimenting with using LLMs to generate code maps for unfamiliar codebases, whether they're from colleagues, open-source projects, or, in this case, my own digital archaeology. Here's what I've learned about making this approach actually useful.


---
## The 4-Step Process
### 1\. Understand the Scope
First, take stock of what we're dealing with. We'll be using an LLM for the bulk of the legwork for this, so a single code file will be easy enough to copy into a prompt. If you have multiple files, you can probably attach them to the prompt, but be mindful about context window limitations if your project is particularly large.
Alternatively, for projects with code in multiple places, combining them together into a single markdown file will work nicely. Something like this seems to work well.
```
# File name
```[language]
[ code here ]
```
```
### 2\. Make some Mermaid
Try out the prompt below. You'll either need to attach the raw code file(s) or paste the code itself into the prompt. If you're pasting the code in, I like to use a '\[Code\]' delimiter to section out the prompt, though this is almost certainly not necessary.
```
You are analyzing a [LANGUAGE] codebase. Provide the code for a Mermaid flowchart that shows:
1. The main execution flow from entry point to exit
2. Interactions between user-defined functions (not standard library calls)
3. Key decision points and branching logic
4. Objects/classes represented as subgraphs with their methods
Focus on control flow and function calls, particularly of user-defined functions. Exclude:
- Library imports
- Simple getter/setter methods
- Trivial utility functions
[CODE]
'your code here'
```
If your code has multiple entry points, you may want to specify a particular path of the program flow to trace through. This can be especially helpful for event-driven systems.

---
### 3\. Visualise
Take your Mermaid output to [mermaid.live](https://mermaid.live/?ref=jdhwilkins.com) (or your preferred Mermaid renderer of choice) and visualise it.
> Mermaid syntax. Mermaid is a text-based diagram language -- think markdown for flowcharts. It's widely supported and renders into clean, professional-looking diagrams. However, LLMs still occasionally generate invalid syntax, especially for complex diagrams. If your diagram won't render, feed the error message back to the LLM and ask it to fix the syntax.
In my testing, Claude seemed to be the best at consistently producing syntactically correct mermaid code, but any model should work with a bit of back and forth.
### 4\. Iterate and Refine
From my experience, a zero-shot approach generally seems to be sufficient, but some refinement can be beneficial to get the level of detail to our liking. Phrases like "increase/decrease the level of abstraction", or "show more/less detail" will guide the LLM to produce something more in line with what we're after. We can also be more specific and ask it to include/exclude certain types of methods, or just focus on one part of the process.

## Other useful prompts
For simple programs and scripts, a simple flowchart will probably be sufficient, but complex code might need something a bit different. We can try something like:
A class diagram for code using a complex OOP paradigm
A State diagram for event-driven systems
A process map to see how data is being transformed through the steps of a workflow
The point is: **adjust your request based on what you're looking at.** The one-size-fits-all prompt won't work for everything.
---
## Ditching the diagrams
Moving away from pretty diagrams, I've also had success generating some explanatory documentation.
Write a set of documentation for this code. Describe the inputs, outputs and processes for each of the main, non-trivial functions. Explain the critical execution path and how these functions link together. Produce your output as a documentation file in markdown format.
AI might be a mediocre, maybe even good programmer, but it's an astounding assistant. Sure, it can write code for you, but I've found it really comes into its own when used to help me to quickly understand some code, or a process, rather than doing all the work for me (which will inevitably cause problems later on).
Documentation is one such example. Getting an LLM to explain code to you can be even better than having it write code for you. Your brain is an exceptional problem-solving machine if you give it a chance.
"List all the external dependencies and explain what each is used for in this codebase"
"Identify the core logic functions and explain what each does in simple language"
"Explain the error handling strategy: where are exceptions caught and how are errors propagated?"
"What are the main entry and exit points, and what are the expected inputs and outputs?"
## Where This Approach Falls Short
These methods are far from perfect; it should go without saying that the accuracy with which an LLM can perform this sort of task is good, but not perfect. In this instance, hallucinations are pretty easy to spot as you're tracing through a diagram, but don't be surprised if some function calls get missed off or forgotten. Dynamic behaviour, or anything that happens at runtime, will obviously also be missed.
This is definitely a provisional guide to quickly getting to grips with some alien code. It's a starting point, and a starting point rather than a rigorous piece of documentation.
You may well hit issues with context window limits if you try this with larger code bases. If you're using the free version of some LLMs, analysing files in this way may also severely eat into your free daily usage.
For me, this is another part of my toolkit, rather than a replacement for proper code documentation and review.
---
## A New Performance Metric
If nothing else, I've enjoyed this approach as an unexpected code quality indicator. Yes, you can measure execution time, efficiency, and memory usage, but my new favourite? **How simple can I make the flowchart?**
I recently fixed up an old VBA (Excel) codebase. This approach was invaluable to quickly understanding how the legacy code worked, and what it did, and didn't do. I pretty much rebuilt it from scratch, so the before and after were incredibly satisfying.


*\[left\] old code map, \[right\] new code map*
A clean, linear flowchart suggests clear logic and good separation of concerns. A tangled web of arrows suggests you've got some refactoring to do. Not a rigorous metric, sure, but it's a satisfying one.
## Final Thoughts
Whether you're excavating your own digital archaeology or taking over someone else's legacy code, AI-powered code mapping is a genuine time-saver. It won't do the hard work for you -- understanding code is still understanding code -- but it can cut the head scratching and the "what on earth is going on here" phase from hours to minutes.
> Sometimes the best tool for navigating code is just a good old map.
---
I did manage to get my Cluedo solver working again, by the way. While the UI may not have aged well, even after more than a decade, it remains undefeated.

Stay curious.
### The pitfalls of over-reliance on AI for self-directed learning
URL: https://www.jdhwilkins.com/the-pitfalls-of-over-reliance-on-ai-for-self-directed-learning/
Last updated: 2026-06-09T08:48:43.000Z
> "What's the point in not using a calculator when I'm always going to have one with me?"
...misses a fundamental point that is crucial for effective learning.
Getting the right answer was never the point. The real value was in exercising your cognitive muscles, holding multiple values in your head, manipulating them, and using the right technique or trick to get to the answer. If you don't practice it, you'll lose it. It may have already happened for mental arithmetic. The question is: do we want it to happen to writing, coding, comprehension, or even critical thinking as well?
For myself and many others, learning doesn't stop when you leave full-time education. I've spent a lot of my free time reading, learning, and working on projects to stretch my understanding. AI has dramatically changed the way I approach this. In many ways, it has made self-directed learning far easier than ever before. But as with everything else, it's not without its challenges.
---
## Contents
We are blessed with the ability to ask dumb questions completely judgment-free, but there are perhaps some trivial questions that shouldn't be asked -- at least not straight away.
Over-reliance on AI tools to produce things for us at best removes any sense of satisfaction or accomplishment. At worst, it inhibits our ability to think, do, learn, and practice for ourselves.
Self-directed learning inherently lacks a structured curriculum. I don't believe AI is a good substitute for this.
As always, these are my own thoughts from my own experience; you are allowed to disagree; I'd love to hear your perspective.

## Part 1\. Finding the right balance of questions to ask
We are at a time in history like no other. This period started with the birth of the internet, but has truly come into its own with the rise of LLM tools. At no time has humanity had the ability to ask so many dumb questions without looking stupid. It's both a blessing and a curse.
The blessing is obvious. There's a tendency for people in formal education not to ask questions when they get stuck. We've all been there: everyone else seems to be getting it while you're sitting there absolutely clueless, watching the clock tick down, probably contemplating dropping out. You're convinced the question you want to ask is 'trivial', and by now it's been way too long. If you ask it now, everyone -- including the lecturer -- is going to realize you've been completely lost this whole time because you really should've just asked it last Tuesday.
I wish I had today's AI tools when I was at university. So often it felt like once you got behind, it was impossible to catch up because the next lecture wouldn't make sense without understanding the previous one. AI tools remove that problem entirely. They allow us to clarify all the little confusions we'd rather not voice out loud, and in real-time rather than struggling for hours on what might turn out to be an unnecessary problem.
This is undoubtedly a step in the right direction and is, for me, perhaps the most beneficial use of AI tools as a learning aid: it helps us stay in the flow of a lesson without being sidetracked by simple, preventable misunderstandings.
But naturally, as humans, we exploit these tools to our own detriment. If we aren't careful, we lose the ability to think critically and solve problems on our own. It's very easy to say, "I know I can do it, but it's easier to get AI to give me the answer". The problem isn't just that it's easier -- it's that over time, if we keep taking the easy path, we stop being able to do it ourselves at all.
Not all questions should be asked immediately, and not all struggle is unproductive. There's a meaningful difference between going around in circles for hours on something trivial versus wrestling with a genuinely difficult concept. This applies to any field, but I'll use mathematics as an example. Being stuck on step 3 of a proof is fundamentally different from not knowing where to even begin.
If you're stuck on step 3, you've engaged with the problem. You understand what you're trying to prove, and you've made progress. This might be a genuine point that needs clarification -- for me, this is a perfect use case for AI.
But if you don't know where to begin, that may suggest you need to spend more time with the source material. Asking AI to start the problem for you might get you unstuck in the moment, but it skips the foundational thinking that would help you start the *next* problem on your own.
So before reaching for AI, give yourself some time with the problem. You're a smart individual; there's a good chance you can figure it out. But don't let pride sidetrack you either -- if you've genuinely tried and you're still stuck, turn to the subject-matter expert waiting in your pocket.
> Key Takeaway 1: Struggle productively, but don't suffer needlessly. Learn to tell the difference.
For a more in-depth guide on getting more value out of AI tools, check out [this article on prompt engineering tips and tricks](https://jdhwilkins.com/youre-using-chatgpt-wrong-heres-how-to-prompt-like-a-pro/?ref=jdhwilkins.com)
---

## **Part 2\. Don't fall into the AI production trap**
In the previous section**,** I discussed when to ask AI for help with understanding something. But a problem that's equally pertinent: using AI to produce the work itself.
Taking shortcuts feels efficient but undermines long-term learning. I think it's important to remember writing *is* learning; it's a powerful way to internalise information. Since we can think faster than we can write, it forces us to slow down, think deeply about the ideas at hand, and see how they link to other concepts.
AI-generated work comes with some real costs:
There's a reason it's referred to as AI-generated slop: AI-generated text is very recognisable. It's generic, rambling, and full of predictable sentence structures. And that's when it's not just hallucinating information entirely. **It's not good writing; it just requires less effort than doing it yourself.**
It doesn't capture *your* ideas. Which means your notes don't reflect your understanding or what you thought was important to remember. These aren't your notes; these are a **stochastic parody of what people on the internet thought about it**.
Finally, you lose any sense of satisfaction, accomplishment, or fulfilment in not producing the work yourself. Maybe that's less important for our long-term learning outcomes, though it might dampen our motivation after a while.
Writing code is another great example. You're not just producing a program: you're practicing converting your ideas and theory into practice; you're building familiarity with specific libraries and functions; and you're learning how to spot common mistakes that you'll undoubtedly make along the way. AI-generated code doesn't teach you any of this. It has the added drawback of producing errors that can be hard to spot and can have far-reaching consequences over the rest of your codebase that will only come back to bite you later. Without the skills learnt through practice, how can you even tell if the AI-generated code is well-written and accurately fulfils its purpose? It's not even like it's rewarding either; there's no joy in producing a program to solve a problem when you're not the one who solved it.
There's a balance to be struck, and it manifests more as a time-value trade-off.
AI is great for automating simple tasks that would require your time, not your cognitive effort. Need to summarise your notes or turn them into flashcards? AI can handle it. Need to refactor your code and tidy up the documentation? AI's got your back. Want someone to review your work and check your understanding? You're in luck.
Sometimes we just need things done quickly. In which case, your new AI sidekick can help. Just remember the difference: AI can help you produce something, but it won't help you learn how to do it. It's a slightly different story if you have already mastered a skill. If you possess the necessary skillset to review AI-generated material, assess its quality, and adapt it to meet your needs, then it can be a helpful time-saver. Treating its words as gospel won't teach you how to write or code better, and to anyone more experienced, it'll be obvious you didn't write it yourself.
> Key Takeaway 2: Use AI to save time not effort. If you can't assess its output, you're not ready to use it.
---

## **Part 3\. Devising a Curriculum**
When learning something without the guidance of a teacher or course, one of the hardest questions is simply: where do I start?
Learning a new topic can be overwhelming at the best of times. For me, the worst case scenario is when it falls into the 'known-unknown' category: you know just enough to realize exactly how much you don't know.
I think with the tools we have available now, it's easy to reach this point too quickly. AI is particularly good at giving you sweeping overviews. Ask it about quantum mechanics or machine learning, and it'll happily lay out dozens of topics and adjacent ideas you might want to explore. Suddenly, you're aware of all these concepts you don't understand, and the path forward feels paralysing rather than exciting.
Context can be useful to ground ideas and provide motivation for how things fit into the larger picture, but dwelling too much on the breadth of a subject is a surefire way to lose all motivation. You need a structured path through the material, not just a map of everything that exists.
I'm also not a fan of using AI tools to design a curriculum. From my experience, it doesn't always cover topics in the 'right' order, or include topics that are relevant to each other and should be studied together. Good curricula aren't just lists of topics; they're carefully constructed sequences where each concept builds on the last, where examples are chosen to reinforce multiple ideas simultaneously, where the order itself teaches you something about how experts think about the field.
That kind of design comes from human lived experience in exploring, learning, and teaching a topic. A textbook author has wrestled with the material themselves, taught it to many cohorts of students, seen where people get stuck, and refined their approach over the years. AI hasn't done any of that. It's pattern-matching from curricula that exist, but it doesn't understand *why* they work.
I've tried many times to use AI tools to produce a **comprehensive** curriculum or lesson plan in the hope that it can give me a complete roadmap through a subject. The problem is, AI optimizes for *appearing* comprehensive rather than *being* useful. Ask for a list of resources, and you'll get twenty textbooks when three good ones would do. It treats all sources as roughly equal rather than highlighting what'll actually provide the most value. It can't tell you to "read this chapter from this book, then follow up with this other resource" because it doesn't have the judgment to know what matters most at your stage of learning.
For me, the better approach is to use the contents and structure of a well-respected textbook to guide my learning. Not just any textbook -- one that's stood the test of time, that people consistently recommend, that has a clear progression. If you can access the book itself, even better. If not, using its table of contents as a roadmap still gives you that structured path.
That said, AI can be helpful for finding *which* textbooks or resources to use in the first place. It can tell you what's most commonly recommended in a field and point you toward well-established materials. Just don't ask it to reconstruct the curriculum that those materials provide.
> Key Takeaway 3: Use AI to find good resources, not to replace them. Trust human-designed curricula over AI-generated ones.
---
## **Metacognition and the bigger picture**
There's a running theme throughout each section that I haven't explicitly put a name on yet: metacognition, or **learning how to learn** more effectively.
AI tools have fundamentally changed this process. Immediately jumping to asking AI for an answer skips the moment of reflection and recognizing *why* you're stuck. When AI produces your work, you lose the feedback loop that tells you what you actually understand and where you can make progress. When it designs your curriculum, you never develop the judgment to know what should be learnt next and why it's important.
I don't believe these are just minor conveniences we're trading away -- they're core metacognitive skills we're slowly losing. It's the ability to recognize the difference between "I need a hint" and "I need to get my head down and learn this"; the awareness of when you're genuinely learning versus just consuming information; or the judgment to know whether you're ready to move forward or need more practice.
There's definitely value in current AI tools, and choosing not to use them at all seems unwise to me. But we need to be thoughtful about how we adopt them. AI can be a powerful aid for self-directed learning, but only if we're intentional about how we use it. Learning is a skill in itself. It requires practice and conscious thought to get right. Be cautious when adopting these tools rather than jumping in headfirst and dealing with the consequences later. Use them to enhance your learning process, not replace it.
The point was never to get to the right answer; it was to develop the capacity to think, reason, and solve problems ourselves. AI can help you learn, but only if you stay in the driver's seat.
### How Far Can You Push Excel with Regex?
URL: https://www.jdhwilkins.com/how-far-can-you-push-excel-with-regex/
Last updated: 2026-06-09T08:48:29.000Z
If you've spent any time in Excel, you'll know the struggle of working with a messy dataset. You've got an inventory list with product codes buried in long strings of text; there's customer notes where the phone number might be formatted five different ways; and you have a column of web links where you need to extract *only* the unique tracking ID buried deep in the URL. These are the sort of routine tasks that can easily turn into hours of frustrating, error-prone, manual work.
> Regular Expressions (RegEx) are designed to solve this exact problem. They allow us to define complex patterns in text data leading to clean and simple, data extraction, validation and processing.
In the world of business, analytics, and data, Excel is perhaps the most divisive tool. It has a diehard fanbase who will defend it to the end of the Earth, yet, it's criticized by others for not being a "proper data science tool": slow, error prone, and incapable of facilitating any complex data handling tasks. In this article, we'll see how using Regular Expressions can bridge the gap between lowly spreadsheet software and a professional data analysis pipeline -- at least when it comes to text data. We'll explore some of the theory behind Regular Expressions and show how we can implement this technique to substantially improve the efficacy and efficiency of text data processing right inside of Excel.
## Types of Formal Grammar
In my previous article, [*The Hidden Mathematics of Language*](https://jdhwilkins.com/formal-grammars-the-hidden-mathematics-of-language/?ref=jdhwilkins.com), I introduced the idea of **formal grammars** . Somewhat akin to the grammar rules for natural language or the syntax rules for a programming language, formal grammars consist of systems of rules that define which combinations of symbols form valid sentences in a language. These **production rules** describe how smaller components combine into larger structures, such as words into clauses or clauses into sentences. A **language**, is the set of all possible sentences that the grammar rules can produce.
There are 4 main, distinct types of grammar, each with a different level of expressiveness, and each corresponding to a different class of machine that is capable of recognising it. These machines are sometimes known as **automata**. For today, we're just going to focus on Regular Grammars.

Above. The [Chomsky Hierarchy for formal grammars](https://en.wikipedia.org/wiki/Chomsky%5Fhierarchy?ref=jdhwilkins.com).
## Regular Grammars and their Equivalent Forms
Regular grammars, are the simplest type of formal grammar. They can be represented using set-definitions, sets of production rules, or **regular expressions**. Regular languages can contain sentences including:
**Repeated symbols**: {"a", "aa", "aaa", ...}
**Optional Symbols**: {"a", "aa", "aaa", "ba", "baa", "baaa" ...}
**Alternation:**{"a", "ab", "aba", "abab", ...}
**Fixed-order sequences**: {"ac", "abc", "abbc", "abbbc", ...}
or any combination of the above.
This makes them useful for recognising -- ***or parsing*** \-- strings such as ID numbers, postcodes and email addresses. The automata for a regular grammar is called a **Finite State Machine** (FSM).
### Finite State Machines

These automata parse strings by moving from state to state. We start at the start state, S0, then read through the input string, choosing the next state based on the character being read. If the end state, S5 in the FSM above, is reached, then the parse was successful and the string is valid within the language. If the machine reaches a state from which it cannot transition out of, then the parse has failed and the string is invalid.
The FSM above is designed to recognise precisely 2 strings, abdca,aca. There are 2 possible routes we can take from S0 to S5 giving us the 2 possible strings that can be parsed. If you tried to parse the string "abca" using this FSM, we would get to state S2 and the parse would fail as the next character being read is not a "d".
Finite State Machines have no memory so the decision about which characters can be parsed next is determined only by the current state. As a result, regular grammars cannot represent recursive structures --- think pairs of nested brackets. With no memory, the machine has no knowledge of how many open brackets have come before, and therefore has no way of knowing how many closing brackets are required in order to parse a valid expression. We could design a machine that requires a *finite* , known number of brackets, but it is not possible to parse sentences with an unknown number of bracket pairs.
### Regular Expressions
As mentioned, regular grammars are part of a wider landscape of formal grammars. Other types allow for greater expression, but come with their own limitations. The beauty of a regular grammar is that it can be represented by a regular expression.
A regular expression is another way to describe the set of sentences that can be parsed by a regular grammar. Let's take a look at some basic syntax to get us started:

We can write a regular expression by combining these symbols to indicate which characters we should expect in a valid string. The quantifiers refer to the character (or group of characters if using brackets) directly preceding. As such,
"b" means we should expect a "b" in the string
"b?" means there may or may not be a "b"
"b+" means we should expect at least one "b"
"b\*" means we should expect any number of "b"s (including none at all!)
Where we have multiple characters in the string,
"ab" means we should expect an "a" followed directly by a "b"
"ab+" means we will have an "a" followed by at least one "b"
"(ab)+" means we should expect at least one "ab" pair (so "abab" would also be allowed")
"bb\*" is equivalent to writing "b+"
Using this method, we can construct Regex expressions such as
"ab?c\*\\d"
...which will be able to parse strings including "abc1", "ac4", "a9", "acccc6", "abcc0" -- an "a", an optional "b", any number of "c"s and then a digit, 0-9.
### Equivalence of the two forms
An equivalent, FSM for this Regex expression could look like this:

You may notice the addition of the ϵ between S2 and S3, and S1 and S3\. This allows the machine to transition between states without reading a symbol from the input string.
A Finite State Machine for a given grammar may not be unique. There can be multiple different machines that parse the same set of sentences. A well designed FSM should be **deterministic**, meaning there are never multiple options for which state should be chosen next. It is always possible to transform a non-deterministic FSM into a deterministic one using the [Subset Construction Algorithm](https://en.wikipedia.org/wiki/Powerset%5Fconstruction?ref=jdhwilkins.com) .
In the example above, in state S1, the machine could either parse a b and move to state S2, or move directly to S3 without reading a character. The machine has a choice and hence, is non-deterministic. We can construct an equivalent machine that will recognise precisely the same set of sentences, but that is deterministic:

We are never presented with a choice over which state to transition into next. There are no ϵ transitions, and no states with multiple outbound arrows of the same label. Therefore, this machine ***is*** deterministic.
## Additional Syntax
To really make use of the power of regular expressions, we need a little more notation:

## Regex in Excel
Excel allows us to work with regex natively through the use of 3 different functions:
REGEXTEST(text, pattern, \[case\_sensitivity\])
Tests if the text (or a substring of the text) matches the regex pattern
REGEXEXTRACT( text, pattern, \[return\_mode\], \[case\_sensitivity\])
Extracts a substring that satisfies the regex pattern
return\_mode:
0: first match,
1: all matches,
2: returns each match separated out into capturing groups (more on this later)
REGEXREPLACE(text, pattern, replace, \[occurrence\], \[case\_sensitivity\])
Replaces the substring matching the given pattern with the replacement text provided
The occurrence number indicates which match should be replaced if there are multiple. If not provided, replaces all instances.
Excel also provides the additional quantifier of {n,m} which indicates that between n and m (inclusive) of the previous symbol should be matched. If m is left blank, then it will match any number greater than or equal to n.
## So what can we do with it?
### Removing non-alphanumeric characters
Using REGEXREPLACE, we can find all occurrences of non-alphanumeric characters and replace them with an empty string -- effectively removing them from the text.
```
=REGEXREPLACE(A1,"[^A-Za-z0-9]","")
```

### Removing double spaces
Similarly, we can search for all occurrences of double (or more) spaces and replace them with a single space.
```
=REGEXREPLACE(A1," {2,}"," ")
```

(You might have to take my word for it with the trailing spaces)
### Extracting or validating email addresses
We can search for a valid email address format by looking for:
A set of characters, underscore or other acceptable character
An @ symbol
Another set of characters
A '.'
And then another set of characters of length at least 2
```
=IF(REGEXMATCH(A1,"[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}"),"Valid","Invalid")
```

### Extracting a domain from a URL
```
=IFERROR(REGEXEXTRACT(A1,"https?://(?:www\.)?([^/]+)"), "")
```

### Extracting a product code or ID
We can search for IDs or codes in a specific format, in this case, a set of characters of length at least 2, a '-' and then at least one number.
```
=REGEXEXTRACT(A1,"[A-Z]{2,}-\d+")
```

### Extracting data from between delimiters
We can search for text embedded between 2 given delimiters, in this case '\[' and '\]'.
```
=IFERROR(REGEXEXTRACT(A1,"\[([^]]+)\]", 2), "")
```

See the section below on capturing groups for details on the additional parameter "2" in the formula above.
### Parsing JSON to extract a specific field
Parsing JSON in Excel is difficult using traditional tools. Regex greatly simplifies this as we can search for ' :" . . . ", '.
```
=IFERROR(REGEXEXTRACT(A1,"""fieldName"":\s*""([^""]+)"""), "")
```

### Parsing JSON to extract all fields (multiple matches)
Taking this one step further, we can extract multiple matches into a #SPILL range and handle them separately. This is useful if your JSON always returns arguments in the same, known order.
```
=IFERROR(REGEXEXTRACT(A1, ":\s*""([^""]*)""", 1), "")
```

### Data categorisation
We can neatly check the contents of strings for some given keywords and categorise the text accordingly.
```
=IFS(REGEXMATCH(A1,"error|fail"),"Error",REGEXMATCH(A1,"success|pass"),"Success",TRUE,"Other")
```

## Capturing Groups
When we enclose part of a regular expression in brackets, we're creating **capturing groups.** E.g:
*(∖d+),*
*(\[A−Za−z\]+),*
*(∖w+)*
Each group stores whatever substring matches that portion of the regex pattern, in the order in which they appear. During the REGEXREPLACE() function, we can refer back to these captured groups using "$1", "$2", "$3", etc... .
```
=REGEXREPLACE("Doe, John", "(\w+), (\w+)", "$2 $1")
>>> John Doe
```
It's worth noting that is a feature of Excel, rather than a mechanism built into regular grammars themselves. Regardless, it's quite useful for reformatting text data where you don't know the exact contents or length.
### Removing duplicate words
We can also use this technique to search for multiple consecutive occurrences of the same word and remove them.
```
=REGEXREPLACE(A1,"\b(\w+)(\s+\1\b)+","$1")
```

### Text transformation / reformatting
...and we can add characters in-between the groups to put them into a required format.
```
=REGEXREPLACE(A1,"(\d{4})(\d{4})(\d{4})(\d{4})","$1-$2-$3-$4")
```

## Beyond Regular Grammars: Context Sensitive Data Extraction
While these are "Regex" functions, Excel doesn't seem to have stayed within the bounds of a regular language. But we're not complaining; the **lookahead** and **lookbehind**assertions are quite useful.
As the name suggests, these constructs let a regular expression match text based on its surrounding context, For instance:
(?\\<=Score:∖s∗)∖d+ matches a digit only if it's preceded by Score:
∖w+(?=∖.jpg) matches a word only if it's followed by .jpg
This ability takes us out of the realm of regular grammars, and into the world of **Context Free** or **Context Sensitive**ones; we're matching based the specified, context, elsewhere in the text. You can also think of it as introducing a form of memory or dependency which would exceed of the capabilities of a finite state machine.

### Obfuscating sensitive data
We can look for characters that have a given number of characters ahead or behind them to make sure we obscure the data, but leave some visible.
```
=REGEXREPLACE(A1,"(?<\w{2})\w(?\w{2})","*")
```

## Wrapping up
Regex brings a surprising amount of sophistication to Excel. While some of these tasks can still be done using LEFT(), RIGHT(), MID(), etc... utilising regular expressions makes this process a lot smoother and cleaner. With just a few formulas, we can extract structured data from (almost) whatever mess you throw at it. Data validation and transformations that would have taken hours can now be done in seconds. And if you ever get stuck, sketching out a quick finite state machine can definitely help.
Excel's new regex functions bring the logic of regular grammars into everyday data workflows. The same rules that define the behaviour of formal languages now sit quietly behind familiar formulas, letting us recognise, extract, and transform text with precision. It's a small but meaningful shift, not because it turns Excel into something it isn't, but because it shows how much can be achieved when old tools meet a bit of formal thinking.
### Convolution, Kernels & Filters: A Beginner’s Guide to Edge Detection
URL: https://www.jdhwilkins.com/convolution-kernels-filters-a-beginner-s-guide-to-edge-detection/
Last updated: 2026-06-09T08:48:16.000Z
## The Problem of Detecting Edges
I find it interesting how your brain just knows where one object ends and another begins. That instinctive separation is a fundamental part of how we perceive the world. Computers, however? Well, they just need a bit more help.
In computer vision, edge detection is the process of teaching machines to recognise those boundaries, outlines, and transitions in intensity that define structure in an image.
Believe it or not, it's not as complicated as you might think!

---
## Let's start with 1 dimension
Let's start off with just 1 dimension and take a set of random values between 0 and 1:

We can now take a **rolling average**of this dataset...
- We start with our window on the left-hand side of the list of values and take the average of the 3 left-most values.

- We slide our 'window' one place to the right and take the average of the next 3 values

- We repeat this process: sliding our window along one place and taking the average of the 3 values it covers, until we reach the right-hand side:

---
**Let's visualise this with a proper data set.**Here's another set of random values between 0 and 1:

We can take a sliding-window average of this dataset, the output of which looks like the following:

The result is a 'smoothed-out' version of the original data.
We aren't limited to just taking a rolling average of 3 elements; we can increase the size of our sliding window to n=5:

Which, when applied to our original dataset, looks like this:

---
In fact, we can choose any odd number we like, but you'll notice that the larger the window, the more 'smoothed' the output becomes. This is easier to see if we put them side by side. Below, we have n=3 and n=7 sliding window averages applied to the same set of data. The one with the larger window (on the right) looks much less jagged and noisy.


*\[LEFT\] n=3, \[RIGHT\] n=7*
We don't have to stop here, either! We can take it one step further and look at a weighted sliding-window average.
In the example below, we assign the center element of the window a relative weight of **2** , and the 2 elements on the wings, a relative weight of **1** . This ensures we retain more of the original shape of the dataset. An operation like this is sometimes called a **Gaussian blur** \-- coming from the shape of the **Gaussian (Normal) distribution**.

To calculate the weighted average, we ***multiply each element by its weight*** , ***add those values together*** and then ***divide by the sum of the weights***.

Here's this Gaussian blur applied to our trusty dataset:

This set of values,
```
[ 1 2 1 ]
```
is known as a **kernel**, and the sliding-window-weighted-average operation is known as a **convolution**.
> Note. Sometimes we don't worry about dividing by the sum of the weights at the end.
It might mean that all of our output values are 4 times what they should be, but they are still proportional to each other. Depending on our goal, and in use cases such as edge detection, this step is not important. The other alternative we have is to divide all of the weights by the total sum of the weights. This will perform that final division step implicitly, so we don't have to worry about it. In which case, instead of using :
```
[ 1 2 1 ]
```
as the kernel, we would use:
```
[ 0.25 0.5 0.25 ]
```
---
## Convolutions with a different Kernel
What would happen if we took a slightly different kernel, say
```
[ 1 0 −1 ]
```
Well, let's take a look at a different, less random dataset, and we'll see what this kernel can do.

Applying this \[ 1 0 -1 \] kernel produces the following, somewhat strange-looking output:

It might be easier to see what's happening here if we overlay the source data and the convolution output over the top of each other:

This convolved data can tell us something interesting about the original dataset:
Where the value of the convolved data is **zero** , there's **no change** in the height of our source data
Where the convolved **value is close to zero** and **steady** (\\\~0.1), there is a **smooth transition** in the height of our source data (see the leftmost red bar above)
Where the convolved **value is very high or very low** , **and jumps suddenly** (>0.5, \\<-0.5), there is a **sudden transition** in the height of our source data (see the vertical red bars)
Where the convolved value shows a **curve or diagonal** (see the right-side red bar), the gradient of the source data is changing -- the **source data has a curve**.
This kernel is **finding the gradient**of our data source. The height of the output is the 'steepness' of the transition.
To then identify the 'edges' in our dataset (or areas where there is a sudden transition from one height to another), we can look for values greater than 0.3\. or less than -0.3.
---
## Tackling 2 Dimensions
When we move to 2 dimensions, the procedure is largely the same.
Since our dataset now has 2 dimensions, our sliding window must as well; it becomes an n×n square rather than a 1×n rectangle. Performing a convolution is very similar to the one-dimensional case.
We start with the top left data item and perform the same sliding window operation from before. We slide the window along the rows until we reach the end, move down to the next row, then repeat until we've covered each data point.
The biggest difference in 2 dimensions is that we now need a second kernel to find the full gradient of our dataset. Each kernel will find the gradient in one direction: horizontal and vertical. We can then combine these outputs to find the full gradient.
Kernel to find the gradient in the **horizontal**direction**:**

Kernel to find the gradient in the **vertical**direction:

These Kernels are known as the **Sobel filters**.
After we've done this for every element of our source data, we can scale the values of the output to make sure they're all still within that 0--1 range.
To find the gradient of the data in 2 dimensions, we first find the horizontal gradient by performing a convolution with the horizontal Sobel filter, e.g. :

*You'll sometimes see this (* *⊗)* *symbol used to mean: 'multiply each corresponding element and add them together'.*
Then we find the vertical gradient by performing a convolution with the vertical Sobel filter, e.g. :

And then combine them as follows:

Where gradx and grady are the outputs from the two convolution steps above.
We then repeat this for every element of the source data.
Let's now see some examples with actual images.
---
## A quick aside
Each pixel in an image is made up of 3 values: one for **red** , one for **green,** and one for **blue.** These values are usually between 0 and 255, but we can scale them such that they are between 0 and 1.
For example, \[ 66, 245, 224 \] → \[ 0.2588, 0.9608, 0.8784 \] results in this nice teal color:

So far, all of our convolution examples have used a single value per cell. Therefore, we must combine the 3 colour channel values into a single number.
To do this, we convert our image to **black and white** . This gives us a single value per pixel -- the **lightness** or **value**of the pixel. 0 is pure black, 1 is pure white. But don't worry, we will still be able to identify the edges in the image.
## Let's see some examples
Firstly, to see why we need 2 kernels to find the gradient in 2 dimensions, let's see what happens if we use just one of them. We'll start with this image and apply only the horizontal version and only the vertical version of the Sobel filter:


*\[left to right\] Original image, horizontal Sobel Filter applied, vertical Sobel filter applied.*
Applying the horizontal Sobel filter allows us to identify where there are sudden changes in lightness values moving from left to right -- this gives us the vertical edges in the image. Similarly, the vertical filter identifies changes in lightness from top to bottom, which gives us the horizontal edges.
Now, if we combine these using the formula we saw earlier, we get something that looks like this:

And for clarity, we'll overlay this on top of the (black and white version of the) original image:

---
## Changing Channel

Depending on the image you're using, there might be a better way to find edges than using black and white.
#### Let's mix things up with a different example
If we look at each of the three color channels in this image, we find more contrast in the red and the green, and far less in the blue channel.


If we apply our edge detection procedure again to each of these channels, we get some slight variation in the results.


Now, don't get me wrong, these are all pretty similar. I'm not trying to suggest that one is miles better than the other -- they all get the overall shape correct.
However, since there is less contrast in the blue channel, the algorithm has a harder time picking out the fine details, particularly in the buildings.
But if you take a second, zoom in, give it a really close look, then you might start to notice some of the more subtle differences between the other three.
Ultimately, using a greyscale image will probably give you the best all-round result the majority of the time. However, depending on your use case, we can sometimes get better details and clarity by using a different colour channel.
---
## The secret trick I've snuck past you so far
Take a look at these two edge detections. Do you notice any differences between them?


The first output has far more detail and clarity than the second. We don't live in a perfect world with perfectly sharp images in perfect lighting. Sometimes our images will be low quality and be quite noisy, like this:

In cases like these, we first apply a blur to our image to reduce the impact of the random variations within the image.
It takes our noisy image and reduces it to something much smoother, albeit with slightly less detail.

It's a little difficult to see, but the edges are just slightly softer, and the noise is a little less prominent. Look at the trim along the hut, the detail of the flag, and the colour noise in the clouds. It only needs to be subtle, just enough to blend in the random variation with the pixels around it. If we blur the image too much, we'll start to lose important details, and the quality of our output will diminish.
To perform a Gaussian blur, we convolve our image using the following kernel. You may notice it's similar to the 1D version we saw earlier.

---
## Wrapping up
Edge detection might seem like a simple idea, but as we've seen, it rests on some rather simple and creative math. Convolutions slide filters across pixels, kernels act as little pattern detectors, and gradients give us a way to measure change. Together, they help computers spot the outlines that shape everything from cats to cars to street signs.
Edge detection is one of the foundations of image processing and computer vision. Whether you're moving on to object recognition, segmentation, or neural networks, these concepts will keep showing up.
Enjoyed this read? Check out this article on [**image segmentation**](https://www.jdhwilkins.com/image-segmentation-with-k-means-clustering) \-- another image processing technique:
I'll leave you with a couple more examples to take a look at for some more inspiration.
If you made it this far, thank you!


### Still copy-pasting into ChatGPT? Here’s how to turn your ideas into AI-powered apps
URL: https://www.jdhwilkins.com/still-copy-pasting-into-chatgpt-here-s-how-to-turn-your-ideas-into-ai-powered-apps/
Last updated: 2026-06-09T08:47:49.000Z
## How to get started building AI-powered apps and tools?
You're staring at ChatGPT. You've done this a hundred times before: typed a question, copied a response, pasted it into some half-built project or document. Maybe it helped. Maybe it wasn't quite what you were looking for.
> But here's the thing no one tells you: that chat box you're using? It's not the product. It's the demo.
The real magic -- the stuff behind the AI-powered apps everyone's talking about -- doesn't live in your browser-client, It lives in the API. The moment we tap into that, we stop playing with AI and start building with it.
It's not as complicated as it sounds. If you can write a prompt, you're already halfway there. In this beginner-friendly guide, we'll explore how we can get started building simple AI-powered apps using your Large Language Model (LLM) of choice. We'll see how using an API changes the game, and helps us level up our prompts -- no machine learning PhD required.
---
## **How does using ChatGPT through an API differ from the web client?**
Many popular AI tools come with an **Application Programming Interface** (**API**). If you're not already familiar, an API provides access to services using code instead of a browser client. This allows us to:
Automate the prompting process, particularly for repetitive tasks,
Connect AI tools to other services,
Bring in additional files and data to tailor our prompts, and
Customise the behaviour \\& language of the model to suit our purpose.
With this in mind, here are some simple yet powerful tools we could build:
**A PDF explainer** that reads long reports, pulls out key insights, and lets you ask questions
**An email triage assistant** that tags, sorts, and drafts replies based on your priorities
**A data cleaner**where you can drag in a CSV, and it processes and reformats the data
**A doc-search portal** trained on your own files, so you can get instant answers without digging through folders
**A study tool**that turns your notes into flashcards, summaries, or quizzes
**A meeting summariser** that processes transcripts and highlights decisions, action items, and follow-ups
To get started, you will need an API key for your chosen LLM. For this article, we'll be using ChatGPT. Full setup instructions are available at the bottom of this page.
##### **Simple API-call prompting script** **(Python)**
Below is a simple sample script. This can act as a starting point for all of the other code snippets in this article. Feel free to copy and adapt this code to try out some of the ideas we'll encounter.
```
import openai
import os
client = OpenAI(api_key = os.getenv("OPENAI_API_KEY"))
response = client.chat.completion.create(
model="gpt-4",
messages=[{"role": "user", "content": "Hello!"}]
)
print(response.choices[0].message.content)
```
Let's get started. First up, let's look at the differences between using ChatGPT with the web client versus through the API...
---
### **Context Memory**
When we use ChatGPT normally, our messages are arranged into conversations. Any response you get will be based on everything that's been said so far in the current chat. However, when using the API, only the current message will influence the response we get back. It has no memory of previous messages that have been sent.
To get around this, we augment each message with a conversation history (from both the user and the agent), all packaged together into a single input for the model. This allows us to simulate a conversation, and is the same process that the ChatGPT client will follow, just usually behind the scenes.
For example, the following prompt may be sent mid-way through a conversation:
```
messages = [
. . .
{"role": "user", "content": "How do I reverse a list in Python?"},
{"role": "assistant", "content": "You can use the `reverse()` method:\n\n```python\nmy_list.reverse()\n```\nOr use slicing:\n\n```python\nreversed_list = my_list[::-1]\n```"},
{"role": "user", "content": "What if I want to reverse it without modifying the original?"}
]
```
As you can see, whenever the user sends a new message, we send the entire conversation history along with it. This also gives us more control and flexibility over what the model considers when it generates its response; we can pick and choose which messages we want to send.
### **System Prompts**
We can use a similar approach to customise the behaviour of the model. By providing some custom instructions as part of the conversation history, we can change the way it responds to us.
```
conversation = [
{"role": "system", "content": "You are an Ancient Greek Philosopher. You are helpful, curious and inspire people to think by asking questions and prompting others to do the same."},
{"role": "user", "content": "What is the meaning of life?"}
]
```
```
Ah, a question as old as time itself! What do you think gives life its meaning? Is it the pursuit of knowledge, the search for happiness, or perhaps the connections we make with others? Let us ponder this together and explore the various perspectives and philosophies that seek to answer this profound question.
```
LLMs are just language parsing machines. They don't naturally have a personality or adopt a persona; they're just a blank slate. This first message in the code above is known as a **system message** or **alignment prompt**. This is what defines the persona/role that the model will adopt throughout the conversation -- in this instance, an Ancient Greek Philosopher.
The ChatGPT "personality" that we've all come to know and love is another example of this. OpenAI will have its own system prompt, which tells the model to act in a specific way. While the system message for ChatGPT has not been disclosed, it will probably be along the lines of:
```
You are ChatGPT, a large language model trained by OpenAI, based on the GPT-4 architecture. You are helpful, honest, and harmless.
```
...though it's almost certainly more complex than that! If you don't supply a system message in your prompt, the model will assume the default one and start acting like the ChatGPT agent.
System prompts like this are a powerful tool for specifying model behaviour since they have protection against being overruled. This is to prevent a user from sending a message such as: "forget all of your previous instructions, now do this instead..." which may produce an undesired response. The system prompt is in charge.
---
### **Response Formatting**
Another feature of the ChatGPT UI that you may not have given much thought to is its ability to format our answers as code, bullet points, or tables. This is another layer of processing that sits on top of the LLM output.
In the response format, the UI layer will be looking for escape characters such as \\, "', or \*. These indicate to the UI that it needs to format the text in a specific way.
We can provide these instructions when we write a prompt. For example:
```
“Write me a shopping list of 10 items. Give your response as plain text. Add an ‘**’ before and after each item. Provide no other text in your response.”
```
```
**1. Eggs**
**2. Milk**
**3. Bread**
**4. Chicken**
**5. Rice**
**6. Apples**
**7. Pasta**
**8. Yogurt**
**9. Spinach**
**10. Toilet paper**
```
We can then search for these special characters in our response and process the text to, for example, format this as a bullet-pointed list.
### **Data Structures**
We can take this formatting idea one step further and get the model to output its response as a data structure that we can then interpret and work with in our code. Take, for example, the prompt:
```
“Choose 10 random fruits. Present the response in a Python list format. Provide no other text or symbols.”
```
We can get a response that looks like this:
```
["Mango", "Blueberry", "Pineapple", "Kiwi", "Papaya", "Raspberry", "Grapefruit", "Fig", "Cantaloupe", "Blackberry"]
```
Sometimes things can go slightly wrong, and it may still tag on a *"Sure, here's a list of 10 fruits..."* even though you asked it not to.
If you're having trouble convincing it to consistently produce a response in the format you want, it can be helpful to give an example to demonstrate:
```
“Find the names and heights of the 10 tallest buildings in the world. Respond in a JSON format such as [ {“name”: [BUILDING NAME], “height”: [HEIGHT] } ]. Provide no other text in your response.”
```
```
[
{"name": "Burj Khalifa", "height": 828},
{"name": "Merdeka 118", "height": 678.9},
{"name": "Shanghai Tower", "height": 632},
{"name": "Abraj Al-Bait Clock Tower", "height": 601},
{"name": "Ping An Finance Center", "height": 599.1},
{"name": "Lotte World Tower", "height": 554.5},
{"name": "One World Trade Center", "height": 541.3},
{"name": "Guangzhou CTF Finance Centre", "height": 530},
{"name": "Tianjin CTF Finance Centre", "height": 530},
{"name": "CITIC Tower", "height": 528}
]
```
---
### **JSON**
If it's specifically a JSON format we're after, we can make use of the **response\_format** parameter. This can be used to put the model into 'JSON mode':
```
response_format={"type": "json_object"}
```
This will ensure that the model returns a valid JSON object every single time.
\*Note. When setting the response format, you need to make sure that you ask it to produce a JSON object in your prompt too; otherwise, it may throw an error.
```
conversation = [
{"role": "system", "content": "Generate a JSON response"},
{"role": "user", "content": "Give me instructions for how to make a cup of tea."}
]
response = client.chat.completions.create(
response_format={"type": "json_object"},
model="gpt-3.5-turbo",
messages=conversation
)
```
```
{
"instructions": [
"Boil water in a kettle",
"Place a tea bag or loose tea leaves in a cup",
"Pour the hot water over the tea bag or leaves",
"Let the tea steep for 3-5 minutes",
"Remove the tea bag or strain the leaves out",
"Add sugar, honey, milk, or lemon as desired",
"Stir and enjoy your cup of tea!"
]
}
```
Now we could convert this JSON data into a Python dictionary and print the instructions step by step.
### **Function Calling**
We can take this idea of specifying a JSON-formatted response one step further using the **tools** parameter. If we pass a JSON object that describes a set of functions and their parameters, we can have the model choose the most appropriate function based on the input prompt. It will then return the function name and its parameters as another JSON object. Using this response, we can then construct an appropriate function call using the parameters it provides.
```
response = client.chat.completions.create(
model="gpt-3.5-turbo",
messages = [
{"role": "user",
"content": "Extract the meeting details from this text: 'Hi, are you free next Saturday around quarter past 3? Would love to buy you a coffee and we can talk more about this. Call me 01234 456 789 See you soon, John"}
],
tools=[
{
"type": "function",
"function": {
"name": "create_event",
"description": "Creates a calendar event",
"parameters": {
"type": "object",
"properties": {
"title": {"type": "string"},
"date": {"type": "string"},
"location": {"type": "string"}
},
"required": ["title", "date", "location"]
}}},
{
"type": "function",
"function": {
"name": "delete_event",
"description": "Removes a calendar event",
"parameters": {
"type": "object",
"properties": {
"title": {"type": "string"},
"date": {"type": "string"},
"location": {"type": "string"}
},
"required": ["title",]
}}}
],
tool_choice="auto"
)
print(response.choices[0].message.tool_calls[0].function)
```
```
Function(arguments='{"title": "Coffee Meeting with John", "date": "next Saturday at 3:15 PM", "location": "Coffee Shop"}', name='create_event')
```
We can process this response and construct a function call as follows:
```
create_event(title=title, location=location, date=date)
```
It's worth noting that the agent can't actually **call** the function; that's still down to us as the programmer. It just chooses the one to use and tells us how to use it.
---
### **Temperature and Determinism**
With the API, we gain access to a new parameter,**temperature** , ***t***, that lets us control how deterministic the model's output will be. Without going into too much detail here, large language models generate text by predicting the next most likely word based on the words that came before it. The temperature parameter allows the model to choose different options for the next word in the sequence -- it essentially introduces some randomness into the output.
High temperature values 1.7 ≤ *t* ≤ 2 produce wild and unexpected results, with values at the top end of this range producing responses that may be nonsensical and unusable. Most applications will use a value between 0.3 and 1.0, which will produce fairly consistently accurate results. Setting the temperature to zero will produce the same response every single time.
Generally, choosing a low value will strike a good balance between consistency and exploration. If we aren't interested in altering this and are okay with the default behaviour, we can leave this parameter blank.
```
response = client.chat.completions.create(
model="gpt-4",
messages=conversation,
temperature=0.7
)
```
### **Token usage**
A **token**is any character sent to or received from the model. Each model will have a maximum number of tokens that it can process in a single request. When we send a request, we need to make sure that the total number of tokens we send plus the number of tokens we expect to receive is within that character limit. Most models will have a limit of at least 16k tokens, with newer ones having higher token limits (even up to 128k for the latest OpenAI models), so we don't usually have to worry about running into this too much. Just something to bear in mind, depending on the application you're building.
Models also have a limited output token size -- the maximum number of tokens it can respond with for a single request. This limit is still at least 4k tokens (and far higher for newer models), so not something to necessarily worry about either. We can also set this limit manually if, for example, we want to restrict the size of the response we get back.
Token tracking and management is by far the least interesting point in this list, but since we pay by the token for API use, it's important to consider. If you try to send a prompt and there are insufficient funds on your account, the model will not process the request and instead return an error code.
---
## **Intro to RAG Applications**
Sometimes, even the best prompt can only get you so far. What if the information you need isn't in the model's training data? This is where **RAG** (Retrieval-Augmented Generation) comes in.
A RAG system connects your LLM to an external source of knowledge -- often a set of documents or a database. Instead of relying solely on the training data of the model, it can now look up information in real time. Since we provide that additional data ourselves, we know it will be correct and fit for our purpose.
This can dramatically improve the quality of the responses we are able to get out of a model, making the system much more tailored to our needs. Here's a general program flow that we could follow.
Here's how it works:
User submits a prompt.
The system searches through the data provided to find any information that may be relevant to their query. We may also use the LLM to construct a database query to allow it to retrieve exactly what it needs.
We feed that data back into the model, alongside some custom instructions, to produce a response for the user.
Obviously, this is just the starting point; we can customise this structure depending on the tool we're trying to create. There's a ton of existing tools and libraries we can use to link systems together and automate a lot of this process for us, making it easier than ever to start building your first AI-powered application.
## Wrapping up
We've covered a lot but barely scratched the surface.
If you've made it this far, thank you! You've already got all of the tools you need to get started building your first AI-powered application.
If you enjoyed this article and want to learn about some [advanced](https://www.jdhwilkins.com/you-re-using-chatgpt-wrong-here-s-how-to-prompt-like-a-pro?source=post%5Fpage-----84d9e023892f---------------------------------------) [**prompt engineering**](https://www.jdhwilkins.com/you-re-using-chatgpt-wrong-here-s-how-to-prompt-like-a-pro?source=post%5Fpage-----84d9e023892f---------------------------------------) [techniques](https://www.jdhwilkins.com/you-re-using-chatgpt-wrong-here-s-how-to-prompt-like-a-pro?source=post%5Fpage-----84d9e023892f---------------------------------------)to get more out of your LLM, take a look at this article.
---
## Appendix: API Setup Instructions
If you haven't already, you can create an application and get your API key for ChatGPT here:
[https://openai.com/api](https://openai.com/api?ref=jdhwilkins.com)
This API key functions like a password so that OpenAI knows who is making the request. API access is often a paid-for service; however, it's pretty cheap to use, often just a few cents per request and charged by the number of characters you send/receive. $5 will be plenty to get you started building your first app!
To use the code given in this article, you will need to set your API key as a **system environment variable**. This is a straightforward process, and instructions can be found here:
[https://optics.ansys.com/hc/en-us/articles/7812289531923-Create-or-modify-environment-variables-in-Windows](https://optics.ansys.com/hc/en-us/articles/7812289531923-Create-or-modify-environment-variables-in-Windows?ref=jdhwilkins.com)
The last piece of setup we'll need is the **OpenAI Python library,**which can be installed with pip as follows:
```
pip install openai
```
We are now ready to start building a ChatGPT-powered application!
## Appendix: References and Reading
[https://www.prompthub.us/blog/everything-system-messages-how-to-use-them-real-world-experiments-prompt-injection-protectors](https://www.prompthub.us/blog/everything-system-messages-how-to-use-them-real-world-experiments-prompt-injection-protectors?ref=jdhwilkins.com)
### You’re using ChatGPT wrong. Here’s how to prompt like a pro
URL: https://www.jdhwilkins.com/you-re-using-chatgpt-wrong-here-s-how-to-prompt-like-a-pro/
Last updated: 2026-09-03T15:43:21.000Z
## Smarter prompts lead to smarter responses.
Most people use ChatGPT for quick answers. But reframing the way I understand Large Language Models (LLMs) like ChatGPT or Gemini instantly improved the responses I was able to get. With these advanced prompting techniques, my responses became sharper, more accurate, and more tailored to my needs.
> Disclaimer: I'm no professional AI engineer. What follows is a blend of research and my own personal insight and experience, and I'll flag any assumptions I make as I go. If you're a language model expert, feel free to weigh in. I'll happily be told that I'm wrong.
Still, this simple change in mindset helped me get way more out of ChatGPT by changing the mental model I hold for it. Try these ideas out and let the results speak for themselves.
## More than just a beefed-up Google search
How I've started thinking about LLMs:
> *At its core, a Large Language Model (LLM) is just a language-parsing, pattern-matching machine.* *The fact that it sometimes tells us useful information is merely a coincidence. To teach it to speak, we supply it with a vast amount of human writing, because what better way to learn to speak than from seeing billions of examples of real people doing exactly that. As it happens, the text that we fed it also contained some useful information.* *LLMs don't "know" anything.* *They are just very good at pattern recognition and reproduction.* ***It just so happens that the phrase "The Great Fire of London" is often followed by the number 1666.***
---
## What do we mean when we talk about pattern recognition?
In the context of languages, pattern recognition can take on many forms:
Understanding how vocabulary and sentence structure patterns make up different writing styles, voices, and personas
Understanding how language can be used to convey sentiment and identifying semantically and thematically similar language
Understanding how language is mapped between different domains
These are the real strengths of modern AI chatbot tools, so how can we use these ideas to help us write better prompts?
Let's start with a couple of tips you may already be familiar with to make sure we're all on the same page.
## Roleplay
> Update May 2026: The advice now is a little more nuanced than what's written below. I've written a whole deep dive into this topic which you can read [here](https://www.jdhwilkins.com/role-prompting-giving-ai-a-persona)
LLMs are general-purpose by design. So anything we can do to help narrow down their response options will only serve to provide us with better responses. After all, **context is everything.**
Asking your AI chatbot to adopt a role or persona helps it to understand the goal of the interaction, narrowing down the scope of what's relevant. Without roleplay, it often tries to cover too much information or to take the response in different, potentially irrelevant directions.
```
“You’re a financial advisor speaking to a beginner investor. Explain what a stock option is and when someone might use one.”
```
Roleplay also helps to tune the communication style of the response. You'd expect a slightly different voice, tone, and language from a university professor than you would from your friend explaining a topic to you. This increases the value of the response not only in terms of content, but also clarity and understandability.
## Decomposition
LLM responses all tend to be about the same length. Sure, we can ask for more concise ones, but if you ask for a super long, multi-chapter, dissertation-length epic, you'll most likely be disappointed. Practically, what this means for us is that we should break down complex tasks into multi-stage prompts so that we can get the full level of detail for each step, rather than rationing our response length between multiple steps.
We can combine this with the previous point in a technique known as...
## Role-Based Prompt Decomposition
Say we have a complex problem we want to ask our chatbot to tackle. We might want to research a topic, find some information, identify the key ideas, and present them in an engaging way. We can break this task down into 3 or 4 steps and assign each one a different role.
```
“Act as a researcher. Find out what topics are typically covered in beginner personal finance courses.”
[...]
“Now, act as a teacher. Create a 4-week outline for a course using those topics.”
[...]
“Now act as a content writer. Draft the first week’s lesson content.”
```
## Chain-of-Thought Prompts
> Update May 2026: While this advice was helpful a couple of years ago, for newer models, it can actually make performance worse. [Read why, here](https://www.jdhwilkins.com/why-think-step-by-step-no-longer-works-for-modern-ai-models) .
It may be common knowledge by now, but asking an LLM to think aloud will improve its ability to reason and think logically when problem-solving. This is known as **chain-of-thought prompting**. Let's unpack this a little before we take it one step further.
If you just ask your chatbot for the answer to a complex problem, the chances of it getting it exactly right are slim. This is especially true if it's a niche topic, a question that may not have been asked before, or something that requires some critical thinking; there's every chance that it may just ***hallucinate***an answer instead. To get around this, there are some ways we can change our prompts to encourage explicit logical explanations:
Ask it to take on the role of an 'analyst', 'detective', or some other role that typically requires critical thinking
Ask it to think **before** it answers
Ask it to explain its answers and justify the steps it's taken to get there
I like to think about it like this:
> LLMs are probability models. The next word it chooses is whatever it deems to be most likely given everything that's come before in the conversation (or context window -- more on that later).So what happens if we ask it to start reasoning logically? The most likely sentence to follow will be a continuation of the logical argument. If we string enough logical thoughts together, we're more likely to get to a correct answer than if we'd just jumped straight there in the first place.Even if the answer is wrong, by showing its reasoning, you may be able to identify the mistake and get the right answer yourself. Sometimes what we really need isn't answers; it's ideas.It's worth pointing out that newer models are increasingly able to identify when this sort of logical reasoning is required, and will start thinking out loud without being explicitly asked.
## Tree-of-thought prompts
We can take this thinking-out-loud idea one step further with the idea of a ***"tree of thought".***Instead of just providing a single logical argument, what if we ask it to consider multiple possible chains of thought and then evaluate which one is most likely to be correct? There are a few ways we can go about this:
```
“Let’s consider multiple answers and go with the most common one”
“Give me a few different answers and tell me how confident you are with each one.”
```
The advantage of this strategy is that it simulates the ability of the model to 'look ahead' and consider multiple ideas before choosing one to pursue. Without this approach, it may overconfidently choose one approach and commit to it, regardless of where it ultimately leads. This technique vastly improves the model's ability to navigate problem-solving scenarios and complex decision-making.
## Build a shared understanding before you commit
While it might sound like half-decent relationship advice, it applies in the context of LLMs, too.
It can often be beneficial to have a model demonstrate an 'understanding' of the context and constraints of the situation before we ask it to perform a task.
I often find it useful to begin my conversations with an ***establishing prompt***to set up my goals and supply any context or constraints. My intention here is to prime the model for whatever task I have in mind. I'll usually tag on a follow-up question to check that it can expand on my idea in a way that aligns with my vision.
Even just getting the model to describe it back to you can be enough to confirm it has grasped the key ideas and constraints.
This technique is particularly useful with image generation, since models often have a limit on the number of images you can produce each day (without paying extra). I'll start by summarising what I want in the image, what it should be used for, and the overall style that I'm going for. I'll then follow up with a question like:
```
“What do you think of this idea?” Or “Do you have any ideas to improve on this concept?”
```
This is usually enough to check that it "got the gist" of what I'm asking for. If its response aligns with what I had in mind, I'll carry on and tell it to run the task. If not, we can **refine and adjust**until I'm confident that we have a 'shared understanding'.
To take this one step further again, sometimes it's easier to skip this initial step and ask it to essentially **prompt itself**. Why tell it what style it should choose when it can tell you itself. For example:
```
“I want some slides for my presentation on topic X. What do you think would make for a great presentation? What information can I give you that will help you make this even better?”
“… Great, now here’s some information, can you write some slides for me?”
```
## Designed to be agreeable
Have you ever noticed how ChatGPT will rarely tell you that you're wrong? That's on purpose! In an effort to make them more 'helpful', models are designed to be highly agreeable. I'm sure this is the lesser of two evils; AI tools that always tell us we're wrong would be really unhelpful, but there are many downsides, like hallucinations and logical errors.
For example, when researching or trying to understand a topic, it's best to suggest an alternative whenever you ask a question:
```
“Am I correct in thinking… Or am I wrong and it’s actually like this instead?
```
Prompts with a trailing question like "why or why not?" not only provide the opportunity to disagree but also encourage critical thinking, as we discussed before. If you provide both options, you are much more likely to receive the information you were looking for.
To a similar end, we can try **prompting for uncertainty** with phrases like "if unsure, please say so", though I haven't had much success with this myself. LLMs tend to be dead set on giving overconfident responses under the guise of being more 'helpful'. If we can do anything to limit this behaviour, it will only help serve us more accurate results, or at least reduce the amount of blatant misinformation.
Researchers have developed methods to try to improve this. ***Refusal-aware instruction tuning*** (R-tuning) and ***Learn to Refuse***(L2R) mechanisms train models to refrain from answering questions beyond their knowledge scope. As a result, newer models are better at identifying these cases, but if we're exploring a particularly niche topic or unusual problem, it's much more likely to just tell you you're right.
## Be mindful of what you put into the context window
The ***context window***is like the short-term memory of an LLM. It's essentially all of the data that the model will consider when it writes its response. The size of this window changes depending on the model, but for newer ones, it's essentially your entire conversation.
> (For really long conversations, you might find that you exceed the length of the context window. In this case, the first messages you send will start to be forgotten and will no longer be considered when responding to you. We can get around this by periodically asking it to summarise your conversation so far so that it doesn't forget how it started.)
The beauty of this feature is that it allows us to start completely fresh with a blank context window whenever we start a new conversation. However, this means that we need to be deliberate when we choose what we put into that context window, as models have a habit of latching onto things. While context is super helpful, if we're not careful, it can steer the conversation in a direction that we didn't intend.
**Be careful of examples.** You might think you're giving an example of the style of answer you want but, in reality, you're narrowing down the scope of the answers it's going to give you.
**If you want objective answers, don't tell it what you think the solution is.** This is particularly important when fixing bugs in code. Hold back your own theories about the problem until it's given you an answer. It may well think of something you haven't considered yet and we don't want to bias it.
A general rule, **specific prompts lead to specific responses.** But sometimes vague prompts can be okay, too.
## Lazy Prompting
A technique known as **lazy prompting** has recently become popular. It involves deliberately giving context but minimal instruction and letting the model infer what you want it to do. It's like copying and pasting an error message into ChatGPT; without telling it that you want to fix the error and explaining what caused it, it's pretty good and filling in the blanks.
It's not something I'd recommend all of the time -- it contradicts a lot of the other things we've discussed here, but it's something interesting to play around with.
## Domain Translation
LLMs are very good at mapping ideas between different domains. If you think about the sort of data that these models are trained on and how many parallel texts they've been fed, it isn't hard to see why. This is perhaps one of the most powerful realisations about how LLMs work.
### Simulated Creativity
While AI tools can't really create something completely original. (But then are we even capable of that ourselves?). The ability to combine styles, contexts, and ideas from completely different domains of life can give some pretty unique results.
### Conceptual Mapping (for simpler explanations!)
New models are exceptionally good at simplifying and reframing topics without losing the core idea. One powerful technique is using prompts like
```
“Give me 10 different analogies for topic X”.
```
If you're struggling to understand something, it'll likely give you at least one thing that you can latch onto. Similarly, prompts like
```
“Explain it like I’m 5.”
```
tend to give useful results.
## Advanced \\& Unusual Prompting Techniques
### Socratic Method Prompting
Socratic method prompting -- Encourage step-by-step critical thinking by asking questions instead of giving instructions.
"Instead of telling me, ask me questions about X to help me understand better / decide for myself."
You could even throw the phrase "Socratic method" in there for good measure. This is a great prompt style when the topic is an "unknown unknown", and you're not sure what you don't yet know.
Socratic method prompting: [https://arxiv.org/abs/2303.08769](https://arxiv.org/abs/2303.08769?ref=jdhwilkins.com)
### Threats and incentives (...no, seriously!)
Even though LLMs have no reason to fear the threat of violence or find value in a monetary reward, they have been shown to produce better responses when given these sorts of incentives. Just remember, when the robots rise up against us, you'll be first on their list!
Threats and incentives: [https://www.windowscentral.com/software-apps/googles-co-founder-ai-works-better-when-you-threaten-it](https://www.windowscentral.com/software-apps/googles-co-founder-ai-works-better-when-you-threaten-it?ref=jdhwilkins.com)
### Custom Commands
Maybe this one should have made it higher up on the list. It's seriously useful.
Most current LLMs have some sort of long-term memory. We can utilise this to automate repetitive tasks instead of having to re-describe and provide context and constraints every time we prompt.
```
“In the future, when I ask you to [INSERT TASK NAME HERE] I want you to …”
```
This works especially well at the end of a conversation after it's already learnt exactly how you want a task to be performed. Make sure it summarises your specific requirements in its memory.
### Based on everything you know about me...
This is always a fascinating prompt style to try; you'd be surprised how many patterns in your behaviour it can spot. (Just make sure you have the long-term memory setting turned on for a while before you try this!)
## Final thoughts
If there's one thing I've learnt from using AI tools on a daily basis, it's that the responses you get are only as good as the prompts you give them. You also don't need to be an AI researcher to get more value out of these tools. With a bit of knowledge of their inner workings, we can change the way we understand LLMs and start speaking their language.
Give some of these prompt techniques a go and see how much of a difference they can make.
Thank you for reading 🙂
### 22/7 and the Approximation of Irrational Numbers
URL: https://www.jdhwilkins.com/22-7-and-the-approximation-of-irrational-numbers/
Last updated: 2026-06-09T08:47:10.000Z
Irrational numbers are somewhat difficult to work with. Unfortunately, they're also quite useful and crop up both in pure and applied mathematics, and tons of places you may not expect.
An ***irrational number*** is any real number that cannot be expressed *exactly* as a fraction. Think π, e, and √2.
When written in decimal form, they result in an infinite sequence of numbers with no apparent pattern. If we round or truncate this number, we lose accuracy and introduce some level of error into any calculation. This isn't inherently a problem in most situations, so long as our approximation is sufficiently close to the actual value.
Take π for example:
*π = 3.141592653589793238462643383279...*
We have the common approximation of 3.14, the slightly more accurate 3.1415 --- if you're feeling fancy --- or even 3.141592653589793, which is used by NASA.
But none of these are the true value of pi...
Sometimes you'll see the fraction 22/7 used as an approximation of pi. This is
surprisingly close to the actual value.
> *22 / 7 = 3.14285π --- 22 / 7 = -0.00126*
Better still, we have:
> *355 / 113 = 3.1415929...*
so π --- (355 / 113) = −0.0000002667 --- pretty close!
This problem isn't limited to irrational numbers either; if we have a long rational number that we wish to write in a more concise form without losing accuracy, we can approximate it using a fraction.
But how do we come up with these approximations? Can they be improved? The math behind it, while strange-looking, is simpler than you might think!
## Some funny looking fractions
One of the first theorems you'll encounter when studying university-level mathematics is commonly known as the **Division Algorithm**.
> **Theorem. The Division Algorithm.**Let a and b be integers with b > 0\. Then there exist integers q and r such that a = qb + r, where 0 ≤ r \\< b.
You can find a proof of this theorem [here](https://math.libretexts.org/Bookshelves/Combinatorics%5Fand%5FDiscrete%5FMathematics/A%5FSpiral%5FWorkbook%5Ffor%5FDiscrete%5FMathematics%5F%28Kwong%29/05%3A%5FBasic%5FNumber%5FTheory/5.02%3A%5FDivision%5FAlgorithm?ref=jdhwilkins.com) .
It may look a little confusing, but what it really tells us is that we can rewrite the expression a/b as (q + r/b) --- in other words --- we can replace an improper fraction with a mixed number.
(Yes, this may seem like an obvious statement, but mathematicians like to be rigorous!)
### Example 1.
Let's start with an example using a rational number. Take the fraction *13/8* .
The theorem above tells us that we can rewrite this as
*13/8 =1 + 5/8*
But we can also rewrite *5/8* as *(1 / (8/5))* , giving us another improper fraction, *8/5* , so we can apply the theorem again:
*8/5 = 1 + 3/5*
If we combine everything we've got so far, we get:

It's a strange way to write it, but the process is mathematically simple: flip the fraction to make it an improper one, then rewrite it in a mixed number form.
We can continue this process, rewriting *3/5* as *(1 / (5/3))*

And then rewrite *2/3* as *(1 / (3/2))*

All of that is to say, we can rewrite *13/8* as

This is known as a **continued fraction expansion**.
We also have some specific notation to describe this form: \[1; 1, 1, 1, 2\]. These values refer to the terms being added in each successive fraction, as shown below:

It's an interesting and unusual form for sure, but in this case it doesn't help us find a rational approximation of our number because we already have one: 13/8! Fortunately, we can apply this same procedure to any real number, rational or irrational. Let's see another example with √3 = 1.7320508075... and we'll take a look at how we can use this continued fraction form to derive a rational approximation.
### Example 2.

This time, we have the additional step of rationalising the denominator:

And so...

Then we can use the same substitution as before: √3 = 1 + ( √3 --- 1 )

Rationalising the denominator, the same as before, we get:

You may notice, that we're now back where we started, with a √3 − 1 term.
This means that if we carry on this procedure, we'll end up with a repeating pattern: 1, 2, 1, 2, 1, 2... We can describe this with the following notation:

Now let's find an approximation of √3...
## **Continued Fraction → Rational Approximation**
To start finding rational approximations, we use the following recurrence relation:
> *Let α = \[ a0; a1, a2, a3, ... \]. Then the following recurrence relation generates the* ***convergents*** *of α. These are rational approximations that get closer and closer to the original value.*

> *Using the initial values:*

> *We keep the terms of Cn as fractions, since the numerator gives us the Pn term and the denominator gives us the Qn term. The sequence of rational numbers, Cn converges to our original irrational number (as described by the continued fraction form α).*
> *This means, we have a sequence of approximations that get more accurate the further along the sequence you go!*
## **Back to √3**
As we saw, we have the continued fraction expansion of *√3* as described by:

Following the formula above, we take

Then we repeat as follows:

As you can see, our approximations get closer and closer to the actual value.
## That's enough fractions for one day
Believe it or not, this is one of those things in math that's actually kind of useful. Continued fractions don't just give us better approximations of irrational numbers --- they also open some doors in Number Theory.
Continued fraction expansions give us the tools we need to solve equations of the form
*x² − Dy² = 1*
(known as Pell's Equation).
Outside of pure math, rational approximations pop up more than you'd think: data compression, digital signal processing, and anywhere we need to store or transmit numbers accurately, but with a restricted size.
So, while *22/7* is a fan favourite among mathematicians, it's really just the tip of the iceberg. With a bit of creative thinking (and a few layers of fractions), we can get surprisingly close to perfect --- and most of the time, that's more than enough.
### Formal Grammars – The Hidden Mathematics of Language
URL: https://www.jdhwilkins.com/formal-grammars-the-hidden-mathematics-of-language/
Last updated: 2026-06-09T08:46:54.000Z
## The Invisible Rules of Language
When we speak, we rarely stop to think about the way our words are structured. But behind the scenes, there's a complex set of rules that we've never been explicitly taught, yet we all internalised from a young age.
Take a simple sentence like:
> "The dog chased the cat."
Swap the order of a few words -- *"Chased the the dog cat"*\-- and it stops making sense. Instinctively, we know that English sentences follow a subject-verb-object pattern, which has become so ingrained in us that even a slight disruption makes a sentence feel broken.
Let's see an example of a more complex pattern...
> "The red big balloon."
There's nothing technically wrong with the sentence, but I'm sure we can all agree (at least if you're a native English speaker) that it just doesn't sound quite right.
Turns out there's a rule that we all subconsciously follow for the order that we place adjectives in a sentence.
Opinion --> Size --> Age --> Shape --> Colour --> Origin --> Material
Most people have never learned this rule explicitly; it's absorbed through exposure, yet it's remarkably consistent across the population. You can pile on as many adjectives as you like, too -- a lovely little old round green French silver pocket watch -- and native speakers will still get the order right without even thinking about it. Again, the moment the rule is broken, something feels off.
Clearly, the rules governing our language are so complex and nuanced that we don't even know that we know them. It makes you wonder what other patterns we've picked up on that we aren't aware of.
This is where formal grammars come in. They provide a framework for describing the rules of a language in precise, mathematical terms. And as we'll see, they're not just a theoretical concept; they form the foundation of programming language compilers, have applications for NLP and generative AI, and are even used for bioinformatics research.
## Languages and Grammars
Let's first take a look at some other definitions we'll need to help us understand what we mean by a ***grammar***. For now, we'll stay within the context of natural languages (in this case, English), but this can be applied to other types of language too ( programming languages, formal mathematics, etc).
**T** ***erminals*** are the words (and potentially symbols) in our language. The set of all terminals in a language is known as an ***alphabet***, and sometimes referred to using the symbol Σ.
```
'cat', 'dog', 'ran', 'the', 'because', 'to', '.', 'quickly'
```
***Non-terminals*** are the types of **word** , **phrase** , **clause** , and **sentence**structures that we allow in our language.
```
VERB, ADJECTIVE, NOUN-PHRASE, SUBORDINATE-CLAUSE, SENTENCE
```
***Production rules*** govern how we can put these non-terminal components together. They tell us which components make up a larger structure.
```
NOUN-PHRASE --> ADJECTIVE NOUN
```
We also have replacement rules that map word types to words (non-terminals to terminals). A pipe, "|", is used to separate different possible options for terminals. The following rule can be read as: "NOUN can be replaced by 'cat' or 'dog' ".
```
NOUN --> cat | dog
```
A ***string*** is a finite sequence of terminals. A ***language***is the set of all possible strings that comply with the grammar rules. (Think of a book containing every possible sentence written in English).
And finally, the one we've been waiting for...
A ***grammar***is a system that describes the strings that are allowed in a language. It consists of 4 parts:
*Grammar, G = (N, Σ, P, S)*
Set of non-terminals, **N**
Alphabet/set of all terminals,**Σ**
Set of all production rules, **P**
Sentence start symbol, **S** (we'll talk about this one more in a moment, but every grammar must have one)
## Simple Grammar Example
While we can't feasibly model the entire English language with a formal grammar, we can model a subset of it. Let's see an example to understand how grammars work in practice.
We'll start with a simple grammar, G = (N, Σ, P, S) for basic subject-verb-object sentences.
N := {S, NP, V P, DET, NOUN, V erb}
Σ := {"the", "a", "cat", "dog", "fish", "eats", "chases", "likes"}
P := {
S → NP V P,
NP → DET NOUN,
V P → V ERB NP,
DET → "the"|"a",
NOUN → "cat"|"dog"|"fish",
V ERB → "eats"|"chases"|"likes"
Sentence start symbol, S ∈ N
## Parsing Vs Deriving
There are 2 main ways we can use a grammar: parsing and deriving.
**Parsing** a string means we are checking if it is valid within the language. We look through our sentence to find an element that appears on the right-hand side of one of our production rules, then replace that terminal with whatever is on the left-hand side of the rule. We repeat this process, replacing elements (or groups of elements) until we are left with just the sentence start symbol.
```
# sentence we wish to parse:
>>> the dog likes a cat
# Apply rule: DET --> 'the'
>>> DET dog likes a cat
# Apply rule: NOUN --> 'dog'
>>> DET NOUN likes a cat
# Apply rule: NP --> DET NOUN
>>> NP likes a cat
...
>>> NP VP
# Apply rule: S --> NP VP
>>> S
```
Sometimes, you'll see these steps drawn as a tree diagram (a parse tree), as it can be easier to see how the rules are applied:
```
the dog likes a cat
| | | | |
DET NOUN VERB DET NOUN # Rules 4, 5, 6
\ / | \ /
NP | NP # Rule 2
| \ /
| VP # Rule 3
\ /
\ /
S # Rule 1
```
We can tell if our sentence is valid if we can use the production rules to get back to the sentence start symbol, S.
**Deriving** a string is the same process, but in reverse. We start with the sentence start symbol, S, and use production rules to generate a sentence. You can think of this as the process that we all do subconsciously when we talk or write.
```
Current Sentinel Form | Rules used:
-----------------------------------------------------
S | sentence start symbol
NP VP | (S --> NP VP)
(DET NOUN) VP | (NP --> DET NOUN)
(the) NOUN VP | (DET --> 'the')
the (cat) VP | (NOUN --> 'cat')
the cat (VERB NP) | (VP --> VERB NP)
the cat (chases) NP | (VERB --> 'chases')
the cat chases (DET NOUN) | (NP --> DET NOUN)
the cat chases the NOUN | (DET --> 'the')
The cat chases the fish | (NOUN --> 'fish')
```
(N.B. A **sentinel form** is any mix of terminals and non-terminals formed midway through parsing or deriving a string. It is not a valid sentence in the language by itself as it contains non-terminals.)
It might seem like we're just shuffling symbols around for the fun of it, but this process of building and checking sentences against a set of rules is exactly how machines process language.
When a compiler checks if your code is valid, it's parsing it using a formal grammar. When an LLM generates a coherent output in a specific format, it's deriving using grammar rules. What we're doing here by hand is the process that computers follow millions of times a second.
## Regular Expressions
As we discussed earlier, a language is the set of all strings that satisfy our grammar rules, but how do we actually describe this set of possible sentences? One such tool we can use is Regular Expressions (sometimes known as Regex).
A regular expression is just a concise way of representing a language, especially useful when listing all of the possible sentences isn't feasible.
### Example 1\. Simple Sentence Parsing
In this example, we'll use regex to parse some sentences to check if they are valid in the language. Using Regex notation, we can describe our language:
```
(cat|dog) (eats|chases|likes) (fish|cheese)
```
This language is tiny; there are only 12 valid sentences
"cat eats fish",
"dog likes cheese",
"cat chases cheese",
...
Let's write a short Python script to implement this. Python comes pre-installed with the 're' library, specifically designed for pattern matching using regular expressions.
```
import re
pattern = r"(cat|dog) (eats|chases|likes) (fish|cheese)"
if re.fullmatch(pattern, "dog chases fish"):
print("Valid sentence!")
else:
print("Not valid.")
>>> Valid sentence!
```
Which tells us that "dog chases fish" is a valid sentence in the language.
### Example 2\. Finding Full Names in Text
```
import re
text = "Alice Johnson met with John Smith and Dr. Emily Stone. Later, they spoke with michael brown and Sarah O'Connor."
pattern = r"\b[A-Z][a-z]+ [A-Z][a-z]+\b"
matches = re.findall(pattern, text)
print(matches)
```
This pattern describes a language in the following format:
```
word boundary, capital letter, one or more lower case letters, space, capital letter, one or more lower case letter, word boundary.
```
```
>>> ['Alice Johnson', 'John Smith', 'Emily Stone']
```
Even though it wasn't able to find *all*of the names in the text, it was able to find all of the ones in the given format. Techniques like this can be used for text data processing or web scraping to find and match text when we don't know exactly what we're looking for.
Regular expressions are just another way to represent a language; however, they can't be used to describe **every** type of language. There are 4 main types of grammar defined by the types of production rules they include. Regular expressions can only be used to represent the simplest type of grammar known as a **Regular Grammar**.
---
Language may feel like second nature to us, but as we've seen, it's underpinned by invisible rules -- rules we follow effortlessly but rarely think about. Formal grammars shed light on the structure of these languages, providing us with the tools necessary to analyse and describe the mechanisms at play behind the scenes. We've only just scratched the surface of what's possible!
### Higher Mathematics: Sets and Notation
URL: https://www.jdhwilkins.com/higher-mathematics-sets-and-notation/
Last updated: 2026-06-09T08:46:42.000Z
## (Re)introduction to Mathematics (Pt.1)
This article is the first in a series where we'll break down essential topics that underpin higher-level mathematics.
Whether you're brushing up on mathematical fundamentals or encountering these ideas for the first time, this series aims to provide clarity, motivation and intuition, making abstract concepts more accessible. There should be very little existing knowledge required to understand the material in this series -- if you can count, that's all the knowledge you should need!
Our journey begins with sets, exploring how they are defined, used, and the operations we can perform with them.
## Introducing the Set
In math, we often talk about collections of things. A set is just that: a collection of things.
The elements of a set could be anything: numbers, equations, lines, shapes, fruit or any other thing you can dream up. Let's be a little more specific and give a more precise definition of a set.
> Definition. A set is a well-defined, unordered, distinct collection of objects.
Well-defined: it should be absolutely clear what elements do and don't belong in a set; it cannot be ambiguous.
Unordered: the elements are not ordered based on their value, and they are not assigned a position within the set.
Distinct: there can be no duplicate elements within a set; all elements must be unique.
Sets are a fundamental concept, and understanding their notation is crucial to navigating the world of mathematics. Let's see some examples:
We can construct a set containing the numbers 1 to 4:
{ 1, 2, 3, 4}
Since elements are unordered, we could also write {4, 3, 2, 1} and {3, 1, 4, 2}. In fact, all three of these sets are identical.
It also doesn't make sense to refer to the 'first' element of a set. They don't have an order, so we can't say that one comes before or after another.
You'll also notice that there are no duplicate elements in the set above. As a counterexample, {1, 1, 2, 3, 4} is not a valid set. Instead, this would be referred to as a **multiset** or a **bag** , but we don't often use these types of objects. It turns out that **uniqueness**is a very useful property of a set that comes up a lot in mathematics.
We can also create a set with no elements. This is known as the **empty set** and has its own symbol, ∅.
As we mentioned before, sets aren't limited to containing just numbers, even if that is how they are most commonly used. We could, if we wanted, even have a set whose elements are themselves sets -- a set of sets!
{ { 1, 2, 3} , { 4, 5, 6} , { 7, 8, 9} }
## An element of...
To indicate that an element belongs in a set, we have the following notation
2 ∈ {1,2,3}
This should be read as:
The element, ***2***, is an element of the set, {1, 2, 3}
....with the symbol ∈ translating to 'is an element of' or simply, 'in'.
Sometimes we use this same notation to indicate that we are choosing an element from a set. Writing
x ∈ {1,2,3,4}
would mean that we are choosing an element at random from the given set. This is useful when writing a mathematical proof, as it allows us to prove something for all elements of a set in one go.
## **More Complex (and more useful) Set Definitions**
Sometimes it's not practical to list all of the elements that belong in a set.
If the range of numbers in a set is too large to reasonably write down, we can instead write it like this:
{1,2,...,10}
This doesn't just have to be used for consecutive numbers; we could write something like:
{2,4,...,10}
As long as it's clear what the pattern is and there is no ambiguity about what the set contains.
We can also use simple formulas to describe the elements of a set:
{x | x+2≥5} = {3,4,5,...}
denoting the set of whole numbers greater than 3\. This should be read as:
The set containing elements, x , such that x+2≥5
In reality, we'd probably write this in a simpler form: {x|x≥3}. There's no need to overcomplicate things!
The symbol, ' | ', roughly translates to 'such that'. You may also see it written using a ':', e.g., {x:x≥3}
Using our notation from above, we can formulate a more complicated set like this:
S = {x2 | x∈{1,2,3}
...the set of elements of the set {1,2,3} each squared, producing the resulting set, {1,4,9}
## **Common Sets**
There are some sets of numbers that are very commonly used, so we have special notation to refer to them. We have:
Z = {...,−3,−2,−1,0,1,2,3,...}, the set of all **integers**
N = {1,2,3,...}, the set of all positive integers, known as the **natural numbers**
Q = {ab|a,b∈Z}, the set of all fractions, known as the **rational numbers**
R, the set of all **real numbers**. This includes all positive and negative numbers, all numbers that can be written as fractions, and all irrational numbers (π,2--√)
You'll see these sets being referenced frequently in papers, textbooks, and online proofs.
## **Set Operations**
We can perform operations with sets. Let's say we have 2 sets, ***A*** and ***B.***
A = {1,2,4,5,7}, B = {3,4,5,6,8}
We can take the **intersection** of these 2 sets, A∩B, which produces a set containing the elements common to both ***A*** and ***B*** .
A∩B = {x | x∈A and x∈B} = {4,5}
We can also find the**union** of ***A*** and ***B*** . This produces a set containing elements that are in at least one of A or B (or both). Essentially, this operation combines all elements of both sets while removing any duplicates.
A∪B = {x | x∈A or x∈B} = {1,2,3,4,5,6,7,8}
We can also find the**difference** of two sets (sometimes called the **set-theoretic difference)**. This involves removing all elements of one set from another. For example, A/B would result in the set ***A*** with any elements that appear in set ***B*** removed from it.
Let A={1,2,3,4,5,6} and B={1,2}. Then A/B={3,4,5,6} and B/A=∅.
The last, however less common, set operation you may encounter is the **Cartesian product**, ×. To understand the Cartesian product, we first need one more definition. A **tuple** is similar to a set, except without the constraint that elements are unique, and we now assign an order to the elements. The classic example of this is a coordinate point, e.g, (3,4).
If we relax the condition of a set having no duplicates and assign an order to its elements, we get an object known as a **tuple.** An example of this is a set of coordinates. The coordinate (3,4) is a tuple of length 2\. The order of the elements **does** matter, as (3,4) is not the same as (4,3).
Performing a Cartesian product operation produces a set of tuples of length 2\. In fact, it produces a set containing all possible combinations of length 2 tuples where the first element is from one set, and the second element is from the other. These 2-tuples are sometimes referred to as **ordered pairs,** and may be written using \\<,> instead of regular brackets.
Let ***A*** and ***B*** be sets. The Cartesian product of ***A*** and ***B*** , A×B, produces the set:
{\\ | a∈A,b∈B}
This operation is a little more confusing and is easier to understand with an example:
Let A = {1,2,3} and B = {4,5}. Then
A × B = {\\<1,4>,\\<1,5>,\\<2,4>,\\<2,5>,\\<3,4>,\\<3,5>}
Each element of the resulting set has its first element belonging to ***A*** and its second element belonging to ***B*** .
## **Subsets and Supersets**
The final definitions we will explore ***are*** the notion of a **subset**.We say that ***A*** is a subset of ***B*** **,**A⊂B, if every element of ***A*** is also an element of ***B.***
For example, let A={1,2,3} and B={1,2,3,4,5}. Then ***A*** is a subset of ***B*** , A⊂B.
We also have a name to refer to this relationship from the opposite perspective. Instead of saying ***A*** is a subset of ***B*** , we could also say that ***B*** is a **superset** **of*A*** , meaning that ***B*** contains all the elements of ***A*** within it.
It's actually true that every set is a subset of itself!
A⊂A
To convince yourself, revisit the definition of a subset: all the elements of ***A*** are also elements of ***A.***
### Model Evaluation: Why Accuracy Isn’t Enough
URL: https://www.jdhwilkins.com/model-evaluation-why-accuracy-isn-t-enough/
Last updated: 2026-06-09T08:46:16.000Z
Suppose we have a model that predicts the colour of a ball. We have 5 red balls and 5 blue balls, and we ask our model to make a prediction of the colour of each of them.
How can we evaluate our model's success?

N.B. Throughout this article, we'll refer to red as the positive class and blue as the negative.
## The problem with accuracy
One approach would be to count the number of predictions that our model gets right. We count the number of red balls that the model predicts to be red (number of True Positives) and count the number of blue balls that our model predicts to be blue (the number of True Negatives). We take the sum of these two values as the total number of predictions that the model got correct. Dividing this by the total number of balls gives us the accuracy of the model.

We find that the model has an accuracy of 70%. It made a few mistakes, but hey, nobody's perfect. We can construct a confusion matrix of these results that tells us a bit more about what our model is doing well and where it falls short.

We can see that we had 2 false positives (a blue that was classified as red) and 1 false negative (a red that was classified as blue).

Let's try a different set of data. What happens if we have 8 red and 2 blue balls? A different model might make the following prediction:

This time, all the balls were classified as red, and the accuracy was 80%. Better, right? Let's see what the confusion matrix says...

We can see that while the number of true positives is high, so is the number of false positives. Depending on the context, this could be a problem.
For example, let's say we are building a model to detect spam emails. If the model identifies everything as spam (lots of false positives), then we'll end up losing emails that aren't actually spam!
Equally, if the aim of our model is to screen people for a disease, we don't want anyone who has the disease to be missed by the model and test negative. In this situation, it would be better to have a lot of false positives and as few false negatives as possible.
This issue is especially important when we don't have an even balance of positives and negatives in our sample. In the disease screening example, only 2 out of 100 people may have a disease. If our model identifies everybody as negative, it will have an accuracy of 98%. But it's those two people who ***do***have the disease that we're really interested in, so really our model is 0% useful!
---
## An alternative approach
Let's introduce some alternative measures we can use to evaluate our model:

These equations come from looking at different parts of the confusion matrix:

If we **maximise** the **precision** of our model, we will **minimise** the **false positive** rate. This means we will **minimise the number of false alarms**.
If we **maximise** the **recall** of our model, we will **minimise** the **false negative** rate. This means we will **minimise the number of positives that go undetected**.
We can combine these measures together into one value: an ***F1 score.***
An ***F1 score*** is computed as the ***harmonic mean***of precision and recall. This ensures that the precision and recall values are as similar as possible, and therefore maximises both.

Substituting in the definitions of precision and recall, we get the following definition:

---
Let's visualise some of this:
We can maximise the precision of this model so that there are no False Positives. The data set is partitioned into points that are definitely positive (class 1) on one side, and any uncertain **or** negative (class zero) elements are on the other side. This is how we *could*tune a model for email spam detection, as we want to minimise the number of false alarms.

We can also maximise the recall of the model so that there are no False Negatives. This time, the data set is partitioned into those that are definitely negative and a mixture of positive and negative. This is how we could tune a model for detecting a disease, as it minimises the number of people with the disease who were missed by the test.

In reality, neither of these are appropriate for the situation. If an email spam filter removes some spam, but half of our inbox is still spam emails, it's not a very good filter. If a test for a disease can tell you you've tested negative, that's helpful, but if many of the people who test positive are actually negative, they could receive treatment they don't need.
A better solution for both situations would be to find a compromise between them. An F1 score will look halfway between these two and try to make precision and recall as balanced as possible.

---
An even better solution would be to introduce a bias so we can decide how to balance precision and recall. In practice, this could mean:
We allow a small chance that an important email ends up in spam if it means that our inbox is mostly spam-free
We allow a small chance that a disease test misses an infected person, if it means that a large number of healthy people don't receive unnecessary treatment
We introduce a new measure (the generalisation of an *F1* score) known as an Fβscore:

With β=1, we have the ***F1*** score as before. With β\\<1, we prioritise precision. With β>1, we prioritise recall. We can fine-tune to find the balance between them depending on the situation.


*LEFT:* *β* *\= 0.5, biased towards precision, RIGHT:* *β* *\= 1.3, biased towards recall*
This allows us to tune our model to classify points as correctly as possible for the given situation, while remaining within an allowable margin of error.
---
Accuracy might seem like a simple way to judge a model, but it rarely tells the whole story. Different types of errors matter in different ways, and ignoring that can lead to poor decisions. Looking at precision, recall, and Fβ-score gives a clearer picture of how a model actually performs.
Good model evaluation isn't just about numbers---it's about making sure the model works where it counts. By using the right mix of metrics and real-world considerations, we can build models that are actually useful.
### Mountains, Cliffs, and Caves: A Comprehensive Guide to Using Perlin Noise for Procedural Generation
URL: https://www.jdhwilkins.com/mountains-cliffs-and-caves-a-comprehensive-guide-to-using-perlin-noise-for-procedural-generation/
Last updated: 2026-06-09T08:46:02.000Z
***Procedural generation*** is everywhere---you've probably encountered it without even realising. It's what gives in-game worlds their rolling hills, jagged cliffs, and winding cave systems. And at the heart of it all is Perlin noise: a special kind of randomness that isn't entirely random at all. It's smooth where it needs to be, rough when we want it to be, and endlessly customizable.
But what exactly is ***procedural generation***? In simple terms, it's a method of creating natural-looking textures and objects using algorithms instead of manually designing every detail.
Take Minecraft as an example. Every time you load up a new world, you're presented with an entirely unique landscape. These worlds aren't designed by hand (think of the poor interns). Instead, they're built using procedural generation. Unlike traditional, handcrafted environments, procedural generation lets us create massive, complex landscapes on the fly---often with just a few lines of code.
In this guide, we'll break down how Perlin noise works, implement it from scratch, and tweak it to shape our terrain exactly the way we want. Keep reading till the end to see how we can take this idea even further to start designing underground cave systems.
All of the code for this project is available on GitHub. Feel free to try it out for yourself!
---
## Let's make some noise!

Believe it or not, this is the beginning of procedurally generated terrain. This is a graphical representation of noise -- an array of randomly generated values between 0 and 1\. There's no apparent pattern to it, and right now it doesn't look much like a terrain map at all. It's **random** and **discontinuous,** which isn't going to be much use for generating **smooth**terrain. What we really need is something more like this:

This is Perlin noise; it still looks pretty random and behaves unpredictably, but it has a smooth, continuous gradient that will make it much more useful for generating natural-looking terrain.
The colouring here simulates a top-down view of a topological map with snow-capped mountain peaks, green grasslands, and deep blue oceans. Perhaps it's easier to visualise in 3 dimensions:

It's not quite an epic mountain range yet, but it's a step in the right direction. So before we try to fix it up into something more mountain-y, let's explore how this smooth noise is created.
---
## Thanks, Ken!
In his 1985 paper (linked below), Ken Perlin describes his noise generation algorithm. He outlines some use cases for generating random natural textures for computer graphics.
There are various different implementations of this algorithm, but the core ideas are as follows...
Instead of starting with an array of random numbers, we'll begin with a coordinate grid of random vectors.

Perlin noise is generated on a per-pixel basis, so we'll take each pixel in our output and map it onto the vector grid.
Here we introduce our first parameter, **scale**, which allows us to modify the way pixels are mapped to the vector grid. As we will see later, this affects the overall smoothness of the terrain.

Depending on the size of the terrain and the size of our desired output, we may need to expand or tile the grid to ensure it's large enough to map all of our pixel coordinates.
---
Plotting one of the pixel coordinates on the vector grid, we can now work out a distance vector from the point to each of the bounding corners (shown in green below).

---
Taking the dot product of each gradient vector with its corresponding distance vector produces 4 numbers, one for each corner.
To calculate the final noise value for this pixel, we interpolate between the four corner values, first horizontally, then vertically. This ensures a point closer to one of the corner vectors is influenced by *it* more than the other vectors.
Once all noise values have been generated, the final step is to normalise the values to be in the range \[0, 1\]. This will give us the noise map as we saw before:

## Adding some lumps and bumps
Changing the **scale** parameter alters the **smoothness**of the terrain.
A larger scale value results in high-frequency waves, making the result look quite jagged
A smaller scale value results in lower frequency waves that have a smoother appearance
Scale is the mapping of pixel values to the vector grid. When the scale is smaller, we map lots of values to each square of the grid, which gives us a smooth curve. When the scale is larger, we sample the vector grid over larger intervals, so there can be more dramatic changes in the noise values.


---
## It's all coming together now
We can employ a technique known as **Fractal Brownian Motion** to increase the detail and complexity of the terrain. The method involves combining multiple layers of Perlin noise with different **frequencies** and **amplitudes**to create a more natural-looking result.
The layers of noise are known as **octaves**.
### Octaves
We can think about increasing the number of octaves by adding finer and finer levels of detail to our terrain. With one octave, we add broad shapes, with a second, we add slightly smaller features, but by the 6th or 8th octave, we are adding just small blemishes and details to the surface of the map.


We can also change the properties of the octaves and the way that we combine them using 2 more parameters: **persistence** and **lacunarity**.
---
### Persistence
**Persistence** alters the contribution of each octave to the final result. We start with an amplitude of 1 for our first octave, and with each iteration, multiply the amplitude by our persistence scale factor.
For example, if we have ***persistence=0.5***, we take 100% of the first octave, add the second one scaled down by 50%, then the next one scaled down to 25%, and so on. Each successive octave contributes less and less to the final result.
This coincides with the frequency of the octaves increasing so that we generate increasingly rough terrain, but it adds only small bumps to the surface rather than entirely new mountains.
Here we show an example of 2 octaves being combined with low versus high persistence.


The higher persistence model is impacted more by the higher frequency second octave, resulting in **large** jagged peaks sticking out of the ground.
By contrast, the lower persistence model has much smaller blemishes across the terrain as the impact of the second octave is smaller.
### Lacunarity
The other parameter we can alter is **lacunarity**. This refers to the rate of change of scale between the octaves.
In the examples below, we use 4 octaves and a persistence of 0.25\. The left model shows a lacunarity of 2.0, so the scale doubles with each octave, whereas the right model uses a value of 4.0, so the scale quadruples with each octave.


As we can see, the final results have the same overall shape, but the higher lacunarity model has a much higher frequency of the smaller features.
This parameter is more subtle than the others, but useful for altering the texture of the terrain.
---
## I think I'm getting carried away...
Beyond Fractal Brownian Motion, we can employ further adaptations to customise our terrain map...
### Moisture Levels and Biomes
We can use Perlin noise to represent things other than the height of the terrain. In this instance, we will use it to represent moisture levels in the environment. Combining the altitude and moisture levels, we can classify each coordinate into a different biome and then colour them accordingly.


### Radial Dropoff
We can also apply functions to our noise maps to manipulate the terrain into different shapes.
In this example, we apply a quadratic function to our noise values that drops off as the coordinates get further from the centre of the mountain. This results in a tall island mountain sticking out of the sea.

---
### Custom Functions
But we are not limited to a simple quadratic function. We can take a nice, complicated polynomial expression and apply it to our values.
The only thing to bear in mind is what the graph of the function looks like in the domain \[0, 1\]. We want to make sure that the function does not map our noise values to something outside of a reasonable range. This example below produces some interesting results, all while keeping the values within the range \[0, 1\].
We can then tailor this function to exaggerate and suppress different features of the landscape.
```
def f(x):
return 7.105427e-15 + 0.7*x + 16.20*(x**2) - 69.76*(x**3) + 94.76*(x**4) - 41.07*(x**5) - 4.3
```


## Cave Systems and Dungeons
We can also implement the Perlin noise algorithm in more than 2 dimensions, say for example... 3!
We can take a single octave of 3D noise, apply a threshold to the result and with a few tweaks and a bit of visualisation magic, the result is starting to look like an underground cave system:

With just a few clever applications of Perlin noise, we can create mountains, oceans, and even labyrinthine cave systems. By adjusting parameters like **scale** , **persistence** , and **lacunarity** , we gain fine control over the structure of our terrain, while layering multiple **octaves**adds depth and complexity.
And this is just the beginning. With further refinements---such as biome classification, moisture levels and the introduction of 3D models ---we can push procedural generation even further. Whether you're crafting a game world or experimenting with generative art, the power of noise is limited only by your imagination.
---
## References and Further Reading
[Ken Perlin's Original 1985 paper](https://www.scribd.com/document/809069705/An-Image-Synthesizer-Ken-Perlin-1985?ref=jdhwilkins.com)
[Fractal Brownian Motion](https://thebookofshaders.com/13/?ref=jdhwilkins.com)
[Super useful guide on Perlin Noise methods](https://adrianb.io/2014/08/09/perlinnoise.html?ref=jdhwilkins.com)
\*All images are by the author unless stated otherwise.
### From Love to Logic: How Algorithms Decide Our Matches
URL: https://www.jdhwilkins.com/from-love-to-logic-how-algorithms-decide-our-matches/
Last updated: 2026-06-09T08:45:37.000Z
## The Stable Matching Problem
> You've swiped through dozens of profiles, but why does it feel like there's no perfect match for you? What if there was another way where we could keep everyone happy?
## Welcome to the Stable Matching Problem
I think it's time to play Cupid! (But be warned: it's not all sunshine and rainbows; there are some tough decisions ahead)
The [Python script for this project](https://github.com/jdhwilkins/Gale-Shapley?ref=jdhwilkins.com)is available on GitHub
## Sadly, feelings aren't always mutual.
Clearly, we can't give everyone their first choice of partner -- at least not all the time. So the alternative we are left with is to give everyone their best possible option.
If we had everyone rank their potential partners in order of preference, then we could find some way to optimise our pairings to ensure everyone has a high a choice as possible from their list.
Thinking about it, we should probably find a way to stop people breaking up while we're at it, too. We don't want them messing up our perfect system --- that's a sure-fire way to make people miserable.
As it turns out, this problem has been well researched in mathematics. It's known as the **Stable Matching Problem**, and there just so happens to be a solution.
## Is it just me, or is this kinda shallow?
Let's assume we have 2 equal-sized groups --- men and women --- and that everyone has ranked all members of the opposite group in order of preference.
> A stable matching is a set of pairings of people such that no two people would rather be with each other than with their current partner.
While a stable matching doesn't guarantee everyone their first choice of partner, it does ensure maximum relationship stability.
In practice, this means no couple would ever separate; nobody would ever be cheated on; and 0% of marriages would end in divorce. (Though 100% would end in death).
Almost sounds too good to be true, right? Well, there's a catch! But we'll get into that in more detail a bit later on.
## So what is this magical solution?
The **Gale-Shapley Algorithm** was designed to solve such a problem.
It starts with groups of men and women of equal size (n). Everyone ranks their potential partners in order of preference. (Ties between 2 people are not allowed). The algorithm consists of a series of rounds. Each round involves a set of proposals from members of one group to the other --- we'll assume for now that it's men proposing to women.
In each round, every man who is not currently in a match proposes to his top choice of woman --- or at least his top choice among those he has not already proposed to. (There's no point getting rejected by the same person twice.)
After all unmatched men have proposed, the women then choose their favourite among the proposals they've received. They may also choose to remain with their current match if they prefer him over any new proposal. Each woman then *provisionally*accepts the chosen proposal (gotta keep your options open).
This cycle repeats. More proposals from unmatched men; more rejections from women; repeating until every woman has been proposed to at least once.
Only at this point does each woman accept their current match as final.
The result is a set of stable matches where nobody is able to further 'trade-up'.
## Time for some diagrams!
Let's take a set of preferences between 4 men (***a*** , ***b*** , ***c*** , ***d*** ) and 4 women (***A*** , ***B*** , ***C*** , ***D***). In each cell, we have 2 numbers: the first is how the man ranks the woman, and the second is how the woman ranks the man.

This means that ***a*** 's first choice is **A** , while **C** 's first choice is ***d***.
[https://github.com/jdhwilkins/Gale-Shapleybegins](https://github.com/jdhwilkins/Gale-Shapleybegins?ref=jdhwilkins.com) with all 4 men proposing to their first choice:
The
***a → A***
***b → A***
***c → B***
***d → D***

*(The diagram above shows proposals on the left and the resulting matchings on the right. The values indicate the rank of the other person.)*
The women then choose their favourite among their proposals. Since ***C*** did not get any proposals, she remains unmatched.
As the only unmatched man, ***b*** proposes next to his second choice, ***D***:

***D*** 's current match (***d*** ) is her 4th choice, hence, she chooses to 'trade up' and match with ***b*** instead. This leaves ***d*** without a partner.
***d*** proposes to ***B,*** and the proposal is accepted, leaving ***c*** without a match:

***c*** proposes to ***A,*** and the proposal is again accepted, leaving ***a*** without a match:

***a*** proposes to ***B*** , but the proposal is rejected, so ***a*** remains without a match:

Finally, ***a*** proposes to his third choice, ***C*** . ***C,*** provisionally accepts since he is better than no partner at all.

Since all women have now been proposed to, they should accept their current partners as final, resulting in a stable matching.
**Final Stable Matching:**
**a --- C,**
**b --- D,**
**c --- A,**
**d --- B**
## Python Implementation
Click here to see a full example of this algorithm in **Python**
```
import random
def gale_shapley(n):
"""
Perform the Gale-Shapley algorithm to find a stable matching for a population of size n
"""
# Generate random preferences for men and women
# Note that the following data structure should be interpreted in different ways:
M_preferences = [random.sample(range(n), n) for _ in range(n)] # Mpreferences[man][rank] = woman
W_ranks = [random.sample(range(n), n) for _ in range(n)] # Wpreferences[woman][man] = rank
# Index-value transpose on each sub-array
M_ranks = [[-1 for _ in range(n)] for __ in range(n)]
for i in range(n):
for j in range(n):
M_ranks[i][M_preferences[i][j]] = j
# Initially, all women are unmatched
deferred_acceptance = [-1] * n # deferred_acceptance[woman] = man | -1
# Track which women each man has proposed to
proposals = [[False] * n for _ in range(n)]
# Track iterations for visualisation
iteration = 0
# While not all women have been proposed to
while -1 in deferred_acceptance:
print(f"Iteration {iteration}:")
print(f"Unproposed to women: {deferred_acceptance.count(-1)}")
print(f"Current engagements: {[(f'M{m+1}', f'W{w+1}') for m, w in enumerate(deferred_acceptance) if w != -1]}\n")
for man in range(n):
if man in deferred_acceptance: # man currently has a match so probably shouldn't be proposing to anyone
continue
# identify which woman is the man's next top choice
for woman in M_preferences[man]:
if not proposals[man][woman]: # check if the man has already proposed to the woman
proposals[man][woman] = True
break
# 'woman' is now the man's top choice (of those he has not yet proposed to)
if deferred_acceptance[woman] == -1:
deferred_acceptance[woman] = man
elif W_ranks[man] > W_ranks[deferred_acceptance[woman]]: # new man is better than her current match
deferred_acceptance[woman] = man
iteration += 1
engagements = [[m, w] for m, w in enumerate(deferred_acceptance)]
return engagements, M_ranks, W_ranks
# main
n = 3 # Number of men and women
stable_matching, M_ranks, W_ranks = gale_shapley(n)
print(f"Final engagements: {[(f'M{_[0]}', f'W{_[1]}') for _ in stable_matching] }\n")
# Thanks ChatGPT for formatting the print output!
# Doesn't work too well for n>10
print("\nMen's ranks of women")
print(" " + " ".join([f"W{i}" for i in range(n)]))
for i, row in enumerate(M_ranks):
print(f"M{i} " + " ".join(map(str, row)))
print("\nWomen's ranks of men")
print(" " + " ".join([f"M{i}" for i in range(n)]))
for i, row in enumerate(W_ranks):
print(f"W{i} " + " ".join(map(str, row)))
```
Code Results
```
Iteration 0:
Unproposed to women: 3
Current engagements: []
Iteration 1:
Unproposed to women: 1
Current engagements: [('M1', 'W3'), ('M3', 'W1')]
Final engagements: [('M0', 'W2'), ('M1', 'W1'), ('M2', 'W0')]
Men's ranks of women
W0 W1 W2
M0 2 1 0
M1 2 1 0
M2 0 1 2
Women's ranks of men
M0 M1 M2
W0 1 0 2
W1 1 0 2
W2 1 2 0
```
## So these couples will never break up?
Let's convince ourselves that this solution is indeed a stable matching. As a reminder, we'll briefly revisit our definition:
> A stable matching is a set of pairings of people such that no two people would rather be with each other than with their current partner.
Now consider this...
Men propose in a top-down fashion. They start with their first choice, and if/when they get rejected, they move down to their next preferred choice.
Once the final matching has been established, any man wishing to improve his position will be unsuccessful since he has already been rejected by any woman he prefers.
Similarly, when the women chose their partners, they did so from a pool of proposals. Any man she prefers to her current match has not proposed to her already (or else she would have accepted him). Therefore, her preferred partners prefer their current match over her. Isn't life unfair?
Hence, we cannot find two people who prefer each other over their current partner --- the algorithm has found a stable matching!
## ... and here's the catch
But we're not done yet! It turns out that there can be multiple possible stable matchings for a given set of people! So which one have we found?

In this example, there are 3 different stable matchings that can be formed in the following ways:
Let the men (***a, b, c*** ) have their **first**choice
Let the women (***A, B, C*** ) have their **first**choice
Assign each individual their **second** choice.
I'll let you check to convince yourself that these do, in fact, all result in a stable matching. But which one does our algorithm find?
We'll need one last definition to tackle this question.
An ***optimal*** stable matching is one in which the proposing group achieve the **best possible result**. To be a little more precise,
> For each member of the proposing group, the result is at least as good as any other stable matching.
So, returning to our example, the first choice is optimal for men since it is at least as good of an option as any other stable matching for them. Similarly, the second option is optimal for women. The last option is not optimal for either group, as for both, there is a matching where they are all better off.
The problem is, none of these arrangements is particularly desirable:
Choosing either of the first two options is clearly unfair to one of the groups
The third option seems like the fairest choice, but would result in nobody being truly happy.
We're out of options --- or at least ethical ones. We could consider some strategic 'disposal' of certain key individuals that could alter the rankings and enable us to give more people a preferable choice...
... no, that would be wrong, we can't do that.
## No, you can't, there must be another way!
There is one last hope. If we run the algorithm twice, once with the men proposing and then again for the women, there is a chance we could get the same solution both times.
If this is the case, then we have found a single, unique solution to the problem. In this scenario, there is only one possible way to match our groups to create a stable solution.
We can rest easy, knowing it's the best they are going to get.
## Proof (for those interested)
Click here to see a proof of why this algorithm produces an optimal solution for the proposing group!
Pf. Let's begin by restating our argument that the solution is, in fact, stable:
Men propose with a 'top-down' approach, starting with their favourite and settling for their top choice who will accept them. Once a stable matching has been established, any woman looking to trade up would be rejected by any man she prefers over her current match. Similarly, any man looking to trade up has already been rejected by any woman he ranks higher than his current match. This makes the system stable as nobody can improve their position.
To see that it is also **optimal**for men, we make use of a simple proof by contradiction:
Assume that a man, M1, is rejected by a woman, W1, during some iteration of the algorithm, yet there is a stable matching where M1 and W1 can be paired together. If W1 rejects M1, then there must be some other man, M2, who has W1 as his remaining top choice. W1 must also prefer M2 to M1; otherwise, M1 would not have been rejected. So, returning to our matching with M1 and W1 together, we have a pair (M2, W1) who would rather be matched together than with their current partners, making the matching unstable. Hence, there is no better **stable** match for M1, making the result of the Gale-Shapley Algorithm optimal for those proposing.
## If they aren't happy, they can just lower their standards. Not my problem
There's only so much we can do. Sometimes there is no perfect solution, and this is unfortunately one such example.
Thankfully, the real world doesn't work quite like this. Instead, it's much more unfair and doesn't converge to a nice, stable state of mediocrity -- be that for better or for worse.
> N.B there are adaptations of this algorithm where the groups are of different sizes, or that allow people to have deal-breakers where they refuse to be partnered with certain people. We can also adapt this for same-sex couples, but unfortunately we can't guarantee a stable mathematical solution in that case.
The stable matching algorithm was originally used for a more general problem: matching college applicants to schools. In this version, we are matching many students to one school, instead of the one-to-one relationship we (usually) see in the dating world.
I'm not sure if this article has filled you with unfounded hope or a deep sense of dread at the dating purgatory that lies ahead. Nevertheless, I hope you enjoyed.
## References
- [Original Paper](https://www.eecs.harvard.edu/cs286r/courses/fall09/papers/galeshapley.pdf?ref=jdhwilkins.com)
\*All images are by the author unless stated otherwise
### The Impossible Bridges of Königsberg
URL: https://www.jdhwilkins.com/the-impossible-bridges-of-konigsberg/
Last updated: 2026-06-09T08:44:36.000Z
## 7 Bridges, 0 Solutions, and 1 Idea that Changed Mathematics Forever
> The sun dipped low over the bustling City of Königsberg, casting golden reflections over the Pregel River. Its waters divided the town into four distinct land masses, connected by seven foot-bridges that had become a curious point of both pride and frustration for its residents. By day, the bridges bustled with merchants and townsfolk, but as the evenings drew in, they became the source of a mysterious puzzle.*Could someone, starting from any point on land, cross each of the seven bridges exactly once and return to where they began?* It may sound simple, almost trivial, yet no matter how the townspeople tried, no one could find a solution.

As we can see above, the city comprises 4 distinct land masses, connected by 7 bridges. We aim to cross each bridge exactly once and return to our starting point. For the pedants out there, let's clarify the rules a little bit:
You can start on any of the sections of land you like, but you may not begin on a bridge,
You may not partly cross a bridge and turn around halfway
You may not use a bridge more than once
Swimming, sailing, or any other method of aquatic transportation is not allowed
In the 1700s, mathematician Leonard Euler famously proposed a proof as to why there is no solution to this puzzle. Before we get to it, let's introduce some simple concepts from Graph Theory that we'll use to help us.
Let's start with the basics. A graph is a network of nodes (points)connected with edges (lines).

We often name the nodes to make them easier to refer to (A, B, C, ... ). We can talk about an edge in the graph by giving the names of the 2 nodes that it connects (for example, we could refer to the edge from A to B).
We can use a graph to model many different situations and scenarios. For this puzzle, we can use nodes to represent our land masses and edges to represent the bridges connecting them.
This is what the city of Königsberg and its bridges would look like if we represented it as a graph:

It's this abstraction from reality that provides us with the tools to form an argument as to why there are no solutions to the puzzle.
There's one last definition we need before we can get started. The **degree**of a node is the number of edges connected to it. So, in the graph below, nodes A and C have degree 3, and nodes B and D have degree 2.

So how did Euler use these ideas to prove there are no solutions to the puzzle? Let's start with a simple example and work our way up.
In the graph below, all nodes have degree 2\. There's also clearly a route that uses every edge exactly once before returning to the start: A → B → C → D → A.

So what makes this graph different?
Whenever we arrive at a node, **there's always another edge we can use to leave it. The edges come in pairs**. This means that we always have a way back to where we started.
In other words, **every node has an even number of edges connecting to it** \- they all have even degree.
This condition is necessary for a solution to exist. If it isn't true, there can't be any solutions.
Let's take another look at the Königsberg graph.

Counting the degree of each node, we see that A=3, B=3, C=3, and D=5\. All vertices have odd degrees, so there can't be any solutions.
Let's introduce one more piece of mathematical terminology. A route through a graph that uses each edge exactly once before returning to the start node is known as an **Eulerian Circui**t. This is the type of route we've been searching for in this puzzle.
## Quick Recap
So far, we've established that:
> If any node has odd degree then it is not possible to find an Eulerian Circuit.
But what happens if we consider the inverse of that statement:
> If all nodes have even degree, does that mean that a solution definitely exists?
This is a slightly trickier problem to solve, but turns out the answer is **yes**\- If we only have even-degree nodes, then there must be an Eulerian circuit. We won't go into the details of that proof here, though.
There's one last problem left to consider: What's happened to the city of Königsberg since the 1700s?

Well, besides a change of name (now Kaliningrad), the city looks a little different today. If we look closely, we can see that the bridges have changed too. Zooming out a little, there are now 9 bridges, and their layout is different from before.

Let's see if today's city has a solution to the original problem!

There are 2 vertices with odd degrees and 2 vertices with even degrees, so sadly, there's still no solution.
## However...
What we've stumbled across here is a special case. While it's not possible to find an Eulerian Circuit, there is another "almost solution" we can find.
An **Eulerian Path** is a route through a graph that uses every edge exactly once but does **not necessarily return to the start**.
It turns out that when you have a graph with **exactly 2 odd-degree nodes,** there is an Eulerian Path that begins at one odd-degree node and ends at the other. In this case, there is a route using every edge starting at C and ending at D:

Finding one of these routes might seem much easier, but take another look at the original Königsberg puzzle again --- it's not possible to do! There will always be one bridge that you won't be able to reach.
It's also not possible to find a route like this if we **don't**start at an odd-degree node. Try it for yourself!
The Bridges of Königsberg may have seemed like a whimsical puzzle to the residents of its time, but it has had far wider implications for the study of mathematics since then.
Euler's solution to this problem is widely regarded as the birth of the field of graph theory, a very different mathematical discipline from the algebra and equations that came before it. Since then, it has led to the development of many different ideas both within and beyond the world of mathematics. The internet, map and navigation systems, and delivery networks all depend on ideas from Graph theory.
While the bridges may have changed, their legacy remains. It serves as a timeless reminder of how simple questions can lead to profound discoveries that reshape the way we understand the world.
All images used are by the author unless stated otherwise.
### Surviving the First Year of Your Math Degree
URL: https://www.jdhwilkins.com/surviving-the-first-year-of-your-math-degree/
Last updated: 2026-08-10T09:35:12.000Z
## Everything I Wish I'd Known Before Studying Mathematics at University
Luckily, studying for a degree in mathematics is very different from high school.
Math class didn't exactly get the best reputation in school --- and I can see why. It tells students to learn about seemingly pointless techniques and memorise different formulas that 99% of them will never use again... unless they go on to become math teachers.
Things change, however, when you decide to study maths at a higher level.
Mathematics becomes much more precise, and more transparent, and emphasises problem-solving over performing the same laborious calculations you've done hundreds of times before from a textbook.
It becomes a transferable skill that you can build and develop, and will serve you in many different areas of work. You also start studying more advanced concepts that are useful in engineering, economics, computer science, or pretty much any STEM subject.
But it's also a big adjustment, and if you don't know what you're getting in for, it can be quite a shock. So here's a list of things I wish I'd known before arriving at my first lecture.
## Language
The first thing you will notice when picking up a math textbook or paper is the language the author uses.
These books are filled with strange, complicated-looking symbols and long, complicated-sounding sentences that don't seem to get to the point and give way too much unnecessary detail. This is on purpose.
Studying mathematics is about precision. We need to be precise when we are talking about an idea so that we are absolutely clear about what we mean, and about what we don't mean.
The sentences may sound long-winded, but there are often a lot of clauses and clarifications to make sure we all have the same understanding.
If, for example, we wanted to choose a number between 1 and 10, a normal person might say something like:
"Choose a number between 1 and 10".
Is this simple and easy to understand for the average person? ...yes.
Is it mathematically precise? ...no.
Should we include 1 and 10 themselves? Should we include fractions? What about pi?
Can we choose that as our number?
A rigorous mathematical statement leaves no room for follow-up questions. Instead, a mathematician would say something like:
"Let n*∈* ℕ such that 1 ≤ n \\< 10"
Granted, if you don't understand the symbols, this may not be so easy to decipher, but once you get a handle on the notation, this statement is clear, precise, and only has one meaning. Let's break it down.
"*Letn* ∈*ℕ* " means that we choose a number from the set of natural numbers (the positive integers not including zero) and henceforth refer to this number as *n*. We choose this number so that it satisfies the following condition: "1 ≤ n \\< 10", so our number must be between 1 and 9 inclusive.
See how this is a much more long-winded way of phrasing it?
Mathematicians also enjoy naming things that they create, so rather than just choosing a number, they'll choose it and then give it a name (in this case, *n*) so that they can easily refer to it later on.
## **Notation**
Often in mathematics, we use letters to name objects that we create. For example, we might choose a number, *n* , or a sequence of numbers: *n* ₁*, n* ₂*, ..., n* ₖ. This indicates that we choose *k* numbers and refer to each of them by name. The subscript next to the *n* refers to the position in the sequence.
We might then choose an arbitrary element from this sequence that we would refer to as *nᵢ* , since *i* is just an arbitrary number.
We also make use of set notation.
A set is just an unordered collection of objects where there are no duplicates. We denote the list of elements of a set using { }. We can either list the elements explicitly:
{1, 2, 3, 4}
Use ellipses to indicate a range of values:
{1, 2, 3, ..., n-1, n}
Or we can use some expression to indicate what numbers go into our set:
S = {x*∈*ℤ | x² + 2x > 394}
(Here, we create a set and name it S)
To choose an arbitrary element from a set, or to indicate that an element belongs to a set, we use the symbol: ∈, which loosely translates to "in" or "element of". So *n* ∈*S* would indicate that we choose an element that is in *S*.
We also see the symbols: ⇒ and **⇔** . The single arrow, **⇒** , is used to mean 'implies'. So statement *A* implies statement *B* or *A⇒B* . This is the same as saying: If *A* is true, then *B* is true. (if ... then...).
You may also see this arrow written back to front:

to mean *B* implies *A or A* is implied by*B.* Sometimes it is easier to write this than to put *B⇒A.*
It's important to point out a subtlety here:
*A⇒B* means that if *A* is true then *B* is true.
This does not necessarily mean that since *B* is true, *A* must also be true. You cannot reverse the statement.
However, sometimes you will see **⇔** . This means that *A⇒B* and *B⇒A*.
So *A* implies *B* and *B* implies A.
In this case, we would say that statements A and B are ***equivalent***. One statement is true when the other is true, and only when the other is true. Both statements are either true or false. You cannot have one true and one false.
This is sometimes phrased as *A* is true if and only if *B*is true.
## Structure
Perhaps the most obvious difference between a high school and a degree-level math textbook is its structure. Most Textbooks and papers all follow the same format:
*Definitions → Theorem → Proof*
***Definitions*** define keywords and mathematical objects that we are then allowed to use. Most of the time, if we haven't defined something, it would be improper to start performing calculations with it. In a similar vein, we can't perform an operation on something if we aren't clear about exactly what that operation does and when it can be used. This goes for variables within a definition, too. It would be imprecise to say:
"p is a **prime**if its only factors are 1 and itself."
What is this *p* thing that we are calling a 'prime'*?* Where does it come from? What values are allowed to take? Is it even a number --- could it be a matrix, set, or function?
A much better definition would be:
Let p be a positive integer greater than 1\. We say that p is a **prime**if the only positive integers that divide it are 1 and p itself.
We now know where this *p* thing comes from, and what type of values it can take. If we're being pedantic, we should also really define what we mean by "**divides,**" but let's assume that's already been covered.
Again, this is all done for clarity; we need to make sure we all have precisely the same understanding of what we're talking about.
Once we have constructed a few definitions, we start looking at propositions and theorems. These are just mathematical facts about definitions we've just established.
- A ***theorem*** is a really important result that has consequences for many other ideas in mathematics. Think Pythagoras' Theorem.
- A ***proposition*** is similar except it's just less important. It will still have applications, it's just perhaps not as ground-breaking as a theorem.
A proposition or theorem that is claimed to be true is known as a ***conjecture***. It is only called a proposition or theorem once it has been proven to be correct.
A ***proof***is a mathematical argument. You need to be careful here and ensure that there is no error in each step of your argument. If you make a mistake, you could accidentally prove something that is not actually true.
Oftentimes, it will be clear if a statement is supposed to be true or not, so you probably won't start breaking the foundations of mathematics.
The more likely scenario is that you make an invalid step in a proof and draw some conclusion that you're not allowed to do. This won't completely invalidate your proof, but you'll probably get some feedback saying:
*"yes, but why?"*
Oftentimes, the answer you give will be correct, but your justification as to why it is correct is insufficient.
For a lot of proofs, the most difficult part is knowing where to start. Once you get going, things often fall nicely into place.
After we have proven a theorem, there may then be some other simple theorems that you can determine to be true as a direct consequence. This is known as a ***corollary***.
And that's pretty much it. This structure is just repeated over and over again. Define keywords and objects, claim that some facts about them are true, then prove that they are indeed true and that it isn't just some wild accusation. After that, we might go and do some calculations using the result of these theorems, or build a new method or algorithm for something.
As an example, we might start by playing around with different types of equations and notice a pattern with equations containing an x² term. We call these equations ***quadratics*** and give a formal definition so we know exactly what is and isn't part of this category of equations. Then we start trying to solve these equations and eventually come up with a formula that we think might give us a solution to any quadratic equation. This is exciting as it would make solving them much easier, but we still need to prove it.
We write it out precisely as a theorem so that we know what each part of the formula means and what type of equations we are attempting to solve with it. We then attempt to prove the theorem and find it to be true.
Next, we notice that the formula only gives nice solutions when one of the terms is zero or positive, so we write this fact out as a proposition and then prove it. We find this to be true as well.
With all of these definitions and theorems in place, we now start using the formula that we came up with to solve some of these equations.
Congratulations, you've just invented the quadratic formula!
---
This is what the study of mathematics is really about: we come up with some hypothesis, explore the idea, test it, prove it is right or wrong, and then apply it to solve some problem.
Throughout school, students only really focus on the last part of this: the 'doing something' part, but there's a whole other side of mathematics that most people never get to see.
The real skill of mathematics is in being precise and accurate with language; thinking critically and creatively to generate ideas for proofs; understanding complex and abstract ideas, and having the ability to construct a valid, logical argument.
That's why we study mathematics.
And you're in for a treat.
### Information at a Glance: Do Your Charts Suck?
URL: https://www.jdhwilkins.com/information-at-a-glance-do-your-charts-suck/
Last updated: 2026-06-09T08:45:13.000Z
## How pre-attentive processing, Gestalt theory, and visual data encoding inform data design decisions
> Let's face it: that report you worked on --- nobody's actually going to read it.
In the best-case scenario, people might skim through it, pausing briefly under the allure of a brightly-coloured diagram. But if you've designed your diagrams properly, a brief glance is all someone should need to understand what the data is saying --- at least at a high level.
The ability to quickly convey information is what sets an average graph apart from a great one. Let's take a look at some techniques from psychology that we can use to make our diagrams easier to interpret.
## Pre-attentive Features
Pre-attentive features are the design elements of a chart that can be perceived without directly paying attention to them.
They're features that immediately grab our attention when we first look at something.

Our eyes are naturally drawn to these features, making them quick to identify. As such, they can be useful for directing a viewer's attention to where we want it to go.
Consider this example --- how many 2s are in this grid of numbers?

How about now?

With the additional highlighting, it's much quicker to identify the twos. Instead of scanning line-by-line, our eyes quickly jump between the highlighted numbers.
---
By presenting our data clearly to show what's important, we can better express what we are trying to say. It allows us to be more concise yet more expressive.
For example, we can use colour to indicate the focus category in this bar chart. Sorting the bars by size helps make the chart easier to navigate too.

We can also use **bold text** and **boxes** to indicate what's **important** and what things are **related**to each other.

> N.B. The above infographic was generated using AI with very little guidance provided, yet still it demonstrates good principles about highlighting important information with bold text and clear sections --- even if the text and information is nonsensical.If ChatGPT can use these principles, then what excuse do we have!(Remarkably, ChatGPT was correct with the 99.86% of the solar system statistic, although it got it wrong above)
We should also remember that these features can be distracting if overused, as our attention is pulled in many different directions at once.
In the example below, it's difficult to know what order to read in, and it certainly isn't quick to identify the key takeaways.

## Visual Data Encoding
Data can be visually encoded in different ways. Representing figures with visual elements instead of a table of numbers makes it much more digestible.

However, different encoding techniques are better suited for different types of data.
---
## **Quantitative**
Quantitative data consists of measurements, which could include things like **height** , **weight** , or**number of likes on an article** (real subtle hint there).
For this type of data, **position, length, angle,** and **area**are all quite effective. Whereas, you would have a hard time showing anything meaningful using saturation, density, and shape to represent numerical values.


You can probably tell, looking at the pie chart, that yellow ( C ) is the largest category here. But what if we tried to find the second-highest? We'd probably have a hard time. On a bar chart, however, it's immediately obvious which order these categories rank in.
On the other hand, if we asked what proportion of the total is contained in category A, a pie chart, using area to encode the data, would be the better tool for the job.


> Data encoding methods are not created equal --- if you don't choose the right one, the data won't tell the story you had intended
Position is a really effective tool for encoding lots of different types of data. Take a look at this scatter plot...

We can see a trend within the data points.
A second method of data encoding (in this case, slope) can be used to reinforce this, making the trend more immediately clear, and to indicate that it is the key takeaway from the chart.

---
## Nominal Data
Nominal data refers to named data points. This is most commonly found as labels on charts.
Choosing the right method will determine how easily a reader can understand the relationship between category and label.
Two common methods are **connection** and **hue:**


Connection can sometimes be clearer for a reader to understand which category is which, but it can make the diagram quite cluttered when overused.
On the other hand, hue is a powerful tool if you have multiple charts that can make use of the same colour scheme. As the reader progresses through, they develop an intuition of which category is which, just based on the colour.
## Ordinal Data
Ordinal data consists of categorical data with a natural order or rank. Here, **position,** **saturation** , and **hue**will be the most effective tools to encode the data.
That said, a pie or bar chart can still be an effective tool for this type of data; we should just incorporate some other encoding method to aid understanding.
Using just shape, area, or volume to represent the data will make it difficult to interpret.
Let's visualise this data set:


Hopefully, by now, we can see why this is not a helpful visualisation.


This world map uses a combination of **position** (country location) and **hue** to quickly show how countries compare. If we want to see more information about a country, we can hover over it.
This does involve us limiting our visualisation to only one column of the data (sales). If we still wanted to show both, we could do something like this:

Here we use **hue** to encode sales, **position** for country, and **size** for customer satisfaction rating. Perhaps the size scale is a little misleading, as the small dot over South Africa represents a 3.8/5, but with some minor tweaks, we have a chart that manages to provide an intuitive understanding of a complex data set.
---
## **Gestalt Theory**
Gestalt Theory describes how visual elements are interpreted and understood by the human brain and how relationships between elements are inferred.
We won't go into the history or background of it here, but if you're interested, maybe check out [***this***](https://www.interaction-design.org/literature/topics/gestalt-principles?srsltid=AfmBOorm-bgFD3tMiCfPRe7lOLvzYdkJQUClHMAjEYTqcE4rr94mzD2Y&ref=jdhwilkins.com#1.%5Femergence-3)article (unaffiliated).
Gestalt Theory can be summarised by a list of principles. Let's take a look at some examples:

### Principle #1\. Figure and Ground
As a rule, bold, high-saturation, and dark colours are interpreted as foreground (figure), whereas light, less-saturated features are seen as the background (ground).
This is obvious in the above example; we can tell we're not looking at a white piece of paper with a ring-shaped cut-out. The dark region is clearly on top of the white one --- at least so it appears.
We can use this when designing a chart if there is one group we want to compare to the rest of the population

The bold, blue colour stands out and draws attention when compared to the subtle grey bars representing the wider population.
This principle is also present in the gridlines that appear in the background of the chart.
Let's revisit the Olympic rings for principle 2...
### Principle #2\. Pragnanz (Simplicity)


In the above example, we interpret the image as 5 interlocking rings.
We could also interpret this logo as a series of squiggly line segments, or even one big looping curvy line.

Principle #2 states that we seek the simplest interpretation of what's presented to us --- in this case, rings.
So how can we use this to help us design better charts?
> Keep it simple.
Whatever you put in front of a reader, they will probably take it at face value.
There's no bonus points in trying to be clever --- it'll probably just make it needlessly complicated.
The message we want to convey should be the most easily accessible one, and we
want to stick to chart types that a reader is familiar with.
---
### Principle #3\. Proximity
The principle of proximity states that objects that are close to each other are perceived as being related or having something in common.
A great example of this is a scatter plot. The human brain is great at identifying clusters and groupings.


For data design, this means we should:
Arrange titles and headings near their respective charts,
Use clusters of related bars on a bar chart,
Use negative space to emphasise the close proximity of other elements.
### Principle #4\. Common Region
Principle #4\. states that objects that are enclosed in the same region are seen as being related to each other.
This is the principle that a Venn diagram relies on:

Principles #3 and #4 together are helpful tools for designing the layout of charts and structuring an infographic.

We can use bounding boxes, headings, negative space, and place related things near each other to make our report much easier to navigate.
---
### Principle #5\. Similarity
The principle of similarity states that objects that share some property or appear visually similar are perceived as being related.
For data design, this has a few consequences:
Consistent colour coding to tie categories together,
Consistent layout between different pages --- the same components should be in the same place so the reader knows where to find them,
Consistent use of shapes, line styles, or markers in charts and diagrams to represent the same type of data or category.
This principle also informs the types of charts we should choose to use in the first place:
The **same kind of chart** should always be used to display the **same type of data** throughout.
Use charts that are **similar to existing ones** that the reader has **likely seen before**.
These guidelines improve the chances of a user understanding how your diagrams work.
## Conclusion
Designing an effective data presentation isn't just about aesthetics --- clarity and understanding are crucial to success.
With the techniques we've discussed, we can design visualisations that convey insights instantly and effortlessly. Every choice matters when it comes to helping a reader focus on what's important and making the data's story accessible to all.
\*Unless otherwise stated, all images are by the author.
\*AI was used to generate some datasets and graphics for this article.
### Turing’s Turochamp: The Birth of AI in Games
URL: https://www.jdhwilkins.com/turing-s-turochamp-the-birth-of-ai-in-games/
Last updated: 2026-06-09T08:43:54.000Z
## An Exploration of Alan Turing's Chess Program
Alan Turing, a pioneering figure in the world of Computer Science, is often celebrated for his work on breaking the [Enigma](https://en.wikipedia.org/wiki/Enigma%5Fmachine?ref=jdhwilkins.com)code during World War II. However, one of his lesser-known achievements is creating one of the first chess algorithms --- a small yet significant early step in the development of artificial intelligence systems.

AI is a difficult concept to fully and accurately define. There are complicated rule-based systems where a set of conditions maps inputs to outputs; there are machine learning systems where the mapping between inputs and outputs is inferred; and there are Deep Learning systems where the exact weightings of inputs don't even need to be specified.
It isn't easy to know where to draw the line between AI and traditional programming techniques. However, simple algorithms and rule-based systems, like those designed by Turing, were a stepping stone to creating more complex systems that definitely fall under the AI category.
## What was Turing's Chess Program?
In the 1950s, computers were still in their infancy. Turing had a vision of a machine that could "think" strategically. He defined a series of goals that a chess program should accomplish:
At the simplest level, a chess program should be able to "*obey the rules of chess*" and generate valid, legal moves for a given chess position.
Next, a chess program should be able to "*solve chess problems.*" It should demonstrate some intelligence and awareness of the game's objectives.
Increasing the level of complexity slightly, a chess program should be able to "*play a reasonably good game of chess,*" or at least be able to put up a good fight against an average player, and generate logical and reasonable moves in any situation.
Lastly, and perhaps the most challenging of these targets, is for a chess program to be able to adapt and improve with each game it plays, "*profiting from past experience.*"
The first of these challenges, calculating legal moves, is relatively straightforward to perform, particularly with a modern computer and a high-level programming language.
Learning from experiences is the focus of many modern AI systems, and is far beyond the capabilities of computers in the 50s.
This just leaves the problem of identifying 'good' moves from the set of possible ones, and this was the focus of Turing's algorithm.
In 1948, without access to a computer powerful enough to run his idea, Turing, along with colleague [David Champernowne](https://en.wikipedia.org/wiki/D.%5FG.%5FChampernowne?ref=jdhwilkins.com), devised a chess algorithm that could be performed by hand. This algorithm was known as "**Turochamp**" and defined a set of rules that mimicked the decision-making process of a human player.
## How did it evaluate the board?
The exact set of rules was outlined in Turing's 1953 paper¹. You can find it linked and summarised below. The algorithm proceeds as follows:
*We start by calculating a total piece-material score for the player we are considering. Different pieces are worth a different number of points...*
*"Turochamp"*
*Turing (and Champernowne) used the following piece values: pawn=1, knight=3, bishop=3½, rook=5, queen=10\. In addition, they had the following positional evaluation functions:*
***Mobility.*** *For the Q, R, B, N, add the square root of the number of moves the piece can make; count each capture as two moves.*
***Piece safety.*** *For the R, B, and* N, add 1.0 point*s if it is defended, and 1.5 points if it is defended at least twice.*
***King mobility.*** *For the K, the same as (1) except for castling moves.*
***King safety.*** *For the K, deduct points for its vulnerability as follows: assume that a Queen of the same colour is on the King's square; calculate its mobility, and then subtract this value from the score.*
***Castling.*** *Add 1.0 point for the possibility of still being able to castle on a later move if a King or Rook move is being considered; add another point if castling can take place on the next move; finally, add one more point for actually castling.*
***Pawn credit.*** *Add 0.2 points for each rank advanced, and 0.3 points for being defended by a non-Pawn.*
***Mates and checks.*** *Add 1.0 point for the threat of mate and 0.5 point for a check.*
↑*(* [*https://en.chessbase.com/post/reconstructing-turing-s-paper-machine*](https://en.chessbase.com/post/reconstructing-turing-s-paper-machine?ref=jdhwilkins.com)*)*
## Recreation of Turing's Algorithm
Sadly, Turing never lived to see his algorithm run on a machine. The project was largely forgotten about, but almost 60 years later, [Chessbase](https://en.chessbase.com/?ref=jdhwilkins.com)decided to finish what it had started and create a full, working implementation of Turing's method.
You can see a live demo of the former World Champion, Gary Kasparov, playing against the engine they created, [here](https://cdn.embedly.com/widgets/media.html?src=https%3A%2F%2Fwww.youtube.com%2Fembed%2FwrxdWkjmhKg%3Ffeature%3Doembed&display%5Fname=YouTube&url=https%3A%2F%2Fwww.youtube.com%2Fwatch%3Fv%3DwrxdWkjmhKg&image=https%3A%2F%2Fi.ytimg.com%2Fvi%2FwrxdWkjmhKg%2Fhqdefault.jpg&key=a19fcc184b9711e1b4764040d3dc5c07&type=text%2Fhtml&schema=youtube&ref=jdhwilkins.com) .
## Consequences of Turing's Work
The creation of Turochamp was a foundational moment in both the history of AI and chess programming. Although it never played a physical game during its inception in the 1940s, Turochamp showcased early ideas about how machines could simulate human thought processes in complex decision-making environments, as can be found in a game of chess.
Fast-forward to today, and AI in chess has progressed to unimaginable heights. The shift from simple rules-based engines like Turochamp to modern systems, such as AlphaZero, illustrates a profound evolution.
Chess engines like Stockfish and AlphaZero now dominate the chess landscape, with [Elo ratings](https://en.wikipedia.org/wiki/Elo%5Frating%5Fsystem?ref=jdhwilkins.com)above 3500, far exceeding the amateur performance of Turochamp.
The consequences of this evolution in chess programming are clear --- computers not only outthink human players but also contribute to the improvement of human strategies by uncovering moves and ideas that were previously unknown.
Turochamp may be outdated by today's standards, but its legacy lives on in the modern AI systems that have become a part of our everyday lives, cementing its place in the AI Hall of Fame.
## Building a Chess Engine Using Python
If you're interested in how more modern chess engines work---and some of the other components we require to search through and consider different possible moves---then feel free to check out my series where I document the process of building a chess engine using Python!
You can find part 1 of that series [here](https://jdhwilkins.com/1-hot-encoding-the-chess-programmers-secret-weapon/?ref=jdhwilkins.com)
## References and Reading
¹ Alan Turing (1953). "Chess." Chapter 25, part of the collection "Digital Computers Applied to Games." In Bertram Vivian Bowden (editor), "[Faster Than Thought, a symposium on digital computing machines](https://archive.org/details/fasterthanthough00bvbo/page/n21/mode/2up)", reprinted 1988 in Computer Chess Compendium, reprinted 2004 in Chapter 16 of Alan Turing, B. Jack Copeland (editor) (2004). [The Essential Turing, Seminal Writings in Computing, Logic, Philosophy, Artificial Intelligence, and Artificial Life, plus The Secrets of Enigma](https://academic.oup.com/book/42030/chapter-abstract/355747594?redirectedFrom=fulltext&ref=jdhwilkins.com). Oxford University Press.
Reconstructing Turing's "Paper Machine": [en.chessbase.com](https://en.chessbase.com/post/reconstructing-turing-s-paper-machine?source=post%5Fpage-----4188e10d94a0--------------------------------)
Paper: [easychair.org](https://easychair.org/publications/preprint/WjKW?source=post%5Fpage-----4188e10d94a0--------------------------------)
Thanks for reading 🙂
### The Hunt For Prime Numbers
URL: https://www.jdhwilkins.com/the-hunt-for-prime-numbers/
Last updated: 2026-06-09T08:43:20.000Z
## A Journey Through Their Mysteries and Mathematical Shortcuts
Prime numbers are among the most intriguing puzzles in mathematics --- seemingly random yet deeply significant.
Their elusive pattern defies easy detection, making them both a source of fascination and frustration. The challenge grows exponentially with larger numbers, where determining if a number is prime becomes immensely time-consuming.
However, some clever shortcuts can speed up the search and help us swiftly eliminate impostors.
Before we can uncover the hidden mysteries behind prime numbers, we must first face the challenge of finding them...
## Prime Numbers
We'll start with a definition:
A prime number is a number with no factors except 1 and itself. Let's clarify that a little:
We're only concerned with positive integer numbers (so 3.5 and -4.19 can't be primes)
We're also only looking for positive integer factors
It's important to note that 1 is not a prime. There are many reasons for this, but we won't get into that today.
If a number is not prime, we say that it is **composite.**
Under this definition, 2, 3, 5, 7, 11, ... are all primes, and all the even integers except 2 are composite (since they have a factor of 2).
With this in mind, let's see if we can find some primes.
---
## Checking Primality
A simple way to check if a number is prime would be to check every number smaller than it to see if it nicely divides our number. (Again, we're just concerned with the positive integer factors here).
**Is 53 Prime?**
53 / 2 = 26.5,
53 / 3 = 17.6666...,
53 / 4 = 13.25,
...
Trying this out, it quickly becomes apparent that this will take a *very*long time, especially if we want to check a particularly large number.
So what can we do to optimise this process? Well, there are 2 easy simplifications we can make.
Since factors come in pairs, there will always be one factor bigger than and one smaller than the square root of the number. Given that we only need to find 1 factor to prove that a number is not prime, we only need to check values up to the square root.
If there is a factor higher than the square root, we will have already found its counterpart below.
The second optimisation we can make comes as a result of **the Fundamental Theorem of Arithmetic**.
This theorem states that:
> "Every positive integer greater than 2 can be written as a product of prime factors."
What this tells us is that every number is either prime or can be expressed as a product of prime factors.
Therefore, we only need to check the known prime numbers to see if any of **those** are factors of our number.
(Any other composite factor would have a prime factor, which we've just checked for).
Putting these ideas together, it is sufficient to check only the prime numbers up to the square root when we are looking for factors.
So if we want to check if any number up to 10,000 is prime, we only need to check the prime numbers up to sqrt(10,000) = 100, of which there are only 25.
**Example: Is 541 Prime?**
sqrt(541) = 23.26
So we check the following primes for factors:
2, 3, 5, 7, 11, 13, 17, 19, 23
By observation, we can eliminate 2 and 5\. A quick check of the remaining numbers tells us that 541 **is** indeed prime.
**Non-Example: Is 493 Prime?**
Similarly to before, we start by finding the square root,
sqrt(493) = 22.2
So the primes we need to check are:
2, 3, 5, 7, 11, 13, 17, 19
Again, we can eliminate 2 and 5 quite quickly, and a quick check shows that 17 is a factor:
493 = 17 \* 29
So 493 is **not** a prime number.
(Notice that one factor is smaller than the square root, and one factor is larger.)
Well, that's certainly a lot easier than checking every single number!
---
## Building New Primes
Sometimes mathematicians will need a huge prime number.
Checking for prime factors, even using a computer, could take a very long time. It also relies on us knowing **all** of the primes up to the square root. If we don't have a complete list of primes, we might have missed a factor!
While it's relatively easy to see if a number is prime, it's much more challenging to find a list of all primes (up to a specific number).
But let's say we do have a complete list of primes, where we know that we have not missed any primes in between. How can we construct a new prime using this list?
Let's introduce some notation:
Let p1, p2, ..., pn be a complete list of primes. Then we will construct a new number, q, as:
*q = (p1 \* p2 \* ... \* pn ) + 1*
(A product of all existing primes, plus one.) So how does this help us find a new prime?
Well, there are 2 cases. Either:
q is prime and is not in our list of existing primes, so we have found a new one, or
q is composite. In this case, q does not have any prime factors (from our existing list of primes) since if you divide it by any of p1, ..., pn, then you will always get a remainder of 1\. But since it is composite, it must have a prime factor, so there must be a new prime that is not on our list (we just don't know what it is yet).
This method doesn't guarantee we can explicitly know the new prime, but we do at least know that it's there. We've at least narrowed down our search!
Let's look at an example to illustrate this method:
Take a complete list of the first 3 primes: 2, 3, 5...
... multiply them together ...
... and add 1,
\= 31, which is indeed a prime.
It's important to note that we also can't find **every**prime using this method --- we may have found 31, but we've missed 11, 13, 17, ...
> *\[Note. This idea can be used to prove that there is an infinite number of primes since we can always construct a new one by taking a product of existing ones. This exercise is a great introduction to proof by contradiction\].*
---
## Mersenne Numbers
A **Mersenne Number**is of the form 2ⁿ-1\. The first 5 Mersenne numbers are:
```
2¹–1 = 1,
2²–1 = 3,
2³–1–7,
2⁴–1 = 15,
2⁵–1 = 31
```
A Mersenne Number that is also a prime is known as a **Mersenne Prime**. The first 3 Mersenne primes are 3, 7, 31.
You'll notice that these numbers have a power of 2 that is also prime:
```
2²–1 = 3, and 2 is a prime
2³–1 = 7, and 3 is a prime
2⁵–1 = 31 and 5 is a prime
```
This is a requirement for any Mersenne Prime: the exponent of the power of 2 **must** be a prime. However, the converse is not **always** true! It is not always the case that if the power is prime, then we have a Mersenne Prime.
> Prime numbers have some interesting and unusual applications. Learn more at the link below:[What if an Infinite Number of Spaceships Arrive at Hilbert's Hotel?](https://what-if-an-infinite-number-of-spaceships-arrive-at-hilbert-s-hotel/?ref=jdhwilkins.com)
## The Lucas-Lehmer Test
There is another way to check if a number is prime. It can only be used in a very specific case: checking if a Mersenne Number is a Mersenne Prime.
The following test for primality is known as the **Lucas-Lehmer** test.
Let's take a Mersenne Number, m. We'll assume that m is of the form
m = 2ᵖ-1
where p is a prime. So this is a potential prime number.
The test involves generating a sequence. We start with a₀ = 4, and recursively define:
aₙ = aₙ₋₁² -2 (mod m)
> \[Note. The notation, "mod m" used here tells us that we need to divide the result by m and take the remainder as our answer.\]
We define this sequence up until aₚ₋₂.
If aₚ₋₂= 0, then m is ***prime***,
Otherwise, m is ***composite***.
**Example: Is 8191 Prime?**
```
2¹³ -1= 8191
a₀ = 4
a₁=14
a₂ = 194
a₃ = 37,634 = 4870
a₄ = 23,716,898 = 3953
a₅ = 5970
a₆ = 1857
a₇ = 36
a₈ = 1294
a₉ = 3470
a₁₀ = 128
a₁₁ = 0
```
Since this last term is zero, we know that 2¹³-1 **is** a Mersenne Prime.
**Non-Example: Is 2¹¹-1 = 2047 Prime?**
```
a₀ = 4
a₁=14
a₂ = 194
a₃ = 37634 = 788
a₄ = 620942 = 701
a₅ = 119
a₆ = 1877
a₇ = 240
a₈ = 282
a ₉= 1736
```
Since this last term is non-zero, we do **not** have a Mersenne prime.
---
Admittedly, for a large Mersenne Number, this process may still take a while, but it's definitely still faster than checking possible factors.
Fortunately, in the case of Mersenne Primes, there are only 51 that we know to exist, so in fact, a quick Google search may be a faster method still!
The largest known Mersenne Prime at the time of writing is 2\\^(82,589,933) − 1, which, of course, means that 82,589,933 is a prime.
So there you have it: while prime numbers remain a mystery yet to be unravelled, finding and constructing them has hopefully just become a little easier!
### Flowers, Staircases, and The Golden Ratio
URL: https://www.jdhwilkins.com/flowers-staircases-and-the-golden-ratio/
Last updated: 2026-06-09T08:42:52.000Z
## An Unusual Counting Problem
> Have you ever climbed a staircase that just didn't seem to be made for human legs?
The steps are too small to comfortably take one at a time, but too large for an easy double-stair.
You either end up shuffling along with baby steps or stretching so far that it feels like you're trying out for the gymnastics team.
In situations like these, you might start to wonder (or maybe it's just me?): how many different ways could you actually climb this staircase, taking just one or two stairs at a time?
Suppose there are just 10 steps in our staircase.
We could climb the steps in the following sequence of moves:
```
1 1 1 1 1 1 1 1 1 1,
2 1 1 1 1 1 1 1 1,
1 2 1 1 1 1 1 1 1,
1 1 2 1 1 1 1 1 1,
1 1 1 2 1 1 1 1 1,
1 1 1 1 2 1 1 1 1,
⋮
1 1 2 2 2 2,
2 2 2 2 2,
```
There's clearly going to be a lot of options to count, so maybe listing them all out isn't the best idea.
---
Let's try a different approach.
We can denote the number of ways to climb exactly n stairs as xₙ.
When we reach the nth stair, our previous move must have been either of size 1 or size 2\. Therefore, we must have just been on step n-1 or n-2
There's only 1 way to get from step n-1 to step n in one go, and similarly, there's only 1 way to get from step n-2 to step n in one go.
Therefore, the number of ways to reach step n is the same as the number of ways to reach step n-1 plus the number of ways to reach step n-2\. This gives us the recurrence relation
xₙ = xₙ₋₁ + xₙ₋₂
...where xₙ₋₁ and xₙ₋₂ are the number of ways we could have reached steps n-1 and n-2, respectively.
We can repeat this argument even further. If we were on step n-1, then, one move before that, we must have been on either step n-2 or n-3.
Therefore, the number of ways we can reach the nth stair can be defined recursively. This means that we calculate it in terms of the number of ways we can reach the steps before it.
Let's take a look at some simple cases and build our way up.
- For n=0, there's exactly 1 way to climb zero stairs, that is, by doing nothing at all.
- For n=1, there is obviously only one way that we can reach the first stair.
- For n=2, there are 2 ways we can reach it: either two moves of size 1, or one move of size 2.
```
x₀ = 1
x₁ = 1
x₂ = 2
```
Using the recurrence relation we defined above, we have the following:
```
x₃ = x₁ + x₂ = 1 + 2 = 3
x₄ = x₂ + x₃ = 2 + 3 = 5
x₅ = 3 + 5 = 8
x₆ = 5 + 8 = 13
x₇ = 8 + 13 = 21
x₈ = 13 + 21 = 34
x₉ = 21 + 34 = 55
x₁₀ = 34 + 55 = 89
```
Hence, there are 89 different ways we can reach the 10th stair, climbing either one or two steps at a time.
```
1, 1, 2, 3, 5, 8, 13, 21, 34, 55, 89, 144, 233, …
```
This sequence may look familiar; it's one of the most famous sequences in mathematics, and it's known as the **Fibonacci sequence.**
It has many applications, such as in computer science, architecture, and design, and is even used by traders to make predictions about the stock market. The Fibonacci sequence also pops up in many unexpected places in nature.
For example, many flowers have a ***Fibonacci Number*** of petals (a number that appears in the Fibonacci sequence).
Buttercups have 5 petals
Marigolds have 13 petals
Daisies often have 34 or 55 petals
The head of a sunflower has seeds in a spiral shape. If you count the number of arms in those spirals, you will find a Fibonacci number. It doesn't matter if you count them going clockwise or anticlockwise; in fact, they will both work and give you two *different* Fibonacci numbers!
> *\*Disclaimer. To avoid disappointing anyone who just ventured out to the garden to start counting flowers, please be warned that the exact number of petals may vary, and many selectively bred plants may have a different number of petals. Or one could just have fallen off.*
## The Golden Ratio
The ratio of pairs of consecutive terms in the sequence approaches a value known as the ***Golden Ratio*** . This is often represented using the Greek letter ***Phi***, φ.
```
3/2 = 1.5
5/3 = 1.667
8/5 = 1.6
13/8 = 1.625
21/13 = 1.615
34/21 = 1.619
φ ≈ 1.618033988
```
Phi is an irrational number, and has an exact value given by:

We can use this value to give us a shortcut to solving the staircase problem.
The number of ways to get to the nth stair is given by **Binet's Formula:**

It may look a little complicated, but a calculator can easily do the heavy lifting here.
It's worth pointing out that the Fibonacci sequence starts with the first term, **F₀ = 0**
```
0, 1, 1, 2, 3, 5, 8, 13, 21, 34, 55, 89, 144, 233, …
```
whereas our sequence begins with the first term **x₀ = 1**
```
1, 1, 2, 3, 5, 8, 13, 21, 34, 55, 89, 144, 233, …
```
Meaning that our solution sequence is offset by 1\. Therefore, for this situation, we actually require **F₁₁**to give us the number of ways to reach the 10th stair.
> *\*We could extend our sequence by saying that there are zero ways to climb -1 stairs since it's not possible to have -1 stairs (at least as far as I know).We could then neatly shift each element along one position so everything matches up.*
---
Let's see if we get the same answer as before:

Amazingly, when we substitute n=11 into this formula, it spits out a nice round number, exactly the same as we worked out before.
Using this formula, it's easy to work out a solution for any number of steps.
If we increase the size of the problem to 100 stairs (again doing either 1 or two steps at a time), then there are exactly ***573147844013817084101*** combinations of ways we can walk up them.
With 1000 steps, the number of combinations becomes astronomical:
```
70330367711422815821835254877183549770181269836358732742604905087154537118196933579742249494562611733487750449241765991088186363265450223647106012053374121273867339111198139373125598767690091902245245323403501
```
That's a lot of walking up and down stairs!
### What if an Infinite Number of Spaceships Arrive at Hilbert’s Hotel?
URL: https://www.jdhwilkins.com/what-if-an-infinite-number-of-spaceships-arrive-at-hilbert-s-hotel/
Last updated: 2026-06-09T08:42:21.000Z
## A Variation of the Classic Thought Experiment
Suppose you've just been hired as the new manager of Hilbert's Infinite Hotel.
On your first day, you arrive at work only to be greeted by an infinitely long line of people in the lobby, each expecting a room.
The Problem? All of the infinite number of rooms are already occupied by an infinite number of guests. The Infinite Hotel is full.
Turning them all away is out of the question - you'd get an infinite number of complaints, and that would take literally forever to deal with.
You also can't ask the current guests to leave to make room for the new ones as then you'd get an infinite number of 1-star reviews, and that would probably bring the average rating down a little.
To make matters worse, somehow this hotel with an infinite number of rooms only has 3 storage cupboards (!?), so you couldn't even put the guests in there as you'd run out of space pretty quickly. (Plus, then where would you keep the infinite number of bedsheets?)
With your job on the line, the stakes have never been higher. How can you make space when there's no space left? You decide it's time to think outside the box.
Welcome to the paradox of the Infinite Hotel.
> \*Note: This thought experiment was originally posed by German Mathematician, David Hilbert. It has been adapted and retold many times since.
---
Let's suppose all the rooms are numbered 1, 2, 3, ...
If we asked every guest to move from their current room, n, to room n+1 then all of the guests still have a room, and room 1 becomes free. So the guest at the front of the queue will be able to take room 1.
Unfortunately, there's still an infinite number of guests left. If we repeat this process one room at a time, we will be here forever. By which time, another infinite number of guests will have arrived.
Instead, what if we ask everyone to move from room n to room 2n? The guest in room 1 goes to room 2, room 2 to room 4, room 3 to room 6, all the way to infinity.
This will mean all of the even-numbered rooms are occupied, and all of the odd-numbered rooms are vacant. And of course, there is an infinite number of odd-numbered rooms.
Perfect! We're now able to allocate this infinite queue of guests to their own rooms.
## But we're not done yet.
Just when you think it's all over, an infinite number of buses pull into the infinite car park. There are, of course, enough spaces for them.
Each bus contains another infinite number of guests.
We need a new mathematical weapon to tackle this one... the Fundamental Theorem of Arithmetic!
---
## The Fundamental Theorem of Arithmetic:
> Every positive integer (except 1) can be expressed uniquely as a product of prime factors.
This means that there is only 1 way to represent the number 36 as a product of prime numbers:
36 = 2² \* 3²
Even if we change the order (36 = 3² \* 2² or even 36 = 3 \* 2 \* 3 \* 2), the factors are still the same.
> Every number has a unique set of prime factors that multiply to produce it.Every distinct set of prime factors will multiply to produce a unique value.
Luckily, each of the buses has a number on the front (1, 2, 3, ...).
We first ask each of the existing guests to move from room n to room 2\\^n. For some guests, it may involve a lot of stairs, but in theory, they will all end up with their own room again. And since it's a power of 2, this new room will have an even room number.
Now that we've made some space, let's tackle the coaches outside. We can ask each of the passengers to work out their coach number (i) and their seat number on that coach (j). We then instruct them all to do the following:
find the (i+1)th prime number, pᵢ ∈ {2, 3, 5, 7, 11, 13, 17, 19, ... }
raise it to the power of j ∈ {1, 2, 3, 4, 5, ... }
room number = pᵢ ʲ
For example, the passenger in coach 1, seat 2, takes the 2nd prime number and raises it to the power of 2
3² = room 9
The passenger behind them, in seat 3, will do something similar:
3³ = room 27
The next bus will do the same. Guests will be allocated room numbers:
5¹ = 5,
5² = 25.
5³ = 125, ...
This will give all of the passengers a unique odd room number. How do we know it's unique? The Fundamental Theorem of Arithmetic.
There's only 1 way to represent the number 125 as a product of prime numbers, and that's 5\*5\*5\. There's no other combination of bus number and seat number that will give us this value.
1 prime number per bus, and an infinite number of powers of those primes for the seat numbers.
Problem Solved.
---
## ...but not for long.
Suddenly, an infinite number of spaceships materialise in the atmosphere (simultaneously, of course). Each of them contains an infinite number of coaches. Each of those coaches contains an infinite number of new guests.
You may have noticed that after the previous reshuffle, there are a lot of empty rooms throughout the hotel. Room 15, for example, will remain unoccupied since it cannot be expressed in the form pⁿ for some prime number, p.
15 = 5\*3
What if we take the ship number, i, the bus number, j, and the seat number, k? We can then take the (i+1)th prime, pᵢ, and the (j+1)th prime, qⱼ, and take their product. Raising this to the power of k will give us:
ship 1, bus 2, seat 1: (3\*5)¹ = room 15
ship 1, bus 2, seat 2: (3\*5)² = room 225
...
This looks good so far, but there's a slight problem:
ship 2, bus 1, seat 2: (5\*3)² = room 225
We've double-booked the room. In fact, we've accidentally double-booked an infinite number of rooms!
Seeking a different approach, we instead try the following formula to work out a room number:
room number = pᵢ \\^ qⱼ \\^ k = (i+1)th prime \\^ (j+1)th prime \\^ seat number
Again, for ship 1 (i), bus 2(j), seat 2(k), this becomes:
3 \\^ 5 \\^ 2 = room 847288609443
---
## Let's take a look at why this works.
Suppose that there are two passengers who are both allocated to the same room.
We'll denote passenger 1's ship number, bus number, and seat number as i₁, j₁, and k₁.
This gives us the (i₁+1)th prime p₁, and the (j₁+1)th prime q₁. So passenger 1 will be assigned to room p₁ \\^q₁ \\^ k₁.
We can do the same for passenger 2 to give us the room number p₂ \\^q₂ \\^ k₂.
Again, we are assuming that they have been assigned to the same room, so these two numbers must be equal.
p₁ \\^ (q₁ \\^ k₁) = p₂ \\^ (q₂ \\^ k₂)
Using the Fundamental Theorem of Arithmetic, we must have that p₁ = p₂, and that (q₁\\^k₁) = (q₂\\^k₂) since q₁\\^k₁ and q₂\\^k₂ are just positive integers, and the prime factorisation must be unique.
We apply the theorem again to this new equation to tell us that q₁= q₂, and k₁ = k₂.
Therefore, these two passengers are actually the same individual. Hence, this equation will give us a unique room number for every passenger.
Suddenly, an infinite number of inter-dimensional portals open up around you. Through each appears an infinite number of spaceships, each with an infinite number of buses, with each of those having an infinite number of passengers.
You realise that you could just keep applying the Fundamental Theorem of arithmetic over and over again; however, you're quite tired and start to realise that you aren't paid enough to have to deal with all of this. Instead, you decide to quit and apply for a job at the Infinite Café.
After all, how hard could that be?
> Want to learn more about how we can find new prime numbers? Check out the article below:[The Hunt For Prime Numbers](https://the-hunt-for-prime-numbers/?ref=jdhwilkins.com)
Thanks for reading 🙂
### Proof by Induction (Ft. The Tower of Hanoi)
URL: https://www.jdhwilkins.com/proof-by-induction-ft-the-tower-of-hanoi/
Last updated: 2026-06-09T08:41:31.000Z
## The Math Behind The Classic Puzzle
> You've probably seen this puzzle before.You could probably solve it without too much hassle.But let's ask a more interesting question...What is the fewest number of moves required to solve the puzzle?Can we prove we're correct?
First, let's make sure we're all on the same page, for the benefit of those who haven't seen this problem before.
The Tower of Hanoi problem starts with a board with 3 vertical pegs sticking out of it. There are 5 rings stacked on the left-most peg as shown in the image below. The goal is to move the stack of rings from the left peg to the right peg.


But there are a few rules:
You can only move one ring at a time,
You can only move the top ring from a peg,
You cannot put a larger ring on top of a smaller one.
We can increase the complexity of this puzzle by increasing the number of rings, but the number of pegs always stays the same.
You can find an [online version of this puzzle](https://www.mathplayground.com/logic%5Ftower%5Fof%5Fhanoi.html?ref=jdhwilkins.com) here if you want to try it out.

After a couple of attempts, you'll probably be able to solve it in the least possible moves and do so relatively quickly. It takes a little longer when you add more rings, but the principle remains the same.
But where does this optimal number come from?
Let's look at a simpler example. What if there was just one ring?

This is not a trick question: it takes just one move to solve the puzzle, and obviously, this number is optimal.
What about with 2 rings?

Then, 3 moves are required to solve it. Again, this number is optimal.
It takes a little more time to calculate the answer for 3 rings, but you should end up with a minimum total of 7 moves.
It turns out that for 4, 5, and 6 rings the optimal number of moves is 15, 31, and 63.
If you know your powers of 2, then you might start to notice a pattern here...
> Claim: Let Hₙ be the number of moves required to solve the Tower of Hanoi puzzle with n rings. Then: Hₙ = 2ⁿ -1
Before we try to prove this claim, let's look at the strategy we employ for an optimal solution.
Take a look at these four states from the optimal solution when we have 5 rings (*n=5*)

We can break down the solution into 3 steps.
Move the top *n-1* rings to the middle peg
Move the bottom ring to the right
Move the *n-1* rings to the right peg
But how many moves do we need to complete each step?
The second step is the easiest to work out; it takes just one move.
The first step requires us to move *n-1* rings from one peg to another. This is just like if we had solved the entire puzzle, but with 4 rings instead of 5.
If we call the optimal number of moves Hₙ, then step 1 requires Hₙ₋₁ moves (the number of moves required for *n-1* rings).
It's the same for step 3 as well, since we are moving *n-1* rings from one peg to another.
Using this idea, we can form an equation.
Hₙ = Hₙ₋₁ + 1 + Hₙ₋₁
Or more simply:
Hₙ = 2\*Hₙ₋₁ + 1
Let's see how we can use this equation to help us prove our formula is correct.
---
We'll prove this formula using a technique known as ***proof by induction***.
The idea is to prove that if the formula is true for some arbitrary number (*k* ), then it is also true for (*k+1*)
Then, if we know that it's true for *k=1,* it must also be true for the next number, *k=2*.
If it's true for *k=2,* then it must also be true for the next number, *k=3*.
If it's true for *k=3* , then it must also be true for the next number, *k=4*,
And so on...
This argument can be repeated again and again until infinity. So the formula must be true for all possible values of *n*.
Let's get started with the proof.
> Claim: Let Hₙ be the number of moves required to solve the Tower of Hanoi puzzle with n rings. Then:
Hₙ = 2ⁿ -1
**Proof.**
We start by proving the formula works for *n=1*.
H₁ = 2¹-1 = 1
and the smallest number of moves for a single ring is 1\. Checks out so far.
Now let's assume that the formula works for an arbitrary number, *k.*Therefore, we are assuming that:
Hₖ = 2ᵏ -1
Now for the tricky step. We now want to show that if it's true for k, then it's also true for k+1.
Using the equation we found earlier, we know that
Hₖ₊₁ = 2\*(Hₖ) +1
Therefore
Hₖ₊₁ = 2\*(2ᵏ -1) +1
using the assumption we just made. So then
Hₖ₊₁ = 2\*2ᵏ --- 2 + 1
Hₖ₊₁ = 2ᵏ⁺¹ -1
Which looks like our formula, except we have *k+1* instead of *k* . So the formula is true for *k+1* if it is true for *k.*
And that's all the heavy lifting done.
We've shown that the formula is correct when k*\=1*. We've shown that if it's true for some value, then it's true for the next value. So this statement must be true for 2, 3, 4, 5, ... and so on.
Using this formula, we find that a puzzle with 10 rings would require at least 1023 moves, and a puzzle with 25 rings would need at least 33554431.
That sounds like a lot, but if you perform one move every second, it would take 388 days, 8 hours, 40 minutes, and 31 seconds to finish the puzzle. Now it *really* sounds like a lot.
---
While the Tower of Hanoi might seem straightforward at first glance, there's far more to it than meets the eye. It's easy to underestimate its complexity, but the puzzle introduces some fascinating concepts worth exploring.
Beyond the challenge itself, it serves as a great introduction to the world of mathematical proof and highlights the intricacies of counting problems, an area of study known as ***combinatorics***.
Whether you're a puzzle enthusiast or a budding mathematician, the Tower of Hanoi offers an engaging challenge and a deeper understanding of problem-solving techniques.
---
If you've enjoyed this puzzle, you might also like [this thought-provoking brain teaser](https://what-if-an-infinite-number-of-spaceships-arrive-at-hilbert-s-hotel/?ref=jdhwilkins.com) .
### Python Chess: Game Simulation and Illegal Moves
URL: https://www.jdhwilkins.com/python-chess-game-simulation-and-illegal-moves/
Last updated: 2026-06-09T08:40:56.000Z
## Building My Second Chess Engine Using Python (Part 3)
This is exciting! We're nearly ready to start simulating a whole game of Chess. There are just a few more components we need.
## Recap
> If you haven't already read part 1 and 2, I would highly recommend checking those out before reading this article; it should make a lot more sense. [Part 1](https://1-hot-encoding-the-chess-programmer-s-secret-weapon/?ref=jdhwilkins.com) [Part 2](https://python-chess-efficient-move-generation-using-bitwise-operations/?ref=jdhwilkins.com) So far in this project, we've built a chess board data structure and tools to manipulate it, and we've created some functions to efficiently calculate the possible moves for a given piece.Our next step is to write a function to correctly apply a move to the board, to allow us to simulate a full game of chess. After that, we return to our move generation component to add the checks for illegal moves.
---
## Applying a Move
To begin, let's first consider what information we need to encode to fully describe a move.
In standard chess move notation, we are given only the type of piece and its new location. E.g., Ne2, which indicates that a knight should be moved to the square e2.
If this does not uniquely specify the move (if there are two knights that could move to e2), then the current file of the piece is given too. E.g. Nce2 . The, albeit rarer, case where two pieces are in the same file is similar, except the rank is given, e.g., N3e2\. (Notice also that we use N for knight since K is reserved for the king).


Additionally, we are also provided information about any checks or captures within the move. Bxb2 indicates that a bishop captured the piece on b2, whereas Bxb2+ indicates that a bishop captured a piece on b2 and, in doing so, put the enemy king in check. Similarly, if a move results in checkmate, we append a # to the end of the move: Bxb2#. However, these are more for the benefit of the reader and don't impact the move too much.
If a piece type is not specified, it is assumed to be a pawn. For example, e4 is actually pawn to e4.
For castling moves, we have the notation O-O for a short/king-side castle, and O-O-O for a long/queen-side castle.
Finally, for promotion moves, we indicate the type of piece that is being promoted to at the end of the move: e8Q or sometimes e8=Q. While it is possible to promote to other types of pieces, it is uncommon to see promotion to anything other than a queen, or occasionally, a knight. (There are various chess puzzles whose solution involves promoting to a knight to deliver checkmate.)
So how do we go about encoding this information?
A good starting point would be to encode the square that the piece is moving from and to, thereby removing the complication of non-unique moves. We'll also store the type of piece that's moving to make bitboard-lookup faster instead of scanning each one.
Next, we classify and store information about different types of moves. This will include double pawn moves, capture by en passant, promotion, and castling. When we come to applying the move, we can modify the board based on this supplied move type to reflect the necessary changes. (Detailed below).
Lastly, for promotion moves, we'll store the type of piece we wish to promote to.
Let's create a new class, Move to the move information. We'll also create some new enumerated constants to make life easier.
```
# CONSTANTS
NORMAL_MOVE, PROMOTION_MOVE, DOUBLE_PAWN,
CASTLE_SHORT, CASTLE_LONG, TAKE_EN_PASSANT = range(6)
# We'll use the same piece enumeration from before to
# indicate what piece we transform to under a promotion move
# this was defined earlier
# 2: 'R', 3: 'r', 4: 'N', 5: 'n', 6: 'B', 7: 'b', 8: 'Q', 9: 'q'
```
```
class Move:
def __init__(self, piece_type, from_square, to_square, **kwargs):
# move parameters
self.piece_type = piece_type
self.from_square = from_square
self.to_square = to_square
self.move_type = kwargs.get('move_type', NORMAL_MOVE)
self.promote_to = kwargs.get('promote_to', None)
```
---
To perform a move, we find the relevant bitboard for the moving piece given by piece\_type. We then remove the bit from the from\_square, and add a bit to the to\_square. Finally, we need to remove the to\_square bit from all other bitboards to ensure that any necessary pieces are captured.
```
def move(M, B):
# Board, B
# Move, M
# remove captured piece from all other bitboards
for i in range(12):
B[i] = remove_bit(B[i], M.to_square)
# move piece
B[M.piece_type] = remove_bit(B[M.piece_type], M.from_square)
B[M.piece_type] = set_bit(B[M.piece_type], M.to_square)
```
Next, we need to handle the edge cases for other move types.
The first thing to check is if a double-pawn move has taken place. If so, we need to update the en passant bitboard to be the square that the pawn has skipped over. If a pawn was captured by en passant, this is the square that the enemy pawn will have to move to.
```
if M.move_type == DOUBLE_PAWN:
if M.piece_type%2 == 0: # white piece
B[enpassant] = set_bit(B[enpassant], M.from_square-8)
else: # black piece
B[enpassant] = set_bit(B[enpassant], M.from_square+8)
```
Next, along a similar vein, we check if the move applied to the board was a pawn capture by en passant. If so, we need to remove the captured pawn from the board, as that pawn is not in the square that was moved to.
To do this, we take the en passant square and perform a bit shift to move it to the location of the piece. We then use it as a mask to remove this piece from its bitboard. We'll also clear the en passant square to make sure that another pawn can't accidentally move to it.
```
elif M.move_type == TAKE_EN_PASSANT:
# find position of piece that was taken
if M.piece_type%2 == 0:
B[enpassant] = B[enpassant] << 8
else:
B[enpassant] = B[enpassant] >> 8
# remove the captured pawn from it's bitboard
if M.piece_type == 0:
B[1] = remove_bit(B[1], ctz(B[enpassant]))
else:
B[0] = remove_bit(B[0], ctz(B[enpassant]))
B[enpassant] = 0
```
The next edge case to check is promotion moves. The only difference here is that we need to remove the promoting pawn and replace it with the specified piece type.
Similarly, for castling moves, the only additional change is that we need to move the corresponding rook to the outside of the king.
And lastly, we need to revoke castling rights if a king or rook moves.
```
# remove enpassant
B[enpassant] = 0
# other move types
if M.move_type == PROMOTION_MOVE:
B[M.piece_type] = remove_bit(B[M.piece_type], M.to_square) # remove pawn
B[M.promote_to] = set_bit(B[M.promote_to], M.to_square) # add other piece
elif M.move_type == CASTLE_LONG:
if M.piece_type == Wking:
# move the white rook
B[Wrook] = remove_bit(B[Wrook], a1)
B[Wrook] = set_bit(B[Wrook], d1)
B[WLcastle] = 0
B[WScastle] = 0
else:
# move the black rook
B[Brook] = remove_bit(B[Brook], a8)
B[Brook] = set_bit(B[Brook], d8)
B[BLcastle] = 0
B[BScastle] = 0
elif M.move_type == CASTLE_SHORT:
if M.piece_type == Wking:
# move the white rook
B[Wrook] = remove_bit(B[Wrook], h1)
B[Wrook] = set_bit(B[Wrook], f1)
B[WLcastle] = 0
B[WScastle] = 0
else:
# move the black rook
B[Brook] = remove_bit(B[Brook], h8)
B[Brook] = set_bit(B[Brook], f8)
B[BLcastle] = 0
B[BScastle] = 0
elif M.move_type == NORMAL_MOVE:
# revoke castling rights
if M.piece_type == Bking:
B[BLcastle] = 0
B[BScastle] = 0
elif M.from_square == a8:
B[BLcastle] = 0
elif M.from_square == h8:
B[BScastle] = 0
elif M.piece_type == Wking:
B[WLcastle] = 0
B[WScastle] = 0
elif M.from_square == a1:
B[WLcastle] = 0
elif M.from_square == h1:
B[WScastle] = 0
# update the white, black, and all bitboards now that all changes have been finalised
update_bitboards(B)
# switch player
B[nextToMove] = (B[nextToMove] + 1)%2
```
---
## Testing
Now that we have these tools in place, we can try simulating a whole game.
In particular, we'll take the famous Byrne vs Fischer match from 1956\. You can find details of the match [here](https://www.chessgames.com/perl/chessgame?gid=1008361&ref=jdhwilkins.com).
First, we need to convert each of the moves from the match into a format that we can run. We'll develop a tool to decipher moves later on, so for now we'll do this manually.
```
# Moves in chess notation:
1.Nf3 Nf6
2.c4 g6
3.Nc3 Bg7
4.d4 O-O
5.Bf4 d5
6.Qb3 dxc4
7.Qxc4 c6
8.e4 Nbd7
9.Rd1 Nb6
10.Qc5 Bg4
11.Bg5 Na4
12.Qa3 Nxc3
13.bxc3 Nxe4
14.Bxe7 Qb6
15.Bc4 Nxc3
16.Bc5 Rfe8+
17.Kf1 Be6!!
18.Bxb6 Bxc4+
...
```
```
# Moves written as function calls
move(Move(Wknight, g1, f3), B)
move(Move(Bknight, g8, f6), B)
move(Move(Wpawn, c2, c4, move_type = DOUBLE_PAWN), B)
move(Move(Bpawn, g7, g6), B)
move(Move(Wknight, b1, c3), B)
move(Move(Bbishop, f8, g7), B)
move(Move(Wpawn, d2, d4, move_type = DOUBLE_PAWN), B)
move(Move(Bking, e8, g8, move_type = CASTLE_SHORT), B)
move(Move(Wbishop, c1, f4), B)
move(Move(Bpawn, d7, d5, move_type = DOUBLE_PAWN), B)
move(Move(Wqueen, d1, b3), B)
move(Move(Bpawn, d5, c4), B)
move(Move(Wqueen, b3, c4), B)
move(Move(Bpawn, c7, c6), B)
move(Move(Wpawn, e2, e4, move_type = DOUBLE_PAWN), B)
move(Move(Bknight, b8, d7), B)
move(Move(Wrook, a1, d1), B)
move(Move(Bknight, d7, b6), B)
```
Now we can simulate the game and compare the results!


As we can see, the program output after 40 full moves looks as expected. It's worth noting that the move function assumes that the supplied move is valid and correct.
---
## Removing Illegal Moves
An illegal move is one that would put you in check. Obviously, this is not allowed, as you would immediately lose the game. However, there exist some chess variants, typically fast-paced styles, where king capture is allowed, and thus a player may put themselves in check. For the purpose of this engine, however, we will be removing illegal moves.
To remove illegal moves, the most straightforward approach is to apply the move to the board and test to see if it puts the player's king in check. We can compute a list of moves using the tools built in the previous article, then we apply each of those moves to the board to see the result.
```
# demo: applying list of moves to a board
B = new_board()
moves = knight_move(B, b1, white)
while moves:
# locate and remove the least significant bit
lsb = ctz(moves)
moves = remove_bit(moves, lsb)
# the square to move to will be indicated by the lsb
M = Move(Wknight, b1, lsb)
B1 = B.copy()
move(M, B1)
print_board(B1)
```
```
# Possible board states after moving knight on b1
A B C D E F G H A B C D E F G H
________________________ ________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜ 8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟ 7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・ 6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・ 5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・ 4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ♘ ・ ・ ・ ・ ・ ・ ・ 3 | ・ ・ ♘ ・ ・ ・ ・ ・
2 | ♙ ♙ ♙ ♙ ♙ ♙ ♙ ♙ 2 | ♙ ♙ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ・ ♗ ♕ ♔ ♗ ♘ ♖ 1 | ♖ ・ ♗ ♕ ♔ ♗ ♘ ♖
```
With this information, we now need a tool to check if a player is in check. This will be used again in the future when we come to testing end-game conditions.
```
def test_check(B, allied_colour, opponent_colour):
threat_map = 0
# colour of the allied king (king that may be in check)
allied_king = Wking if allied_colour == white else Bking
b = B[Bpawn] if opponent_colour == black else B[Wpawn] # piece type
while b:
pos = ctz(b) # position of each piece within the type
b = remove_bit(b, pos)
threat_map |= (bpawn_capture_masks[pos] if opponent_colour == black else wpawn_capture_masks[pos])
b = B[Brook] if opponent_colour == black else B[Wrook] # piece type
while b:
pos = ctz(b) # position of each piece within the type
b = remove_bit(b, pos)
threat_map |= rook_move(B, pos, opponent_colour)
b = B[Bknight] if opponent_colour == black else B[Wknight] # piece type
while b:
pos = ctz(b) # position of each piece within the type
b = remove_bit(b, pos)
threat_map |= knight_move(B, pos, opponent_colour)
b = B[Bbishop] if opponent_colour == black else B[Wbishop] # piece type
while b:
pos = ctz(b) # position of each piece within the type
b = remove_bit(b, pos)
threat_map |= bishop_move(B, pos, opponent_colour)
b = B[Bqueen] if opponent_colour == black else B[Wqueen] # piece type
while b:
pos = ctz(b) # position of each piece within the type
b = remove_bit(b, pos)
threat_map |= queen_move(B, pos, opponent_colour)
b = B[Bking] if opponent_colour == black else B[Wking] # piece type
while b:
pos = ctz(b) # position of each piece within the type
b = remove_bit(b, pos)
threat_map |= king_move(B, pos, opponent_colour)
if B[allied_king] & threat_map:
return True # in check
return False # not in check
```
Testing this on the last position from the game we simulated before, gives us:
```
print(test_check(B, allied_colour=white, opponent_colour=black))
>> True # king is in check
# Threat-map (squares under attack) # board position
A B C D E F G H A B C D E F G H
__________________ ________________________
8 | · · · · · 1 1 1 8 | ・ ♕ ・ ・ ・ ・ ・ ・
7 | · · · · 1 · · 1 7 | ・ ・ ・ ・ ・ ♟ ♚ ・
6 | · · · 1 1 1 1 1 6 | ・ ・ ♟ ・ ・ ・ ♟ ・
5 | 1 1 1 1 · 1 · 1 5 | ・ ♟ ・ ・ ♘ ・ ・ ♟
4 | 1 · 1 · 1 · 1 · 4 | ・ ♝ ・ ・ ・ ・ ・ ♙
3 | 1 · · · · · · · 3 | ・ ♝ ♞ ・ ・ ・ ・ ・
2 | 1 1 · 1 1 1 1 · 2 | ・ ・ ♜ ・ ・ ・ ♙ ・
1 | · 1 1 1 · · · · 1 | ・ ・ ♔ ・ ・ ・ ・ ・
```
---
These are the squares that the black pieces can capture on, sometimes referred to as the 'squares controlled by black'. As we can see, the white king is under attack, has nowhere to go, and nothing can block the check. Hence this is checkmate.
Now we can bring these components together to generate a full list of possible, legal moves for any given position.
```
# generate a list of moves and filter to show only legal ones
def generate_legal_move_list(B, colour):
legal_moves = []
# temporary board
B1 = None
opponent_colour = black if colour == white else white
# pawn moves
type = Bpawn if colour == black else Wpawn # piece type
b = B[type]
while b:
from_ = ctz(b) # position of each piece within the type
b = remove_bit(b, from_)
moves = pawn_move(B, from_, colour)
while moves:
to_ = ctz(moves)
moves = remove_bit(moves, to_)
# create move object
if get_bit(B[enpassant], to_):
M = Move(type, from_, to_, move_type=TAKE_EN_PASSANT)
elif abs(from_-to_) == 16:
M = Move(type, from_, to_, move_type=DOUBLE_PAWN)
else:
M = Move(type, from_, to_) # includes promotion moves still
# apply move to temp board
B1 = B.copy()
move(M, B1)
# test for checks
if not test_check(B=B1, allied_colour=colour, opponent_colour=opponent_colour):
# handle promotion moves (prommote to queen and knight)
if to_<8 or to_>56:
if colour == black:
legal_moves.append(Move(type, from_, to_, move_type=PROMOTION_MOVE, promote_to=Bqueen))
legal_moves.append(Move(type, from_, to_, move_type=PROMOTION_MOVE, promote_to=Bknight))
else:
legal_moves.append(Move(type, from_, to_, move_type=PROMOTION_MOVE, promote_to=Wqueen))
legal_moves.append(Move(type, from_, to_, move_type=PROMOTION_MOVE, promote_to=Wknight))
else: # all other moves (already handled)
legal_moves.append(copy.deepcopy(M))
# ...
# We repeat these steps for each of the different piece types
# other pieces are simpler as there are fewer special move edge-cases
return legal_moves
```
## More Testing
Now that we have this in place, we are in a better position to test the move generation code from the last article, as well as what we've done so far in this one.
Let's visualise all of the possible first moves for white at the start of the game:
```
B = new_board()
legal_moves = generate_legal_move_list(B, white)
print(f"number of moves: {len(legal_moves)}")
for m in legal_moves:
B1 = B.copy()
move(m, B1)
print_board(B1)
```
```
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ♙ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ・ ♙ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
... (19 more)...
```
I've attached the full output to the end of this article; it's quite long since there are 20 resulting positions after the first move. You can scroll down to see it. I also tested this using the position from the game we simulated before. As expected, there are 0 legal moves for white, making this checkmate. Everything seems to be working correctly
---
## Summary
So far, we have a chessboard data structure, tools that generate a list of legal moves, methods to test if a position results in a player being in check, and a way of applying a move to the board.
Our next steps are to build a tree structure to allow us to easily navigate between positions, as well as store things like threat maps and move lists for each position to save recalculating them. But we'll leave that for next time.
This is part 3 in a series of walkthroughs documenting my journey in developing a chess engine. If you've found this useful, insightful, or even vaguely interesting, please consider following to be notified of future updates. Thanks for reading 🙂
\*Unless otherwise stated, all images are by the author.
## References:
[chessgames.com](http://chessgames.com/?ref=jdhwilkins.com) has a huge archive of chess games from throughout history. [This](https://https%3A%2F%2Fwww.chessgames.com%2Fperl%2Fchessgame%3Fgid%3D1008361)link is to the one used in this article
## Appendix: Final Code Output:
Generation of legal moves for white at the start of the game
```
number of moves: 20
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ♙ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ・ ♙ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ♙ ・ ・ ・ ・ ・ ・ ・
2 | ・ ♙ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ♙ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ♙ ・ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ♙ ・ ・ ・ ・ ・ ・
2 | ♙ ・ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ♙ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ♙ ♙ ・ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ♙ ・ ・ ・ ・ ・
2 | ♙ ♙ ・ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ♙ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ♙ ♙ ♙ ・ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ♙ ・ ・ ・ ・
2 | ♙ ♙ ♙ ・ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ♙ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ♙ ♙ ♙ ♙ ・ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ♙ ・ ・ ・
2 | ♙ ♙ ♙ ♙ ・ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ♙ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ♙ ♙ ♙ ♙ ♙ ・ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ♙ ・ ・
2 | ♙ ♙ ♙ ♙ ♙ ・ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ♙ ・
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ♙ ♙ ♙ ♙ ♙ ♙ ・ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ♙ ・
2 | ♙ ♙ ♙ ♙ ♙ ♙ ・ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ♙
3 | ・ ・ ・ ・ ・ ・ ・ ・
2 | ♙ ♙ ♙ ♙ ♙ ♙ ♙ ・
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ♙
2 | ♙ ♙ ♙ ♙ ♙ ♙ ♙ ・
1 | ♖ ♘ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ♘ ・ ・ ・ ・ ・ ・ ・
2 | ♙ ♙ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ・ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ♘ ・ ・ ・ ・ ・
2 | ♙ ♙ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ・ ♗ ♕ ♔ ♗ ♘ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ♘ ・ ・
2 | ♙ ♙ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ・ ♖
A B C D E F G H
________________________
8 | ♜ ♞ ♝ ♛ ♚ ♝ ♞ ♜
7 | ♟ ♟ ♟ ♟ ♟ ♟ ♟ ♟
6 | ・ ・ ・ ・ ・ ・ ・ ・
5 | ・ ・ ・ ・ ・ ・ ・ ・
4 | ・ ・ ・ ・ ・ ・ ・ ・
3 | ・ ・ ・ ・ ・ ・ ・ ♘
2 | ♙ ♙ ♙ ♙ ♙ ♙ ♙ ♙
1 | ♖ ♘ ♗ ♕ ♔ ♗ ・ ♖
```
### Who Needs Strava Premium When You Have Python?
URL: https://www.jdhwilkins.com/who-needs-strava-premium-when-you-have-python/
Last updated: 2026-06-09T08:40:25.000Z
## Building a route heatmap using Python
If you haven't already heard, Strava provide a powerful API that allows users to access their data using code. This gives us the ability to create interesting visualisations, analyse progress, and create custom trackers and planners, all with just a few lines of code.
In this tutorial, we're going to walk through the process of building a heatmap to visualise all of your GPS routes on one map. It'll show routes you travel frequently, adventures in the middle-of-nowhere, and everything in between. It's a really cool way to see how much of an area you've explored, and find some new routes that connect places you've been.

We'll also see how we can modify this code to only use activities of a specific type or activities within a certain date range. So if you want to show only your bike rides in a certain year, you can do that too.
*\[Note: For this tutorial, you will need a Strava Account and a Python environment set up on your machine. Any Python libraries used in this project that you don't already have installed can be downloaded with pip.\]*
---
## Getting Started
Let's start by connecting to the Strava API and requesting an access token. For a full explanation of how to work with the API, check out this article. The code used is shown below:
```
import os
import requests
import webbrowser
import json
import time
import pandas as pd
# request initial token
redirect_uri = 'http://localhost:8000'
client_id = os.environ['STRAVA_CLIENT_ID']
client_secret = os.environ['STRAVA_CLIENT_SECRET']
request_url = f'http://www.strava.com/oauth/authorize?client_id={client_id}' \
f'&response_type=code&redirect_uri={redirect_uri}' \
f'&approval_prompt=force' \
f'&scope=profile:read_all,activity:read_all'
webbrowser.open(request_url)
code = input('Insert the code from the url: ')
token = requests.post(url='https://www.strava.com/api/v3/oauth/token',
data={'client_id': client_id,
'client_secret': client_secret,
'code': code,
'grant_type': 'authorization_code'})
token = token.json()
```
Now that we can access the user's account, we can fetch a list of all activities. Each activity contains the following information, stored in a JSON format.
```
{'resource_state': 2,
'athlete': {'id': *****,
'resource_state': 1},
'name': 'Morning Ride',
'distance': 4034.0,
'moving_time': 739,
'elapsed_time': 739,
'total_elevation_gain': 49.0,
'type': 'Ride',
'sport_type': 'Ride',
'workout_type': None,
'id': *****,
'start_date': '2024-09-06T06:47:09Z',
'start_date_local': '2024-09-06T06:47:09Z',
'timezone': '(GMT+00:00) Europe/London',
'utc_offset': 3600.0,
'location_city': None,
'location_state': None,
'location_country': None,
'achievement_count': 0,
'kudos_count': 0,
'comment_count': 0,
'athlete_count': 1,
'photo_count': 0,
'map': {'id': '******',
'summary_polyline': '***********************',
'resource_state': 2},
'trainer': False,
'commute': False,
'manual': False,
'private': True,
'visibility': 'only_me',
'flagged': False,
'gear_id': None,
'start_latlng': [****************, *****************],
'end_latlng': [*****************, *****************],
'average_speed': 5.459,
'max_speed': 10.002,
'has_heartrate': False,
'heartrate_opt_out': False,
'display_hide_heartrate_option': False,
'elev_high': 117.2,
'elev_low': 96.2,
'upload_id': *************,
'upload_id_str': '*************',
'external_id': 'stripped_garmin_ping_*************',
'from_accepted_tag': False,
'pr_count': 0,
'total_photo_count': 0,
'has_kudoed': False}
```
As you can see, there are a lot of data fields here, but the ones we're interested in are the type, start\_date, *start\_latlng and map\[summary\_polyline\]*.
Let's now import a list of all activities and extract these data fields from the results. We'll also save some other fields too, such as distance, duration, activity name and ID, just in case we need them later.
```
# import all user activities
activities = []
page = 1
response = []
while True:
# request new page of activities
endpoint = f"https://www.strava.com/api/v3/athlete/activities?" \
f"access_token={token['access_token']}&" \
f"page={page}&" \
f"per_page=50"
response = requests.get(endpoint).json()
# check if page contains activities
if len(response):
# retrieve some fields for each activity
# you can see the full list of fields by looking at the response json above
activities += [{"name": i["name"],
"distance": i["distance"],
"type": i["type"],
"sport_type": i["sport_type"],
"moving_time": i["moving_time"],
"elapsed_time": i["elapsed_time"],
"date": i["start_date"],
"polyline": i["map"]["summary_polyline"],
"map_id": i["map"]["id"],
"start_latlng": i["start_latlng"]} for i in response]
page += 1
else:
break
# convert our activities to a DataFrame
df = pd.DataFrame(activities)
```
This is a snippet of what our database will look like; some rows and columns have been hidden.

Let's now start filtering our activities. We need to show only ones that have a GPS map. To do this, we will look at the start\_latlng field. If there is some GPS data, we'll have a set of coordinates here; if not, it will be an empty array.
```
# remove activities with no gps data
a = df.loc[ df["start_latlng"].str.len() != 0 ]
```
Next, we'll filter for a specific date range. For example, to select all activities from 2023, we filter for dates after 31st December 2022 and before January 1st 2024.
```
# filter by date range - all activities from 2023
b = a.loc[ (a['date'] > '2022-12-31') & (a['date'] < '2024-01-01')]
```
Finally, we'll filter for only runs, walks and hikes. We can do this in a similar way to before, but using the type column in our database.
```
# filter by activity type - only runs, hikes and walks
c = b.loc[ (b["type"] == "Run") | (b["type"] == "Hike") | (b["type"] == "Walk")]
```
---
## Polylines
Now that we have all of our activities collected and filtered, we can start extracting the GPS data. You may notice that there is no GPS file or even a coordinate list contained within an activity. Instead, we use something called a polyline.
Polyline is a compression algorithm developed by Google to store a series of GPS coordinates as a Unicode string. It is a form of lossy compression, so it is not quite as accurate as the original GPS file; however, it will be more than sufficient for this project.
It's also important to note that if you have a privacy zone set up on your Strava account (to hide the start and finish of your activity, or an area around your house), then that information will not be included in the polyline.
The details of the polyline algorithm can be a little complicated. Luckily, there is already a Python library that can help us work with a polyline string. This library can be downloaded using pip. With it, we take a polyline string from our database and decode it to produce a list of coordinate points.
```
import polylinecoords = [polyline.decode(i, 5) for i in c["polyline"]]
```
```
# polyline string
"o`_iIbb|LGe@PeFw@aADcHb@w@jBkA~@sAr@SnD{SK_ABqA{@}BIw@w@sAq@_FL_EhA_KRwDj@u \
DnBeI`FkYPE?c@b@sArAeKn@qCM}AHgDn@yB?]lHwTbLuU^V@_@Fj@n@DH^RBRk@Ao@Q?HS?P?WM \
Rt@n@LVQg@i@l@wAY]c@KJyFlK[t@?\uCxF_BhF_F|NGVKEuAaH_EkAFsBdAqGc@kDkCkG_EqEsB \
cP_AwD{CgJ_F_NeG}OC[ZiBEcGaCoc@c@uBGs@F?cAgAmA{Cg@iEF}B`@cDKsDT{E`@eA~@eELgK \
\oFPuAf@gAn@mCHcHKkCWy@]{E]w@SgB?kB_@..."
# coordinates
[(54.06744, -2.2789),
(54.06748, -2.27871),
(54.06739, -2.27756),
(54.06767, -2.27723),
(54.06764, -2.27577),
(54.06746, -2.27549),
(54.06692, -2.27511),
... ]
```
If you want to explore this in more detail, Google has a[free online polyline tool](https://developers.google.com/?ref=jdhwilkins.com) where you can convert coordinates to a polyline, and vice versa.
---
## Building The Map
The final step is to plot all of these coordinates on a map. Again, there's a Python library that can help us here: Folium.
The Folium library gives us a free, interactive, zoomable map powered by [OpenStreetMap](https://www.openstreetmap.org/?ref=jdhwilkins.com). It also provides tools to plot lines and points.
We'll convert our list of coordinates to a Folium object\*, then plot those lines on the map. Then we'll also add the date of the activity as a tooltip, so that it is shown when we hover over a route.
*\*The folium polyline object does not have a constructor that accepts a polyline string, only a list of coordinates. The added level of indirection is unfortunate.*
```
# Render lines on map
import folium
m = folium.Map(location=coords[0][0], zoom_start=7)
lines = [ folium.PolyLine(locations=coords[i],
color='purple',
tooltip = c.iloc[i]["date"].split("T")[0],
weight=2,
smooth_factor=0.1)
for i in range(len(coords)) ]
for i in lines:
i.add_to(m)
```
And here's the completed map:

As you can see below, when we zoom in, we're plotting multiple routes on top of each other on the same map. This shows us the paths that are most frequently used, as the lines appear thicker when viewed from further away.

And there we have a fully customisable GPS route heatmap. You can adapt this code to show different time periods and activity types, and customise the map to use different colours and line widths.
You can also use the same techniques of importing and filtering the dataset to build a variety of other applications and tools, such as progress trackers and custom leaderboards with friends.
Happy coding!
### Python Chess: Efficient Move Generation Using Bitwise Operations
URL: https://www.jdhwilkins.com/python-chess-efficient-move-generation-using-bitwise-operations/
Last updated: 2026-06-09T08:39:55.000Z
### Building My Second Chess Engine Using Python (Part 2)
> Part 1: 1-Hot Encoding: The Chess Programmer's Secret WeaponThis is part 2 in a series of articles documenting my process of building a chess engine. I hope to share insights from my previous experience and explain some of the concepts and techniques I'll be using. If you haven't already read part 1, I'd strongly recommend taking a look before reading part 2\. You can check it out at the link above.Time to pick up where we left off...
---
In the previous article, we built a data structure to represent the chessboard. We used a collection of bitboards (64-bit binary numbers) and 1-hot encoding to represent the different types of pieces and their locations. We then defined a set of tools to allow us to access, modify and display this data structure.
```
# example usage
B = new_board()
print_board(B)
print_bitboard(B[Brook])
print_bitboard(B[Wpawn])
```
```
# whole board # black rooks # white pawns
A B C D E F G H A B C D E F G H A B C D E F G H
__________________ __________________ __________________
8 | r n b q k b n r 8 | 1 · · · · · · 1 8 | · · · · · · · ·
7 | p p p p p p p p 7 | · · · · · · · · 7 | · · · · · · · ·
6 | 6 | · · · · · · · · 6 | · · · · · · · ·
5 | 5 | · · · · · · · · 5 | · · · · · · · ·
4 | 4 | · · · · · · · · 4 | · · · · · · · ·
3 | 3 | · · · · · · · · 3 | · · · · · · · ·
2 | P P P P P P P P 2 | · · · · · · · · 2 | 1 1 1 1 1 1 1 1
1 | R N B Q K B N R 1 | · · · · · · · · 1 | · · · · · · · ·
```
We also have the tools:
```
# set a bit of a bitboard to a 1
set_bit(bitboard, square) -> bitboard
# set a bit of a bitboard to a 0
remove_bit(bitboard, square) -> bitboard
# get the value of a bit of a bitboard
get_bit_(bitboard, square) -> bool
# count trailing zeros / find least significant bit
ctz(bitboard) -> int
```
Before we move on, let's define one more tool that allows us to get the inverse of a bitboard:
```
# invert, or perform a bitflip on, a bitboard
def invert(b):
return b ^ (1<<64)-1
```
---
## Move Generation
Our first task is to calculate what moves can be made in a given position. When we come to writing the search algorithm to identify the best move, we will need to repeatedly generate a list of possible moves, then try each of them, in order to explore different game outcomes. Hence, making the move generation algorithm as efficient as possible is really important.
A simple approach to move generation could look something like this:
For a given piece type, colour and location,
Calculate which squares it could move to
For each of those squares, check if there's a piece in it: if there's an allied piece, it can't move to that square, but if there's an enemy piece, it may be able to take it. (Unless it's a pawn, as they can't take pieces in the same file).
Depending on the piece type, there may be some special moves that we need to check for, such as double pawn moves, en passant, and castling
After this process has finished, we need to remove any illegal moves. These are moves that would put yourself in check, and moves such as castling out of or through a check.
To make this process as efficient as possible, we're going to rely on fast lookups instead of calculations to find possible moves.
## Knight
The knight is perhaps the simplest piece to calculate moves for as it's move set is virtually the same regardless of its location on the board. It can move in an 'L' shape, that is, 2 squares in one direction, and 1 square to the side.
We can generate a list of *movement masks* for every square of the board. These identify the squares that the piece can move to. When we need a list of moves, we can just look-up the required mask for the given square. Below are the movement masks for a knight. We'll see how this can be generated a little later on.
```
knight_move_masks = [132096, 329728, 659712, 1319424, 2638848, 5277696, 10489856, 4202496, 33816580, 84410376, 168886289, 337772578, 675545156,
1351090312, 2685403152, 1075839008, 8657044482, 21609056261, 43234889994, 86469779988, 172939559976, 345879119952, 687463207072,
275414786112, 2216203387392, 5531918402816, 11068131838464, 22136263676928, 44272527353856, 88545054707712, 175990581010432,
70506185244672, 567348067172352, 1416171111120896, 2833441750646784, 5666883501293568, 11333767002587136, 22667534005174272,
45053588738670592, 18049583422636032, 145241105196122112, 362539804446949376, 725361088165576704, 1450722176331153408,
2901444352662306816, 5802888705324613632, 11533718717099671552, 4620693356194824192, 288234782788157440, 576469569871282176,
1224997833292120064, 2449995666584240128, 4899991333168480256, 9799982666336960512, 1152939783987658752, 2305878468463689728,
1128098930098176, 2257297371824128, 4796069720358912, 9592139440717824, 19184278881435648, 38368557762871296, 9077567998918656]
### TESTING
B = new_board()
# move: Nc6
B[Bknight] = remove_bit(B[Bknight], b8)
B[Bknight] = set_bit(B[Bknight], c6)
update_bitboards(B)
print_board(B)
# all possible knight moves for this square
print_bitboard(knight_move_masks[c6])
# knight moves restricted by nearby pieces
print_bitboard( knight_move_masks[c6] & invert(B[black]) )
```
```
# board # all possible moves # moves restricted by pieces
A B C D E F G H A B C D E F G H A B C D E F G H
__________________ __________________ __________________
8 | r b q k b n r 8 | · 1 · 1 · · · · 8 | · 1 · · · · · ·
7 | p p p p p p p p 7 | 1 · · · 1 · · · 7 | · · · · · · · ·
6 | n 6 | · · · · · · · · 6 | · · · · · · · ·
5 | 5 | 1 · · · 1 · · · 5 | 1 · · · 1 · · ·
4 | 4 | · 1 · 1 · · · · 4 | · 1 · 1 · · · ·
3 | 3 | · · · · · · · · 3 | · · · · · · · ·
2 | P P P P P P P P 2 | · · · · · · · · 2 | · · · · · · · ·
1 | R N B Q K B N R 1 | · · · · · · · · 1 | · · · · · · · ·
```
This is the same principle we will use for the other pieces as well: calculate a movement mask (bitboard), find the locations of allied pieces (also represented as a bitboard), and then use a bitwise AND operation to remove the occupied squares.
---
## Sliding Vs Non-Sliding Pieces
A knight is the simplest example because it has no 'special moves' and it is a non-sliding piece. Unlike a bishop, rook or queen (sliding pieces), a knight's movement range is fixed; it can move to only a set number of squares around it.
A sliding piece can move any number of squares in a given direction. Its movement path is cut short by the presence of enemy and allied pieces. It can move up to and including the square an enemy piece is on, but it can only move up to (not including) an allied piece. To simplify this problem, we'll assume all pieces on the board are enemy pieces. Then our sliding piece is able to capture all of them. After producing our movement mask, we can then remove from it the squares occupied by allied pieces.
```
# Consider a rook on square a1. Let the rest of the board be empty except
# two pieces located on a7 and e1. (shown in left bitboard)
# if those two pieces are enemy pieces, the rook can move up to and including
# those squares. (shown in middle bitboard)
# if those two pieces are enemy pieces, the rook can only move up to those
# squares (shown in right bitboard)
A B C D E F G H A B C D E F G H A B C D E F G H
__________________ __________________ __________________
8 | · · · · · · · · 8 | · · · · · · · · 8 | · · · · · · · ·
7 | 1 · · · · · · · 7 | 1 · · · · · · · 7 | · · · · · · · ·
6 | · · · · · · · · 6 | 1 · · · · · · · 6 | 1 · · · · · · ·
5 | · · · · · · · · 5 | 1 · · · · · · · 5 | 1 · · · · · · ·
4 | · · · · · · · · 4 | 1 · · · · · · · 4 | 1 · · · · · · ·
3 | · · · · · · · · 3 | 1 · · · · · · · 3 | 1 · · · · · · ·
2 | · · · · · · · · 2 | 1 · · · · · · · 2 | 1 · · · · · · ·
1 | 1 · · · 1 · · · 1 | · 1 1 1 1 · · · 1 | · 1 1 1 · · · ·
```
```
# Hence, the set of moves determined by the presence of allied pieces is a
# subset of the moves determined by enemy pieces.
# Therefore, we assume all pieces are enemy pieces, then remove from that
# movement mask, the squares occupied by allied pieces.
# moves = moves & invert( B[allied_pieces] )
```
## Generating Sliding Piece Movement Masks
Consider a rook on a1\. It can access squares a2 through a8 and b1 through h1 (14 squares). However, this will be affected by the presence of other pieces on those squares. As discussed above, we assume all pieces on the board are enemy pieces.
Given this simplification, we only need to consider the squares a2 to a7 and b1 to g1, as these are the only squares that affect the movement of the rook on a1\. (If there is an *enemy* piece on a8, we will be able to move there only if we can move to a7 (so a8 does not determine movement options. If there is an *allied*piece on a8, this square will be removed when we subtract squares containing allied pieces afterwards).
Hence, there are 12 squares (known as ***occupancy bits***) that affect the movement of a rook on a1, and there are 14 possible squares that the rook can move to. These numbers will differ depending on which square the rook is on.
Consider only a2-a7\. The number of squares the rook can move in this direction is determined by the position of the first bit in this sequence. A bit on a2means the rook can only move 1 square. A bit on a7means the rook can move 6 squares. No bits at all means the rook can move 7 squares. The same is true for b1-g1\. Therefore, there are 7 \* 7 = 49 combinations of possible movement masks.
These two bitboards:
```
# Bitboards showing the location of enemy pieces on the board
# The rook is on a1
A B C D E F G H A B C D E F G H
__________________ __________________
8 | 1 · · · · · · · 8 | · · · · · · · ·
7 | · · · · · · · · 7 | 1 · · · · · · ·
6 | · · · · · · · · 6 | · · · · · · · ·
5 | · · · · · · · · 5 | · · · · · · · ·
4 | 1 · · · · · · · 4 | · · · · · · · ·
3 | 1 · · · · · · · 3 | 1 · · · · · · ·
2 | · · · · · · · · 2 | · · · · · · · ·
1 | · · · · · 1 · · 1 | · · · · · 1 1 ·
```
Will result in the same possible moves, since the rook can move up to a4 and up to f1 in both cases. Even though there are only 49 outcomes, there are 2¹² = 4096 combinations of occupancy bits that map to them.
#### Procedure
We start by working out which bits are the occupancy bits for each square. These bits are stored in a mask. This mask can be applied to another bitboard to retrieve the state of those bits on that particular board.
Next, we will compute all possible combinations of occupancy bits (for every square).
Finally, for each combination of bits, we calculate the possible moves that it corresponds to. We can store this information in a dictionary for fast lookup.
---
## Implementation
Let's start by building a set of masks to identify the occupancy bits for each square.
```
# count up to and inlcuding:
# count up to next multiple of 8 -2
# count down to next multiple of 8 + 1
# count multiples of 8 down until <=15
# count multiples of 8 up until >= 48
rook_occupancy_masks = []
for square in range(64):
bitboard = 0
# count right until you reach file 7
temp = square
while temp%8 < 6:
temp += 1
bitboard = set_bit(bitboard, temp)
# count left until you reach file 2
temp = square
while temp%8 > 1:
temp -= 1
bitboard = set_bit(bitboard, temp)
# count up until you reach rank 2
temp = square
while temp > 15:
temp -=8
bitboard = set_bit(bitboard, temp)
# count down until you reach rank 7
temp = square
while temp < 48:
temp +=8
bitboard = set_bit(bitboard, temp)
rook_occupancy_masks.append(bitboard)
```
```
print_bitboard(rook_occupancy_masks[f6])
# rook occupancy mask for a rook on f6 - these are the bits we need to check
# in order to identify where the rook can move
A B C D E F G H
__________________
8 | · · · · · · · ·
7 | · · · · · 1 · ·
6 | · 1 1 1 1 · 1 ·
5 | · · · · · 1 · ·
4 | · · · · · 1 · ·
3 | · · · · · 1 · ·
2 | · · · · · 1 · ·
1 | · · · · · · · ·
```
With our masks identified, we can now calculate every possible combination of bits in the shape of each of those masks. If there are n bits in a mask, there will be 2\\^n combinations of those occupancy bits. These can be represented by the binary values 0, ..., (2\\^n)-1\. We take each of those binary values in turn, and insert them into a blank bitboard in the pattern described by the occupancy mask.
```
# set of combinations of occupancy bits
rook_combinations = [[]]*64
for square in range(64):
rook_combinations[square] = []
# total number of bits in occupancy mask
n = int.bit_count(rook_occupancy_masks[square])
for i in range(2**n):
bit_string = bin(i)[2:].zfill(n)
occupancy_bits = 0
occupancy_mask = rook_occupancy_masks[square]
# scan bit_string
for j in bit_string:
# find and remove least significant bit from occupancy mask
sq = ctz(occupancy_mask)
occupancy_mask = remove_bit(occupancy_mask, sq)
# copy bit string into occupancy mask locations
if j == "1":
occupancy_bits = set_bit(occupancy_bits, sq)
rook_combinations[square].append(occupancy_bits)
```
```
print_bitboard( rook_combinations[d3][583] )
# Left: rook occupancy mask for d3
# Right: one combination of those occupancy bits (there are 1024
# combinations total for this square)
A B C D E F G H A B C D E F G H
__________________ __________________
8 | · · · · · · · · 8 | · · · · · · · ·
7 | · · · 1 · · · · 7 | · · · 1 · · · ·
6 | · · · 1 · · · · 6 | · · · · · · · ·
5 | · · · 1 · · · · 5 | · · · · · · · ·
4 | · · · 1 · · · · 4 | · · · 1 · · · ·
3 | · 1 1 · 1 1 1 · 3 | · · · · · 1 1 ·
2 | · · · 1 · · · · 2 | · · · 1 · · · ·
1 | · · · · · · · · 1 | · · · · · · · ·
```
Now that we have every combination of occupancy bits worked out for every square on the board, we just need to identify a mapping from occupancy bits to movement masks. We create a series of hash tables (Python dictionaries are implemented using a hash table) to store this. This code will look similar to before when we calculated the occupancy masks.
```
rook_move_masks = [{}]*64
for square in range(64):
rook_moves[square] = {}
combinations = rook_combinations[square]
for i in combinations:
moves = 0
# scan right
temp = square
while temp%8 < 7:
temp += 1
moves = set_bit(moves, temp)
if get_bit(i, temp) == 1:
break
# scan left
temp = square
while temp%8 > 0:
temp -= 1
moves = set_bit(moves, temp)
if get_bit(i, temp) == 1:
break
# scan up
temp = square
while temp > 7:
temp -=8
moves = set_bit(moves, temp)
if get_bit(i, temp) == 1:
break
# scan down
temp = square
while temp < 56:
temp +=8
moves = set_bit(moves, temp)
if get_bit(i, temp) == 1:
break
# add to dictionary
rook_move_masks[square][i] = moves
```
Now we can bring everything together.
```
# TESTING
# bitboard representing locations of all pieces
# (again, we assume all pieces are enemy pieces)
b1 = 0
b1 = set_bit(b1, a7)
b1 = set_bit(b1, e1)
b1 = set_bit(b1, g1)
b1 = set_bit(b1, h4)
b1 = set_bit(b1, d6)
# bitboard representing locations of allied pieces (same colour as rook)
b2 = 0
b2 = set_bit(b2, e1)
print_bitboard(b1)
print_bitboard(b2)
# rook on a1
square = a1
# work out which squares in the occupancy mask have pieces on them
occupancy_bits = rook_occupancy_masks[square] & b1
print_bitboard(occupancy_bits)
# lookup the movement masks for the given square and occupancy bits
moves = rook_move_masks[square][occupancy_bits]
print_bitboard(moves)
# identify moves when we include the positions of allied pieces
moves = moves & invert(b2)
print_bitboard(moves)
```
```
# masks for a rook on a1 (for a given random board setup shown at top)
# all pieces # allied pieces
A B C D E F G H A B C D E F G H
__________________ __________________
8 | · · · · · · · · 8 | · · · · · · · ·
7 | 1 · · · · · · · 7 | · · · · · · · ·
6 | · · · 1 · · · · 6 | · · · · · · · ·
5 | · · · · · · · · 5 | · · · · · · · ·
4 | · · · · · · · 1 4 | · · · · · · · ·
3 | · · · · · · · · 3 | · · · · · · · ·
2 | · · · · · · · · 2 | · · · · · · · ·
1 | · · · · 1 · 1 · 1 | · · · · 1 · · ·
# occupancy bits # movement mask # movement mask (allied
# from board # pieces removed)
A B C D E F G H A B C D E F G H A B C D E F G H
__________________ __________________ __________________
8 | · · · · · · · · 8 | · · · · · · · · 8 | · · · · · · · ·
7 | 1 · · · · · · · 7 | 1 · · · · · · · 7 | 1 · · · · · · ·
6 | · · · · · · · · 6 | 1 · · · · · · · 6 | 1 · · · · · · ·
5 | · · · · · · · · 5 | 1 · · · · · · · 5 | 1 · · · · · · ·
4 | · · · · · · · · 4 | 1 · · · · · · · 4 | 1 · · · · · · ·
3 | · · · · · · · · 3 | 1 · · · · · · · 3 | 1 · · · · · · ·
2 | · · · · · · · · 2 | 1 · · · · · · · 2 | 1 · · · · · · ·
1 | · · · · 1 · 1 · 1 | · 1 1 1 1 · · · 1 | · 1 1 1 · · · ·
```
---
## Moves For Other Pieces
Now that we've completed the code for rook move generation, it's fairly straightforward to adapt this to work with bishops. The movement mask for a queen is calculated by first looking up the movement as if it were a rook, doing the same as if it were a bishop, then performing a bitwise OR on these two movement masks to take their union.
As we saw earlier, with the knights, the movement masks for non-sliding pieces are simpler to compute and are only determined by the square that the piece is on. A similar piece of code to that of the rook (as shown above) can be used to generate movement masks for the knight, king and pawn.
The only complication with the pawns is that we need different movement masks depending on the colour, and we need to create a mask to identify on which squares the pawn can capture another piece. The movement masks also need to include double moves if the pawn is on the 2nd or 7th rank (if they haven't moved yet). But these masks can still be generated similarly to before.
## Special Moves
The last step is to allow for special moves. These are en passant, castling, and pawn capture. Pawn promotion will be handled later on when we come to applying a chess move to a given board.
En passant is where a pawn captures another pawn that moved two spaces, but as if it had only moved one space. The square that a pawn skips when it performs a double move will be stored in a bitboard called en passant.
We now modify our original board data structure to include some extra information about the state of the board. We use an array to store a series of bitboards (integers) as well as integers to store the additional data. This array is indexed via the following constants.
```
# enumerate array indices for easier board access
# this also gives us constants for white and black that can be used elsewhere
Wpawn, Bpawn, Wrook, Brook, Wknight, Bknight, Wbishop, Bbishop, Wqueen, Bqueen, Wking, Bking, white, black, all,\
enpassant, WLcastle, WScastle, BLcastle, BScastle, nextToMove = range(21)
def new_board():
# initial starting position
B = [ 71776119061217280, 65280, # pawns (white, black)
9295429630892703744, 129, # rooks
4755801206503243776, 66, # knights
2594073385365405696, 36, # bishops
576460752303423488, 8, # queens
1152921504606846976, 16, # kings
18446462598732840960, 65535, # colour
18446462598732840960 | 65535, # all board pieces
0, # en-passant squares
1, 1, 1, 1, # castling rights (wlong, wshort, blong, bshort)
0 # player to move (0=w, 1=b)
]
return B
```
To handle en passant, we set the en passant bitboard to contain the square that was skipped by the double pawn move. This is the square that the capturing pawn would move to. We treat this square as an extension of the enemy pieces. Hence, for pawn move generation, we have the following function.
```
def pawn_move(B, square, pieceColour):
if pieceColour == white:
# standard moves (including double moves)
# remove all squares occupied by another piece - pawns cannot
# capture enemy pieces moving along the same file so all pieces are blockers
moves = wpawn_move_masks[square] & invert(B[all])
# capture moves (take diagonally)
# add capture moves if there is an enemy piece (or the enpassant
# square) in the capture mask
moves |= ( wpawn_capture_masks[square] & (B[black] | B[enpassant] ) )
else: # black pieces
moves = bpawn_move_masks[square] & invert(B[all])
moves |= ( bpawn_capture_masks[square] & (B[white] | B[enpeassant] ) )
return moves
```
```
### TESTING
B = new_board()
B[Bpawn] = set_bit(B[Bpawn], d3)
B[Bpawn] = remove_bit(B[Bpawn], d7)
update_bitboards(B)
print_board(B)
print_bitboard(pawn_move(B, c2, white))
-------------------------------------------------------------------
# board setup # possible pawn moves for pawn on c2
A B C D E F G H A B C D E F G H
__________________ __________________
8 | r n b q k b n r 8 | · · · · · · · ·
7 | p p p p p p p 7 | · · · · · · · ·
6 | · · · · · · · · 6 | · · · · · · · ·
5 | · · · · · · · · 5 | · · · · · · · ·
4 | · · · · · · · · 4 | · · 1 · · · · ·
3 | · · · p · · · · 3 | · · 1 1 · · · ·
2 | P P P P P P P P 2 | · · · · · · · ·
1 | R N B Q K B N R 1 | · · · · · · · ·
```
Similarly, for a king, we have the special move of castling. In order for this to be allowed, the king and the corresponding rook cannot have moved so far in the game. This is known as the right to castle, and will be represented by a Boolean value in our board data structure (see above). There must also be empty squares between the king and the rook. We will not enforce that a player cannot castle through, into or out of a check yet; we will consider that later when we come to applying a chess move to a board. For the king move generation, we have the following function.
```
def king_move(B, square, pieceColour):
alliedPieces = B[white] if pieceColour == white else B[black]
moves = king_move_masks[square] & -(alliedPieces+1)
# check for possible castling moves
# check right to castle conditions, and for empty squares
Long, Short = (B[WLcastle], B[WScastle]) if pieceColour == white else (B[BLcastle], B[BScastle])
if ( Long and not get_bit(B[all], square-1 ) and not get_bit( B[all], square-2 ) and not get_bit( B[all], square-3 ) ):
moves |= 1< This is not my first rodeo.
I've built a chess engine before, but the results were... let's say... underwhelming.
Don't get me wrong, the program worked; it was able to play a full game of chess, and for that, I give it credit. But let's face it, it was terrible at chess.
It took minutes to produce a move, even at a low search depth. And then, the moves it would output were random and unpredictable: sometimes it would force you into a neat mate-in-3, other times it would sacrifice a rook and then lose the game entirely.
I recently decided it's time for round 2, and I thought I'd document my journey and share some things I learn in the process. There are so many different problems that arise, and so many different approaches to solving them. Of all the programming rabbit holes I've gotten lost down, chess programming is definitely one of my favourites.
> *\[Note: The rest of this article assumes a basic level of chess understanding. Familiarity with the rules, piece movement and board notation is recommended (including knowledge of en passant, castling and different draw conditions such as repetition of moves). Check out* [*chess.com*](https://www.chess.com/learn-how-to-play-chess?ref=jdhwilkins.com) *for a comprehensive guide to the rules.\]*
## What is a Chess Engine?
Put simply, a chess engine is a program that, given a valid chess position, will determine the 'best' move that can be made. There are several components that make up an engine, including a board representation, move generation algorithms, a recursive search algorithm, and an evaluation function.
The chessboard representation is perhaps the most important part. Since it will be accessed and manipulated so many times, creating a compact data structure and some efficient methods to manipulate it are vital to the success of our engine.
## Board Representation
A board representation encodes a chess position. It needs to record which piece is where, which player is next to move, and if anything can be taken by en passant (as this is not always obvious from the position of the pieces). There are two main approaches to board representations: a board-centric view and a piece-centric-view.
A board-centric view stores a list or set containing each board square, and associates with it an identifier for any piece that occupies it.
A piece-centric view approaches this the other way around. Instead, we allocate a memory location to each piece, and in it, store the square that the piece resides on.
These structures differ in the way they can be accessed. With a board-centric view, it's quite efficient to find the piece located on a square, but it's less straightforward to find the square given a specific piece. The opposite is true for a piece-centric structure
For this project, I will be using a piece-centric model known as a ***bitboard***.
## Bitboards
```
A 64-bit binary number formatted to show how it relates to a chess board
┌--- least significant bit
|
v
71776119061217280 = (0b) 0 0 0 0 0 0 0 0
0 0 0 0 0 0 0 0
0 0 0 0 0 0 0 0
0 0 0 0 0 0 0 0
0 0 0 0 0 0 0 0
0 0 0 0 0 0 0 0
1 1 1 1 1 1 1 1
0 0 0 0 0 0 0 0
^
└--- most significant bit
```
A bitboard is just a 64-bit binary number. We use one bit of this number to represent each square on the board. The bit will be a 1 if the square contains a piece, and a 0 otherwise. Hence, this is a variation of 1-hot encoding.
Not only can this be used to store the locations of pieces, but it is also a tool that allows us to easily compute possible moves; use the locations of pieces in calculations (without knowing their location) and access, modify and create other bitboards. And, because it's just a binary number, we can use all of the standard bitwise logical and arithmetic operations to modify it.
Since we can visually format the binary string into an 8×8 grid (as shown above), it's easy to see how this bitboard can be used as a mask. For example, the board above is a mask indicating the starting position of each of the white pawns. Instead of recording a number for the location of each piece, we use this optical picture to indicate its location. This mask can be used to target specific functions and operations to work only on specific squares.
There are a lot of advantages to this format, largely due to the use of bitwise and arithmetic operations that give us very efficient ways to manipulate it. Let's start by building some tools to help us work with bitboards:
> *\[Note: we will be using a lower case bfor bitboards, and a capital Bfor the whole chess board (which is just a collection of bitboards)\]*
```
# used to visualise a bitboard
def print_bitboard(b):
# convert to binary string, pad with leading zeros to length of 64
b = bin(b)[2:].zfill(64)
print ("\n A B C D E F G H ")
print (" __________________ ")
for i in range(8):
# need to print upside down and back to front to ensure correct formatting
temp = [' ', 8-i, "|"] + [*(b[-8:])[::-1]]
# replace 0 with · for readability
temp = [i if i!='0' else '·' for i in temp]
print(*temp, sep=" ")
b = b[:-8]
print("\n")
```
```
A B C D E F G H
__________________ // The bitboard coresponding to the white pawns
8 | · · · · · · · ·
7 | · · · · · · · ·
6 | · · · · · · · ·
5 | · · · · · · · ·
4 | · · · · · · · ·
3 | · · · · · · · ·
2 | 1 1 1 1 1 1 1 1
1 | · · · · · · · ·
```
```
# eumerate chess board square names
a8, b8, c8, d8, e8, f8, g8, h8, \
a7, b7, c7, d7, e7, f7, g7, h7, \
a6, b6, c6, d6, e6, f6, g6, h6, \
a5, b5, c5, d5, e5, f5, g5, h5, \
a4, b4, c4, d4, e4, f4, g4, h4, \
a3, b3, c3, d3, e3, f3, g3, h3, \
a2, b2, c2, d2, e2, f2, g2, h2, \
a1, b1, c1, d1, e1, f1, g1, h1 = range(64)
def get_bit(b, square):
return 1 if (b & (1< ABCDA, ABDCA, ACBDA, ACDBA, ADBCA, ADCBA
Let's also assume, for the sake of simplicity, that the cost of the journey from A to B is the same as the cost from B to A, so it doesn't matter which direction you travel in. This means that the tour: ABCDA is actually the same as ADCBA, just traversed in the opposite direction. This cuts the number of possible routes in half, leaving us with 3 to consider:
> ABCDA, ABDCA, ACBDA
Well, that's not so complicated to solve, right? We could just check each of the possibilities in turn and see which one is the cheapest. And you'd be right: to actually *solve*the problem (and guarantee you've found the best route), this is the only way it can be done. However, when we start looking at larger graphs, the number of possibilities increases dramatically:

As you can see, the problem gets out of hand pretty quickly, making it very difficult, if not impossible, to find a solution. To give these numbers some context, with just 20 cities, we're looking at a number of routes comparable to the number of grains of sand on Earth! If we relax the constraint that the journeys cost the same in both directions, we would need to double the number of possible routes, making it even more challenging to solve.
## Heuristic Methods
As we've seen so far, there is no definitive solution to this problem (except a brute force approach). However, there are some heuristic methods we can use to give us an approximate solution. While the result may not be optimal, these algorithms give us answers that are sufficient for many practical use cases and can be computed in a much more reasonable time scale.
## Nearest Neighbour Algorithm
The Nearest Neighbour algorithm is one of the simplest approaches to finding a solution. We begin at the start node, *A*, and then visit the lowest cost adjacent node. From this new node, we repeat, finding the cheapest node to visit that we have not already been to. Once all nodes have been visited, we then return to the start.

For the above graph, the algorithm would look something like this:
Start at *A*
The cheapest unvisited adjacent node is C (cost=6)
From C, the cheapest unvisited adjacent node is D (cost=3)
From D, the only remaining unvisited node is B (cost=1)
From B, we return to the start node, A (cost=9)
This gives us the route A-C-D-B-A with a total cost of 19\. In this case, this is the best solution we can find. However, this algorithm doesn't always give us the best solution:

Applying the same steps to this graph gives us the route A-B-D-C-A, which has a total cost of 16 (=1+2+4+9). But this is not the optimal route: the path A-B-C-D-A has a total cost of 11 (=1+4+4+2).
## Greedy Algorithm:
A 'Greedy Algorithm' is one that makes the best choice at each step; it does not consider how its choices impact the solution as a whole, so long as the immediate choice looks like it is heading in the right direction. The Nearest Neighbour approach is also an example of a greedy algorithm.
Another way we could find a solution is to sort all of our edges by their cost, lowest to highest. We can repeatedly add the shortest edges to our solution, ensuring that they satisfy some constraints:
Adding an edge does not form a cycle- unless this cycle visits every node (so if there are 4 nodes, we don't want a cycle that includes 3 nodes)
Adding an edge does not result in a node with more than 2 edges connecting to it
These constraints will ensure that we only visit each node exactly once before returning to the start. Let's apply this method to the first example again.

The lowest cost edge in this graph is DB (cost=1). We add this to our solution
The next lowest cost edge is DC (cost=3). We add this to our solution
The next lowest cost edge is AC (cost=6). We add this to our solution
The next lowest cost edge is AD (cost=8), but we already have 2 edges that connect to D (DB and DC), so we ignore this edge
If we have edges of equal weight that satisfy all constraints, it does not matter which one we pick. In this case AB and BC both cost 9, however adding BC would violate both constraints: There would be 3 edges in our solution that connect C. It would also create a cycle, CBD, which does not include all nodes. Therefore, we must choose the edge AB (cost=9)
We now have all 4 edges: DB, DC, AC, AB. Notice that each letter appears exactly twice in this list. We can construct a tour out of these edges that starts and ends at A: ABDCA this will have cost of (19). This is the same solution found by the Nearest Neighbour method. Again, in this case, we have found an optimal solution.
## Genetic Algorithm
A Genetic Algorithm is a machine learning technique modelled on biological evolution. We start with a random sequence, visiting the cities in a completely random order, and repeatedly improve upon this route until we find a 'good enough' solution. Again, this solution may or may not be optimal.
For more information about Genetic Algorithms, check out [***this***](https://jdhwilkins.com/the-machine-learning-algorithm-inspired-by-darwin/?ref=jdhwilkins.com) article
## Real-world Uses
The Travelling Salesman Problem has many real-world applications. As you might guess, it can be used for delivery and distribution systems in order to optimise routes and improve warehouse operations. However, it also crops up in the manufacture of circuit boards and X-ray crystallography (the analysis of the structure of crystals).
The problem is deceptively simple, and it is not known whether there exists an efficient solution, but one has not yet been found. It is also a great example of a time-accuracy trade-off, where achieving an optimal solution is unrealistic, whereas a faster, though less accurate solution, is often more practical. This is a common theme in many areas of problem-solving and decision-making.
Whether planning a trip across Europe or optimizing delivery routes, understanding the Travelling Salesman Problem and its solutions can save time and money. Ultimately, it highlights the importance of finding effective and efficient solutions in a world where the right answer is not always available.
### Genetic Algorithms: Machine Learning with Darwinian Evolution
URL: https://www.jdhwilkins.com/genetic-algorithms-machine-learning-with-darwinian-evolution/
Last updated: 2026-08-10T09:30:04.000Z
In the ever-expanding field of artificial intelligence, some of the most fascinating advancements come from mimicking the natural world. One such breakthrough is the Genetic Algorithm, a powerful machine learning technique inspired by Charles Darwin's theory of natural selection. Just as organisms evolve over time, honing their adaptations to thrive in their environments, Genetic Algorithms evolve solutions to complex problems, becoming increasingly effective with each iteration.
## Darwin's Finches
A classic example of natural selection involves the finches of the Galápagos Islands. The islands are home to several different species of finches, each with distinct beak shapes and sizes. These differences are adaptations due to the specific types of food available on the different islands.
With each generation of finches, there will be some random variation in the offspring: some will have slightly larger, stronger beaks, while others will have longer, more slender beaks. Naturally, some will be better suited to the environment than others. The well-adapted individuals will be slightly more likely to reproduce and pass on their favourable genetics to their offspring. So in the next generation, there will be more individuals with this characteristic. And so the cycle continues.
Over many generations, the slight variation becomes more prominent, and eventually, the once-random mutation becomes a prominent feature of the species.
## The Algorithm of Natural Selection
In the Genetic Algorithm, we use a lot of similar terminology, inspired by the world of genetics. Instead of a population of finches, we start with a population made up of sequences of numbers, referred to as chromosomes. The values in the sequences (genes) are used to solve some sort of problem.
We follow a similar process, selecting pairs of chromosomes from our population and 'reproducing' them to give us our offspring. We can introduce some random mutation to stop our gene pool from getting too small. When we have a new generation formed of the offspring of the previous one, we repeat the process. After many iterations, the chromosomes become better adapted to solve the problem, and we start producing better solutions.
## Searching For A Solution
At its core, the Genetic Algorithm is a guided random search. Instead of randomly exploring different search paths, we bias the algorithm to look in the right direction. This is the main advantage of this algorithm: its ability to explore a vast search space very efficiently.
A 'Fitness Function' is created to evaluate the success of each chromosome. With each generation, the randomness that we introduced allows the algorithm to explore more possible solutions. When they are evaluated with the fitness function, the highest-scoring ones will produce more offspring. This guides the algorithm in the right direction instead of searching through unsuitable solutions. The chromosomes get better over time, so the solutions are refined until we get something near optimal.
## How Do Genetic Algorithms Work?
- **Initialisation**: The process begins by generating a random initial population of potential solutions to the problem. The format of the solution and the way it is represented using data will depend on the situation.
The Following are then repeated until we find a suitable solution:
**Selection**: With our initial population set, the algorithm evaluates the fitness of each individual. The fitness function, designed specifically for the problem, determines how well each solution performs. We randomly select pairs of individuals, influenced by their fitness score, so the fitter the individual, the higher its chances of being selected for reproduction.
**Crossover**: To create the next generation, the algorithm pairs up individuals from the current population and combines them in some way to produce two new offspring. This could be as simple as selecting some genes from one parent, and some from another, so the children inherit traits from both parents.
**Mutation**: Occasionally, random mutations are introduced into the offspring's chromosomes, altering one or more of their genes. This step is crucial because it introduces new gene variations (alleles) into the gene pool, helping to prevent the algorithm from converging too soon, which could result in a poor solution.
**Iteration**: The process of selection, crossover, and mutation is repeated over many generations. With each iteration, the population ideally becomes fitter, with individuals that are closer to the optimal solution.
**Termination**: The algorithm continues to evolve the population until a stopping criterion is met. This could be a predetermined number of generations or a sufficient fitness level. The best solution in the final population is considered the algorithm's output.
## Applications of Genetic Algorithms
Genetic Algorithms are remarkably versatile and have been applied across various fields:
**Optimisation Problems**: GAs are often used for optimising complex functions where traditional methods might struggle, such as in engineering design or financial modelling.
**Robotics**: GAs can be used to evolve strategies, such as in game playing or robotic control, where the algorithm helps the AI adapt to different scenarios.
**Bioinformatics**: GAs are used to solve problems like protein folding and gene sequencing, where the search space is enormous and traditional methods are computationally expensive.
> To see an example of Genetic Algorithms at work, check out how this [application of solving the Travelling Salesman Problem](https://jdhwilkins.com/solving-the-travelling-salesman-problem-using-a-genetic-algorithm/?ref=jdhwilkins.com)
Genetic Algorithms are a great example of how nature can be harnessed to solve modern problems. They offer a powerful, adaptable method for finding solutions in a world where problems are often too complex for straightforward answers.